after the data
$p(\theta \mid d)$
posterior
∝
how well the parameters explain the data
$p(d \mid \theta)$
likelihood
×
before the data
$p(\theta)$
prior
Doctoral thesis in Physics
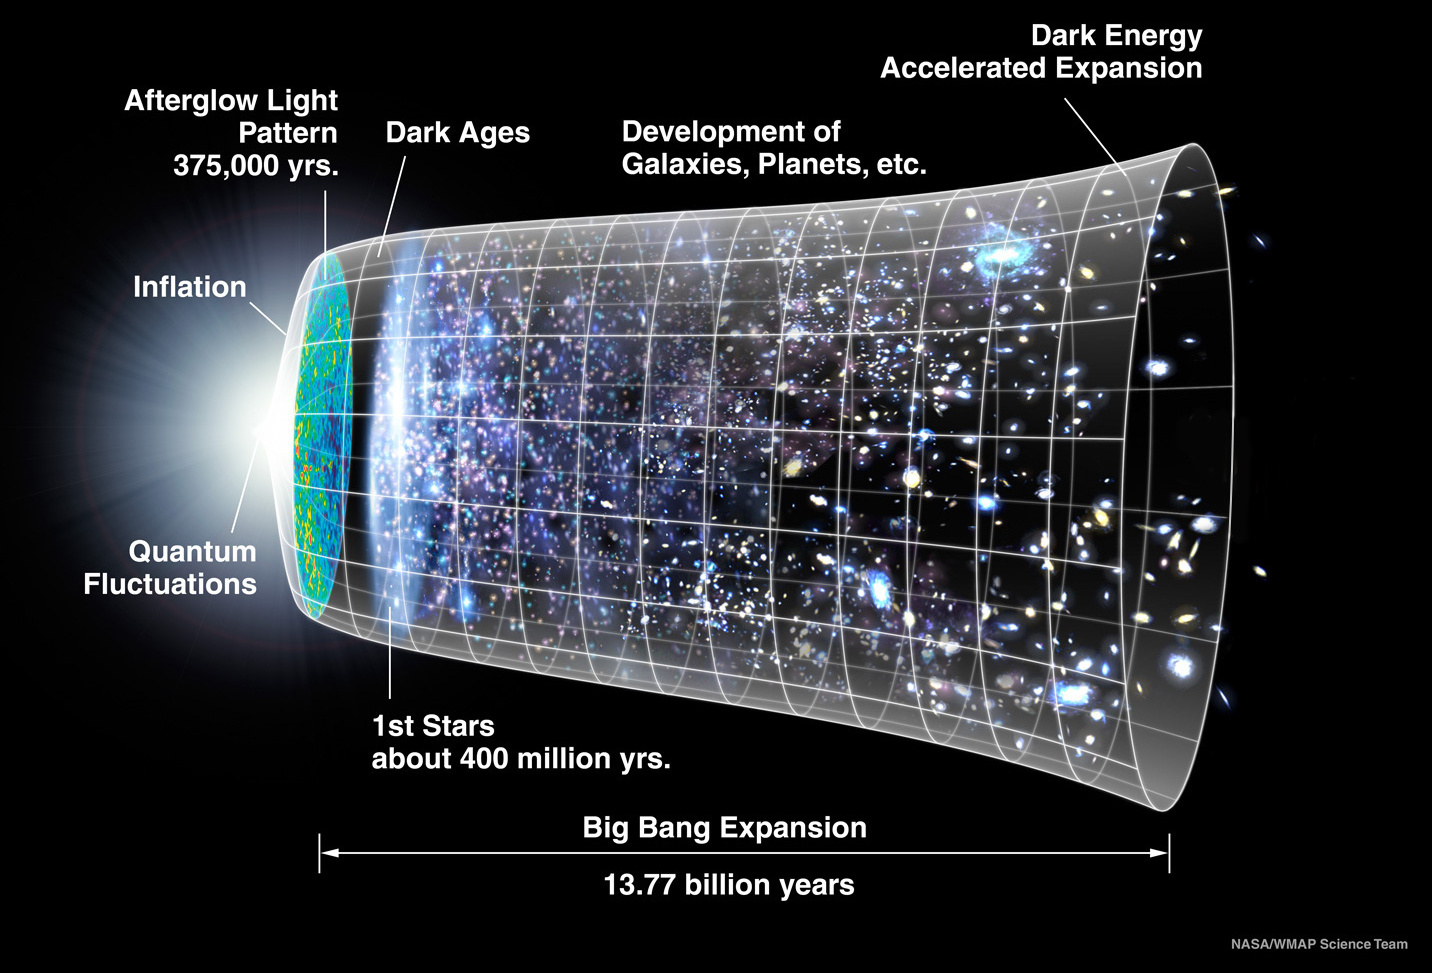
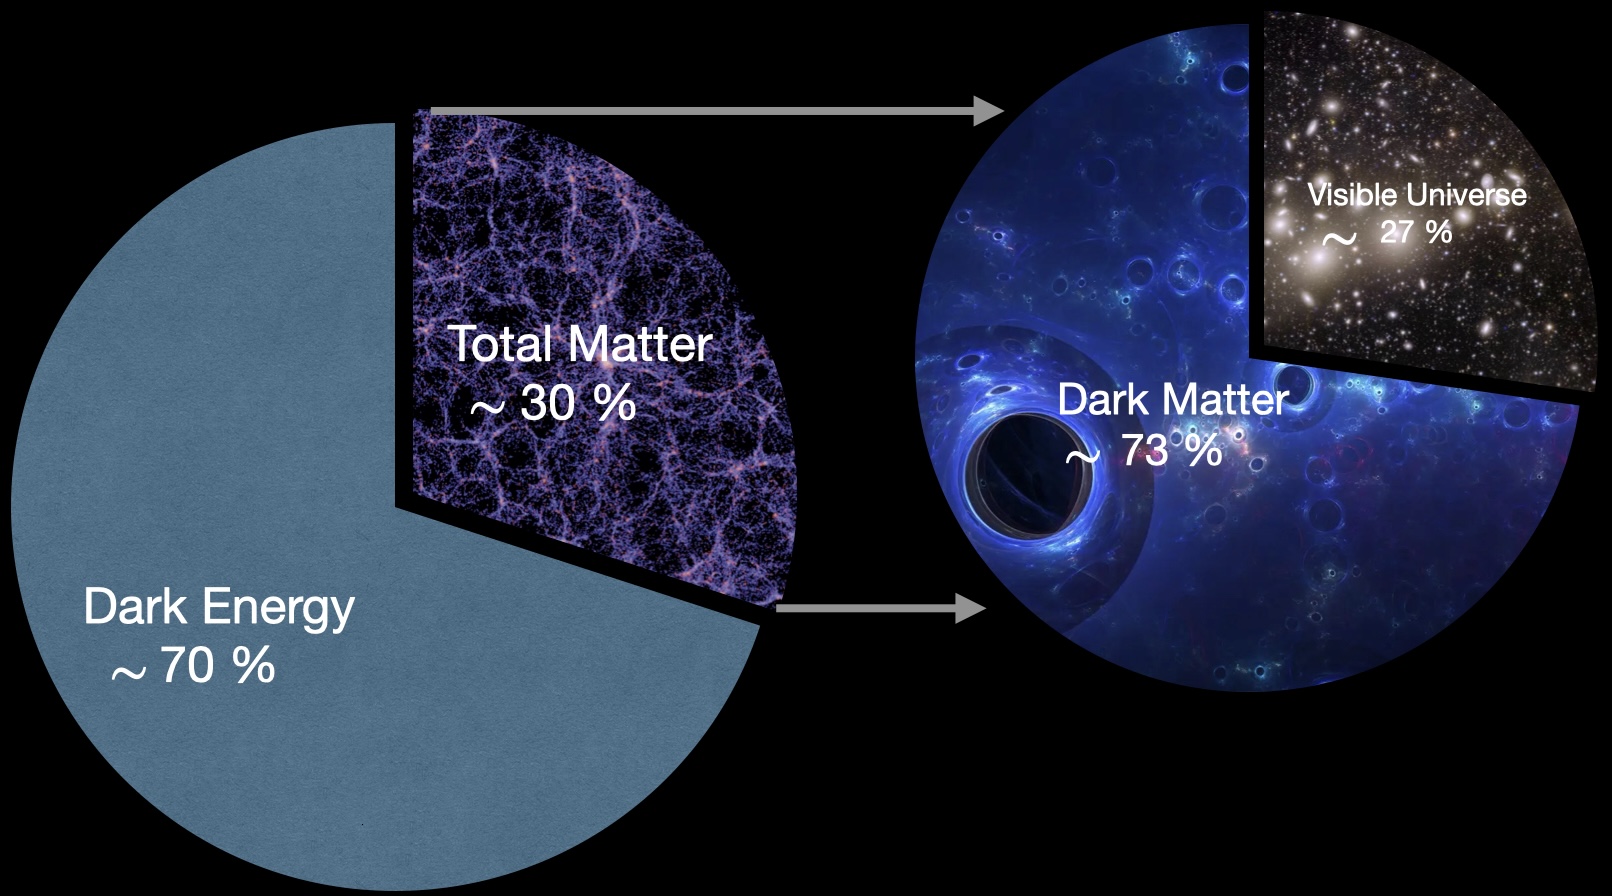
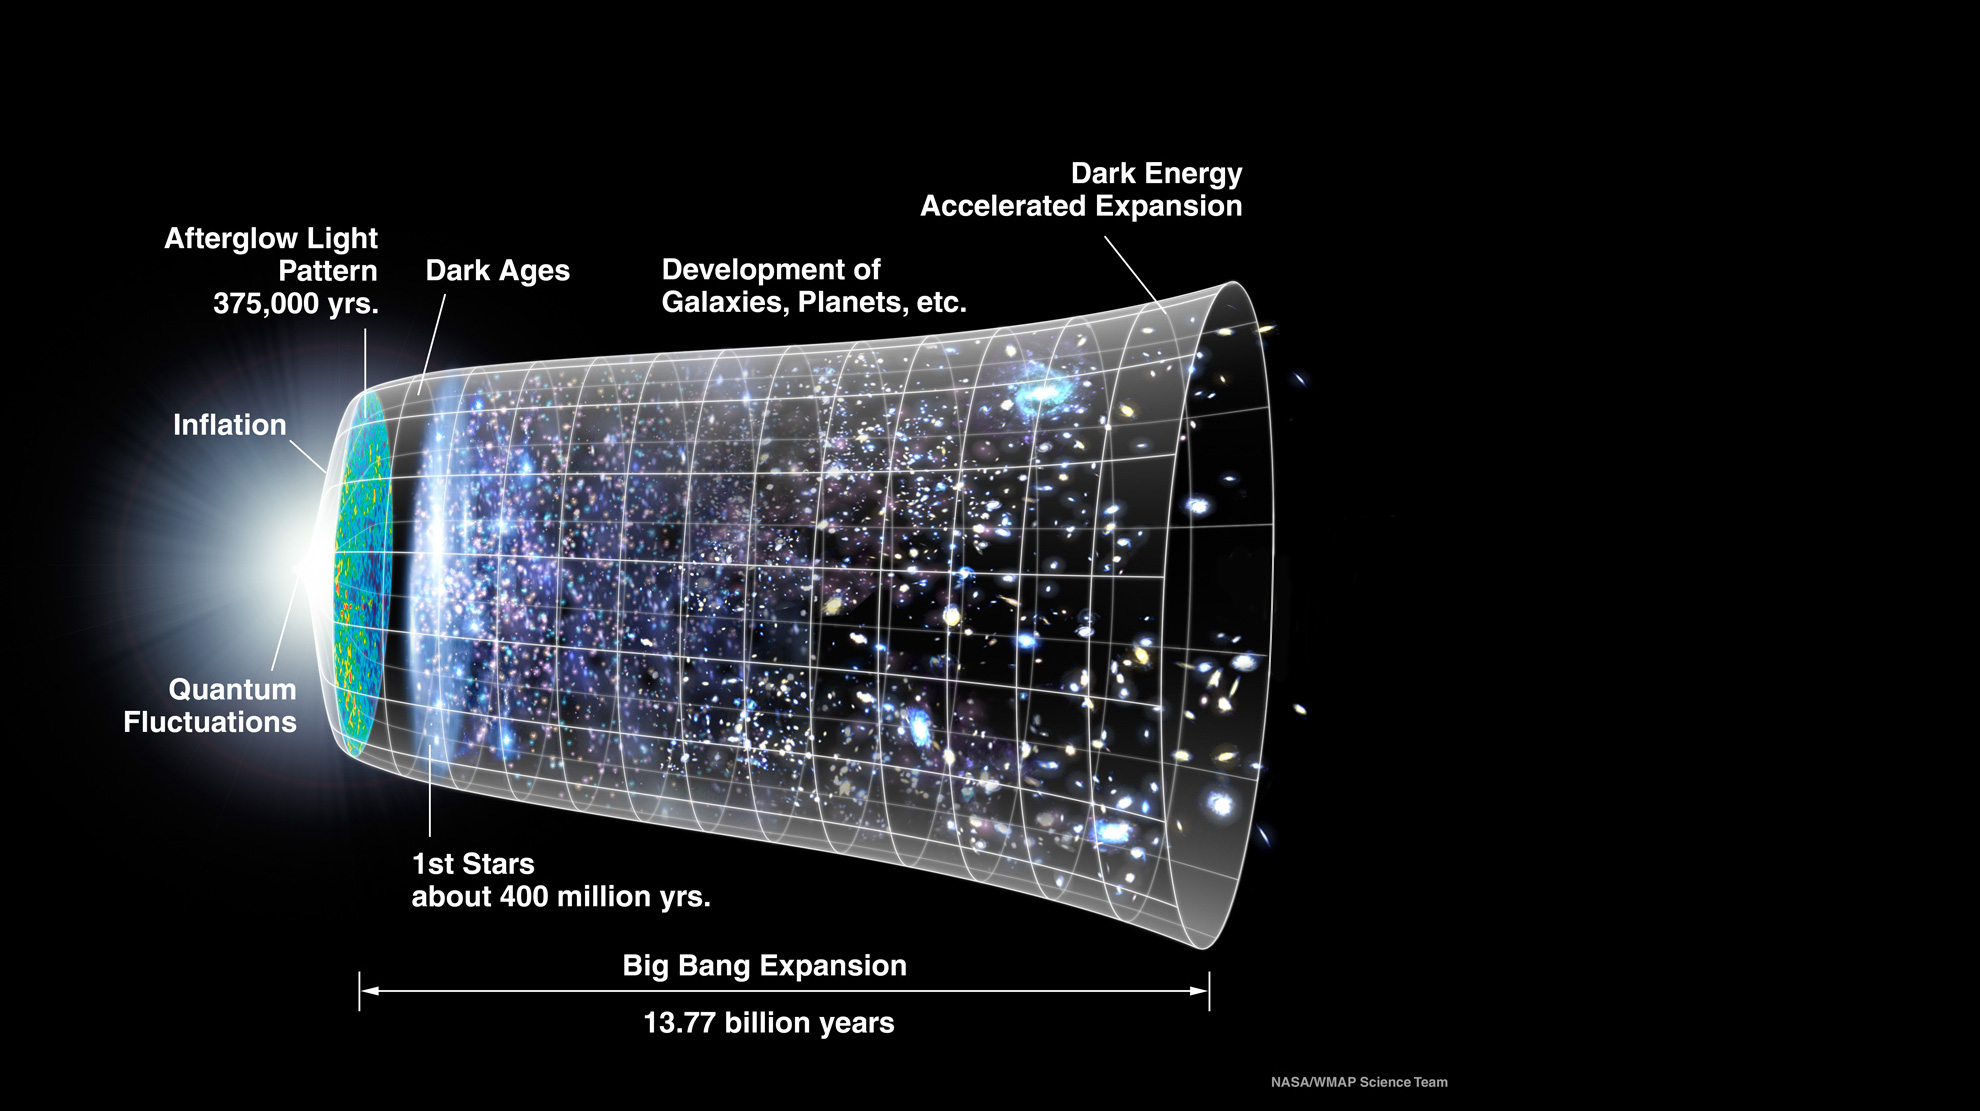
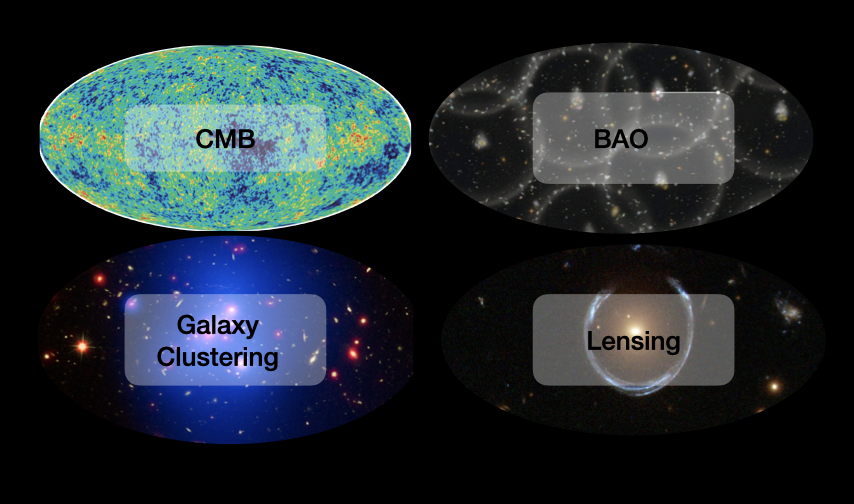
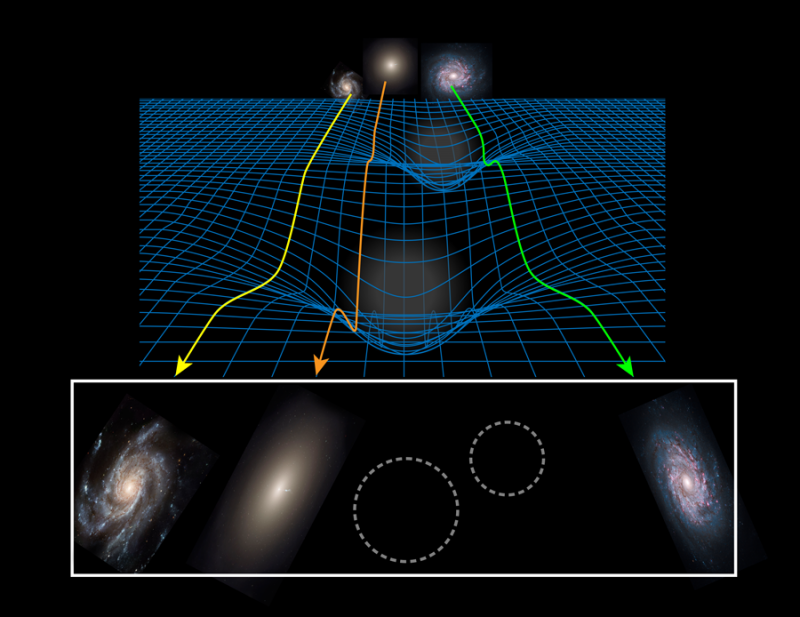
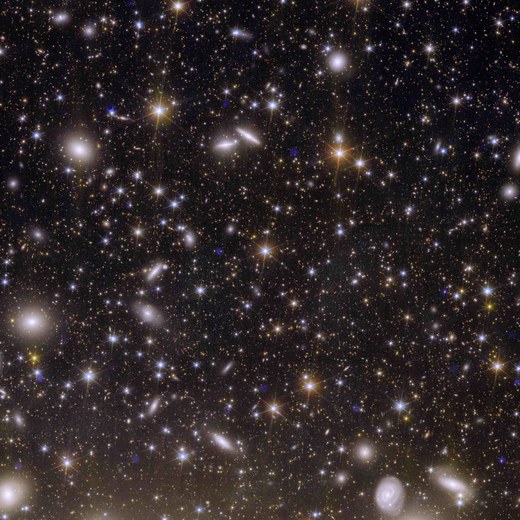
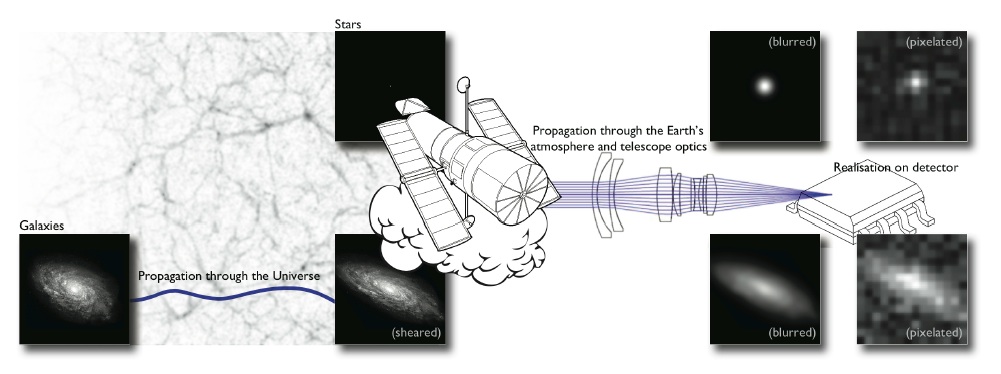
Image © American Physical Society / Alan Stonebraker; galaxy images from STScI/AURA, NASA, ESA and the Hubble Heritage Team / astronomie.nl.
Lensing and clustering together, to measure cosmic geometry and growth at percent-level precision.
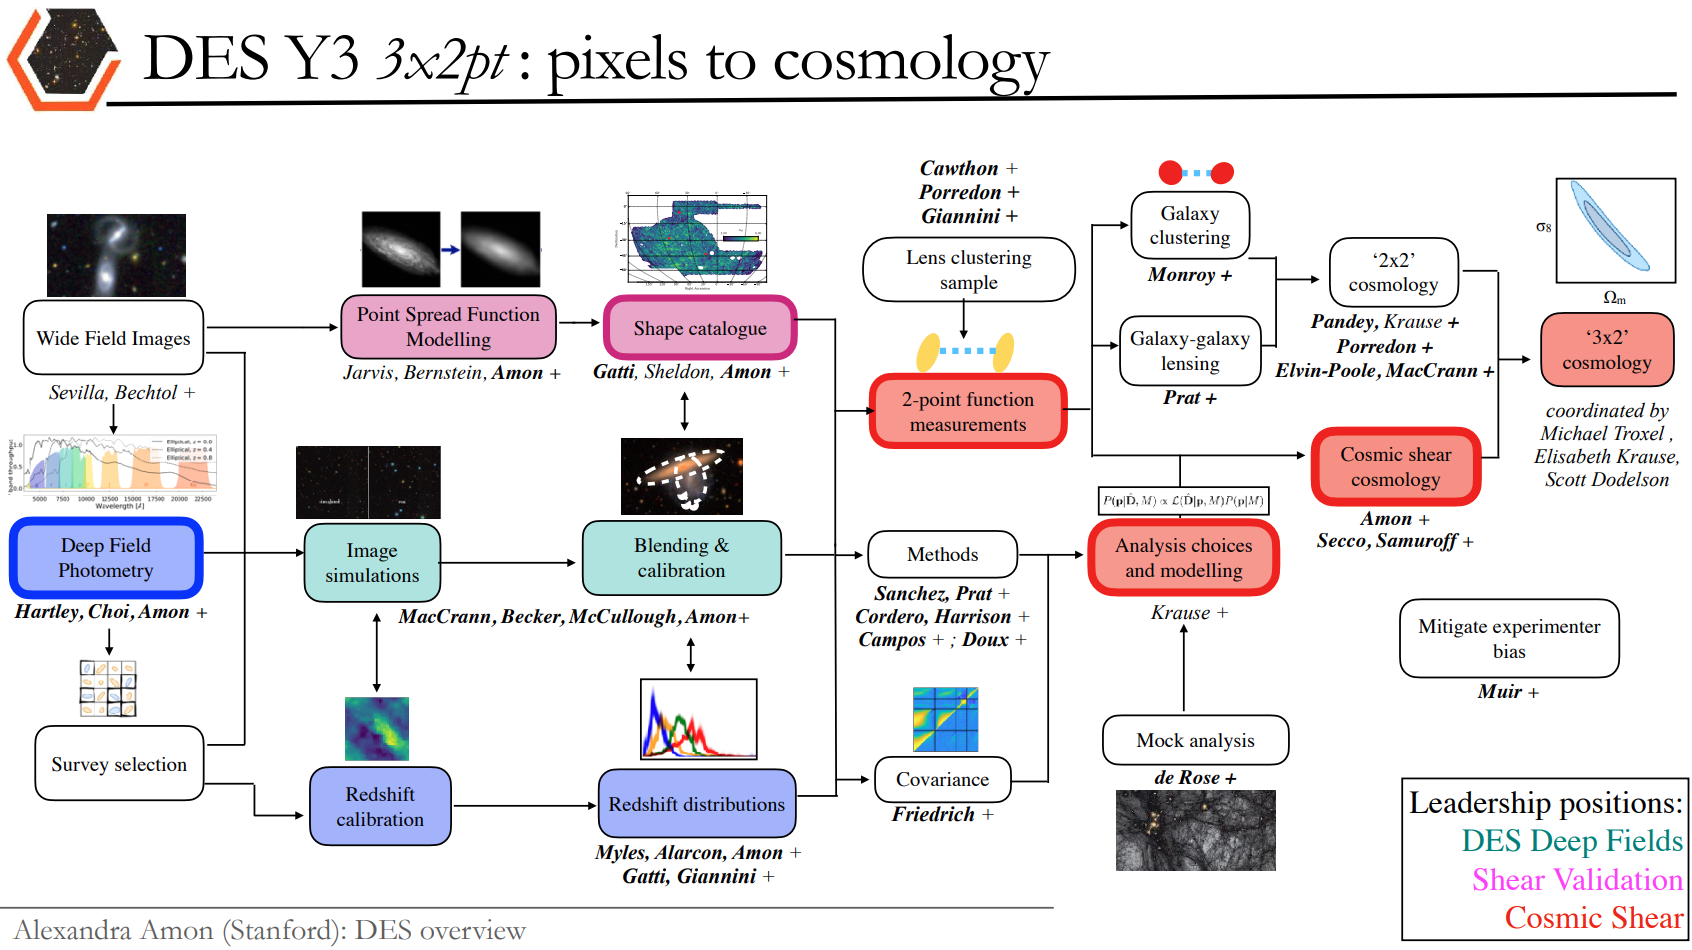
Almost every box is a paper on its own, and most of the work is measurement and calibration (PSF modelling, shape calibration, blending, redshift distributions, covariances). .
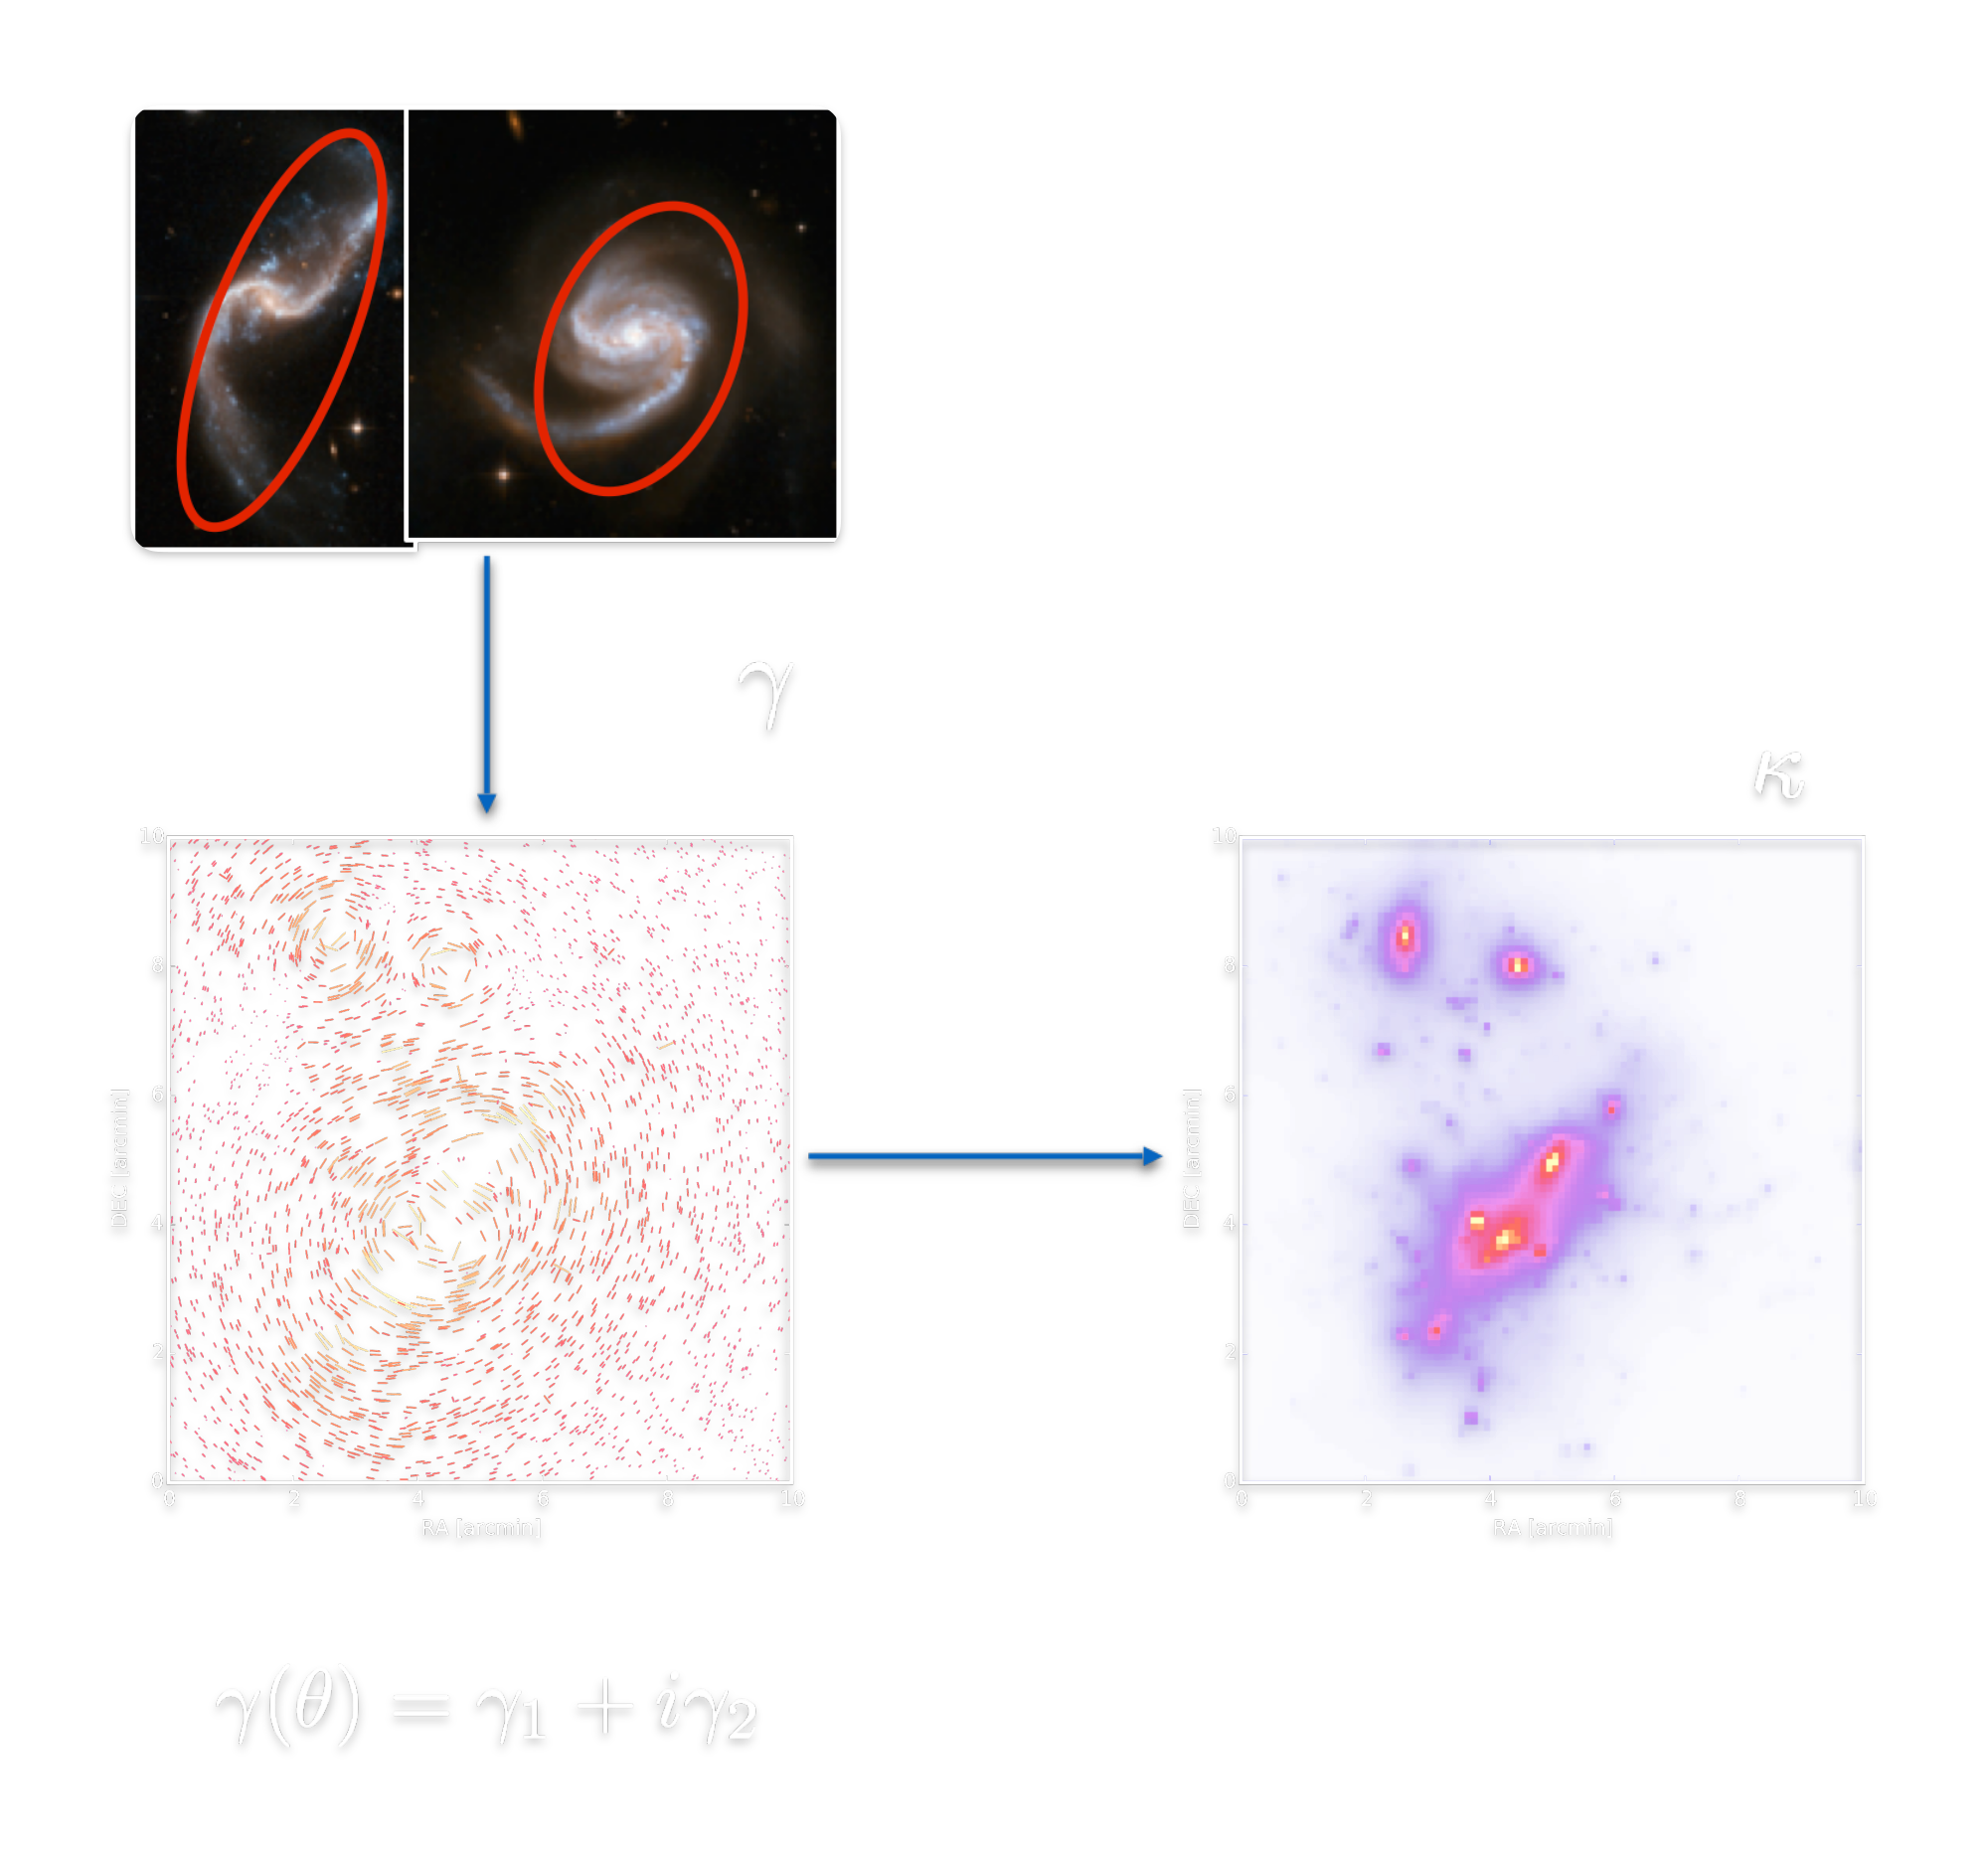
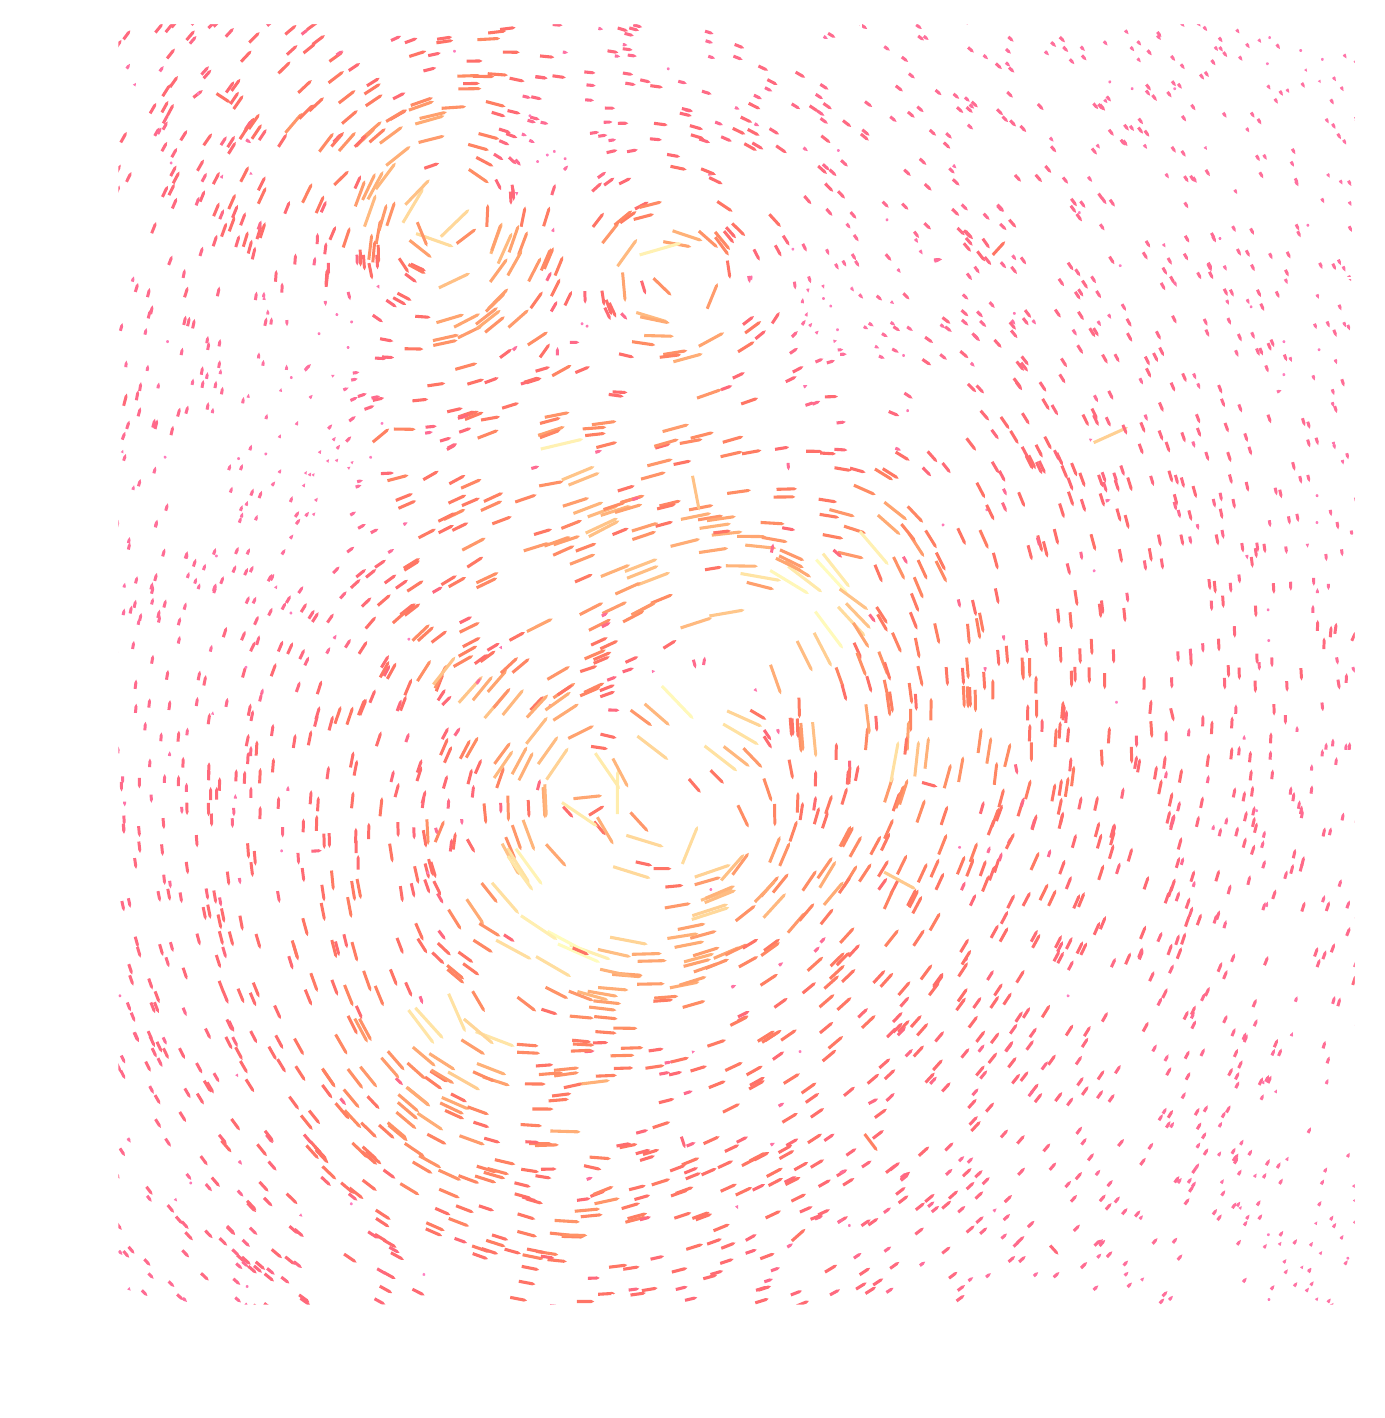 measured galaxy shapes
the data
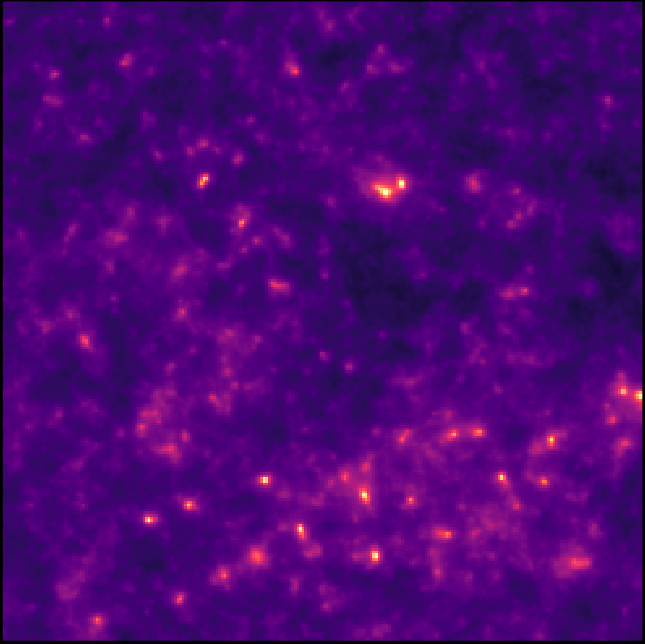
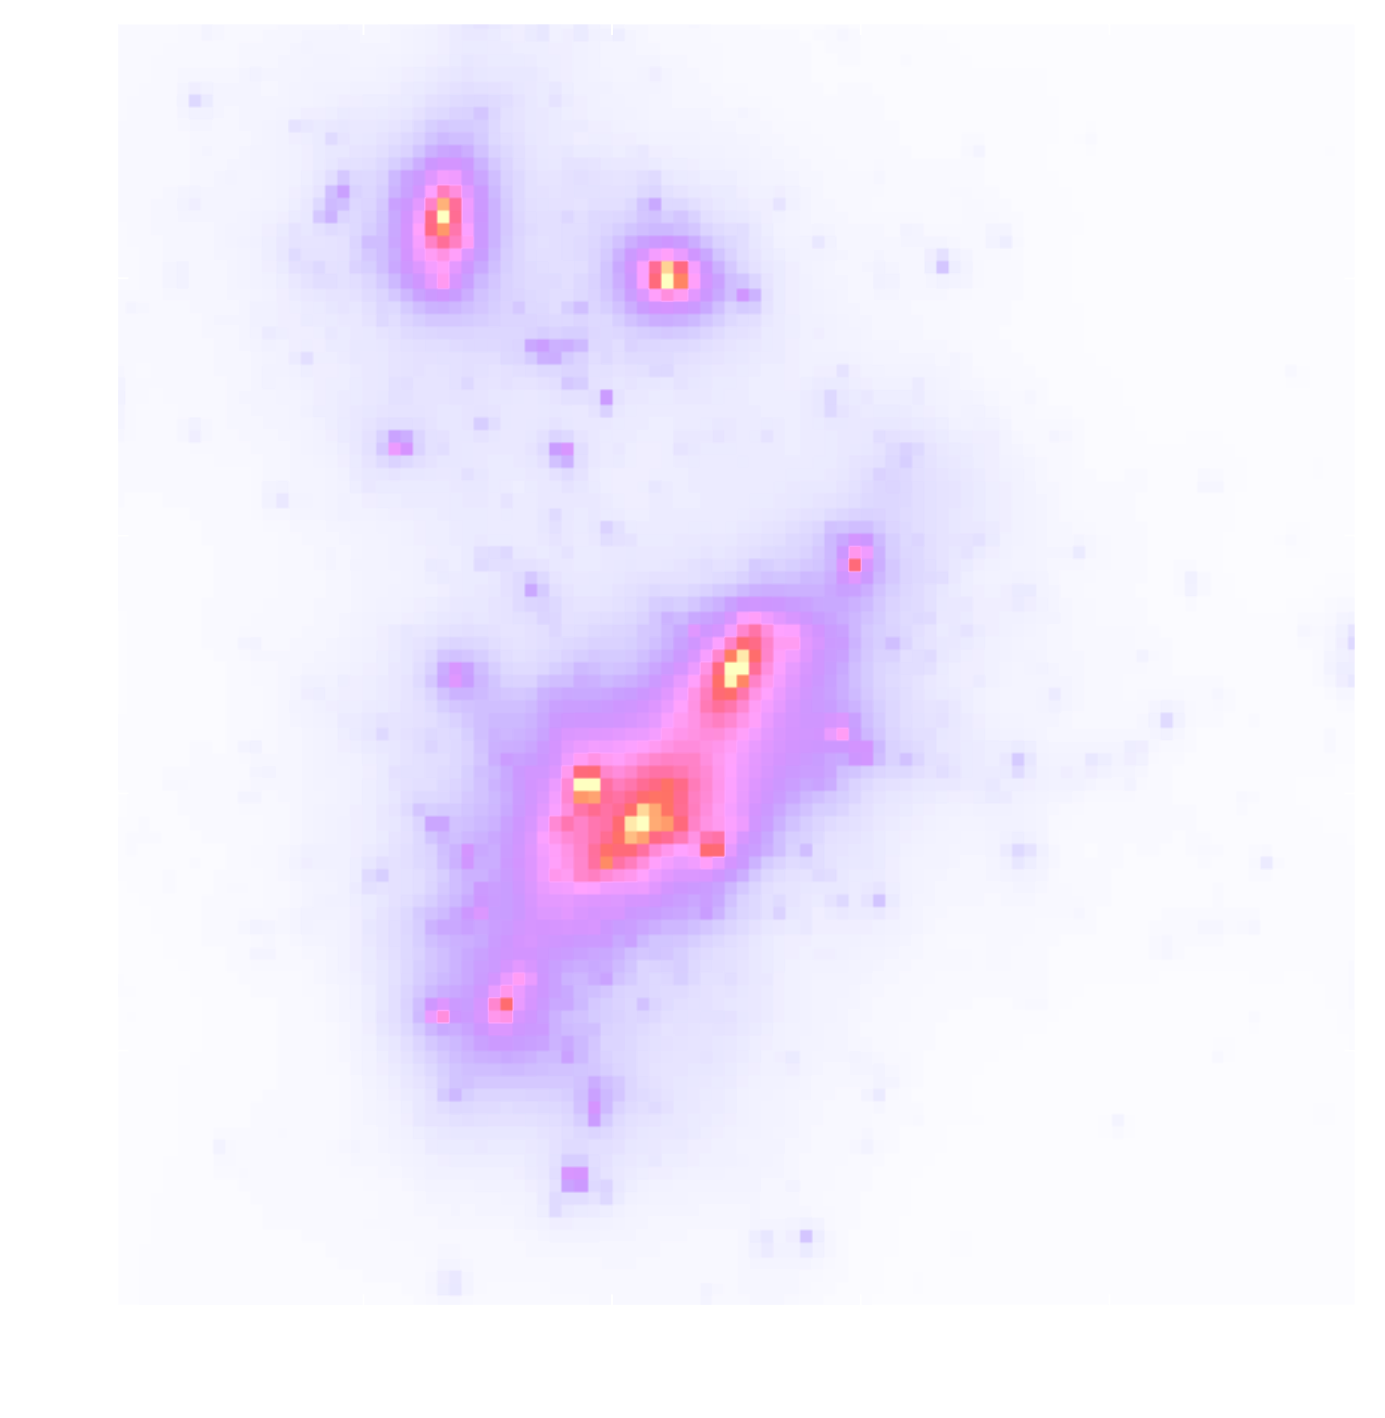 reconstruct the matter map
step 1
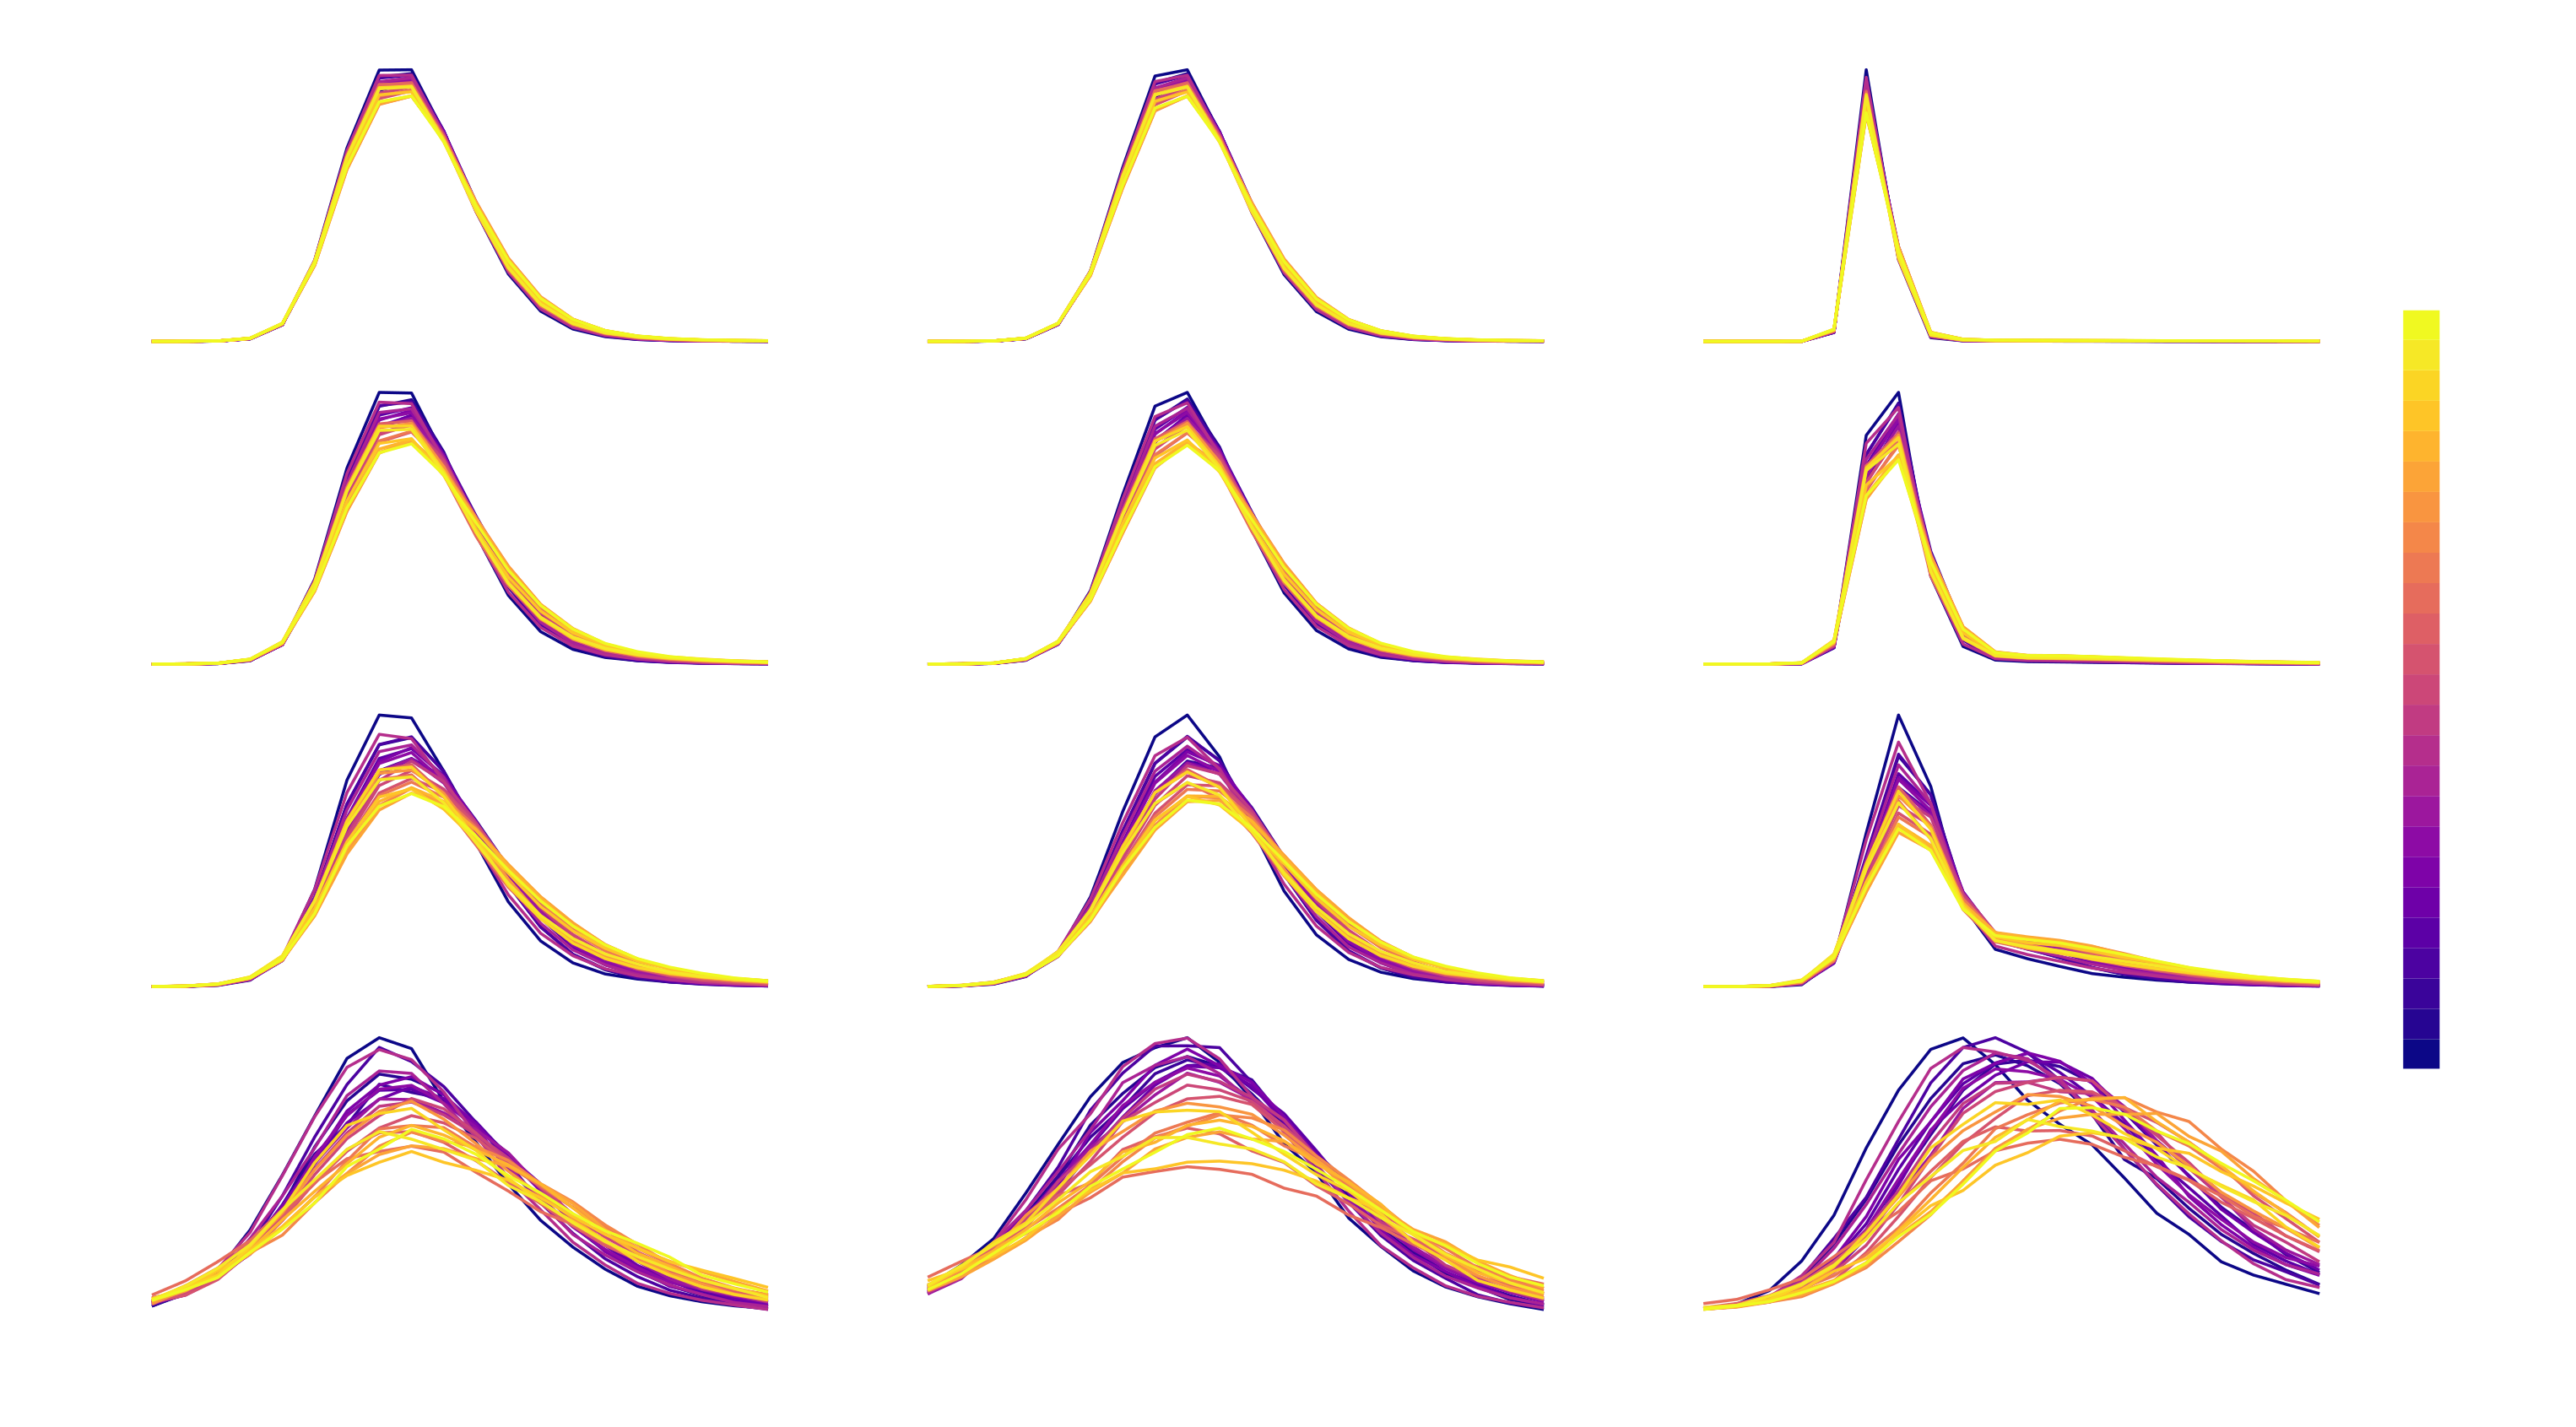 summarise it with a statistic
step 2
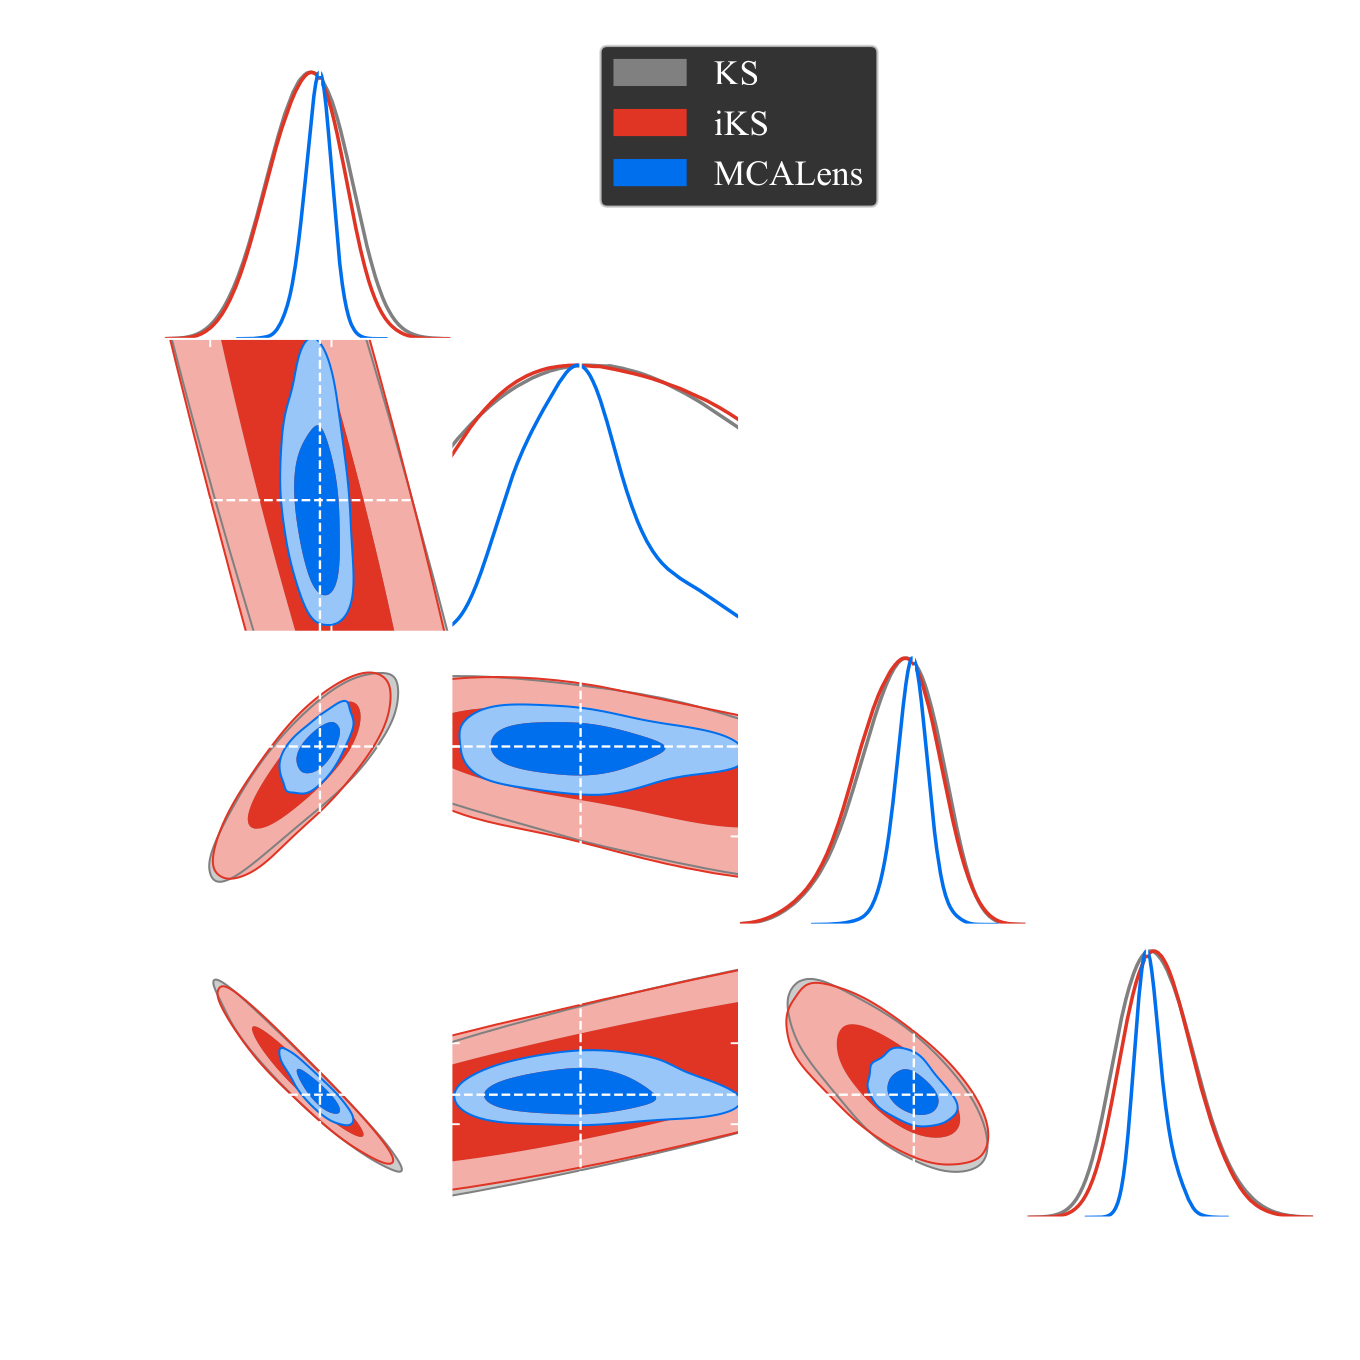 infer the parameters
step 3
Every one of those steps is now built out of learned components, and every one of them can bias the result or discard information, and there is no internal check that would detect it.
Shear in, a mass map out. Everything in Parts 1 and 2 is about what happens between those two boxes.
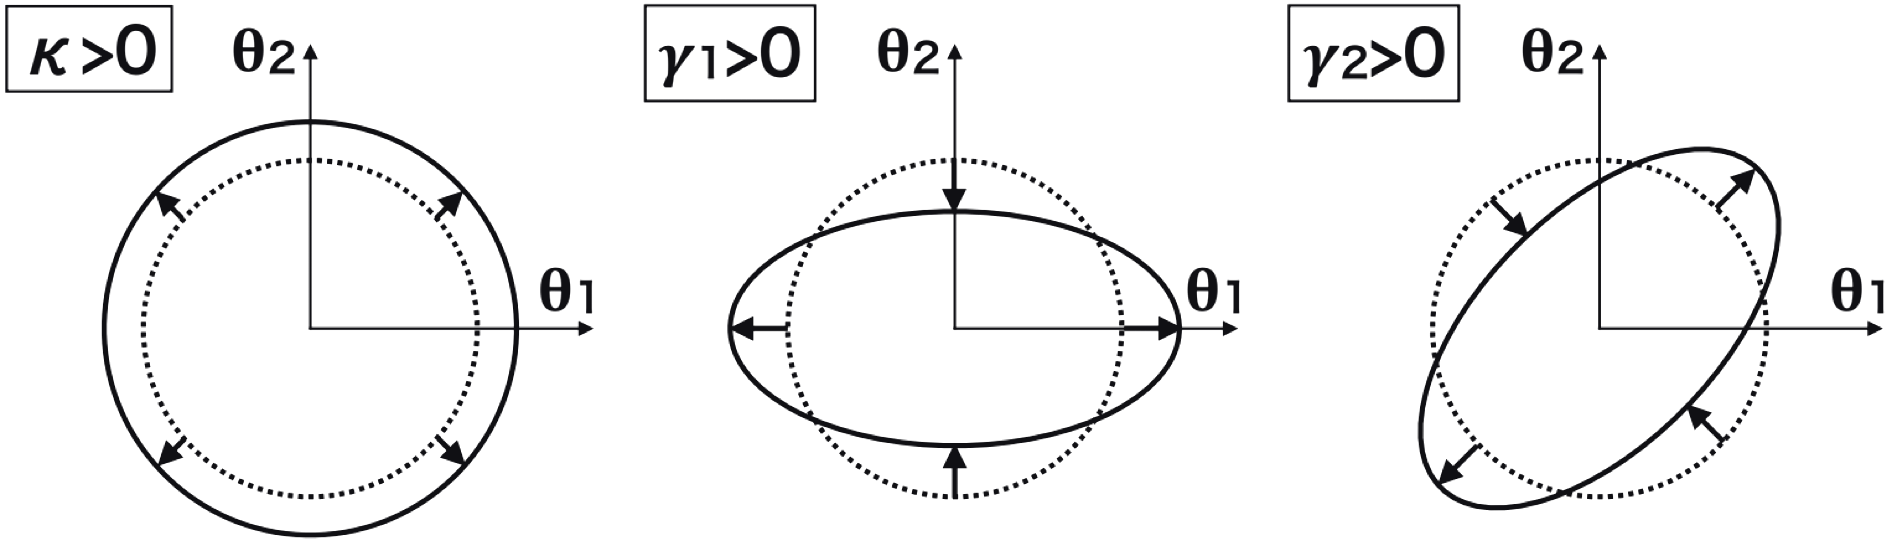
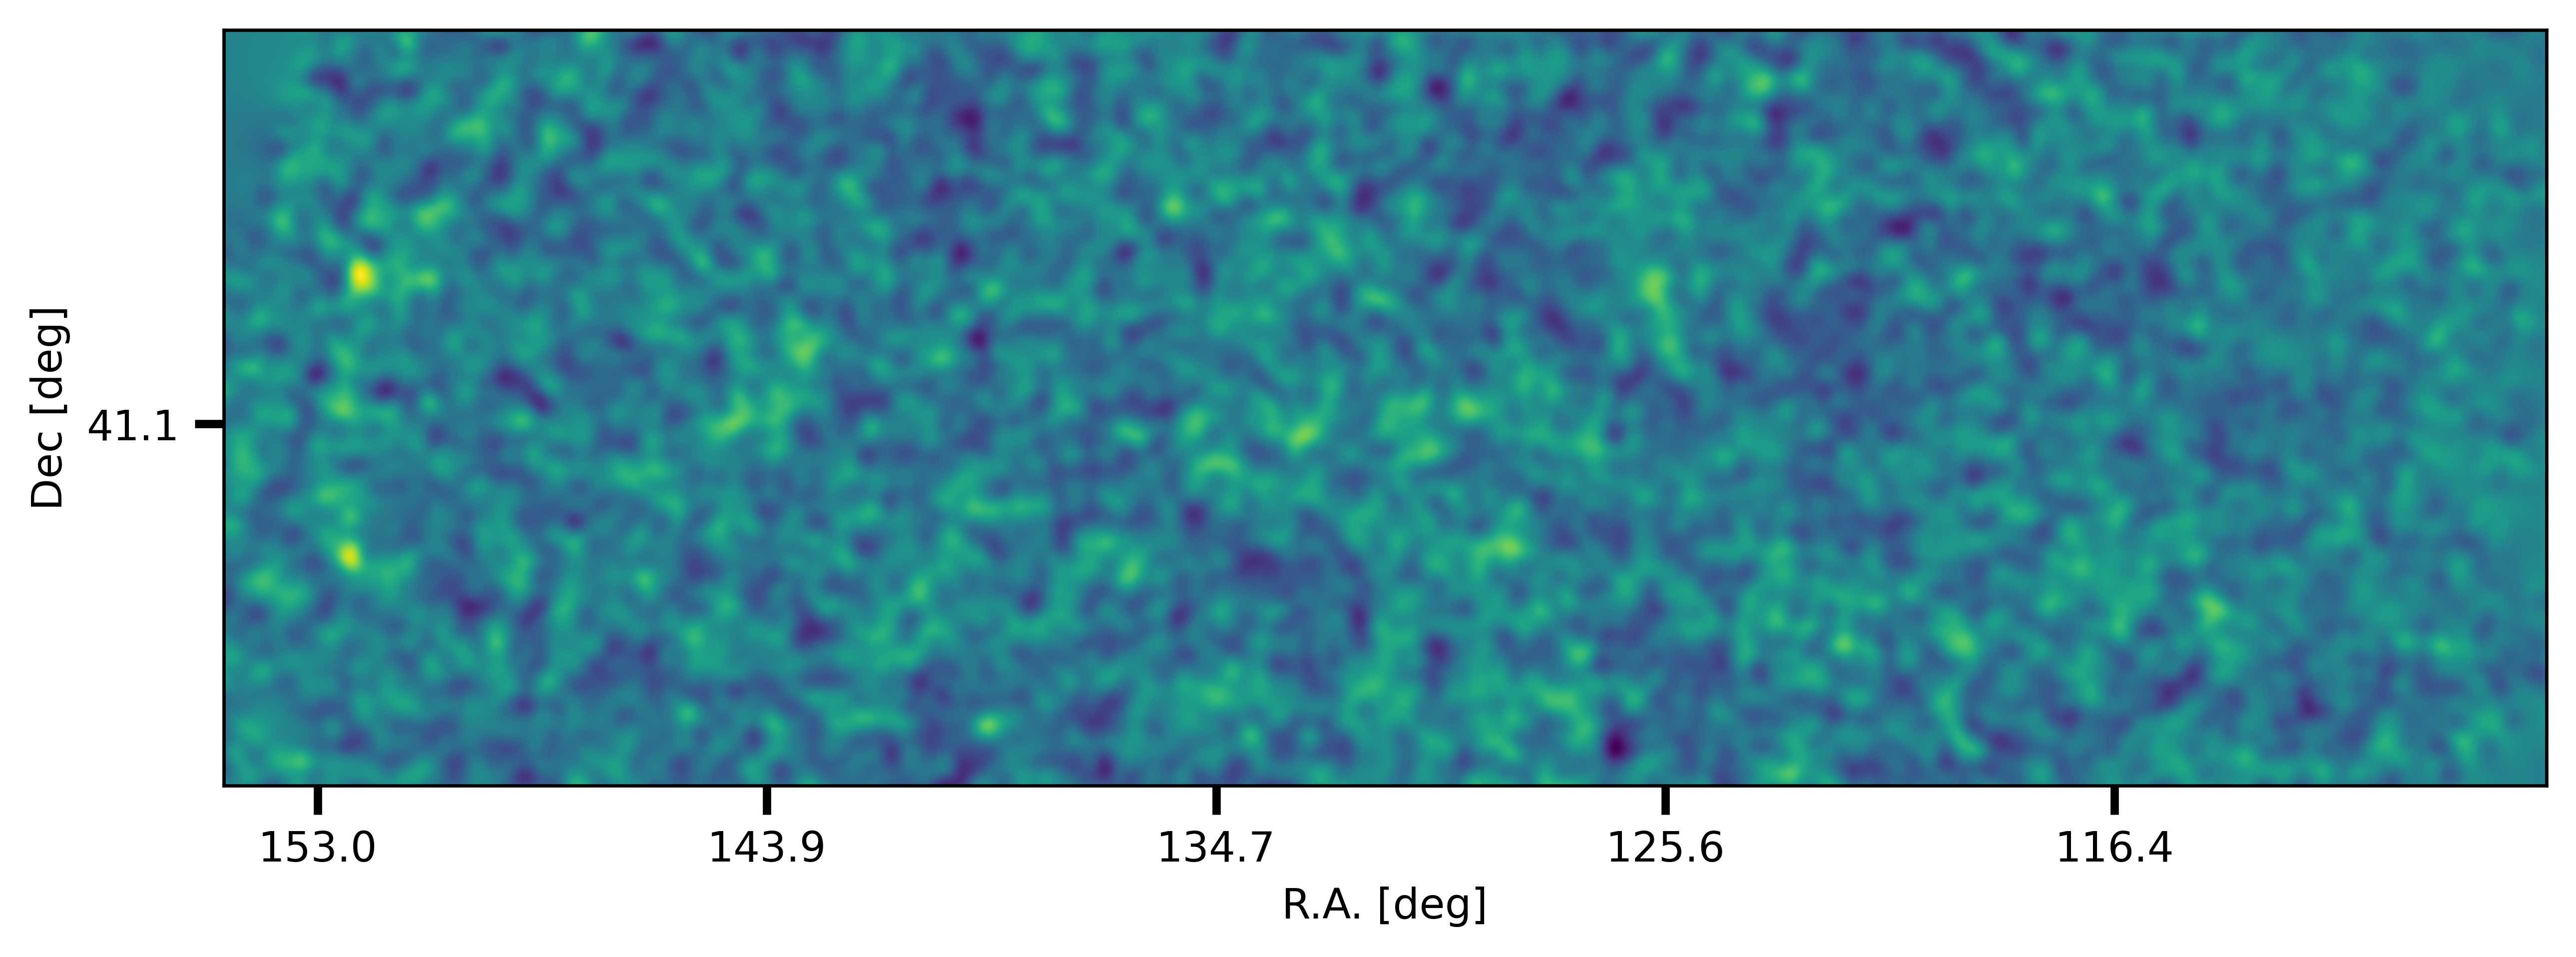
So a convergence map is a map of the mass.
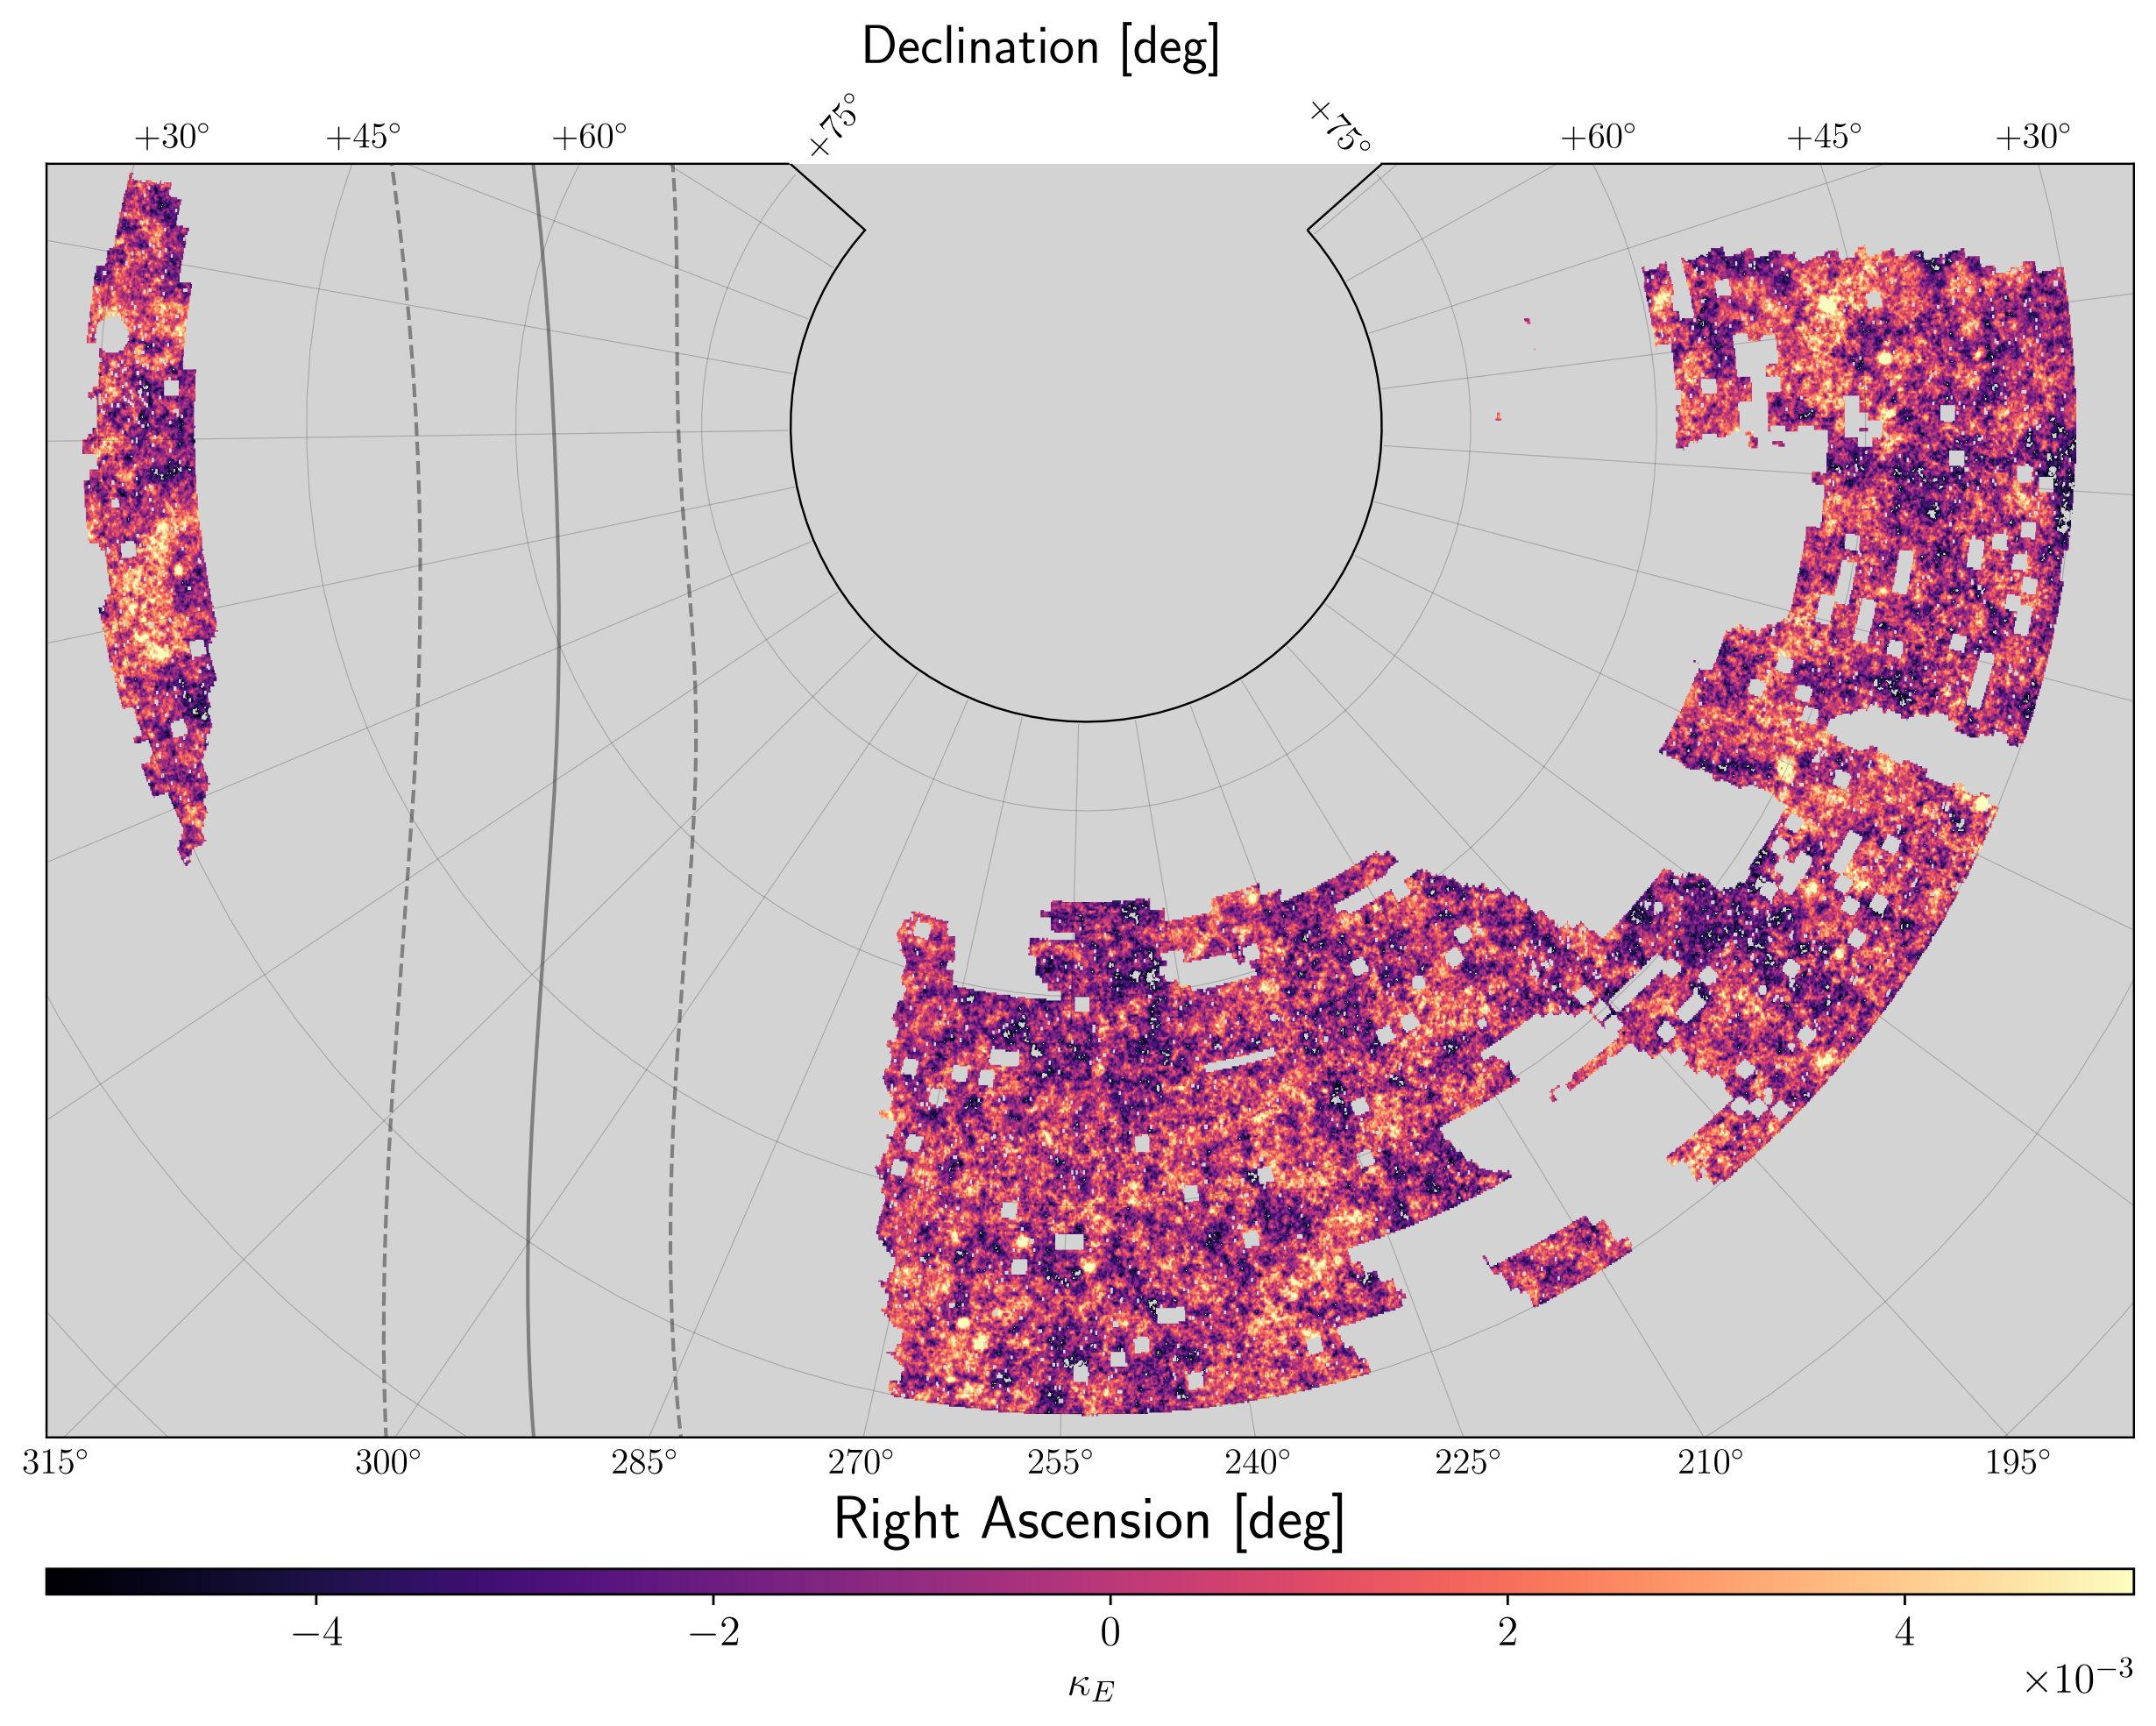
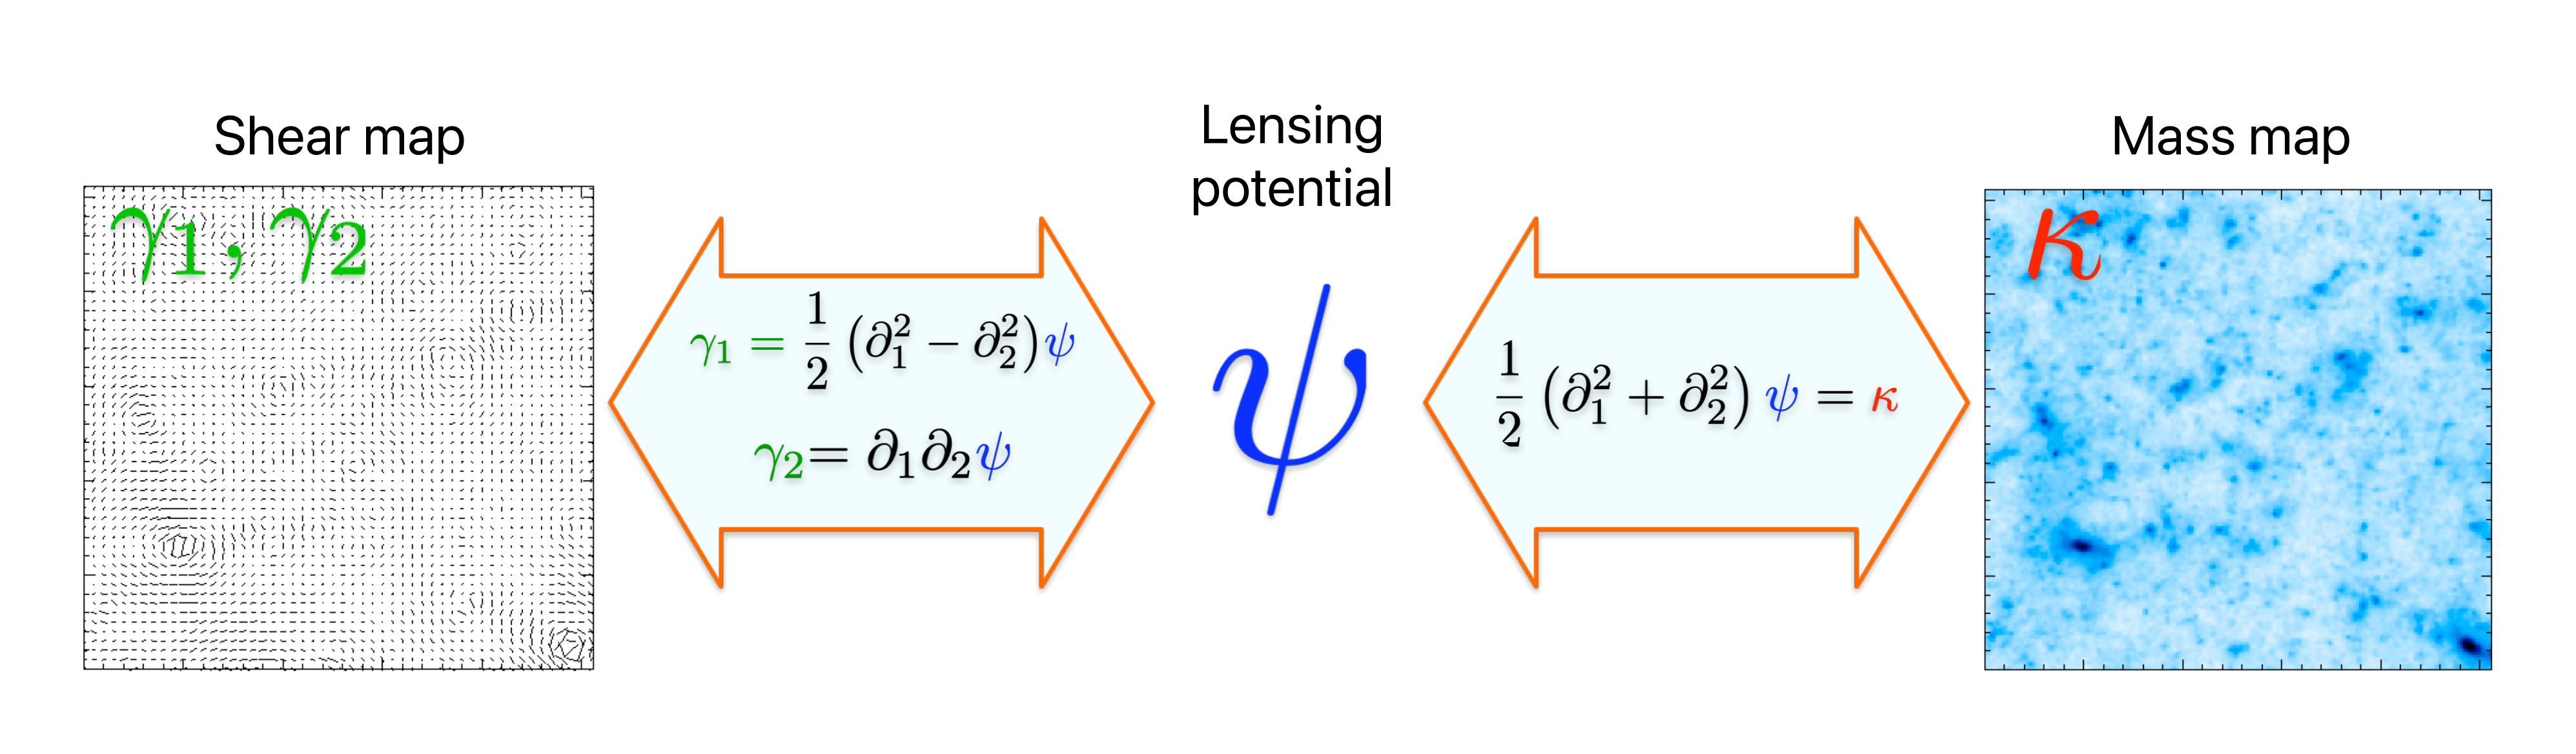
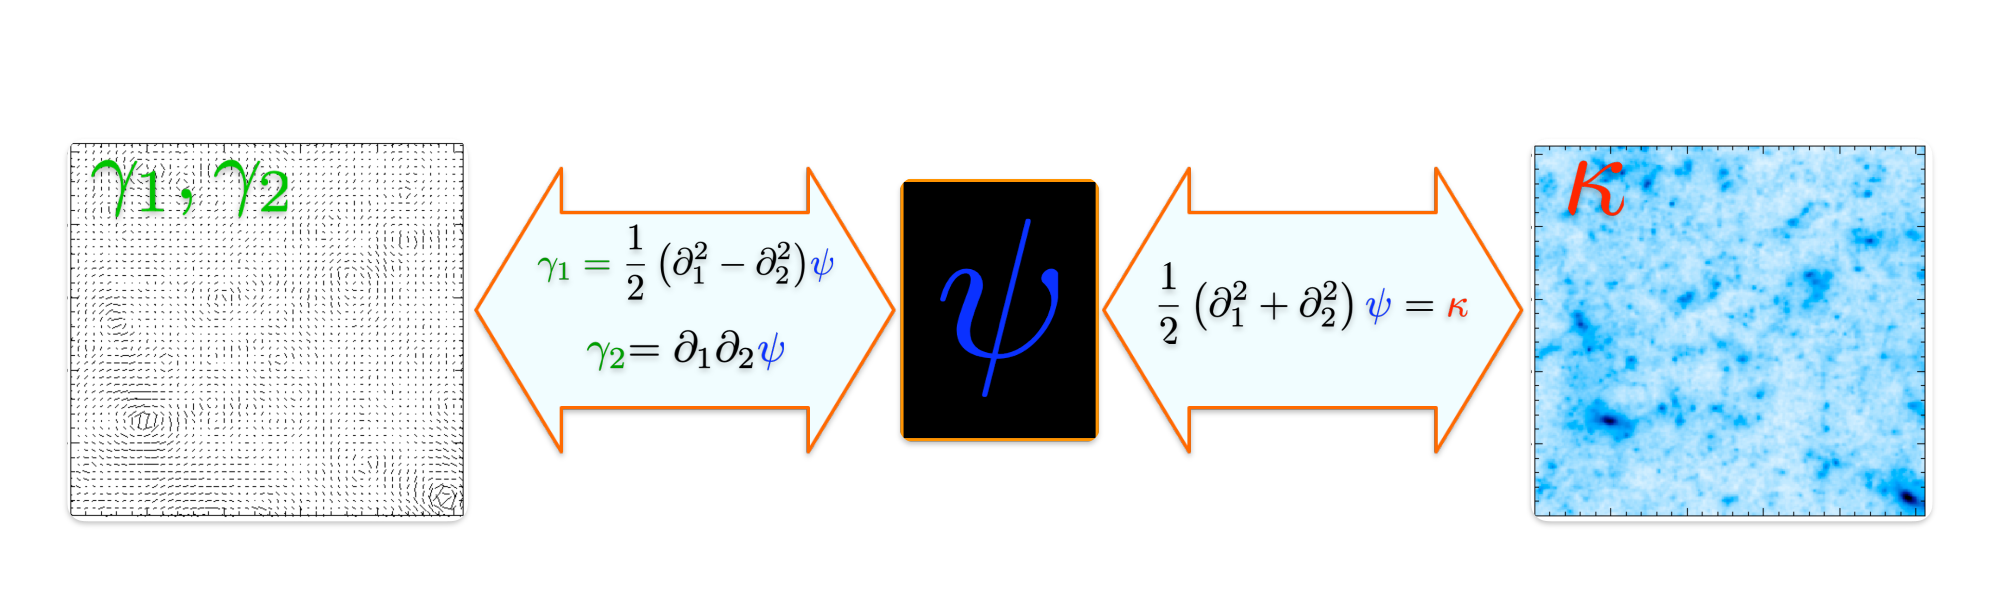
$$\gamma \;=\; \underbrace{\mathbf{M}}_{\text{the mask}}\quad \underbrace{\mathbf{P}}_{\text{shear operator}}\; \kappa \;+\; \underbrace{\mathbf{n}}_{\text{shape noise}}$$
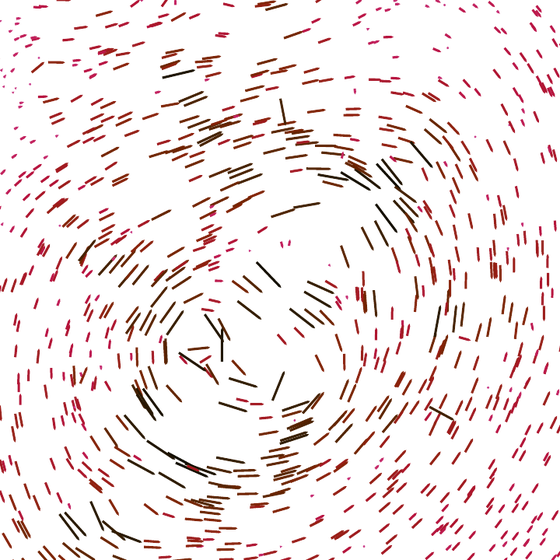
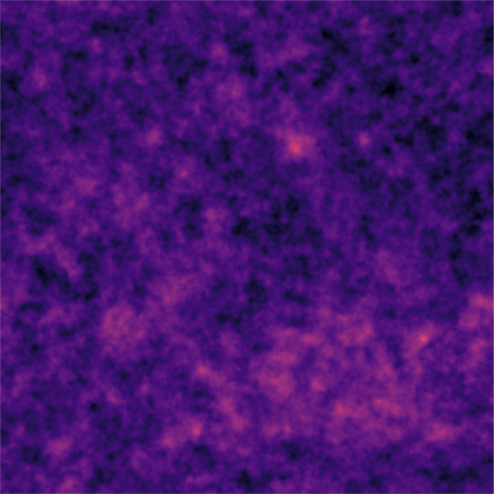
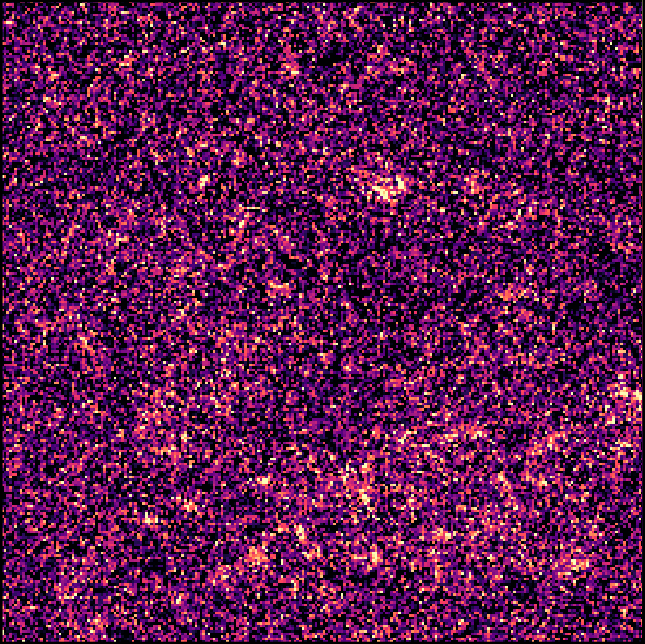
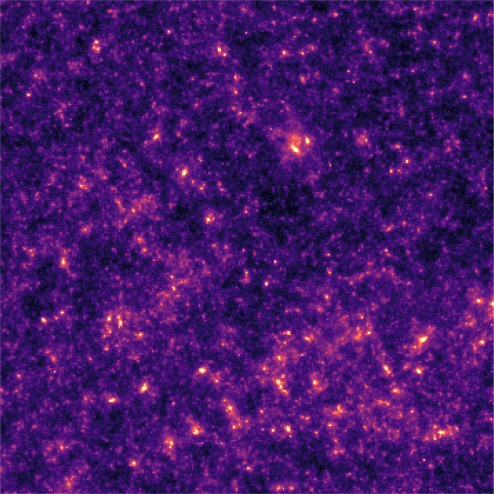
Selecting one solution requires a prior on $\kappa$, and the choice of prior is what distinguishes the methods.
$$\hat{\kappa} \;\in\; \arg\min_{\kappa}\; \underbrace{\tfrac{1}{2}\big\lVert \mathbf{P}\kappa - \gamma \big\rVert^{2}_{\mathbf{N}^{-1}}}_{\text{data fidelity: does it match the shear?}} \;+\; \lambda\, \underbrace{\mathcal{R}(\kappa)}_{\text{regulariser: is it a plausible map?}}$$
estimated with a Wiener filter, which needs only the power spectrum.
sparse in the starlet domain (peaks and haloes).
solve $\kappa_{\rm G}$, holding $\kappa_{\rm NG}$ fixed ↻ solve $\kappa_{\rm NG}$, holding $\kappa_{\rm G}$ fixed
Iterate to convergence. Each sub-problem is solved with a proximal step.
the proximal operator
$$\mathrm{prox}_{\lambda\mathcal{R}}(v) \;=\; \arg\min_{u}\; \tfrac{1}{2}\lVert u - v \rVert^{2} \;+\; \lambda\,\mathcal{R}(u)$$
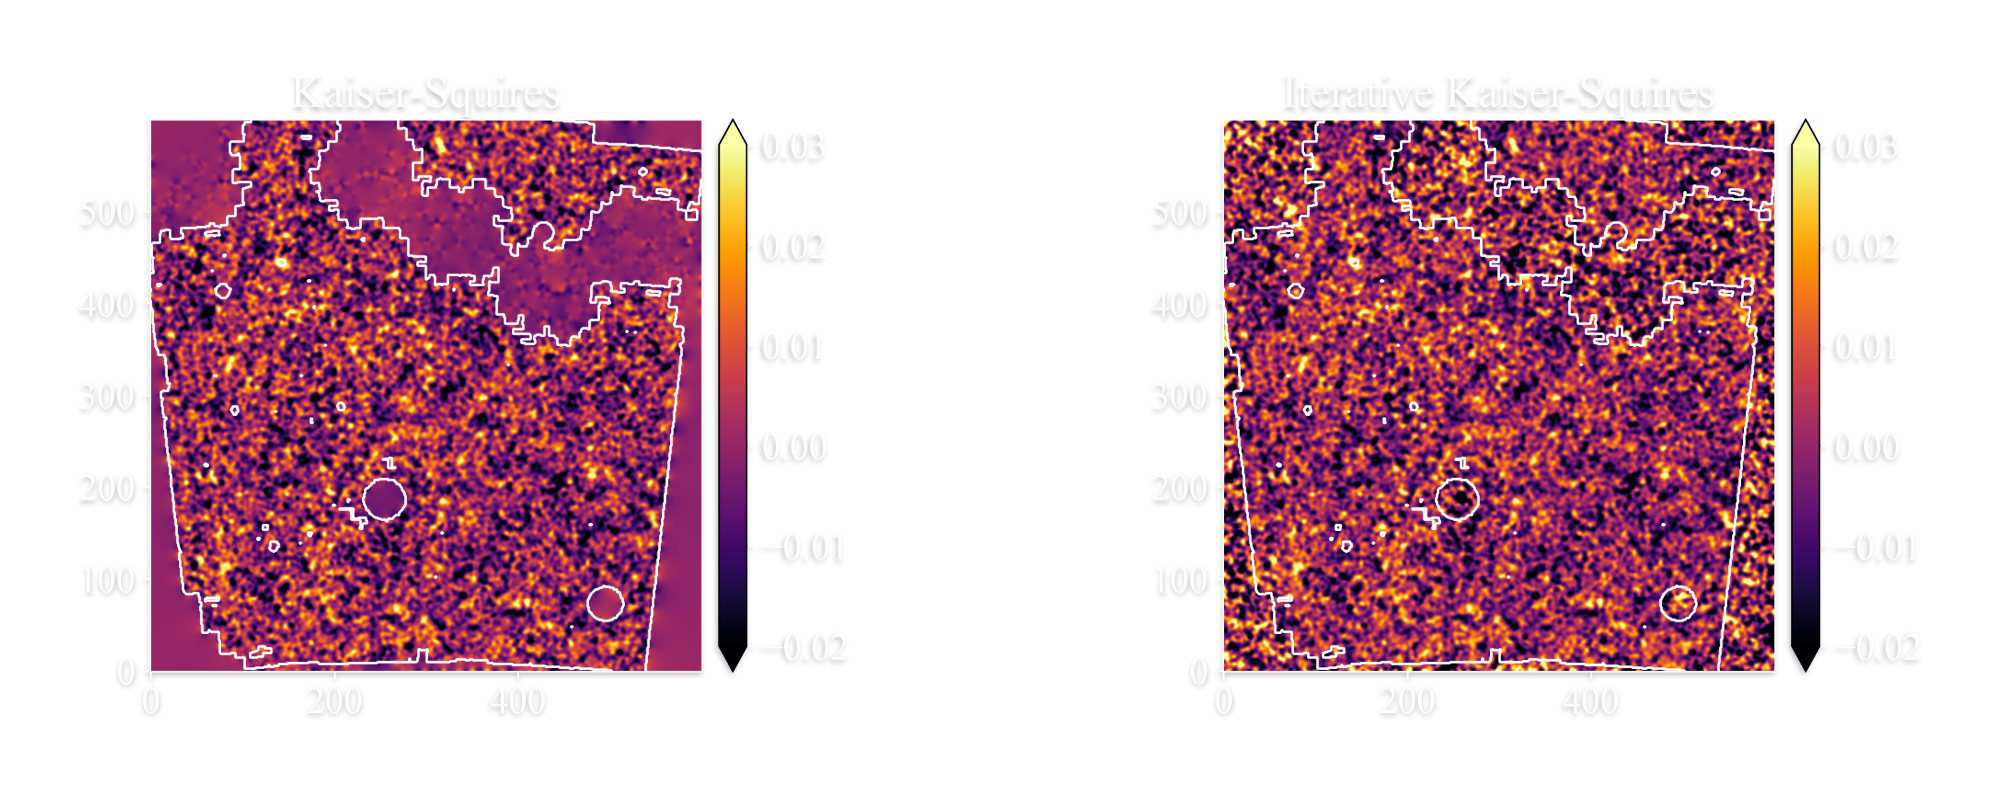
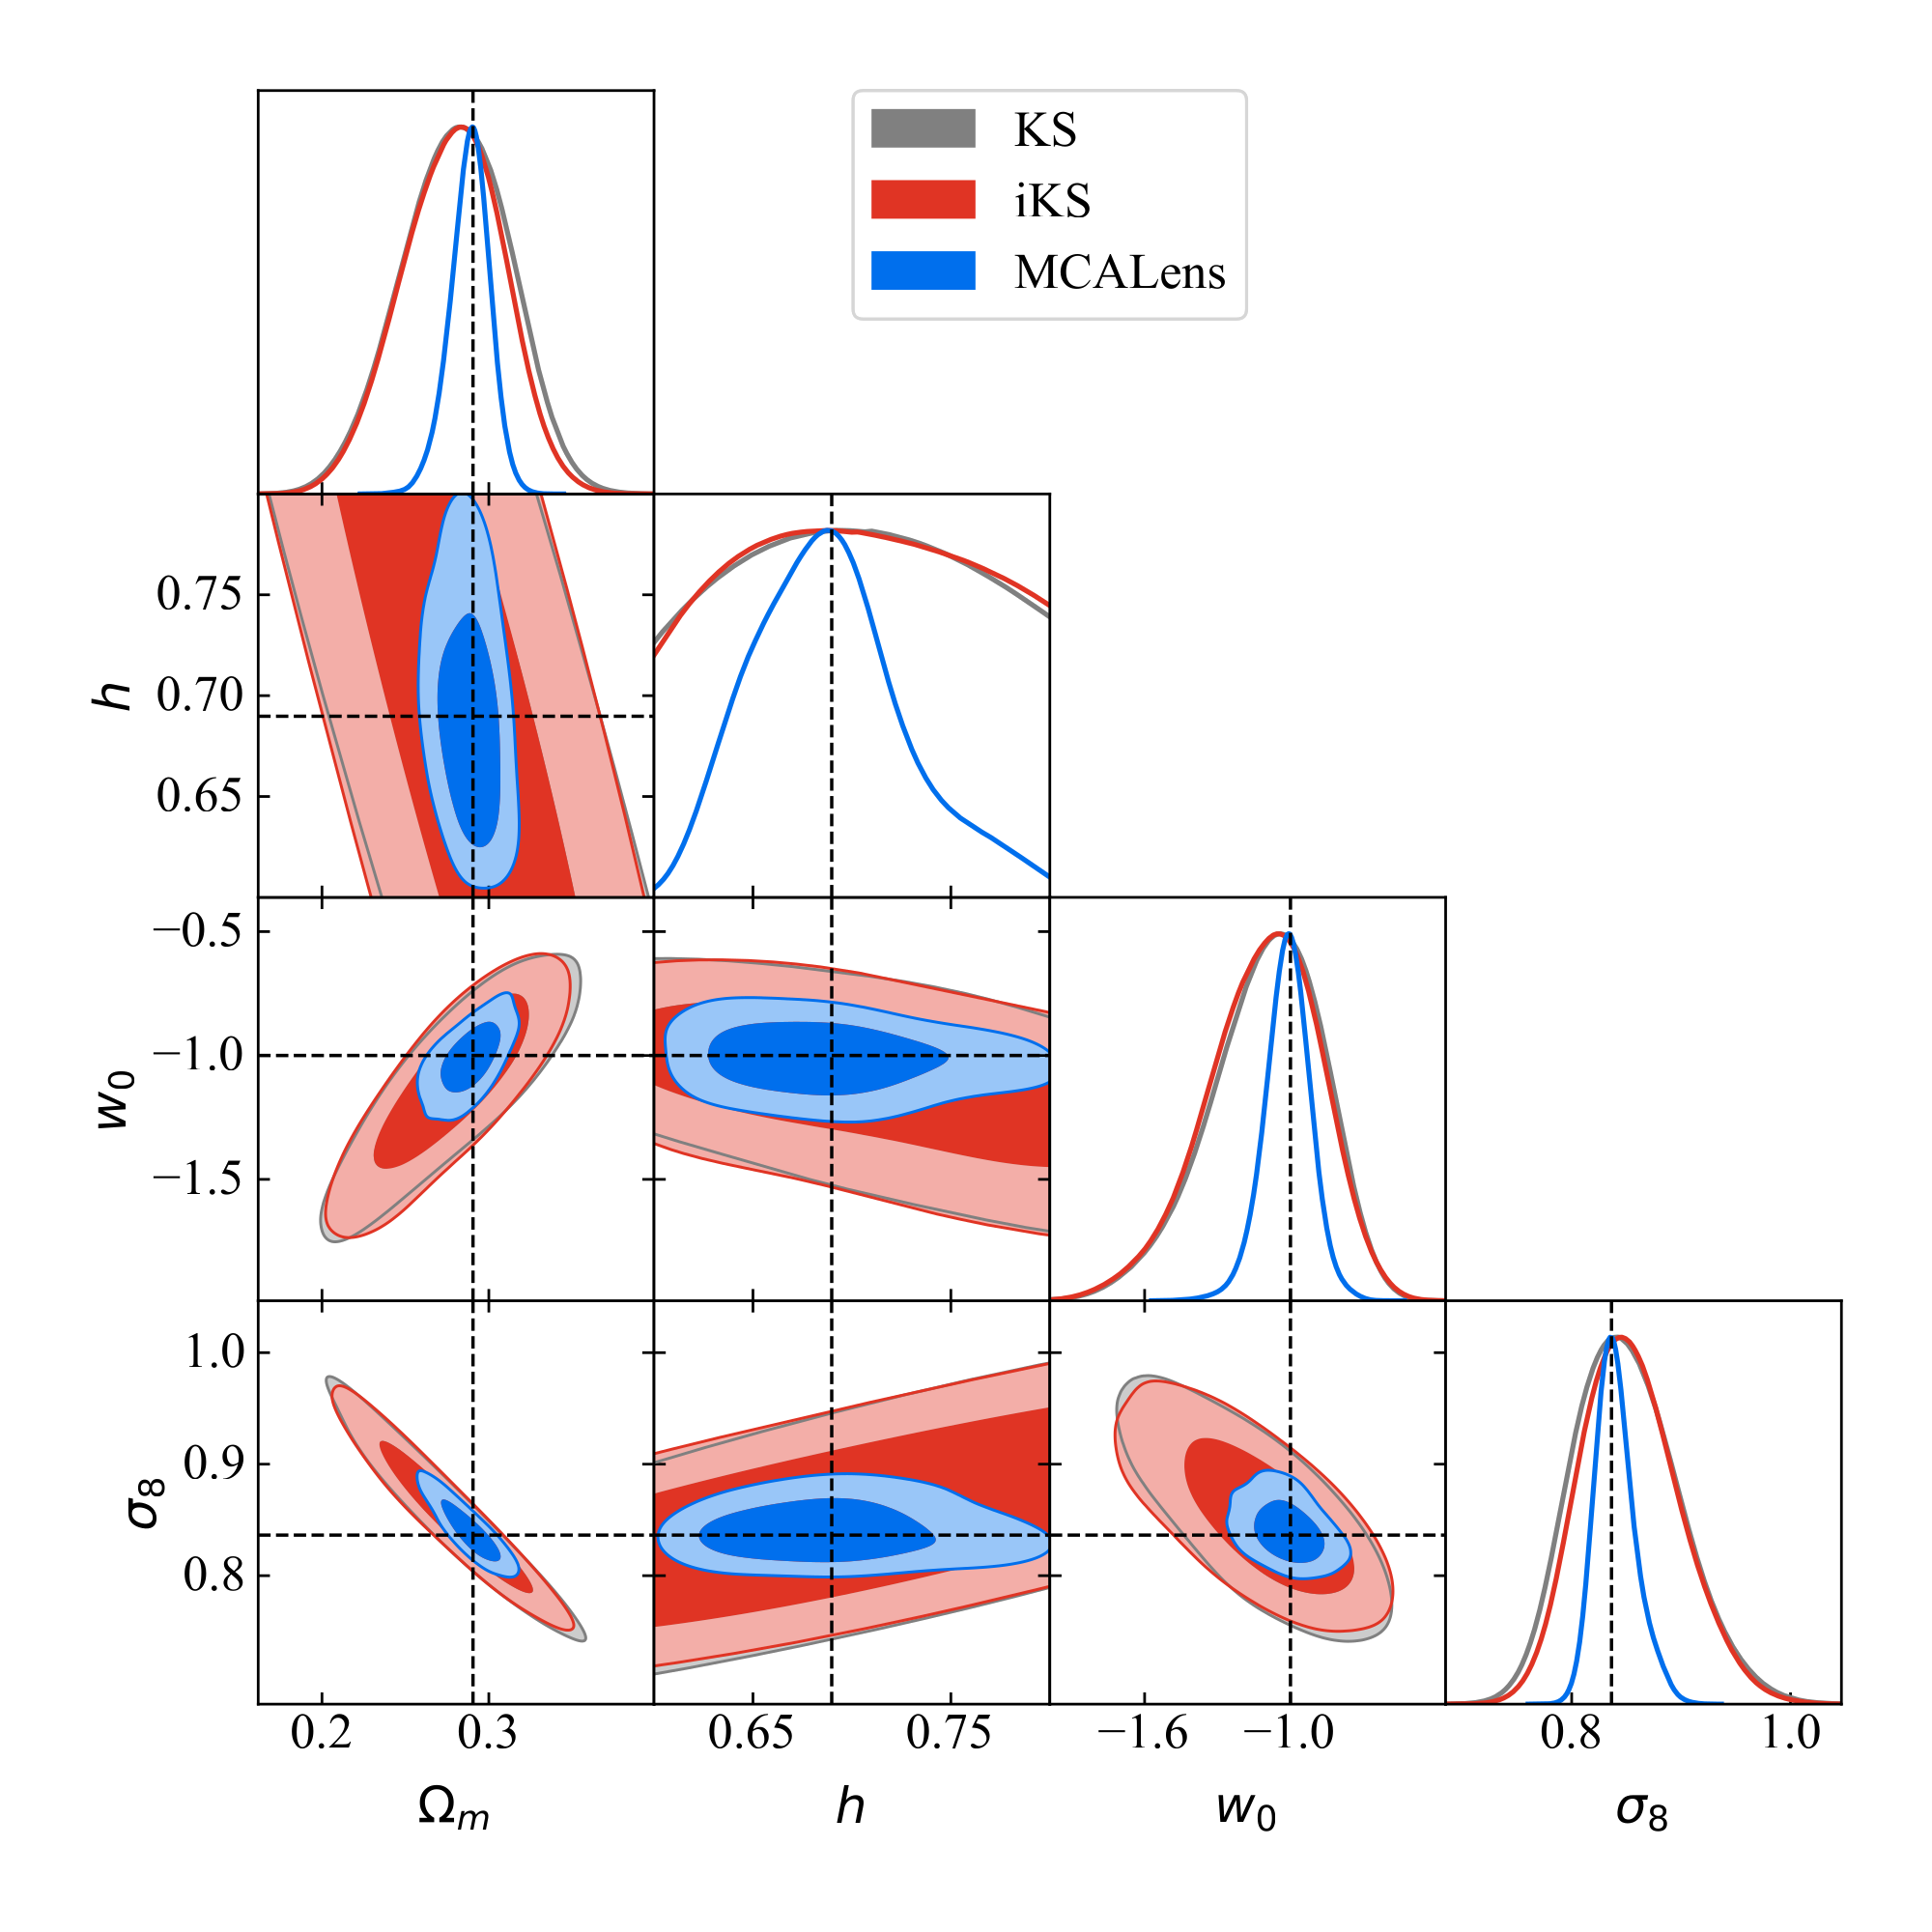
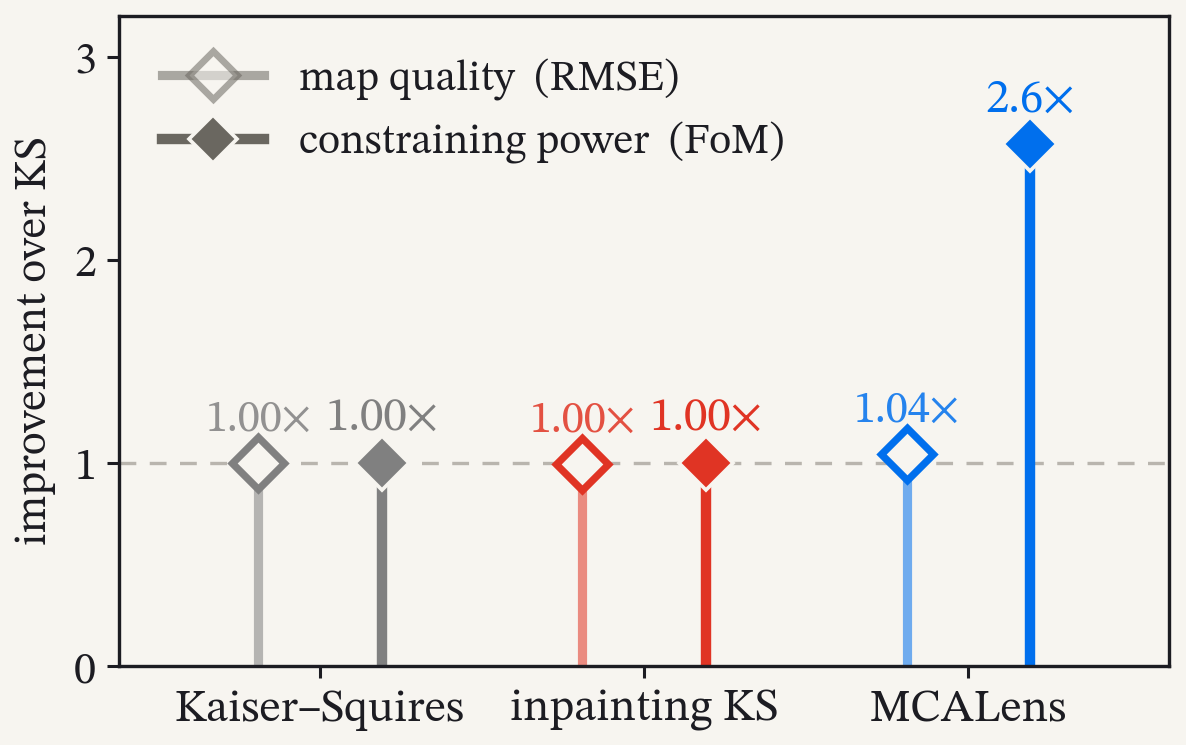
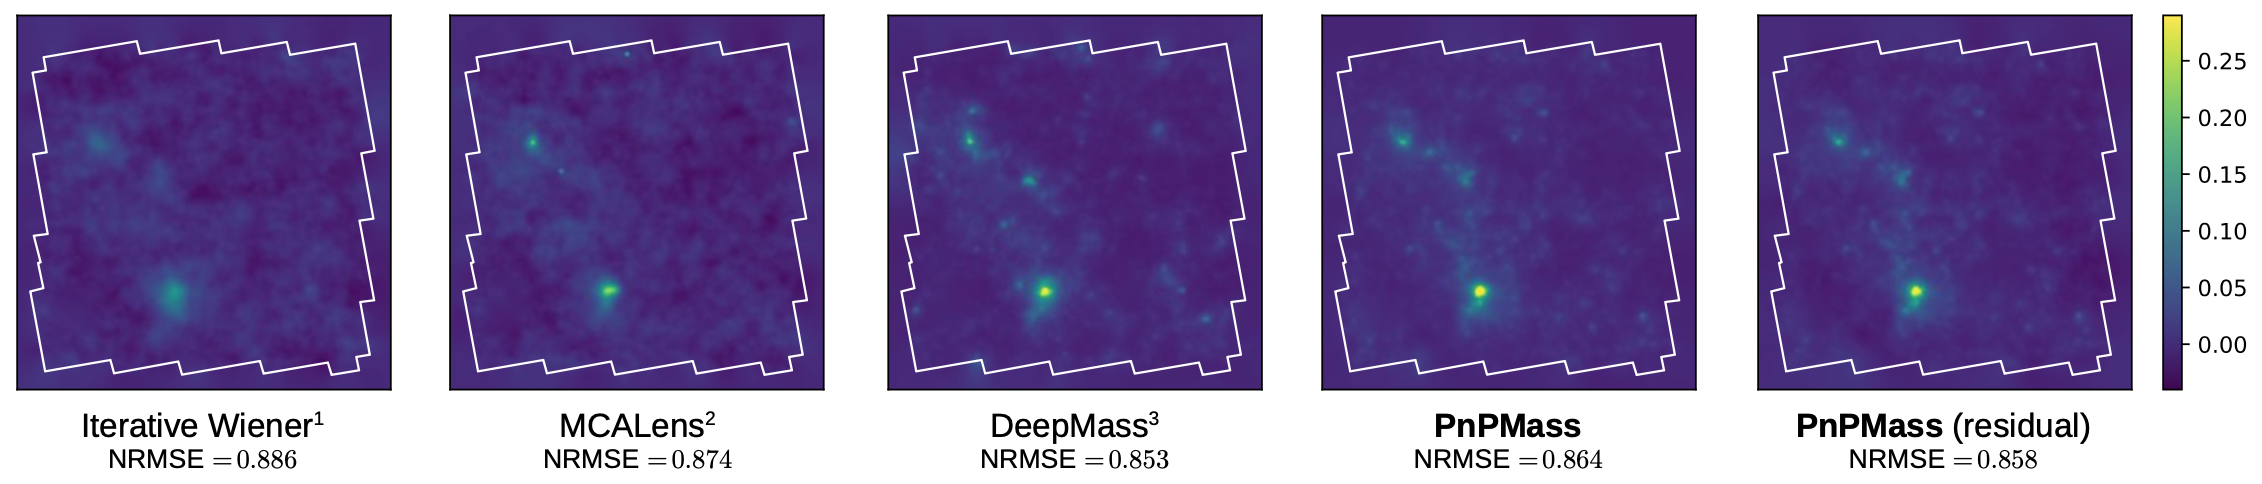
A practical question for Euclid: is an advanced reconstruction method worth the effort, or is any reasonable method good enough?
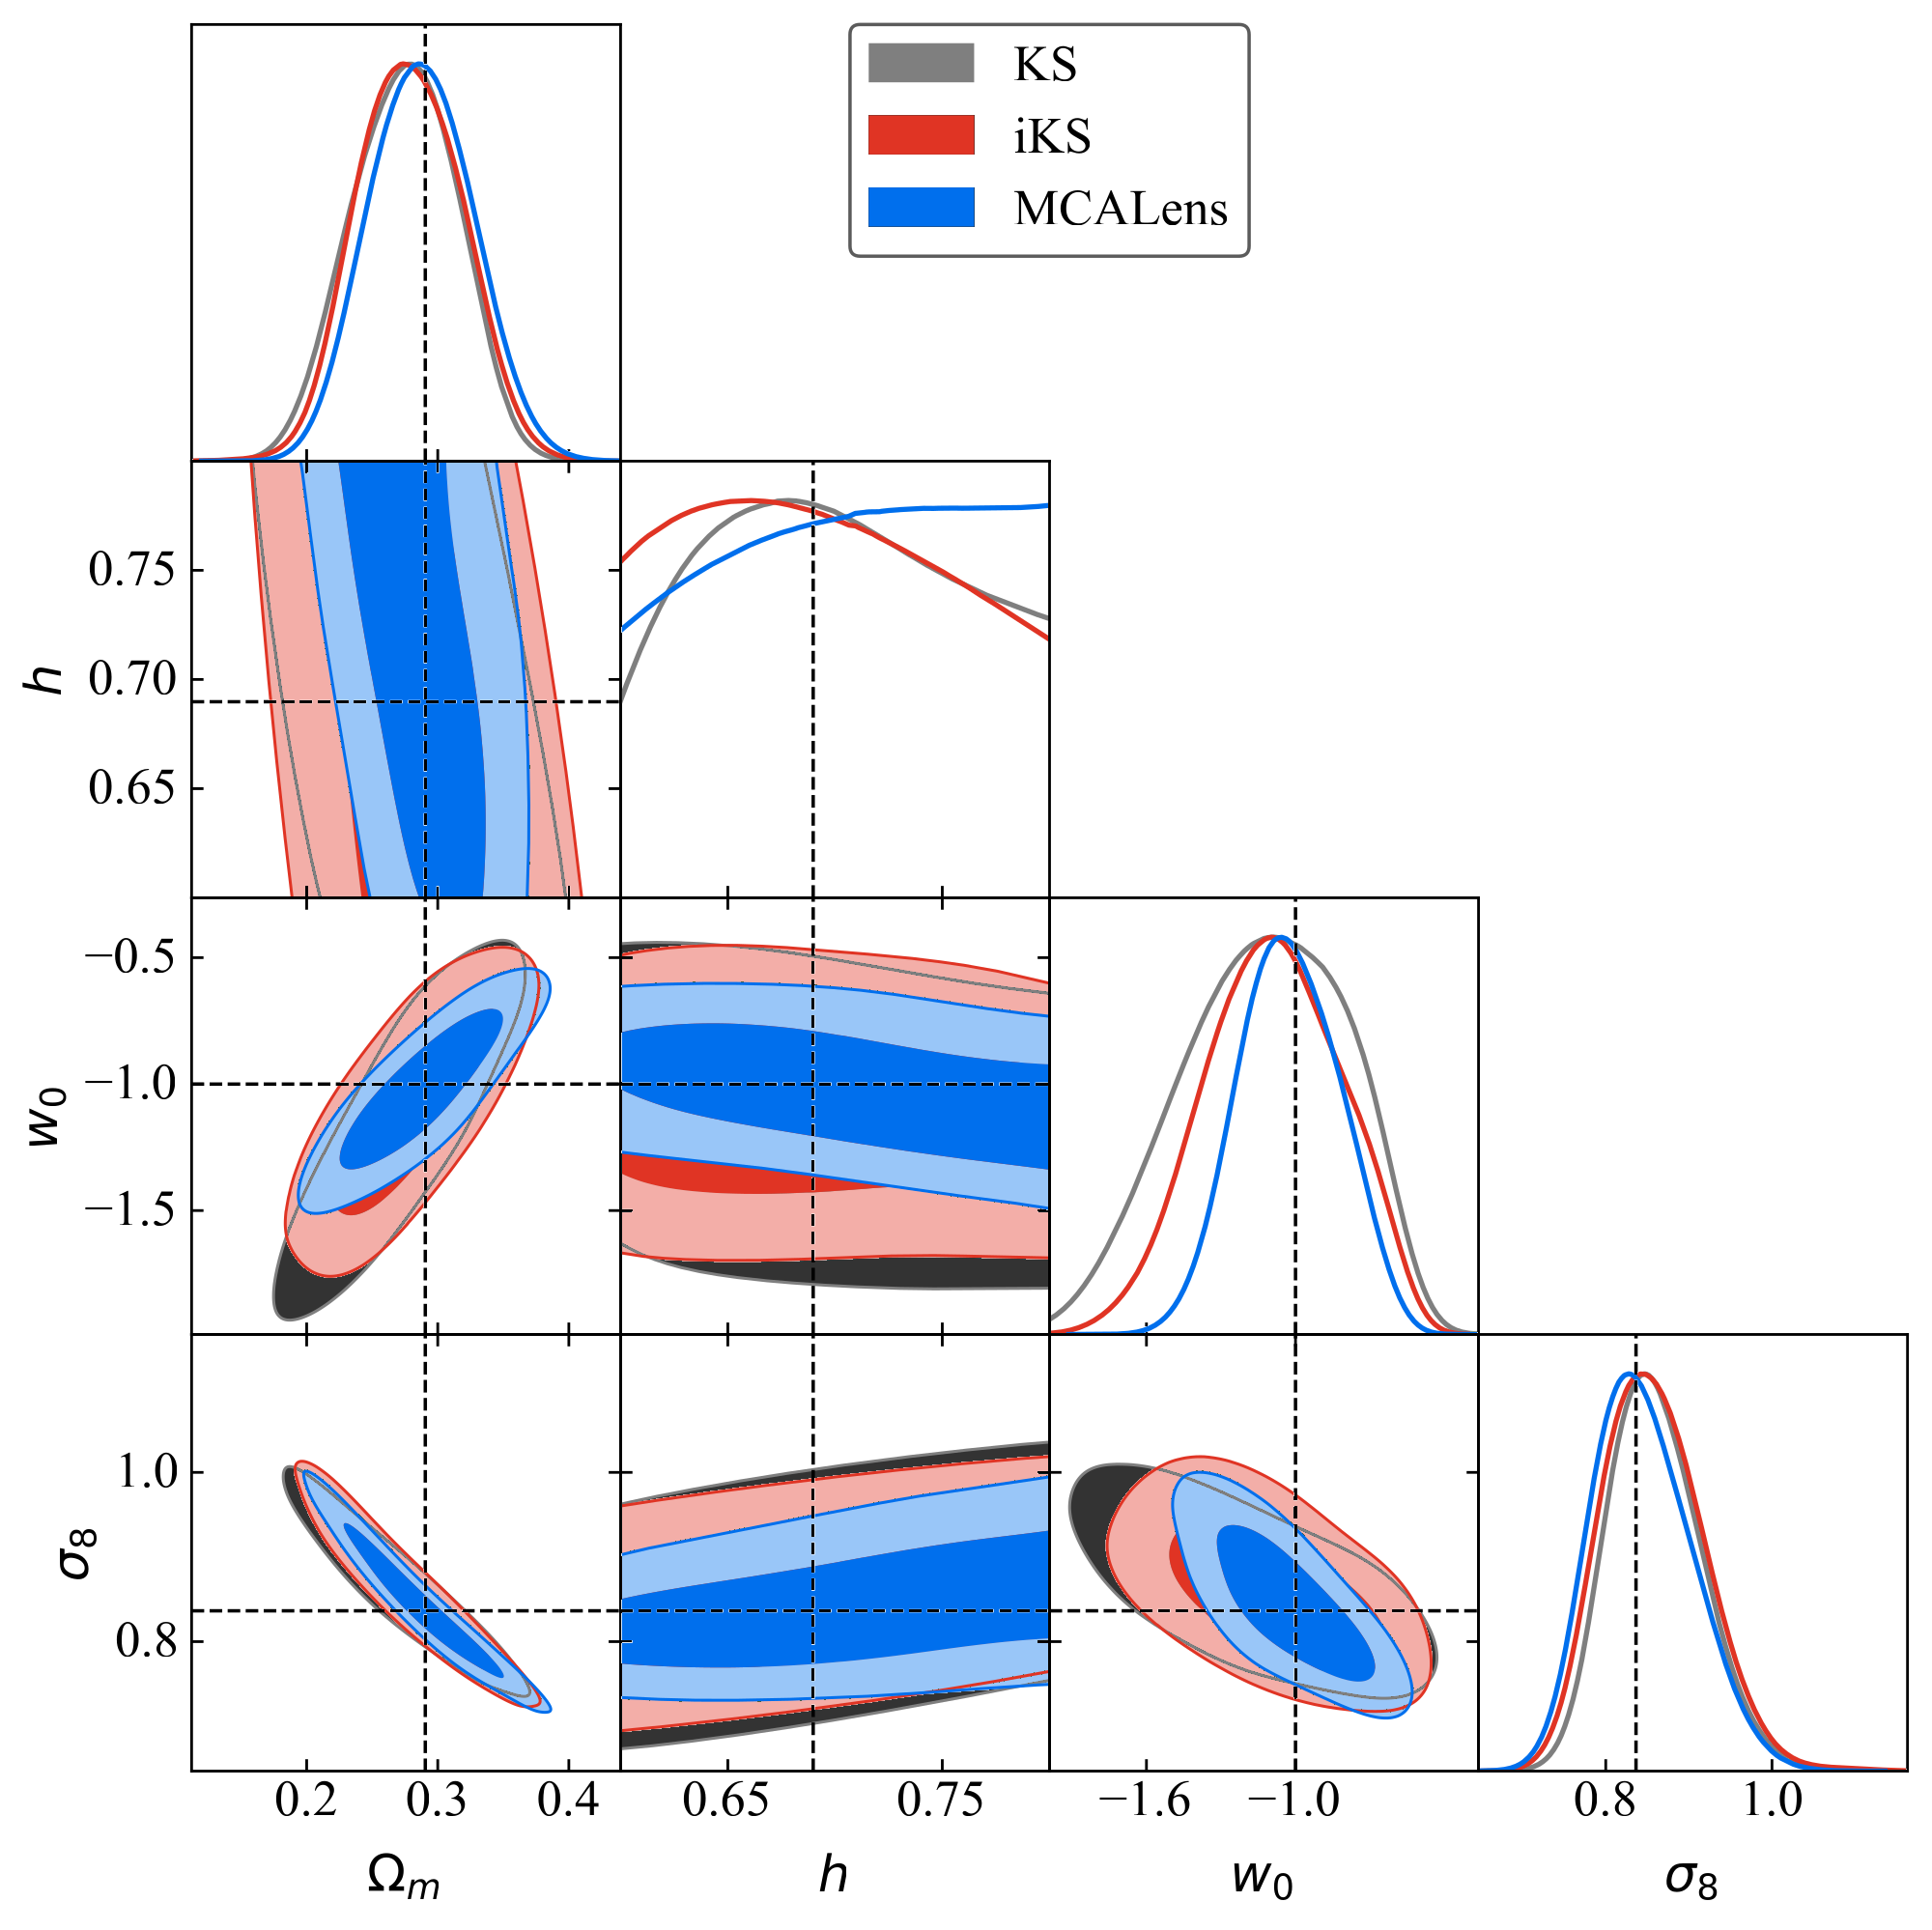
Everything else is fixed, so any change in the posterior comes from the reconstruction.
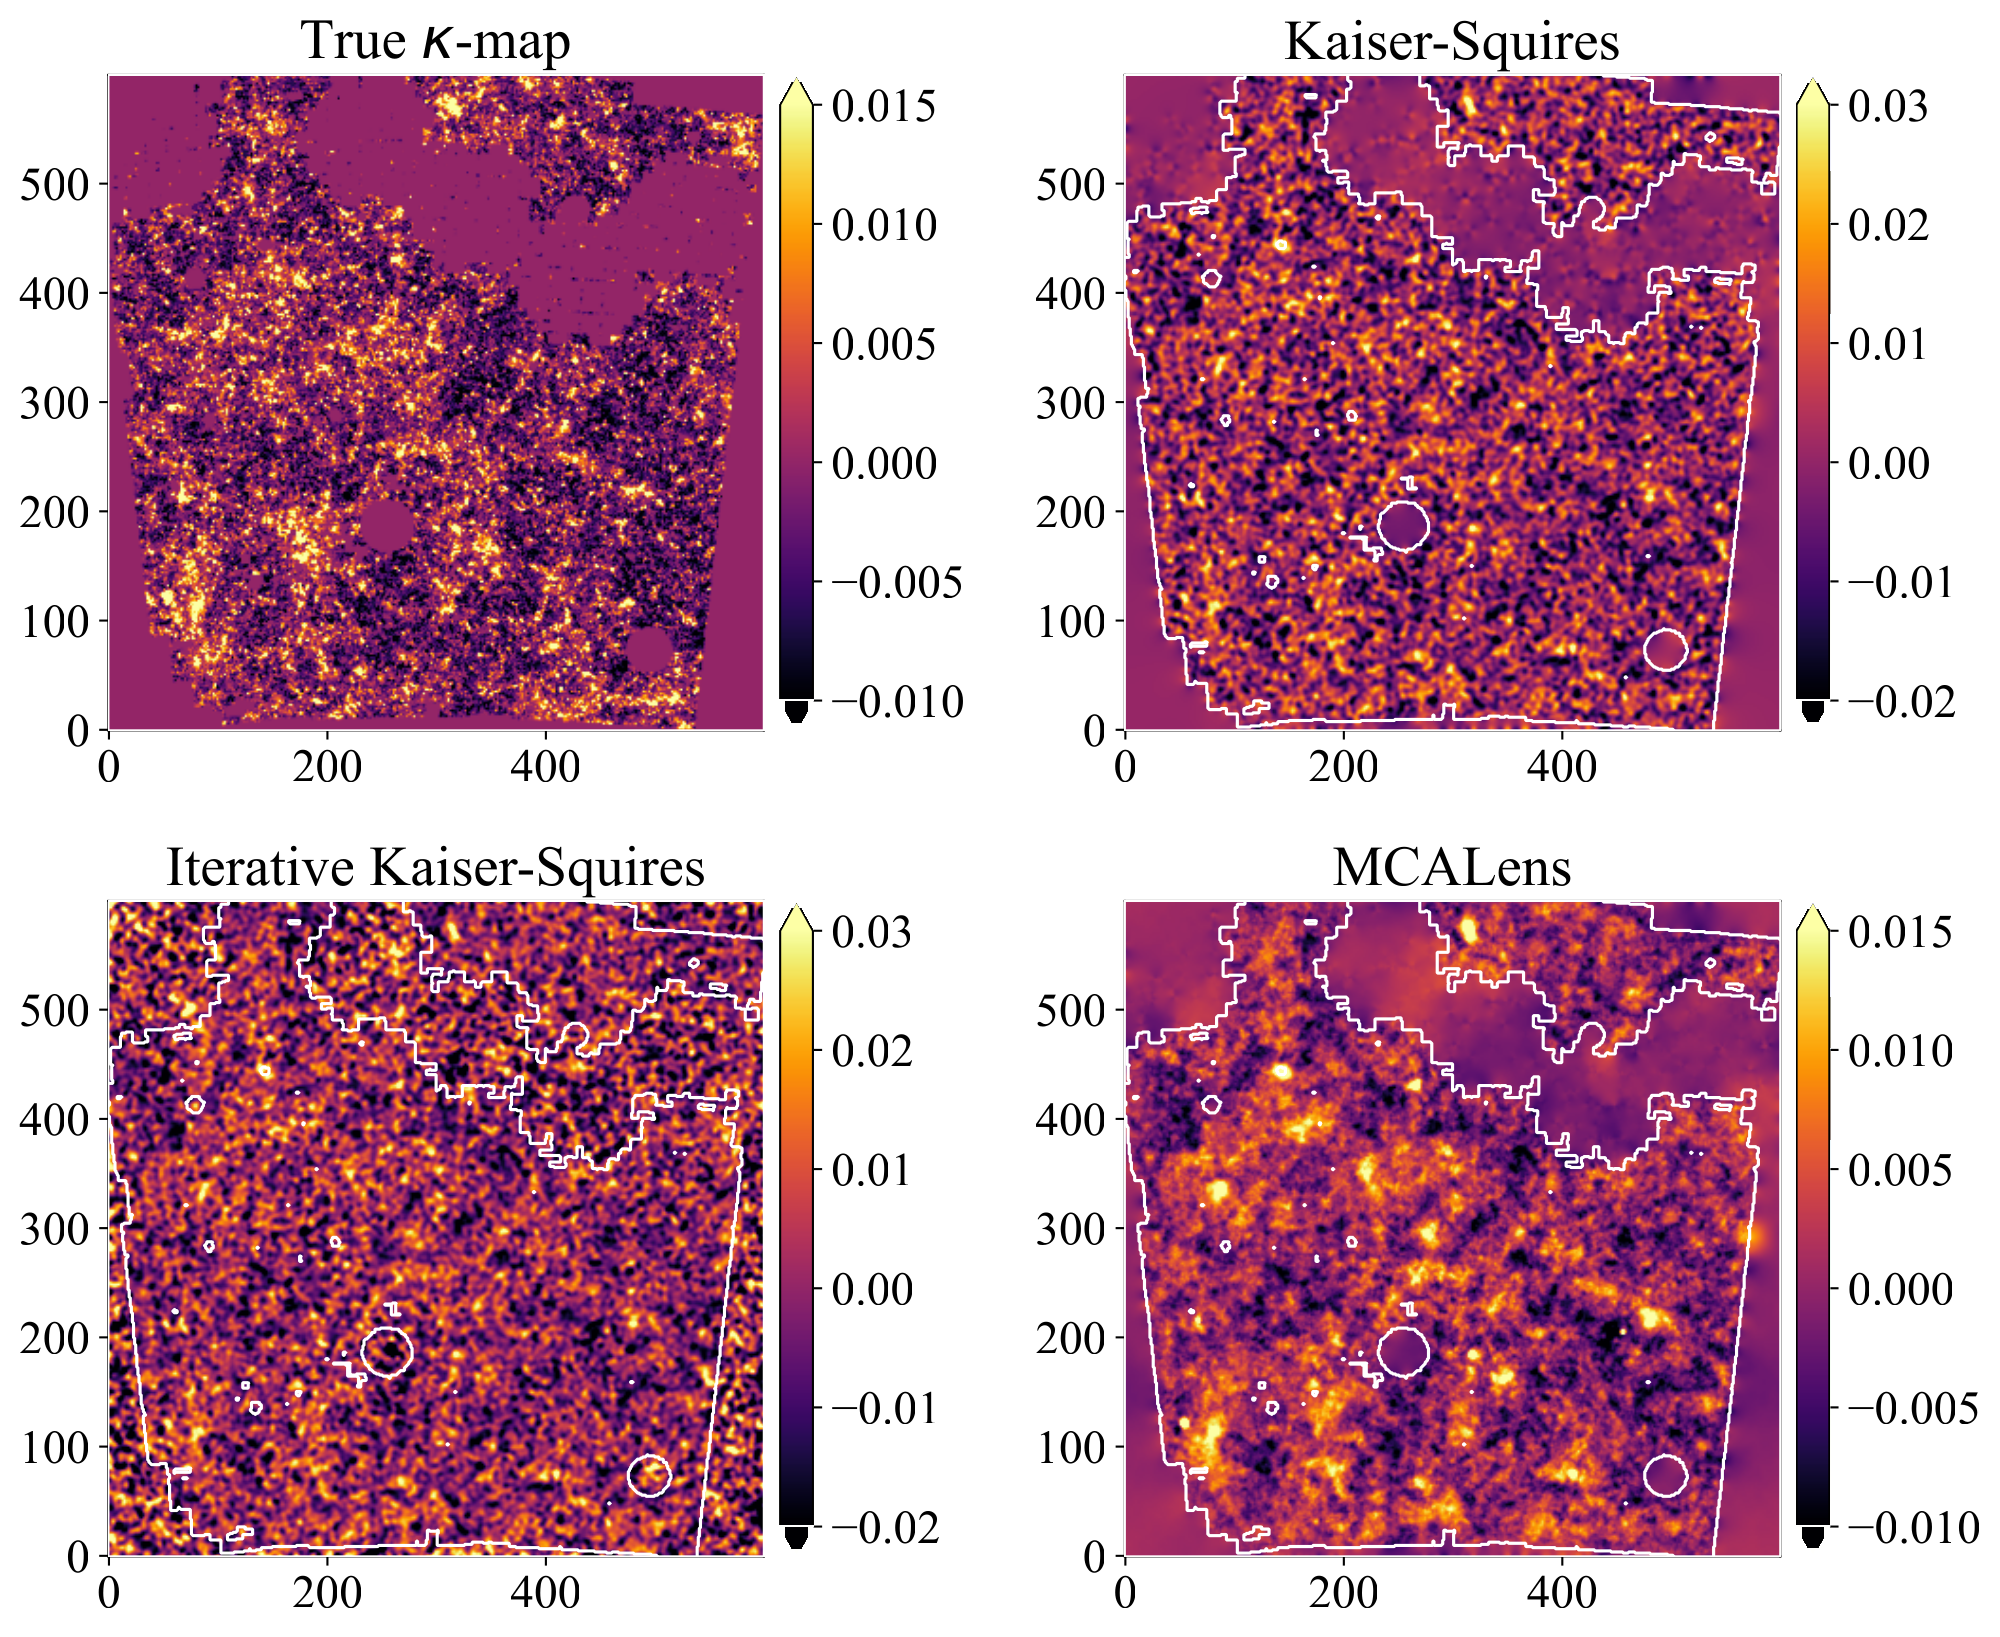
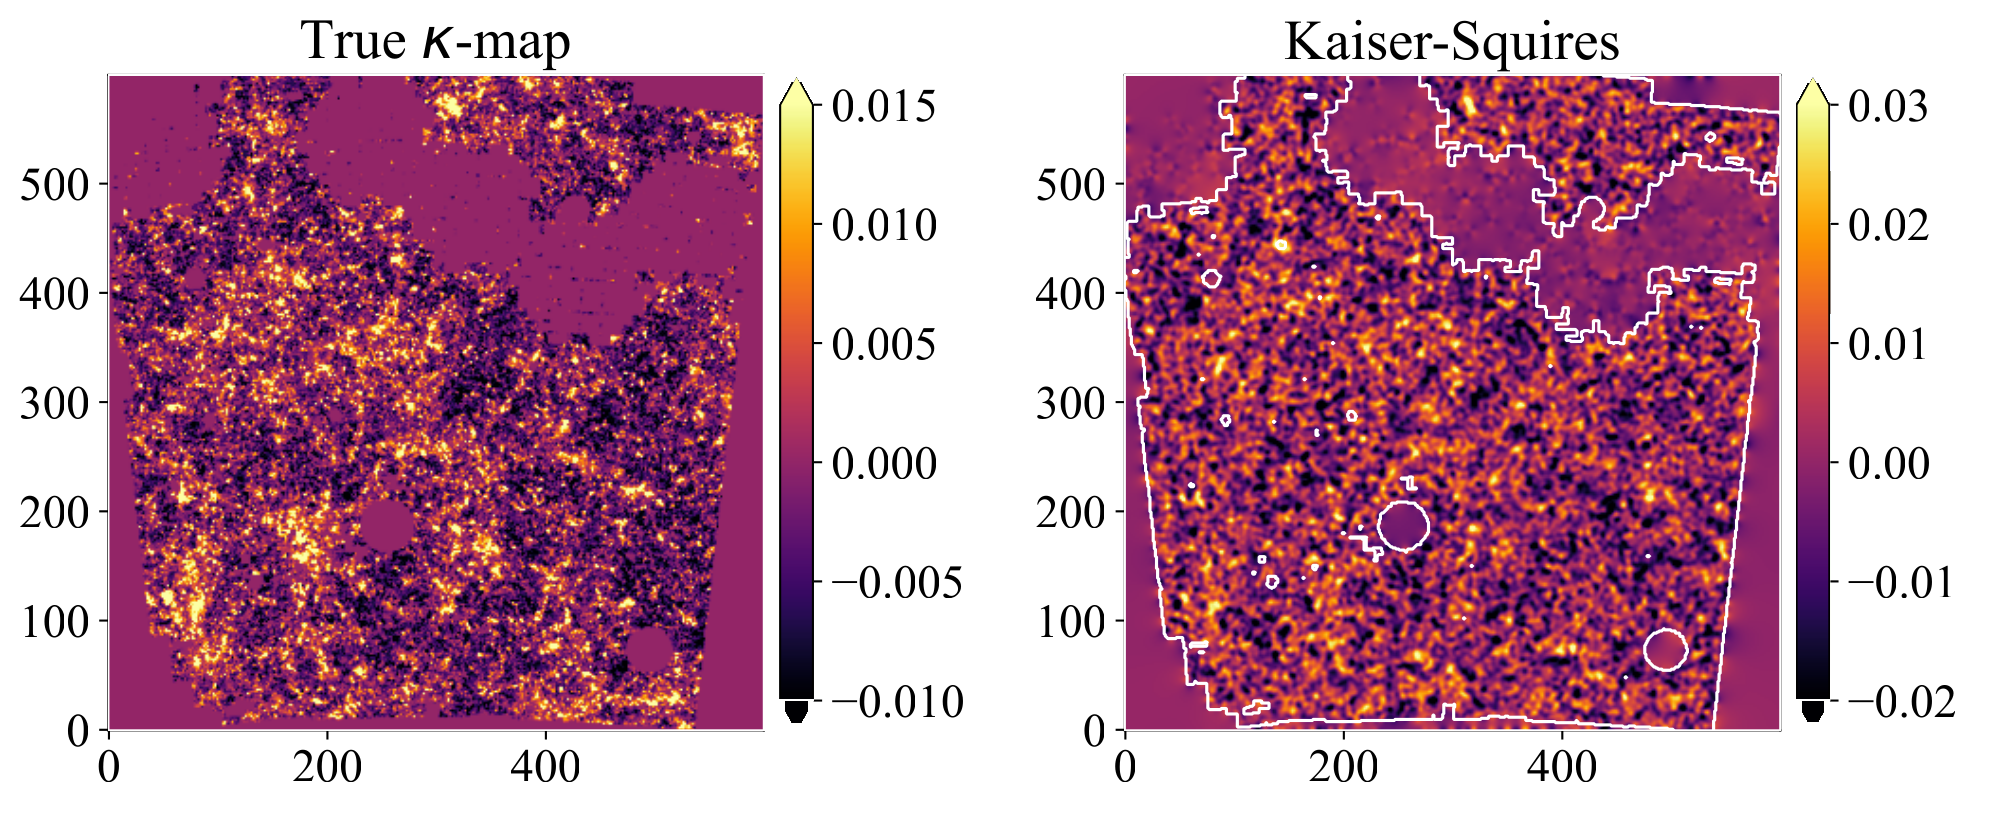
Mass mapping has been treated as a preprocessing step with little effect on the cosmology, which is why the Euclid baseline is the simplest method, Kaiser–Squires.
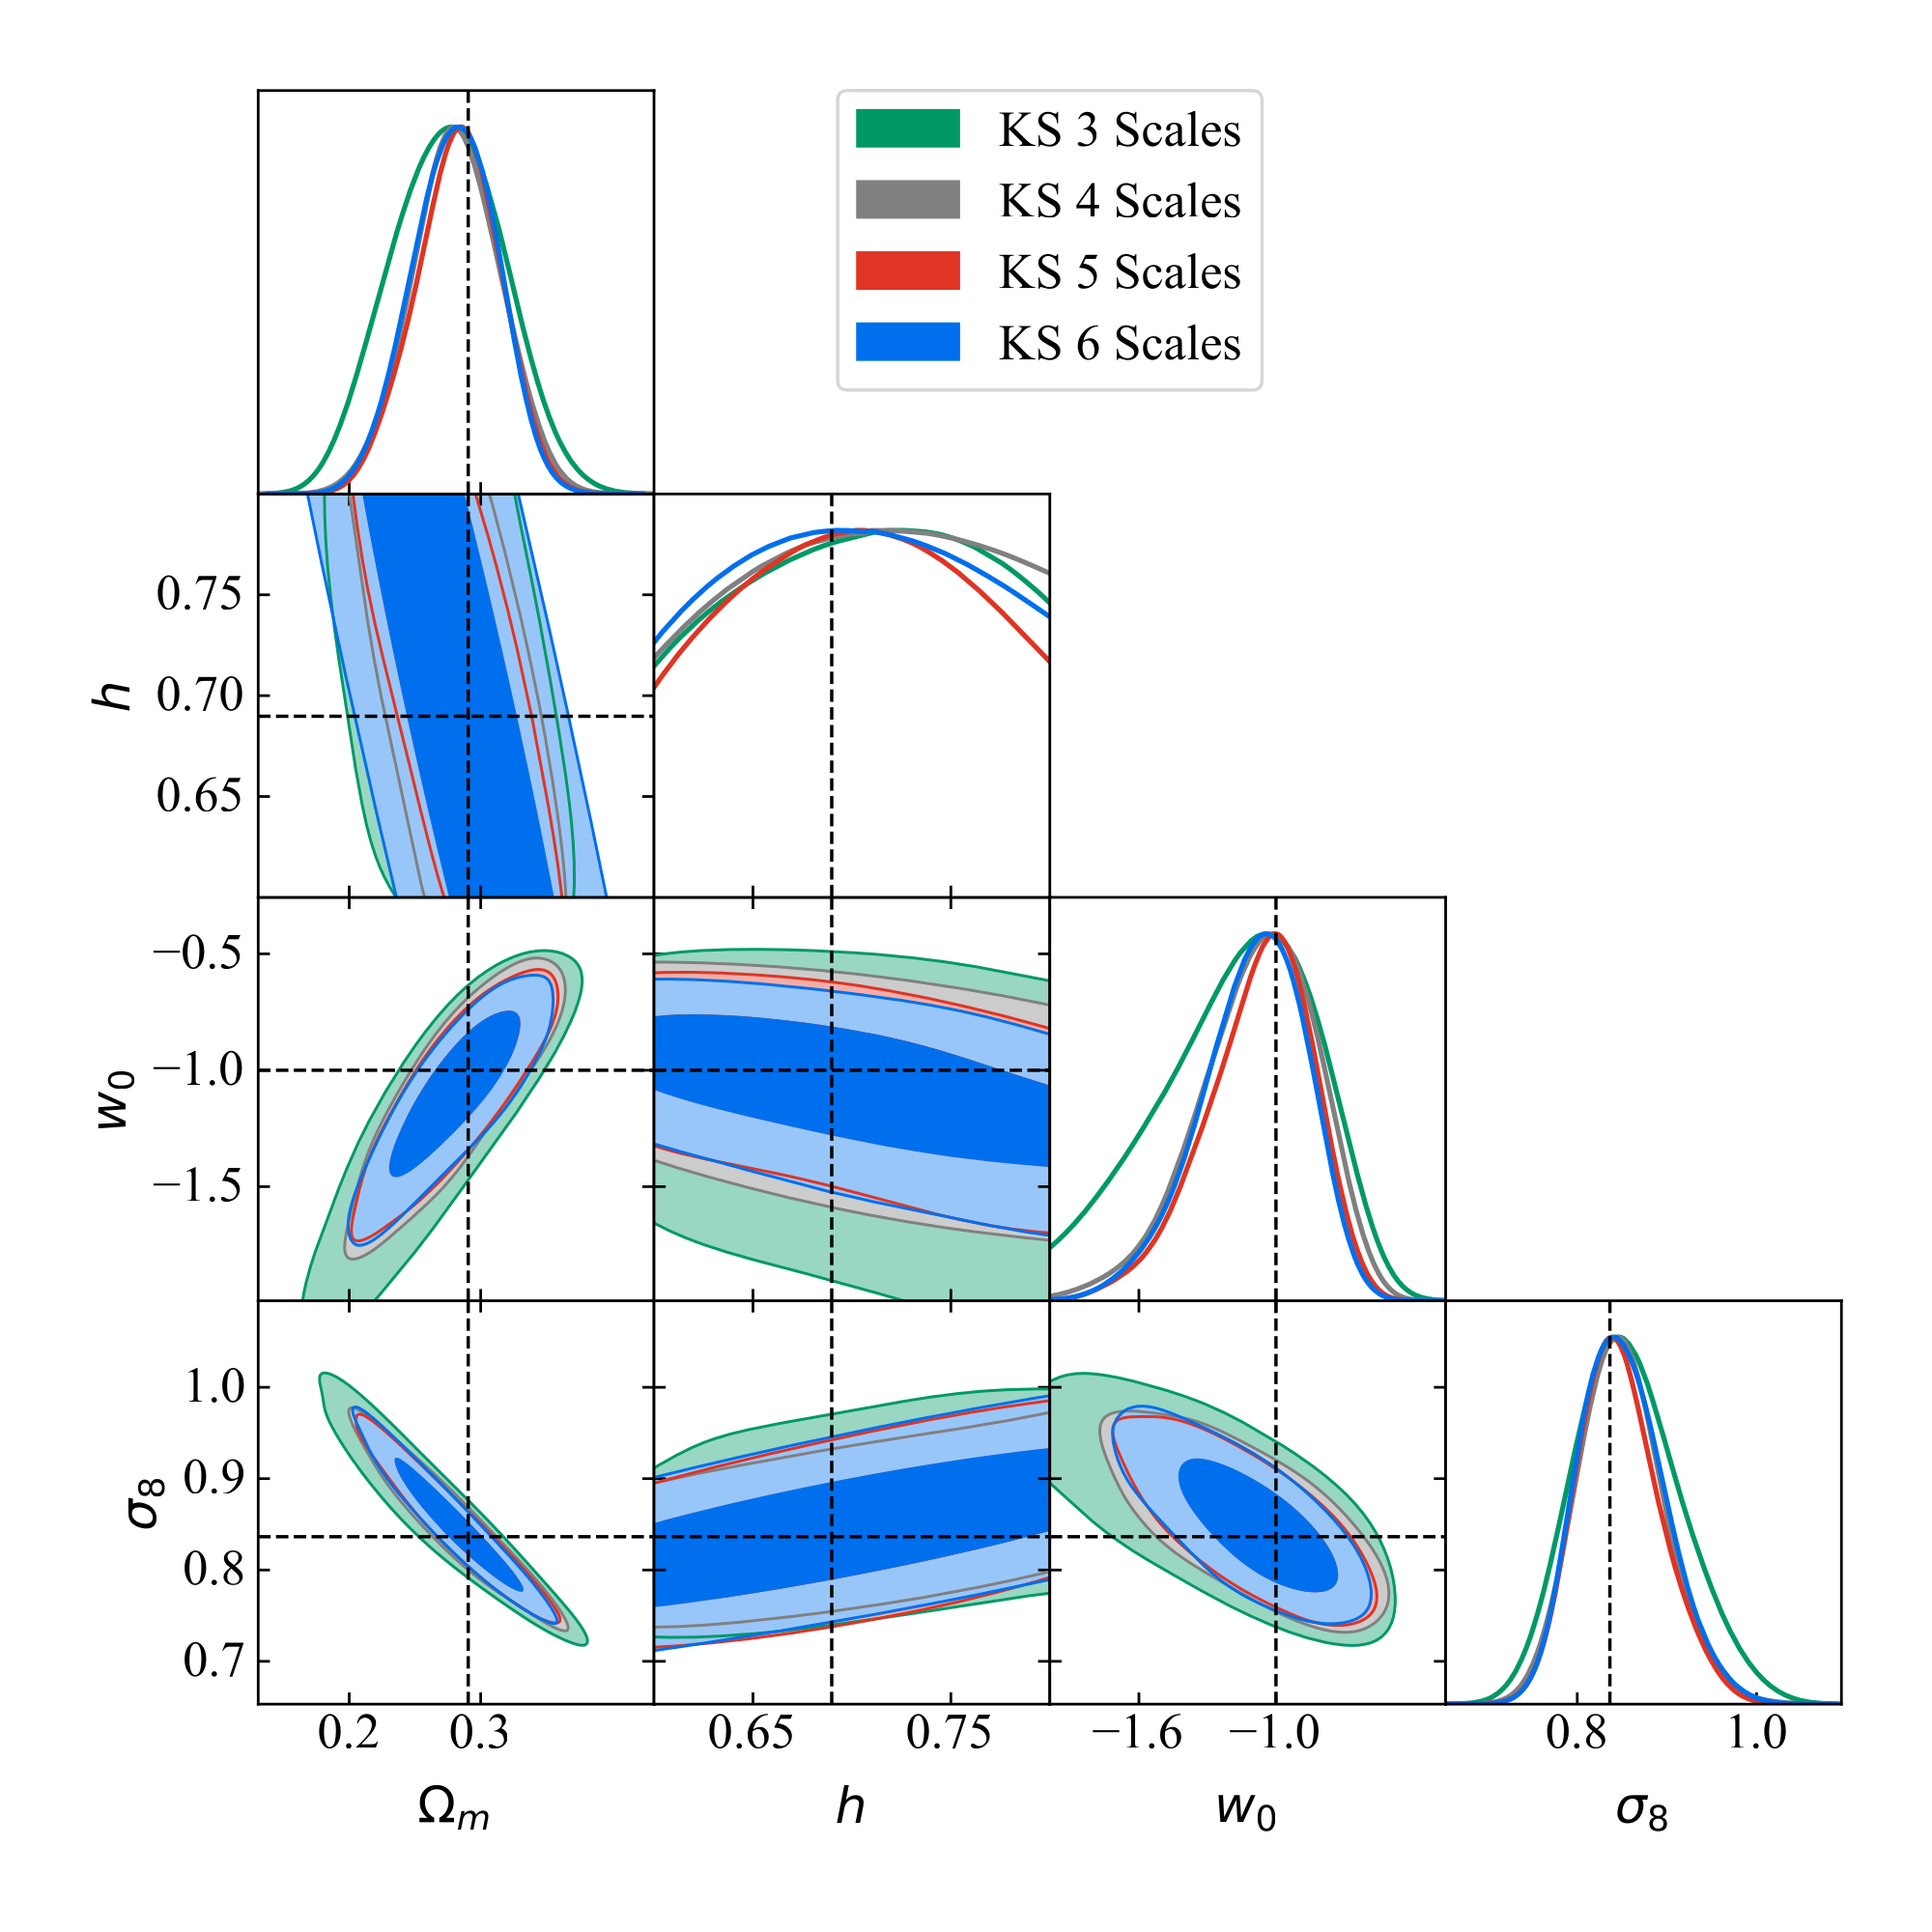
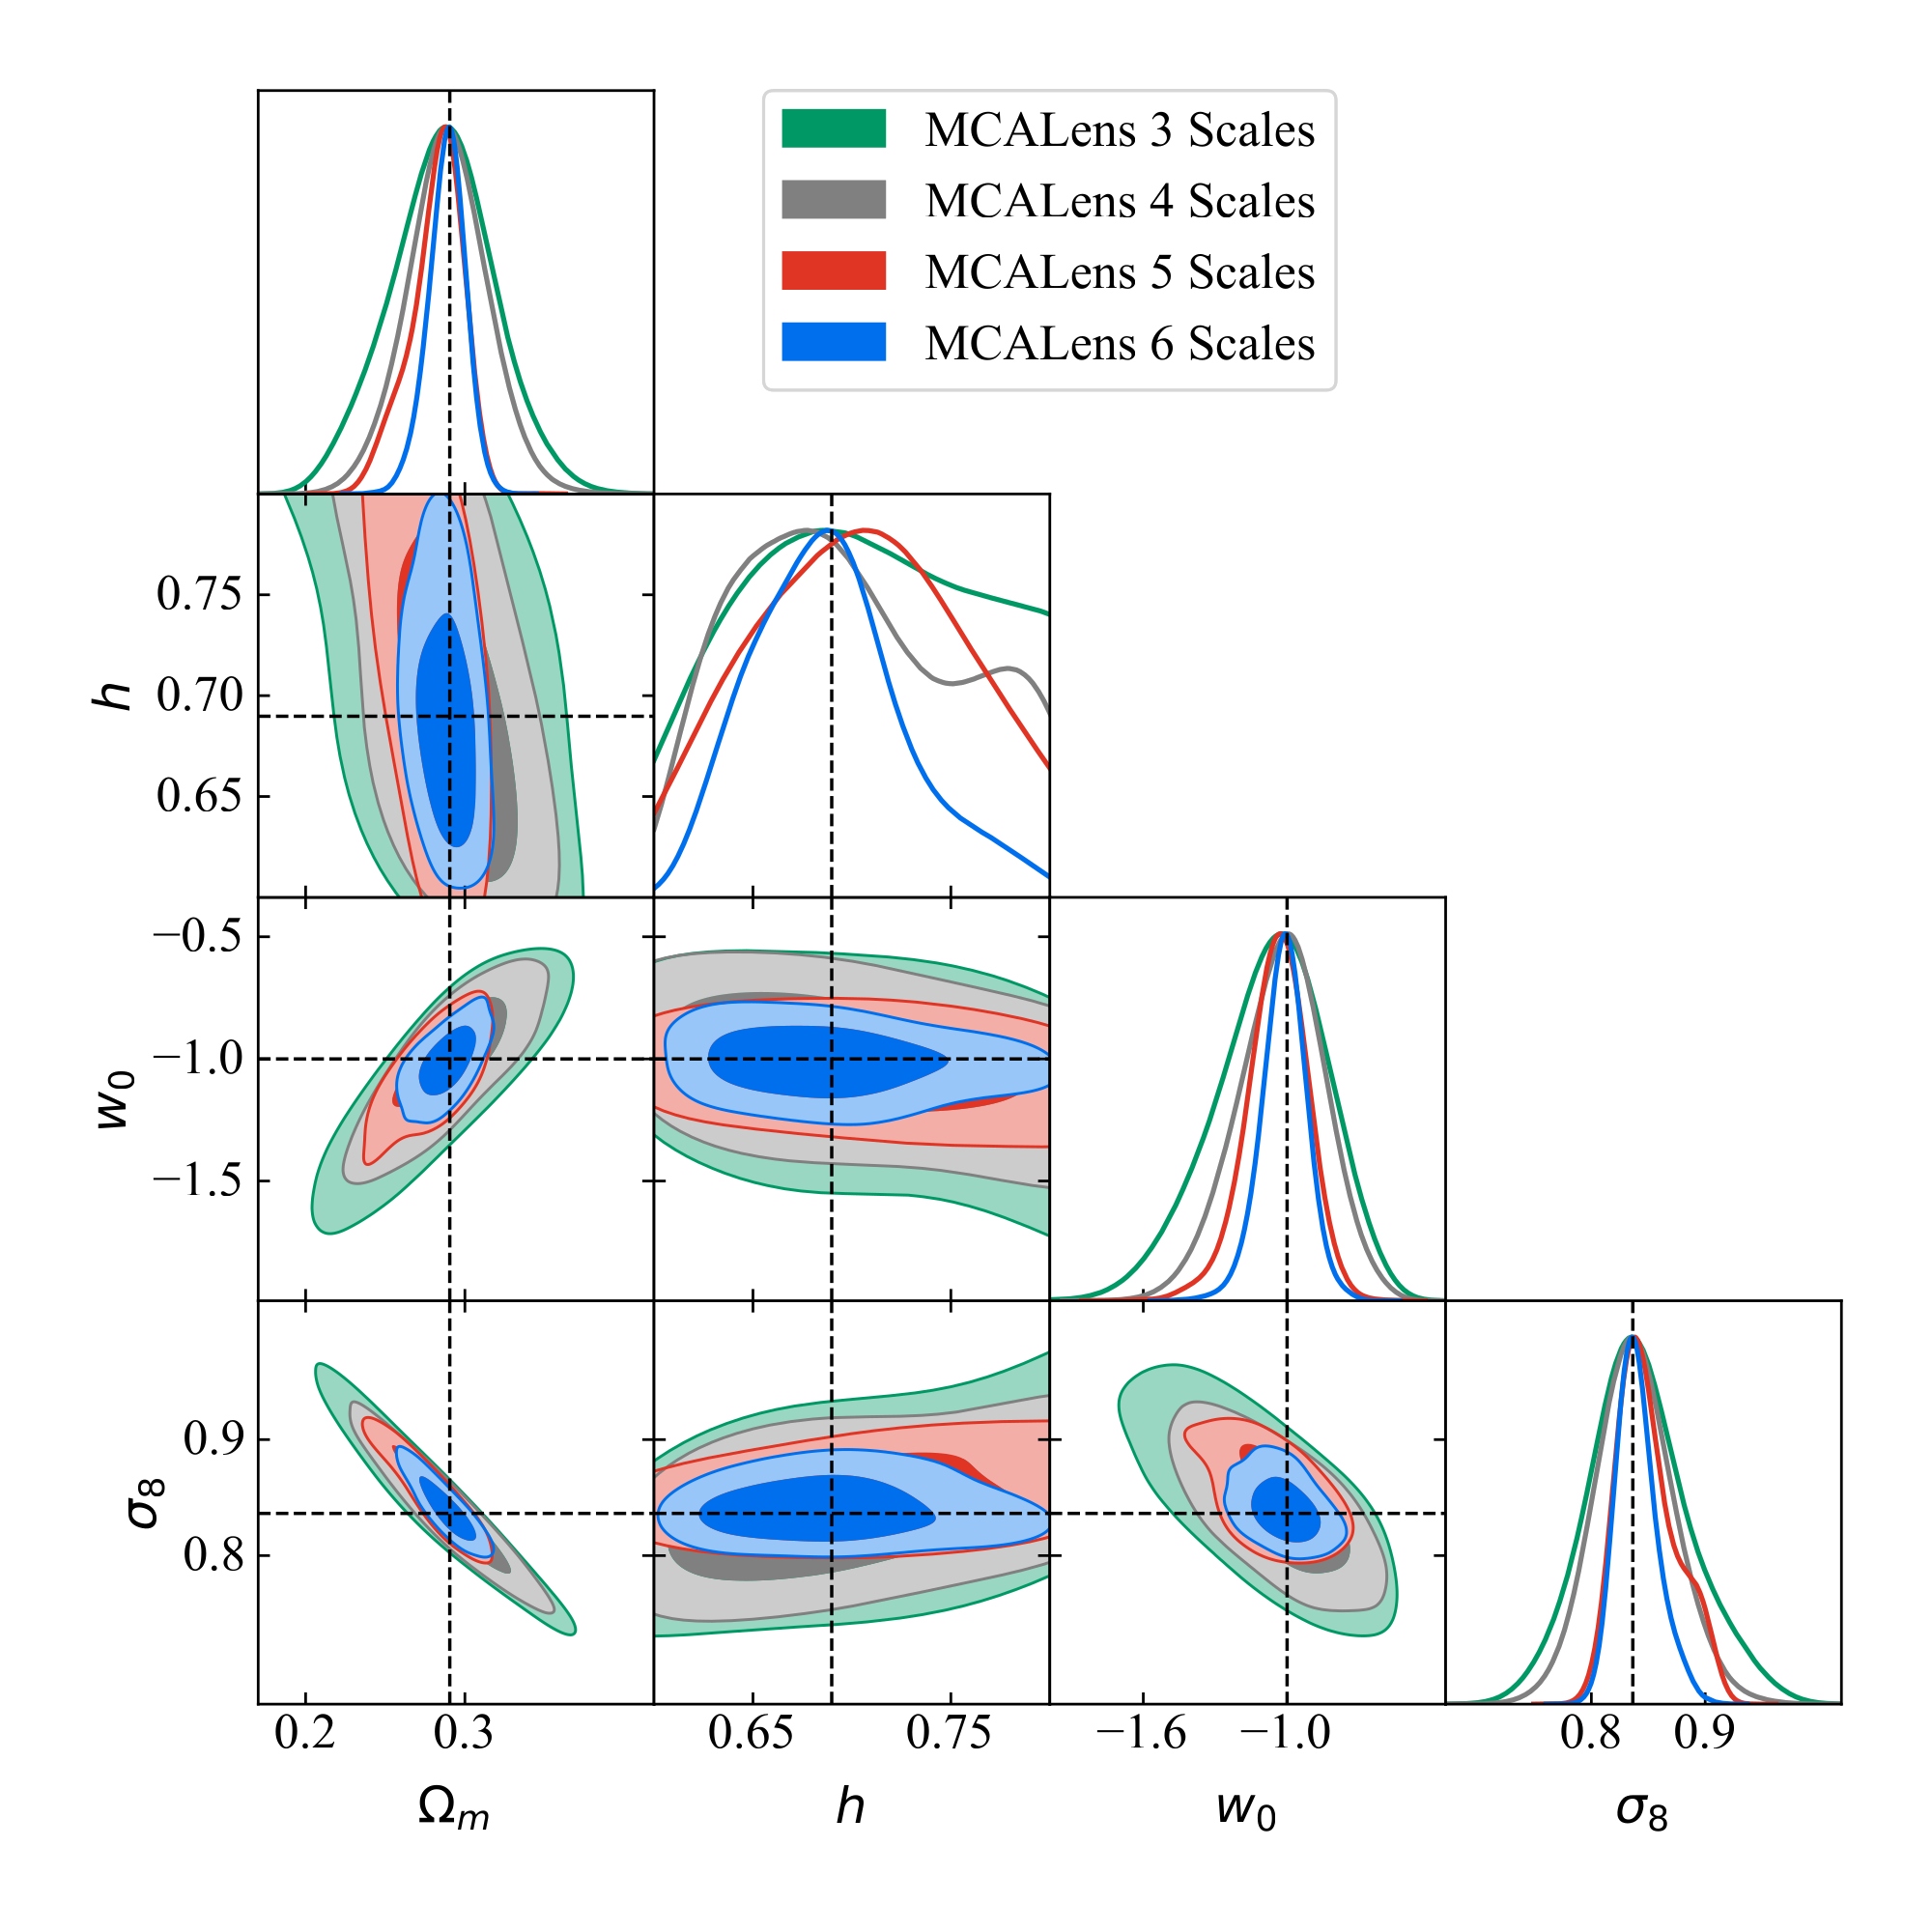
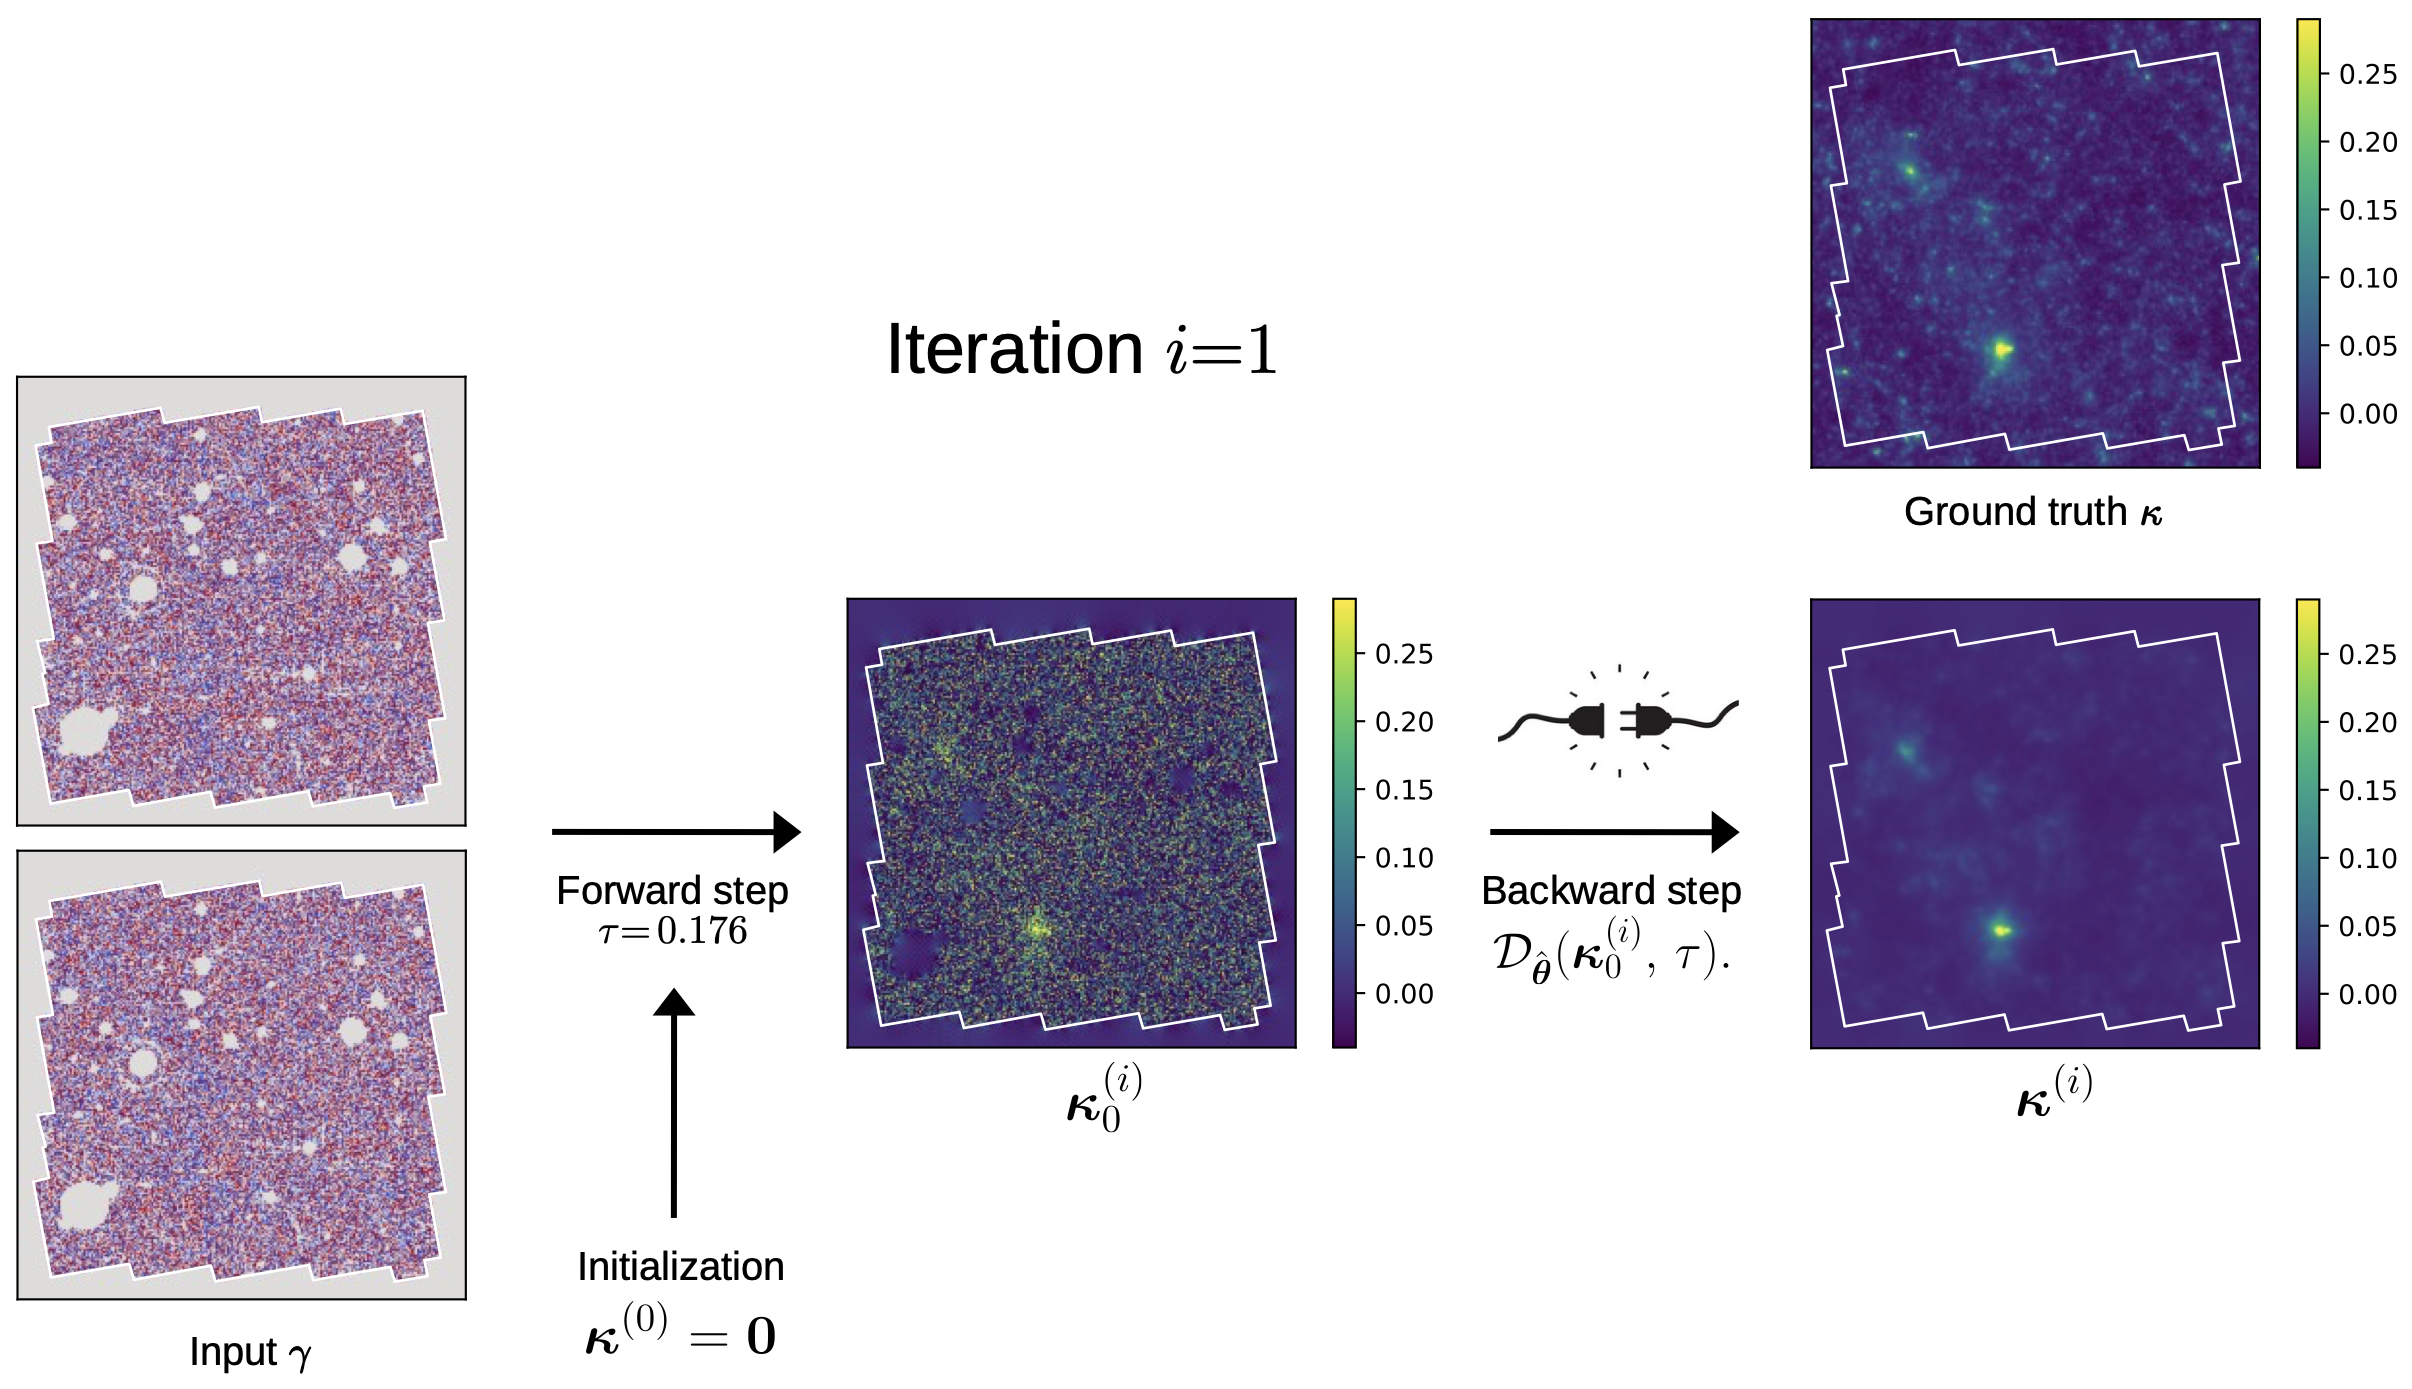
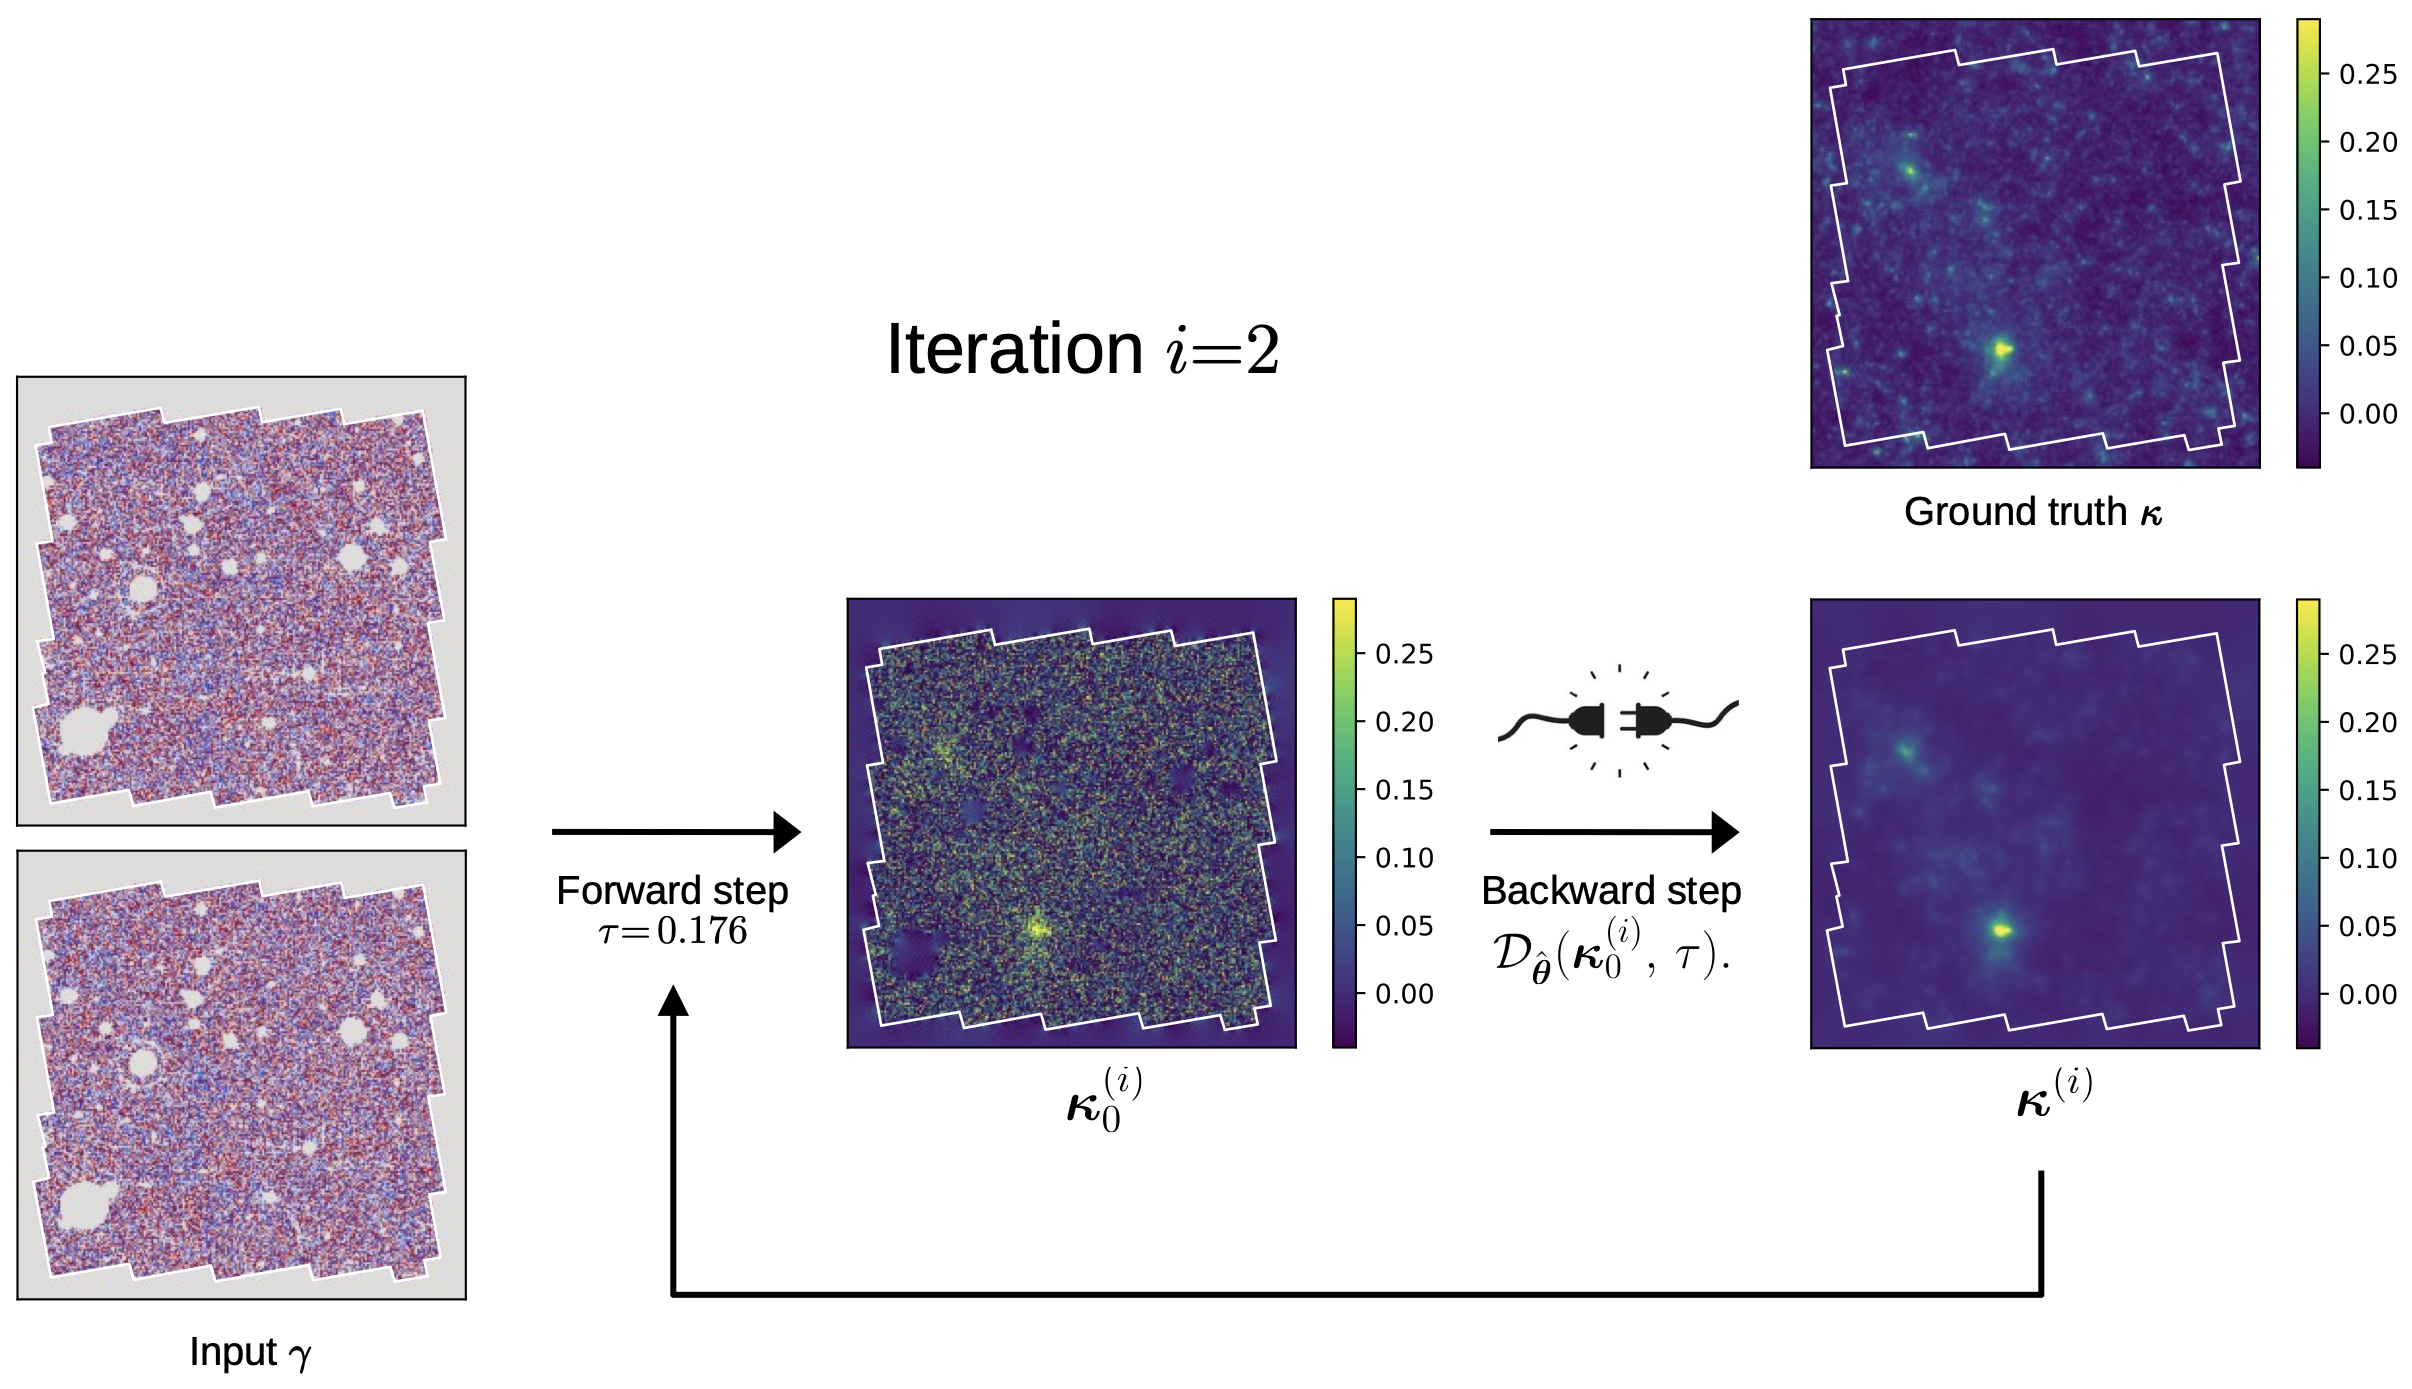
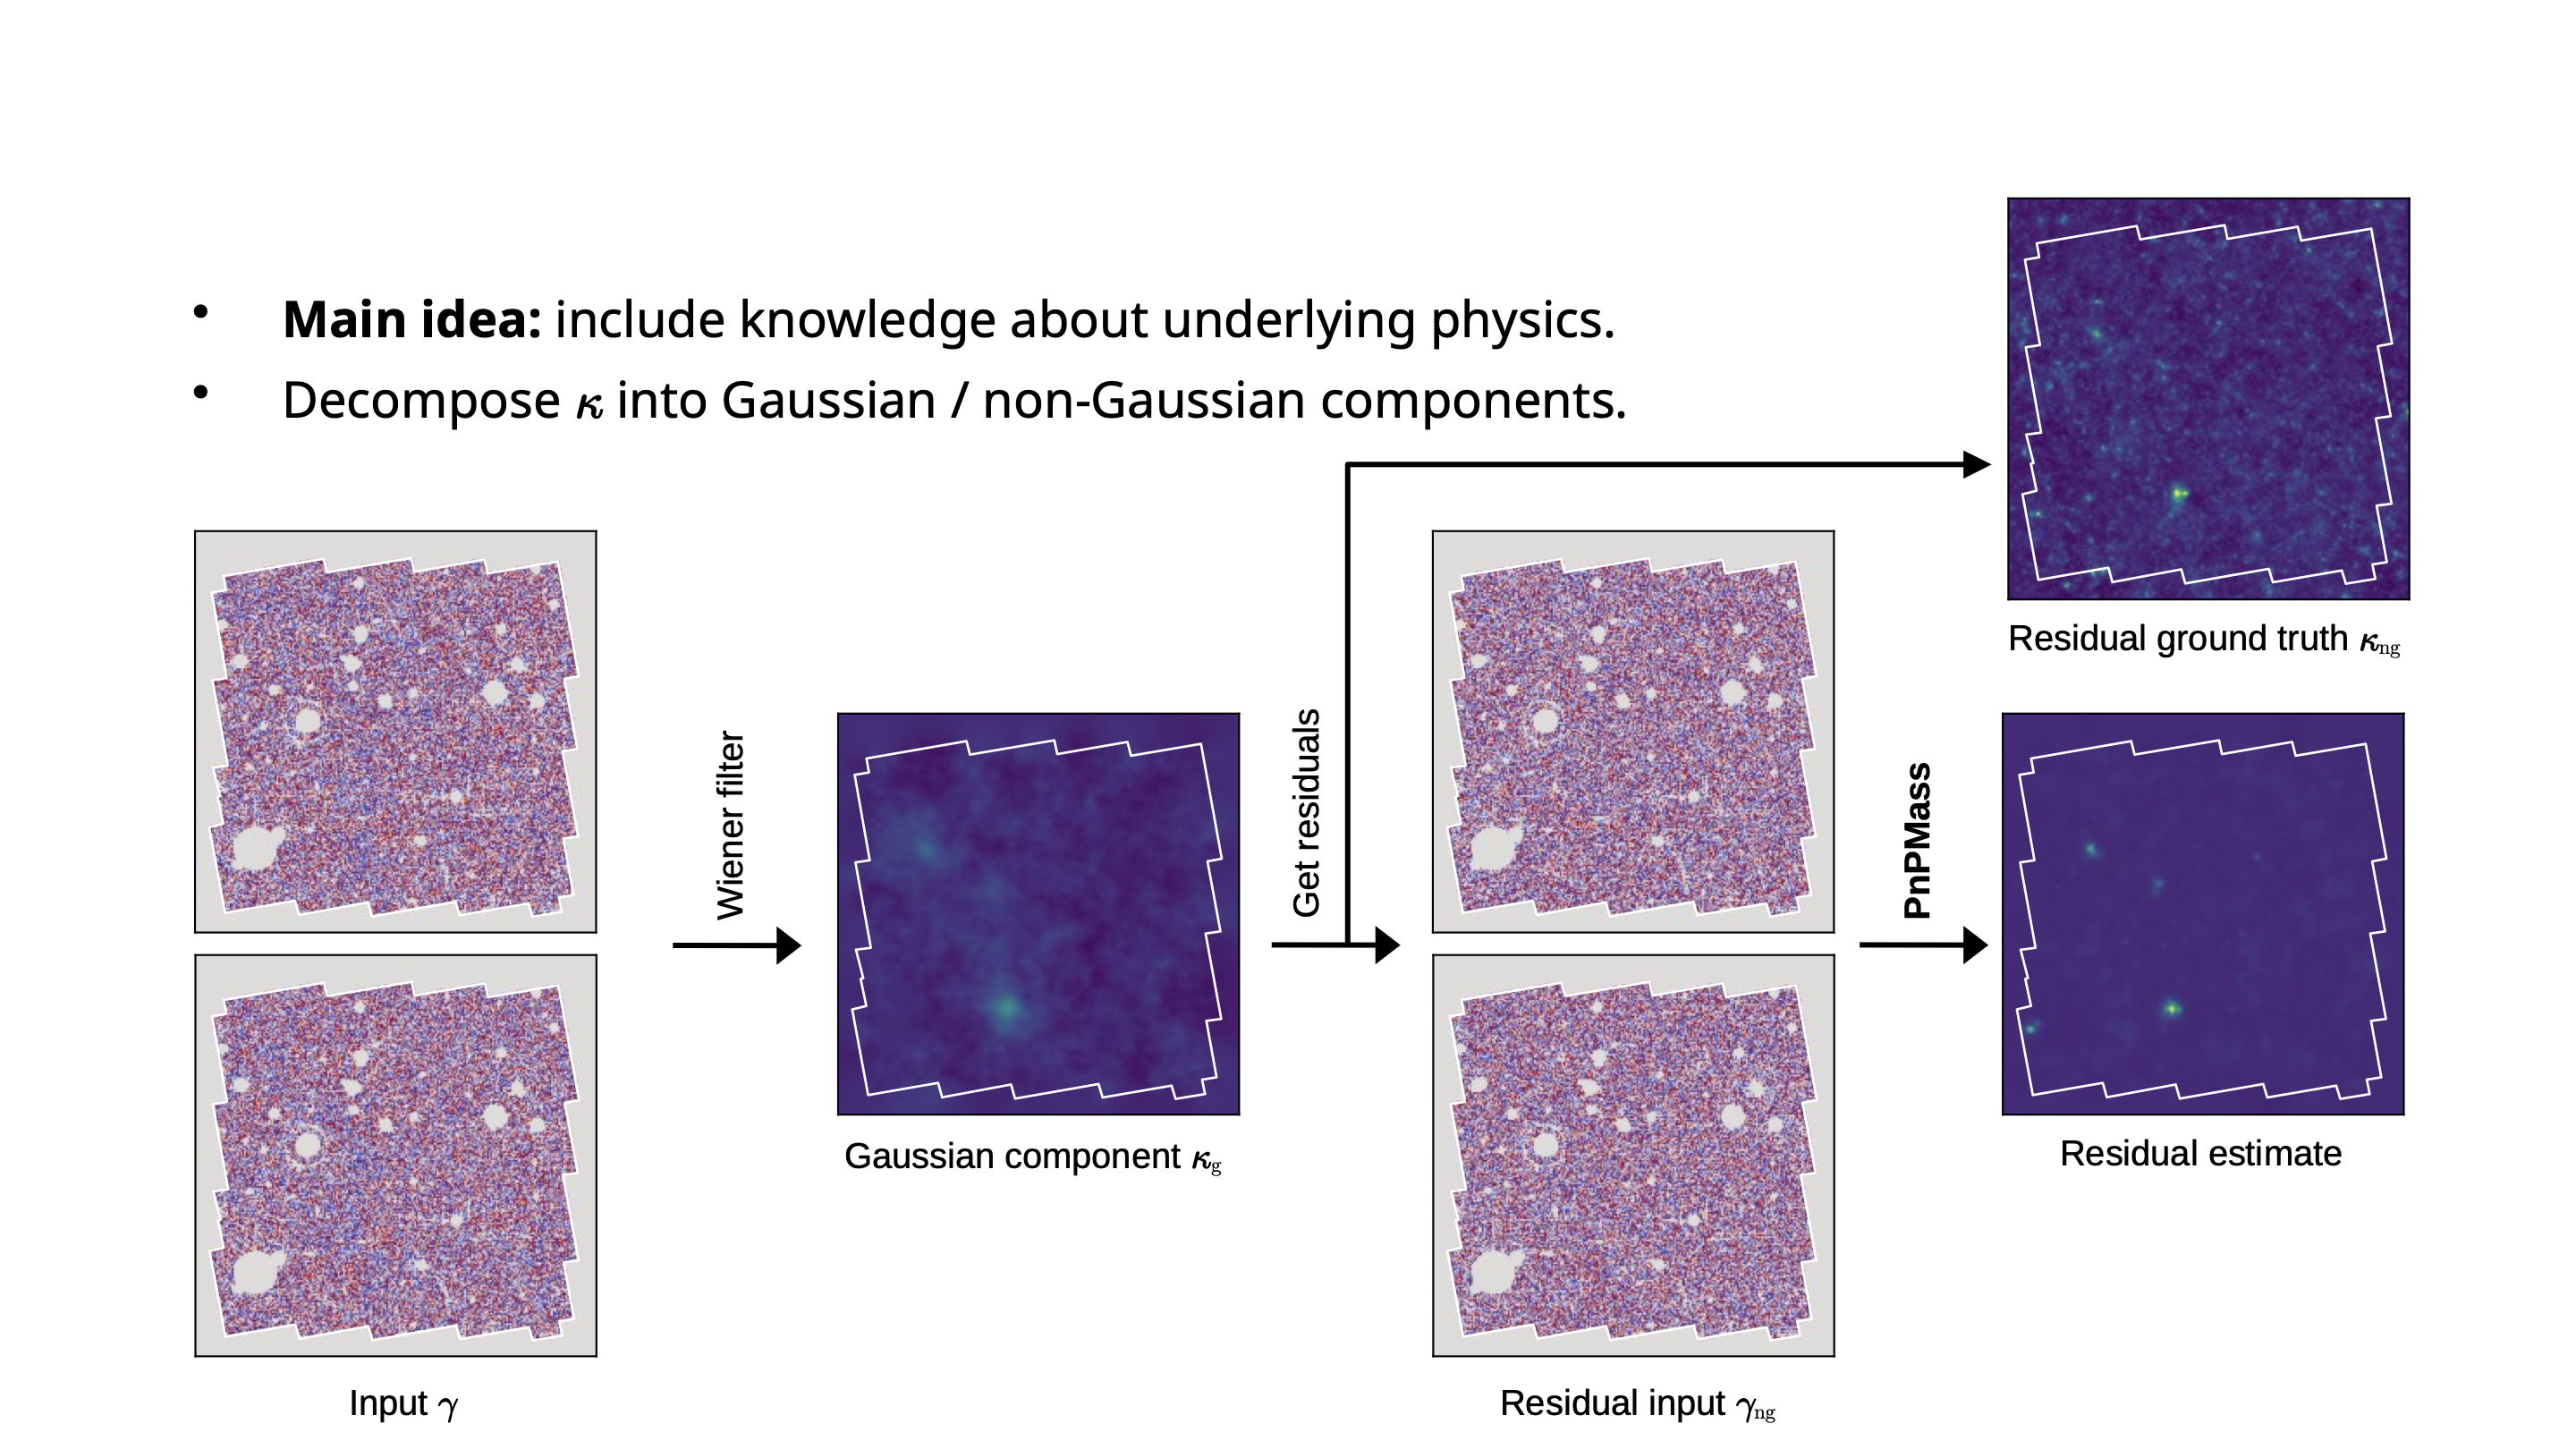
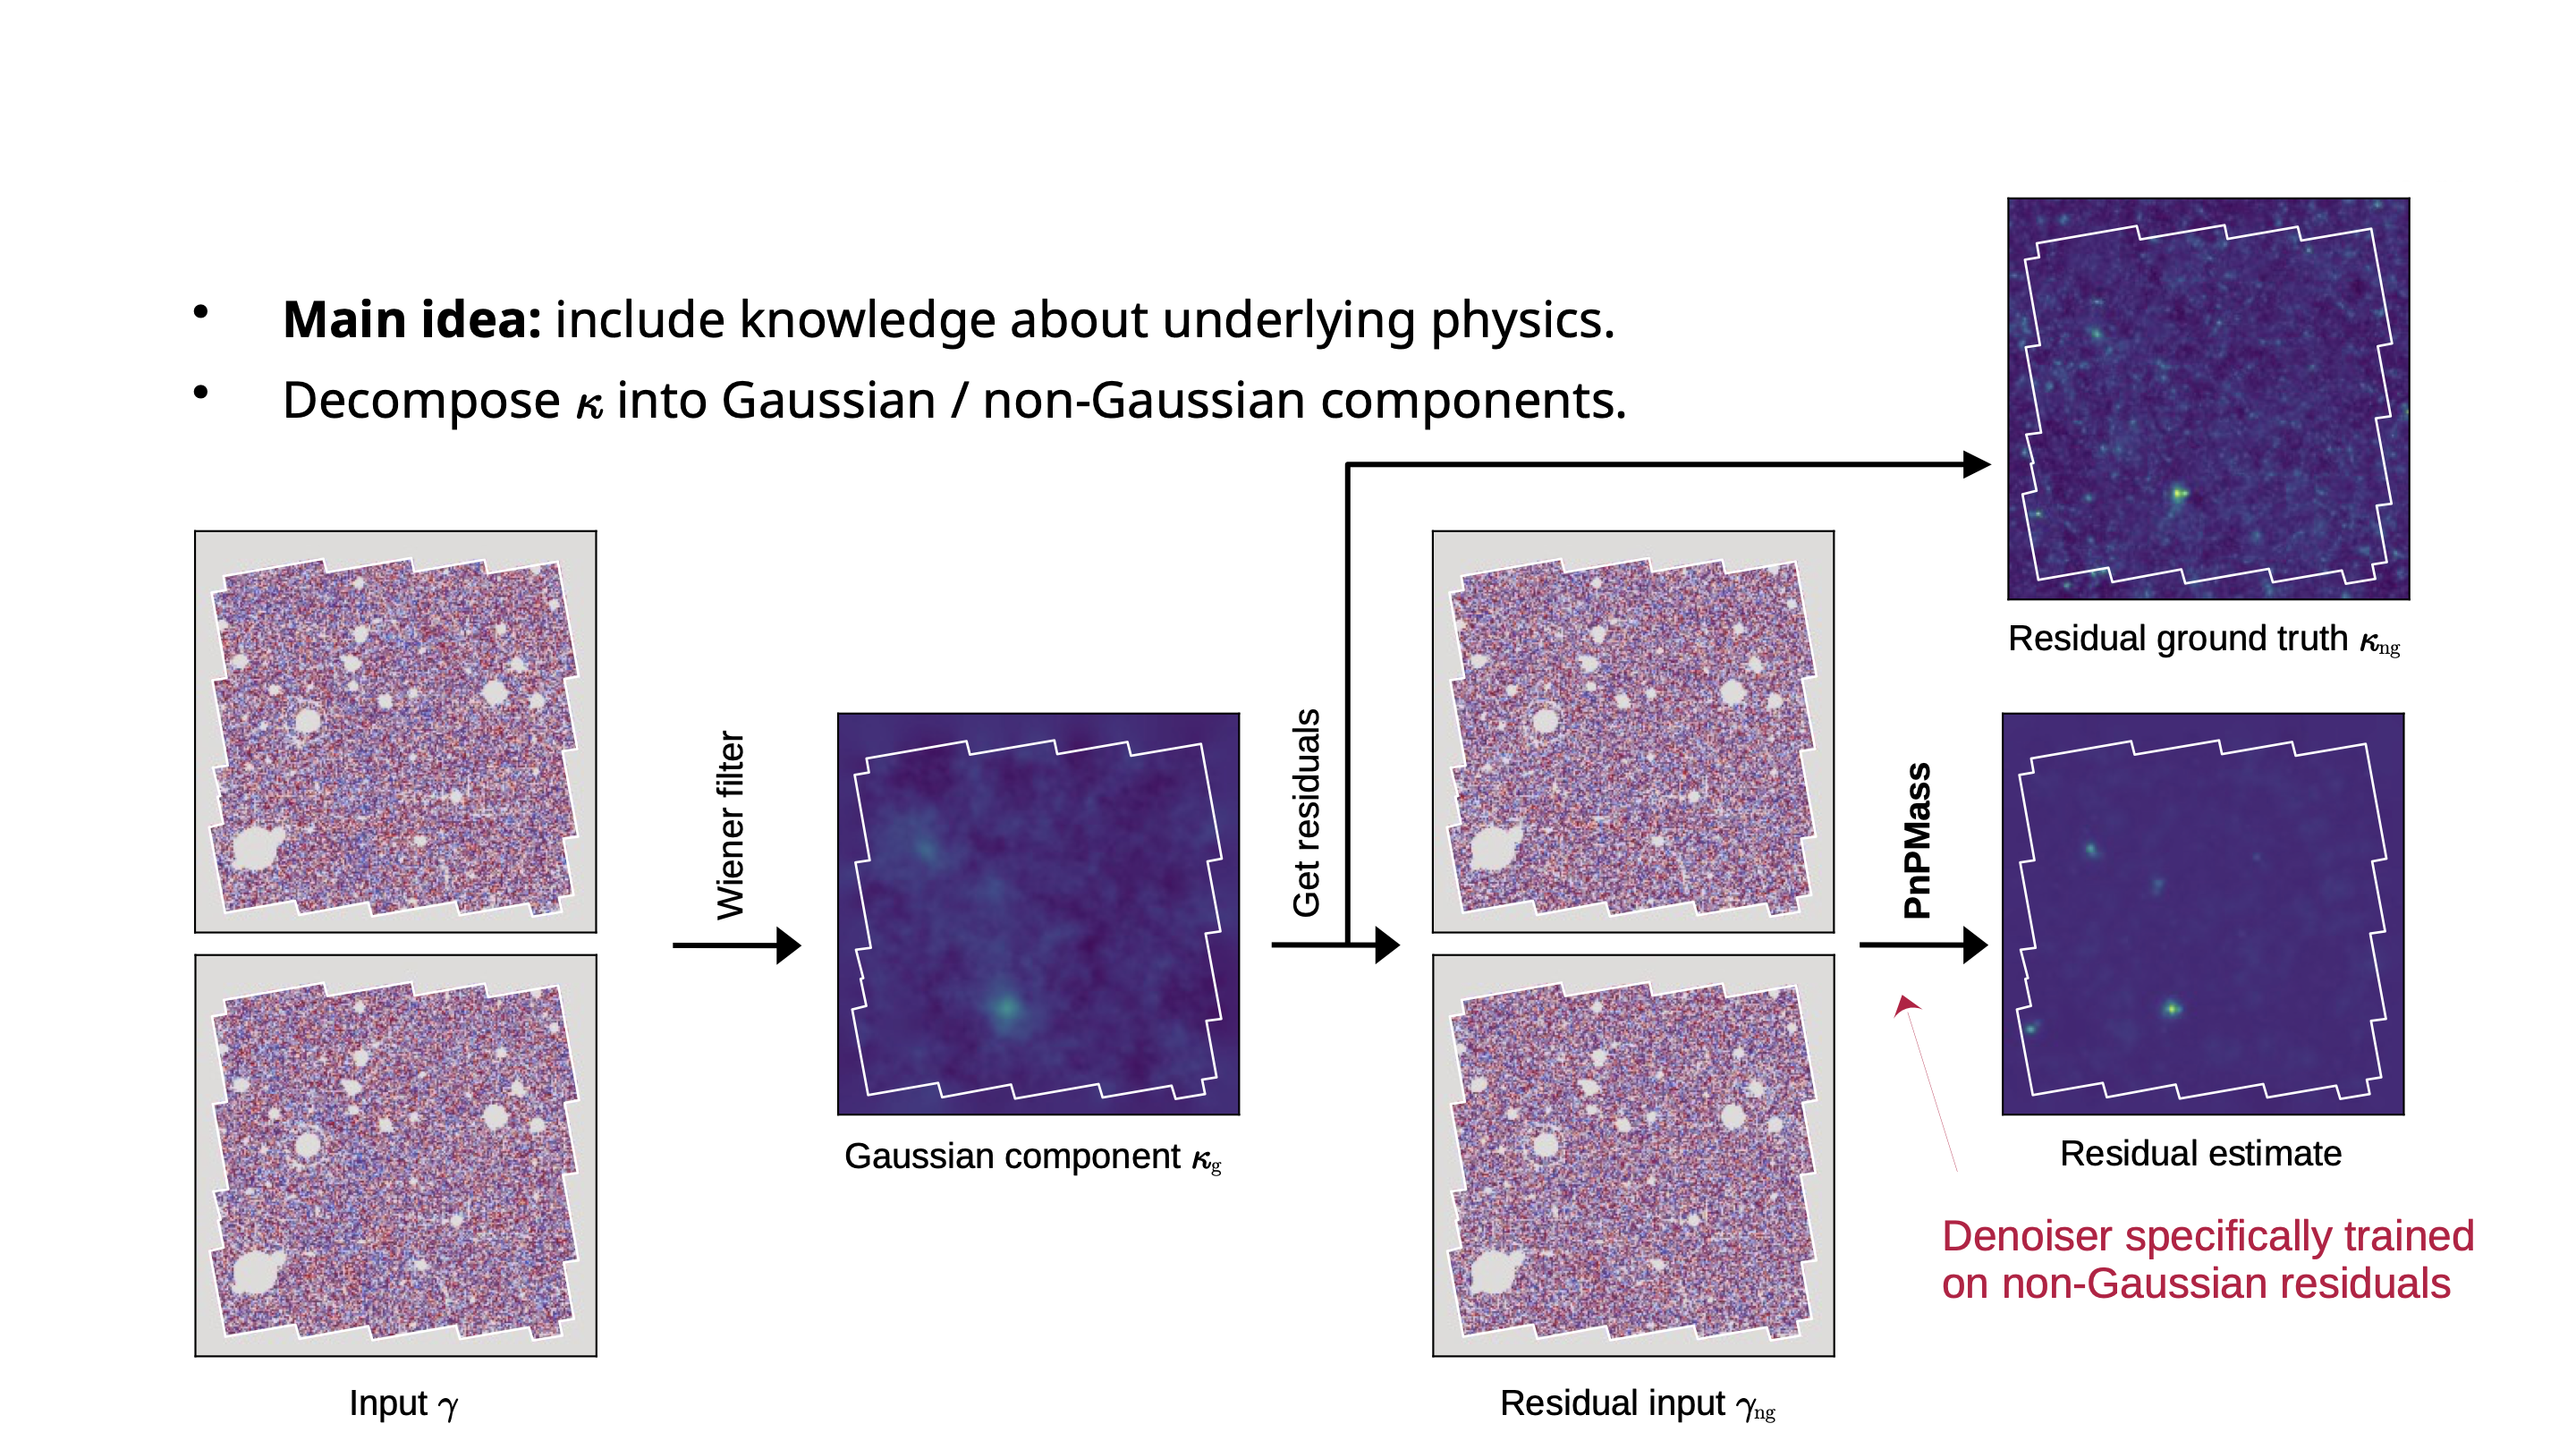
Use the PnP framework: replace prox by an off‑the‑shelf deep denoiser trained on simulations
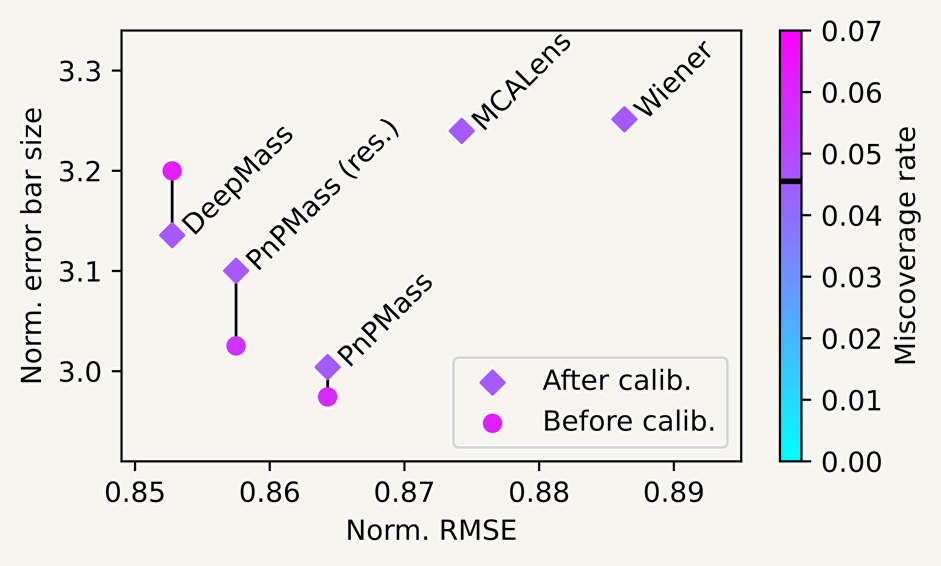
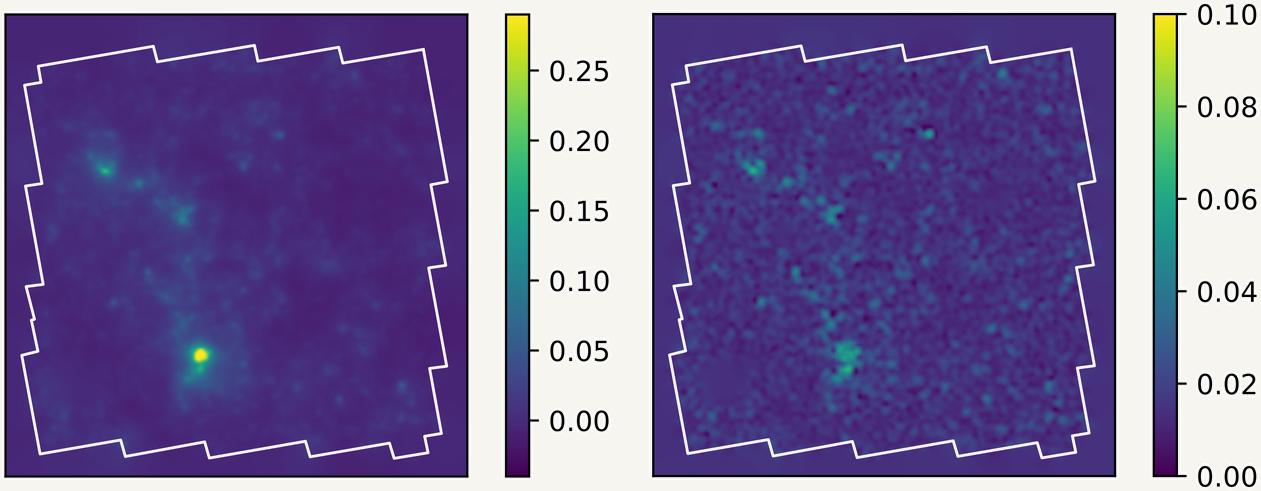
the uncertainty map traces the structure
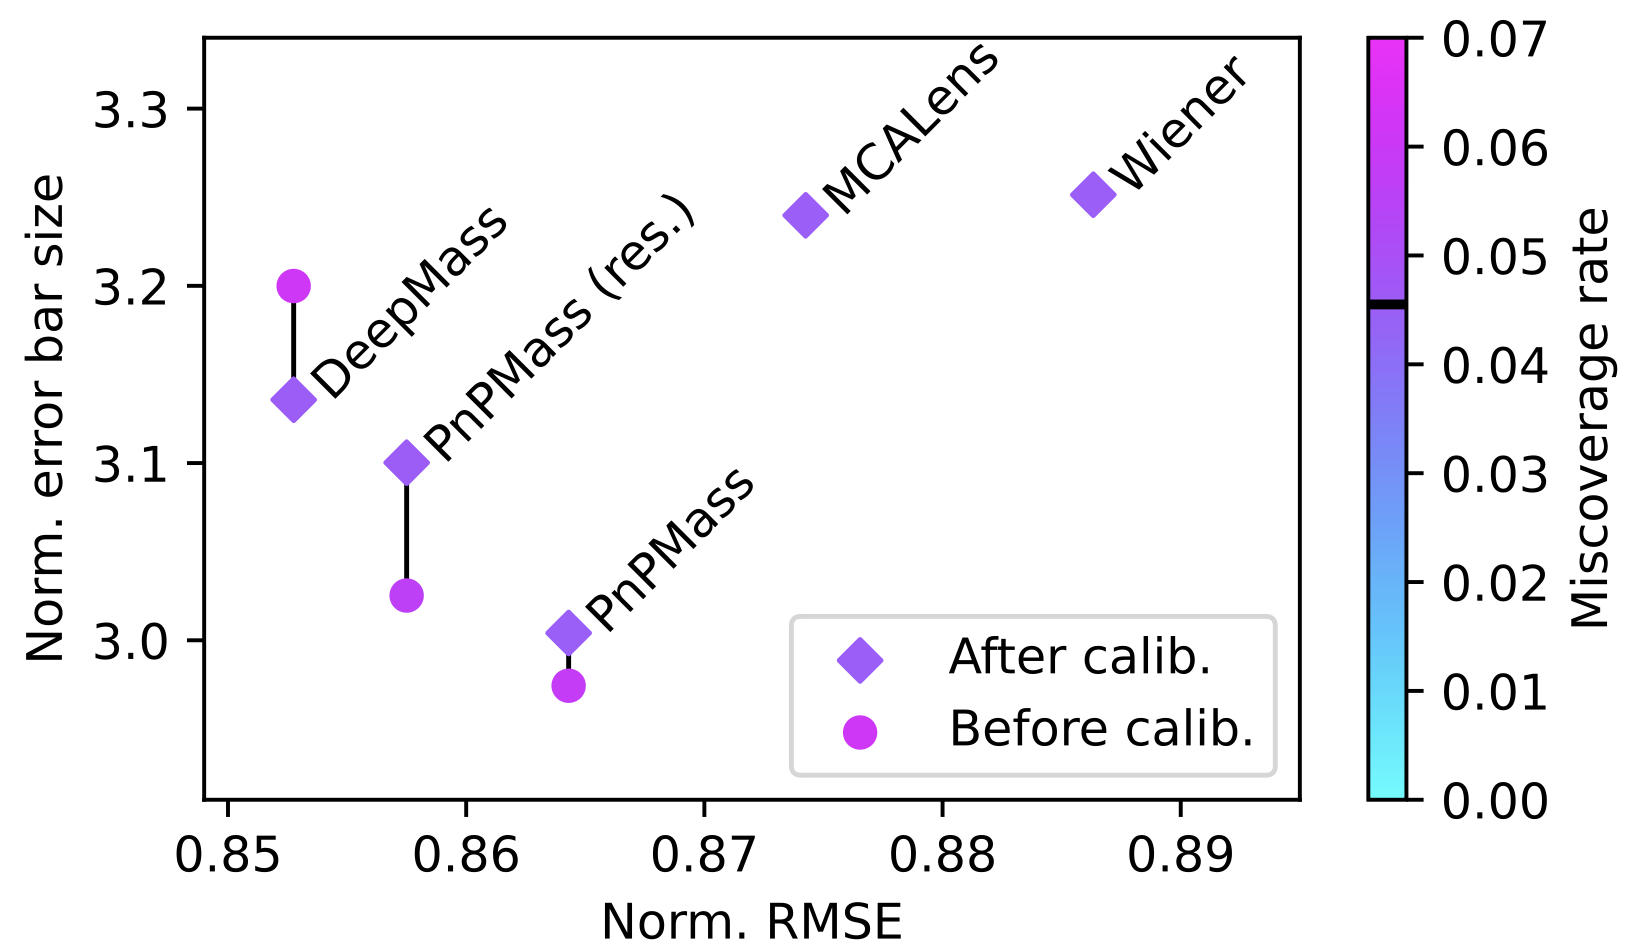
DeepMass and MMGAN need retraining for every new mask or noise level; PnPMass is trained once and applies to any configuration.
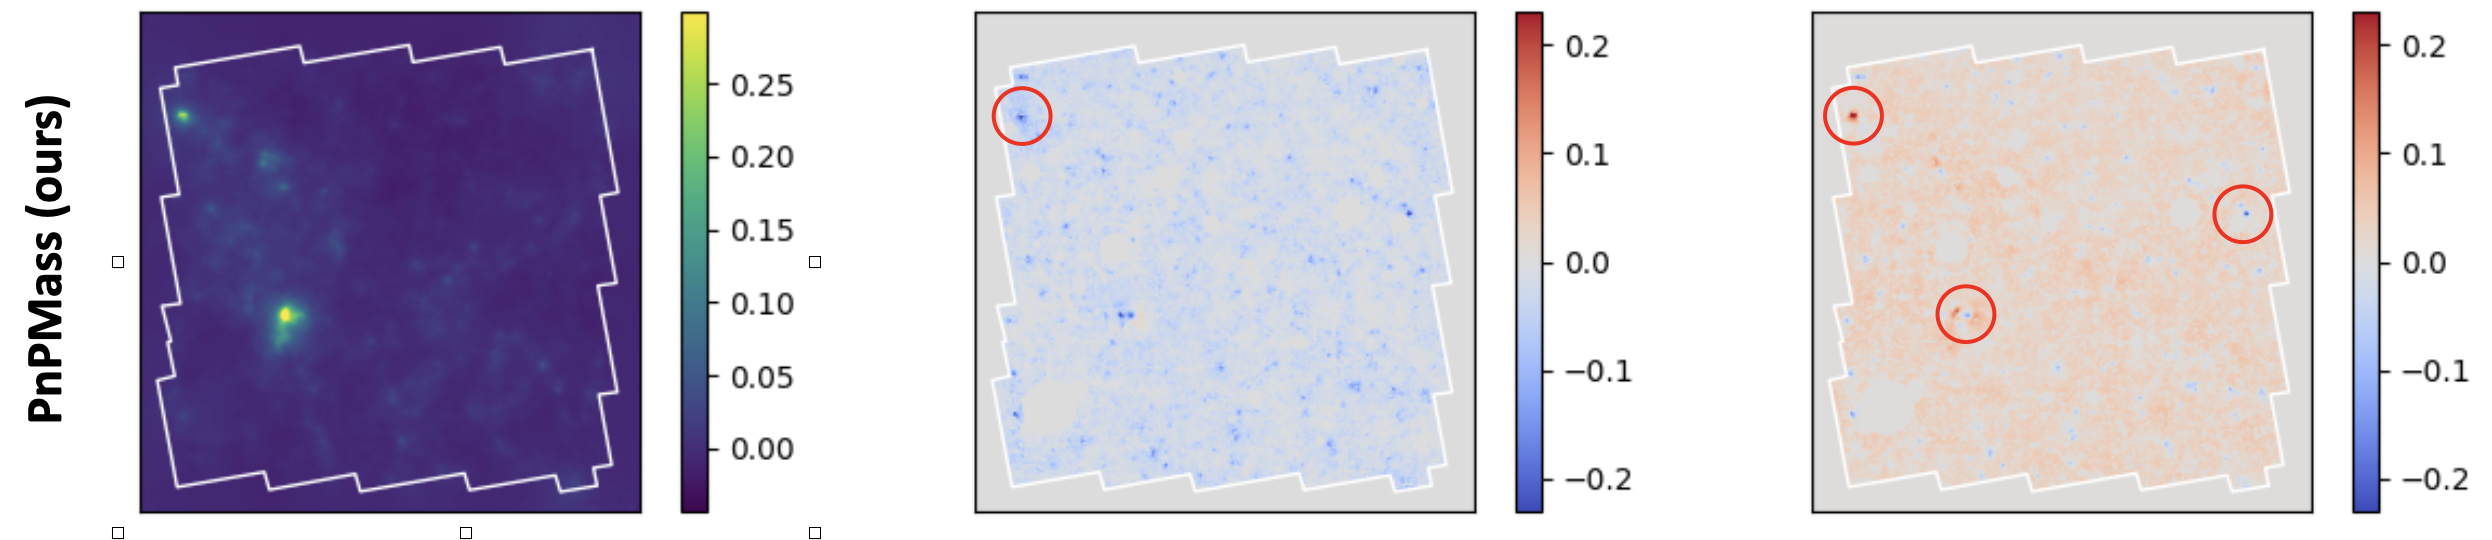
Replaced on 2026-09-03 by the restyled Act 1 slides. Kept for reference; nothing is deleted.
The same argument rebuilt in the preprint components. Kept for comparison against the lifted originals.
Tersenov, Baumont, Starck & Kilbinger, arXiv:2501.06961
Leterme, Tersenov, Starck et al. — joint work: I co‑developed the method and built the uncertainty quantification
flexible — the physics is written down, so nothing is retrained
no useful uncertainty; Wiener assumes the field is Gaussian; MCALens is slow
accurate, and fast once trained
trained for one noise level and one mask; returns a point estimate with no error bar
flexible fast accurate and calibrated
—
$$\kappa^{\,n+1} \;=\; \mathrm{Denoiser}\big(\kappa^{\,n} + \text{data residual}\big)$$
Swin‑Transformer denoiser, 7.2 M parameters, trained once on white Gaussian noise with the noise level as an input channel. Eight iterations per map.
Coverage is marginal, not conditional — the miscoverage concentrates at the peaks, exactly where Chapter 2 says the information lives. And this is a single cosmology.
Parts 1 and 2 were about the mass map. Parts 3 and 4 are about the summary statistic, and its robustness to systematics.
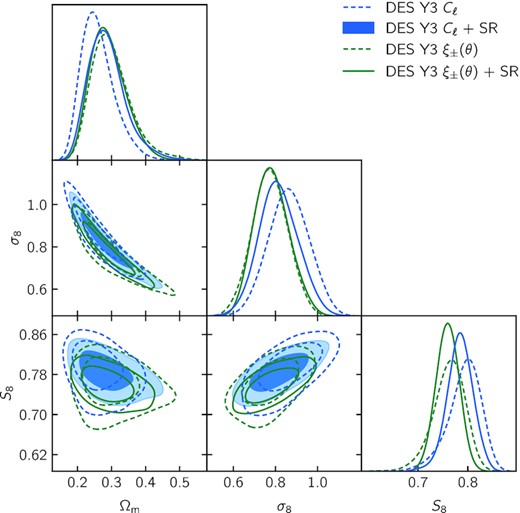
what it measures
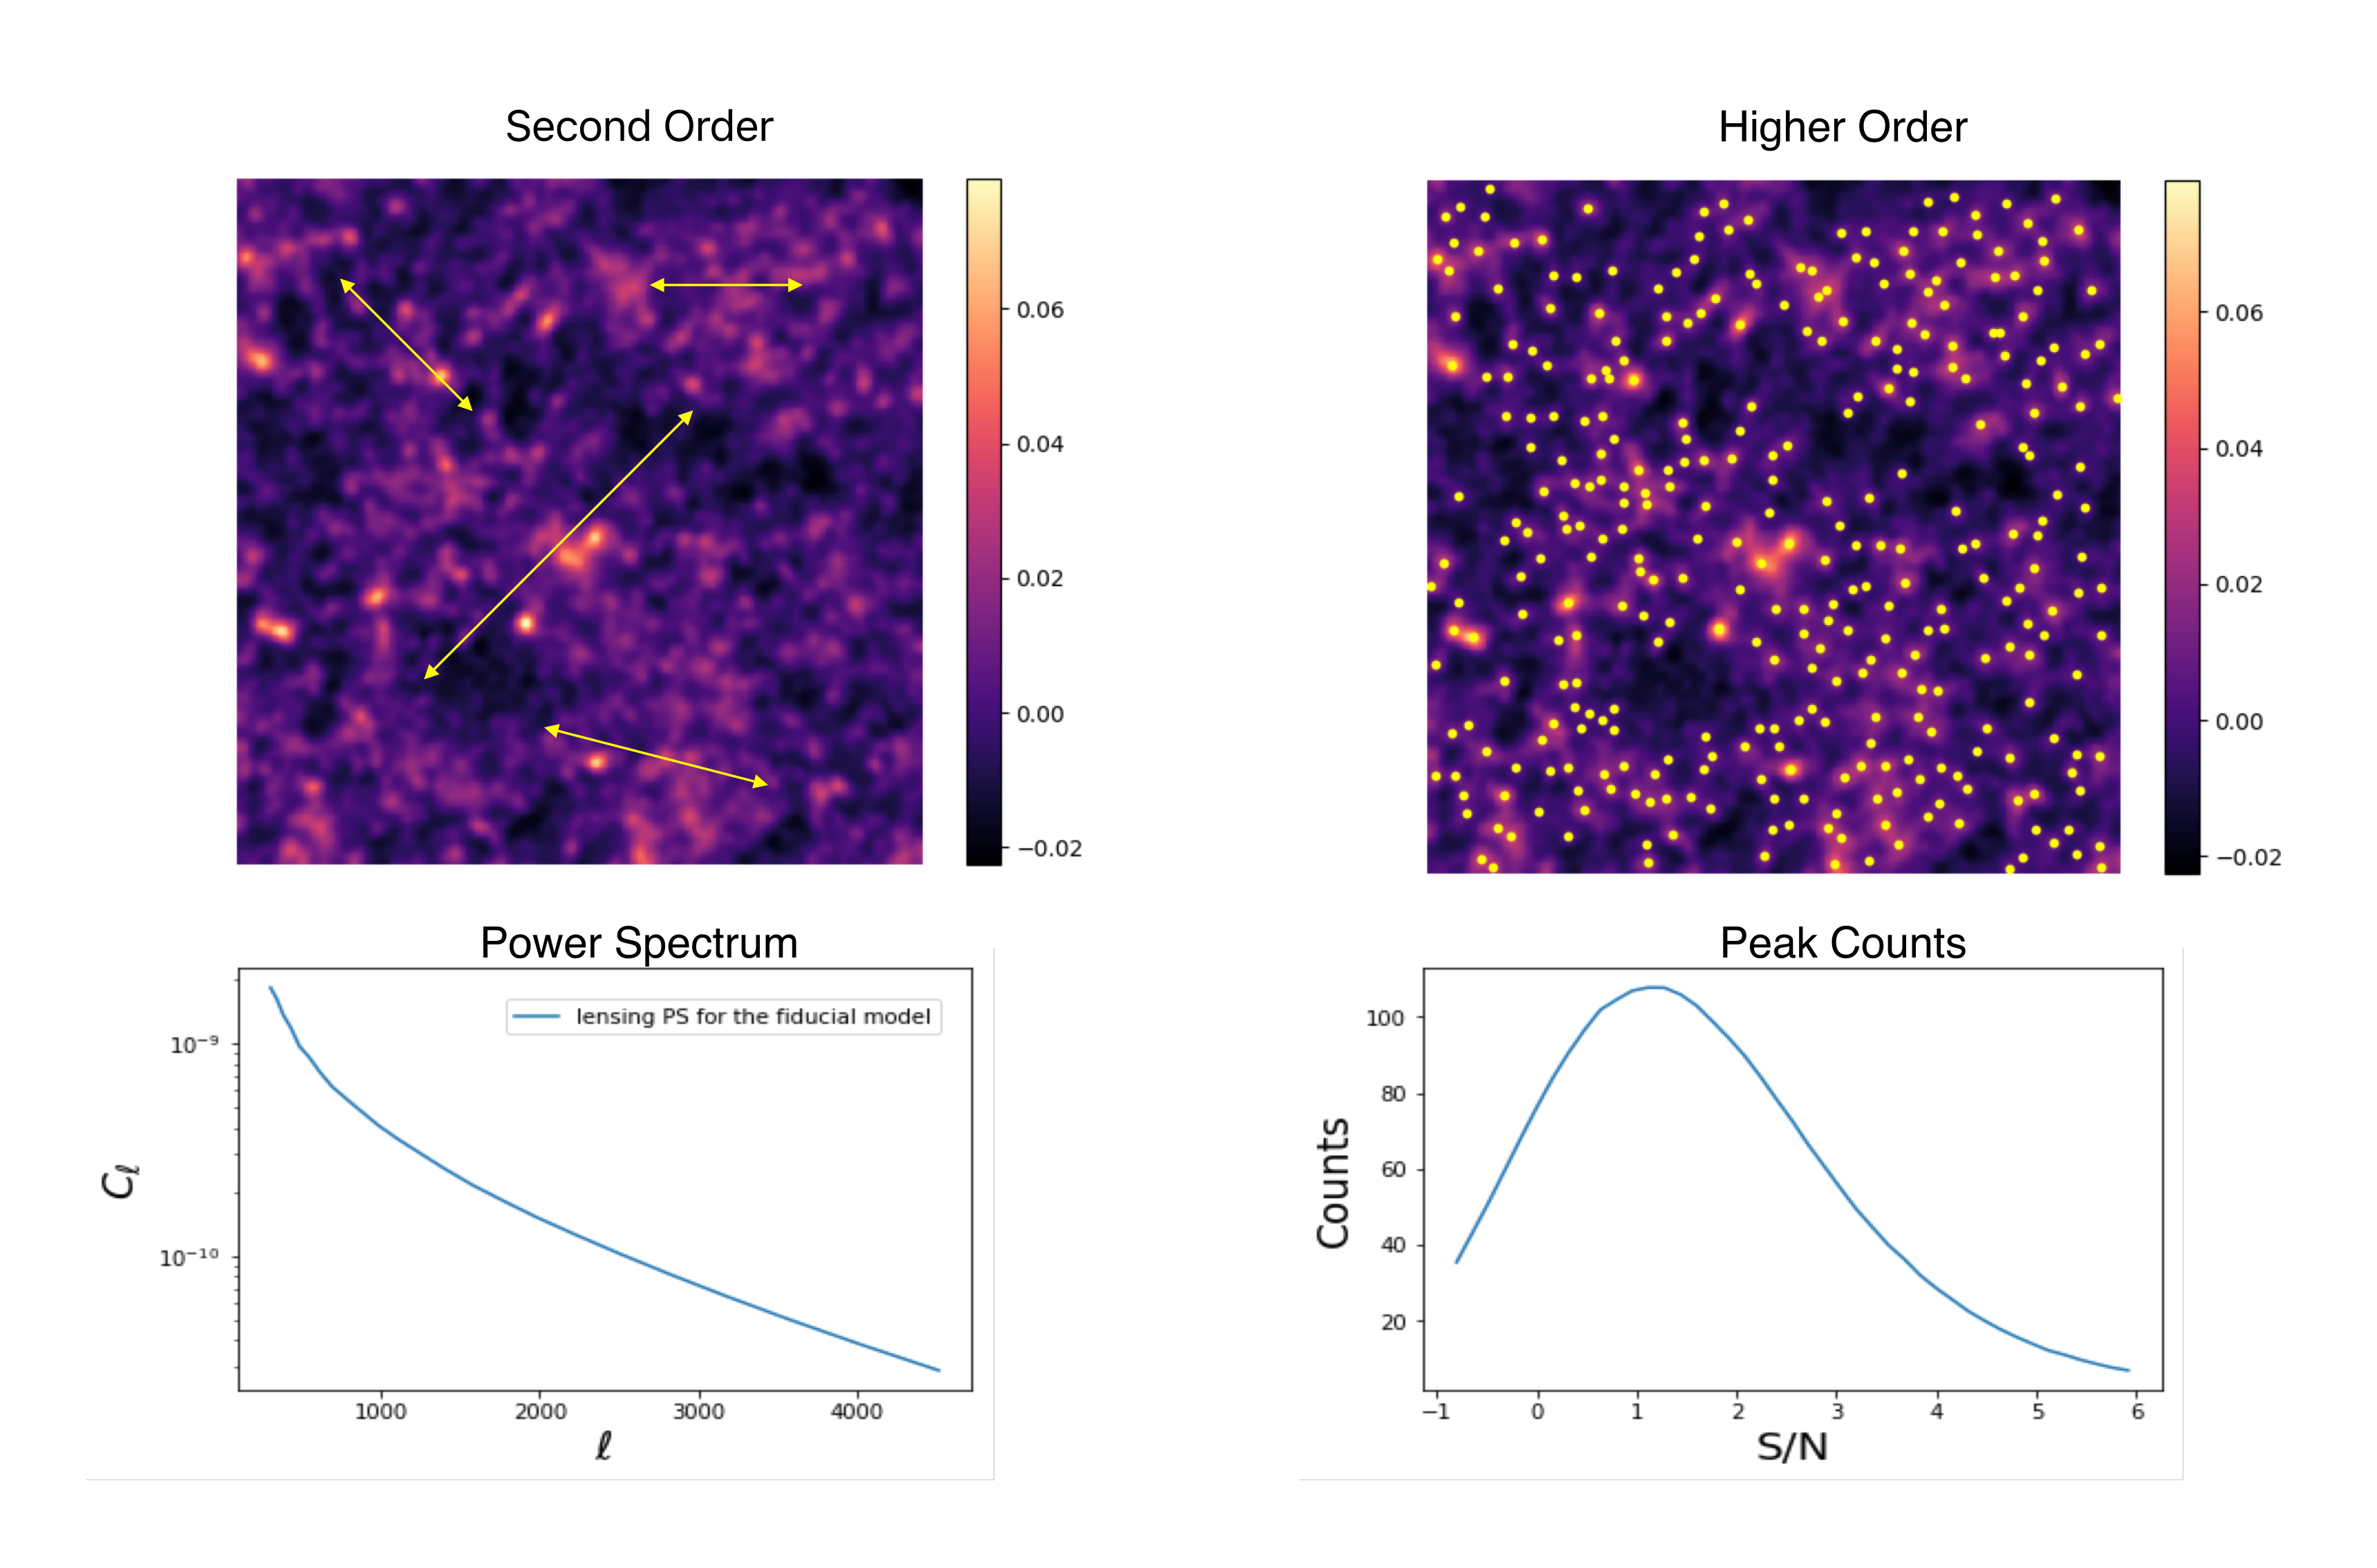
How correlated the shear is between pairs of galaxies separated by an angle $\theta$. Measured as $\xi_\pm(\theta)$, or as $C_\ell$.
For a Gaussian random field, the power spectrum contains all the information. But the late‑time density field is not Gaussian.
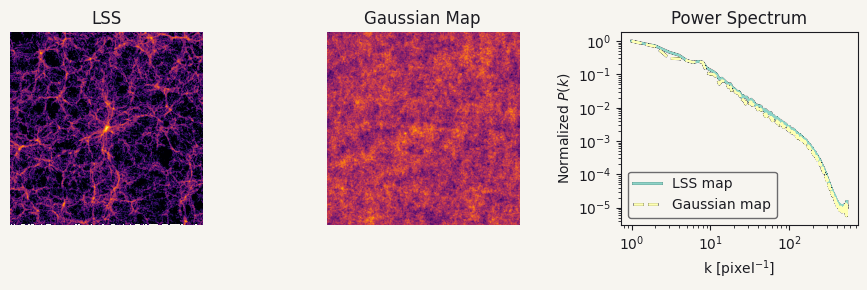
To access the information the power spectrum misses we need higher‑order statistics: peak counts, wavelet statistics, the ℓ1‑norm, Minkowski functionals.
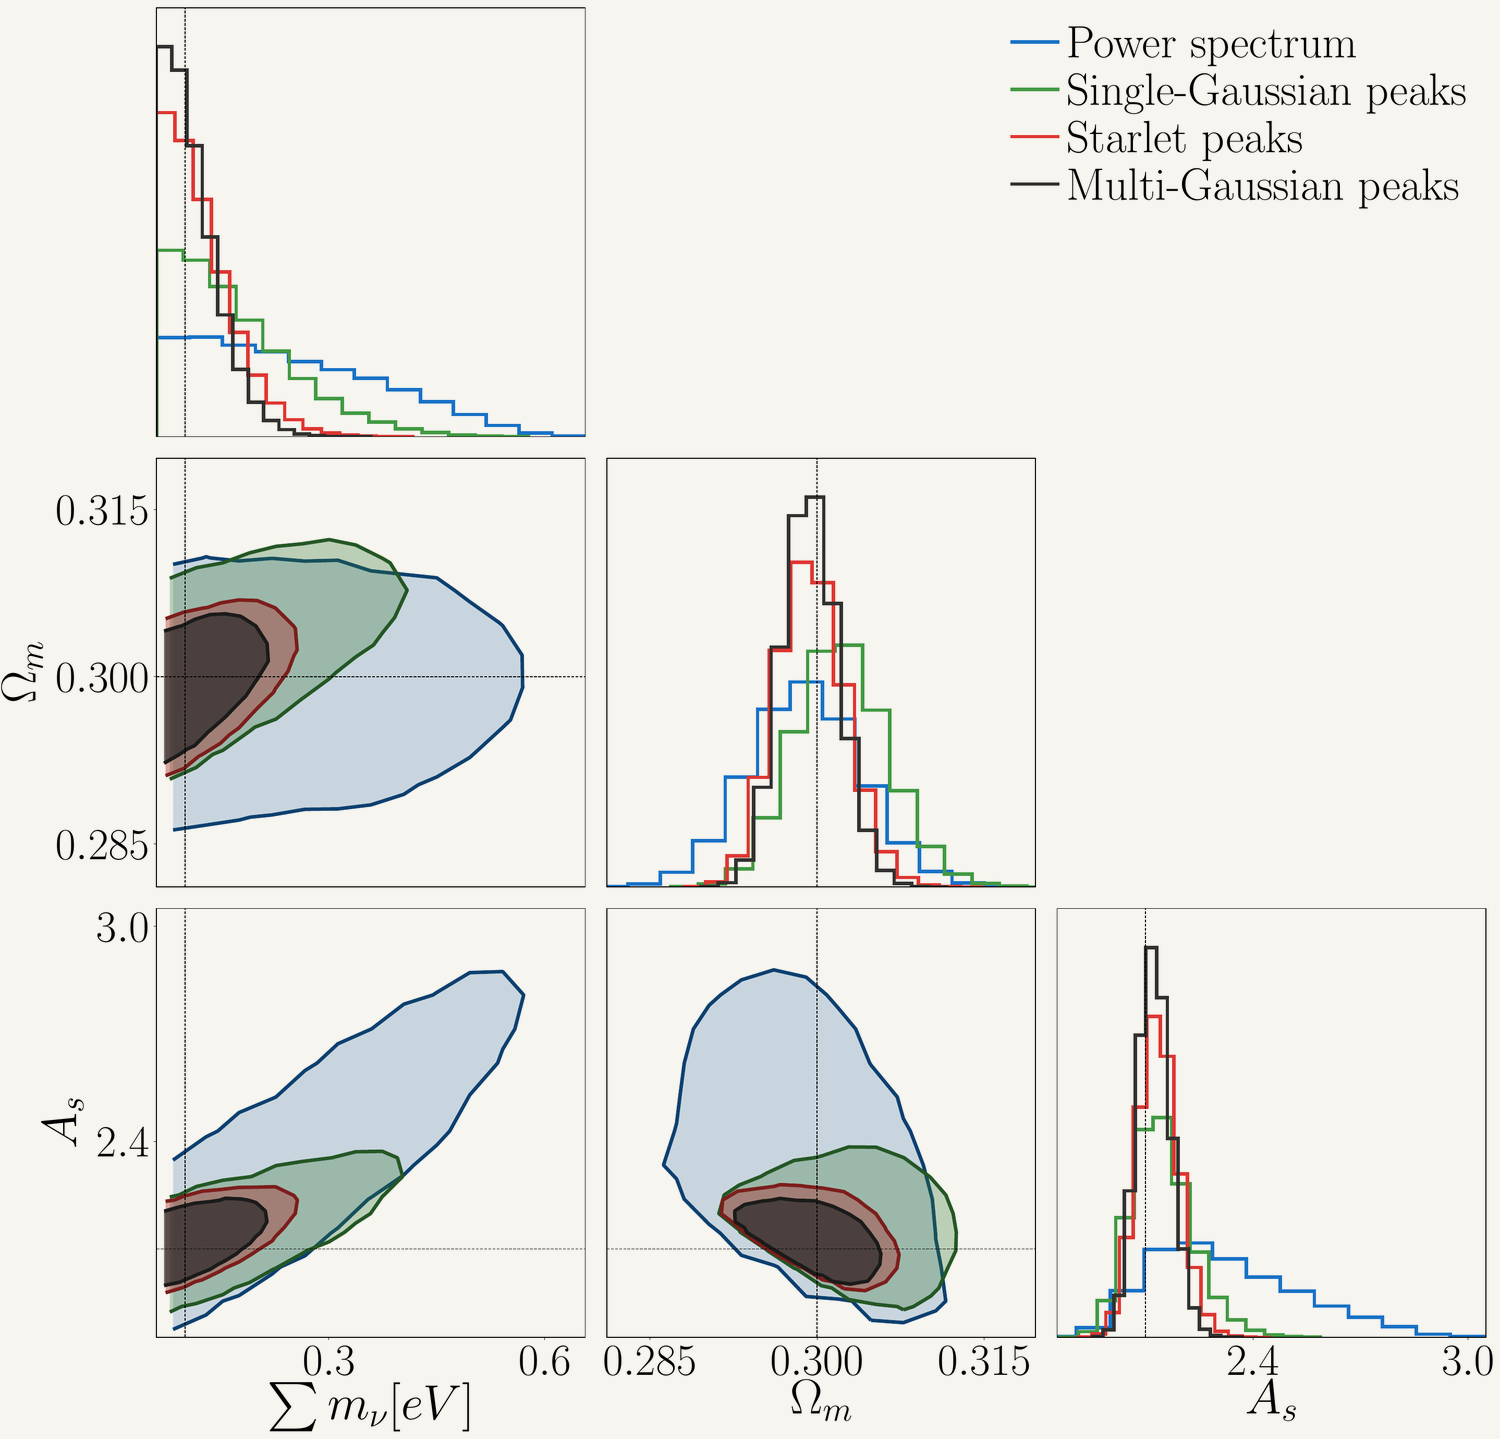
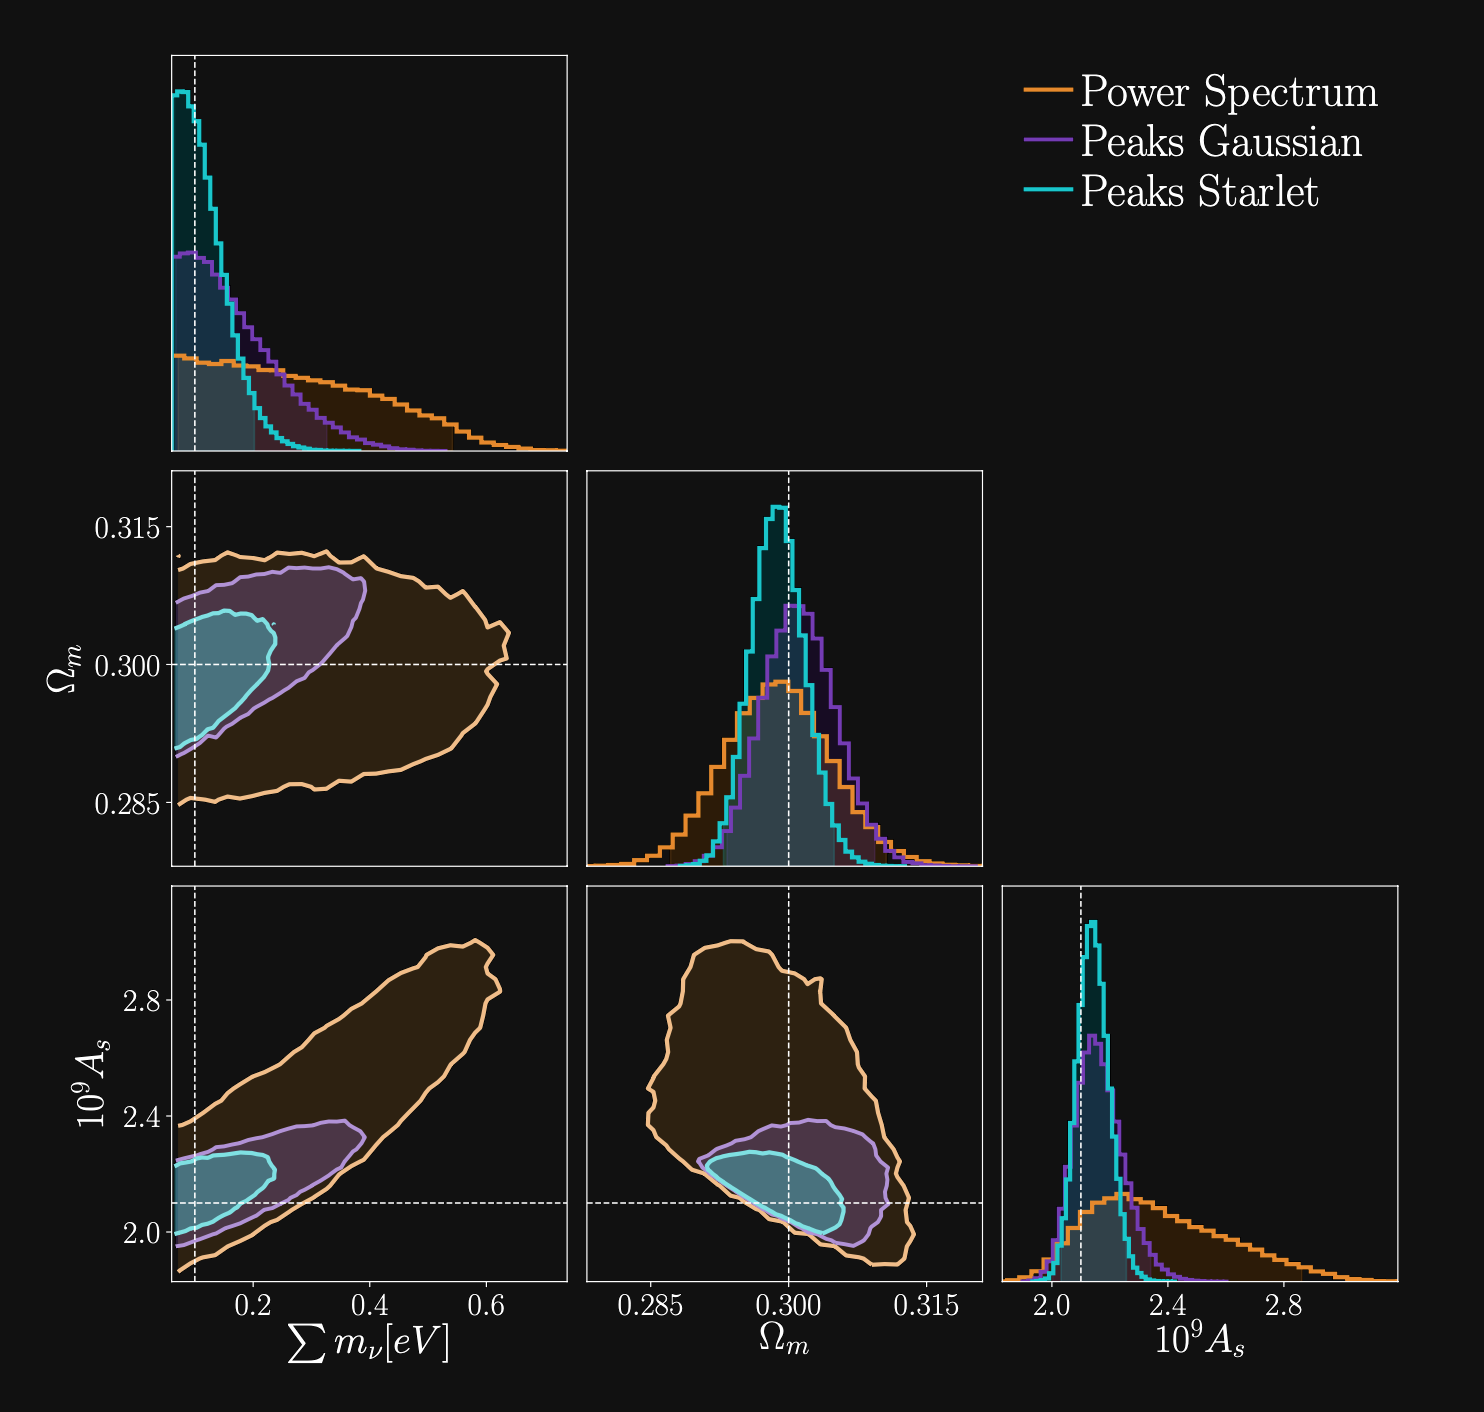
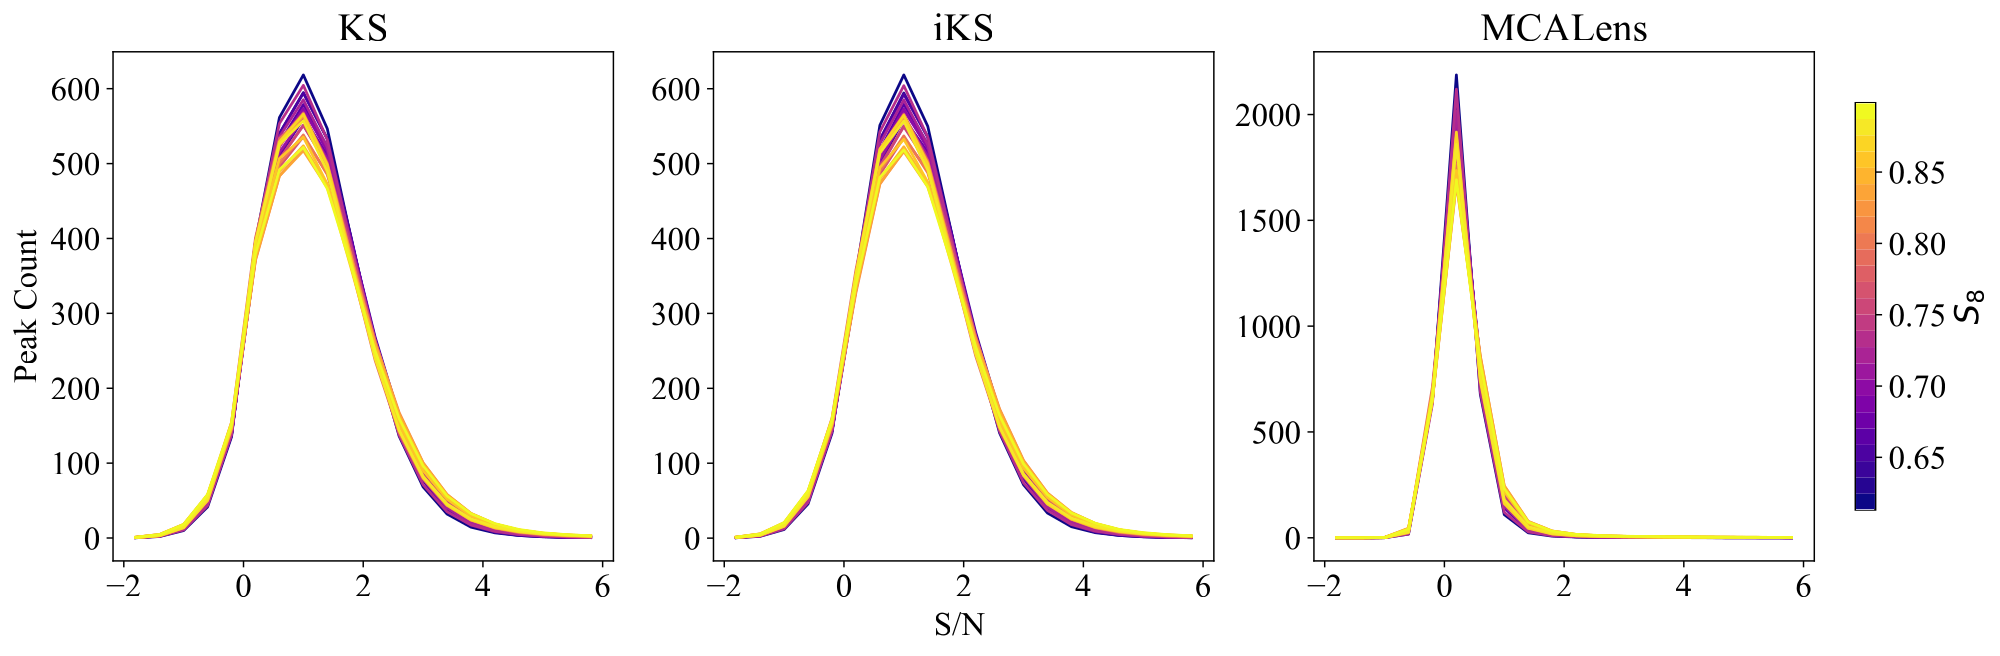
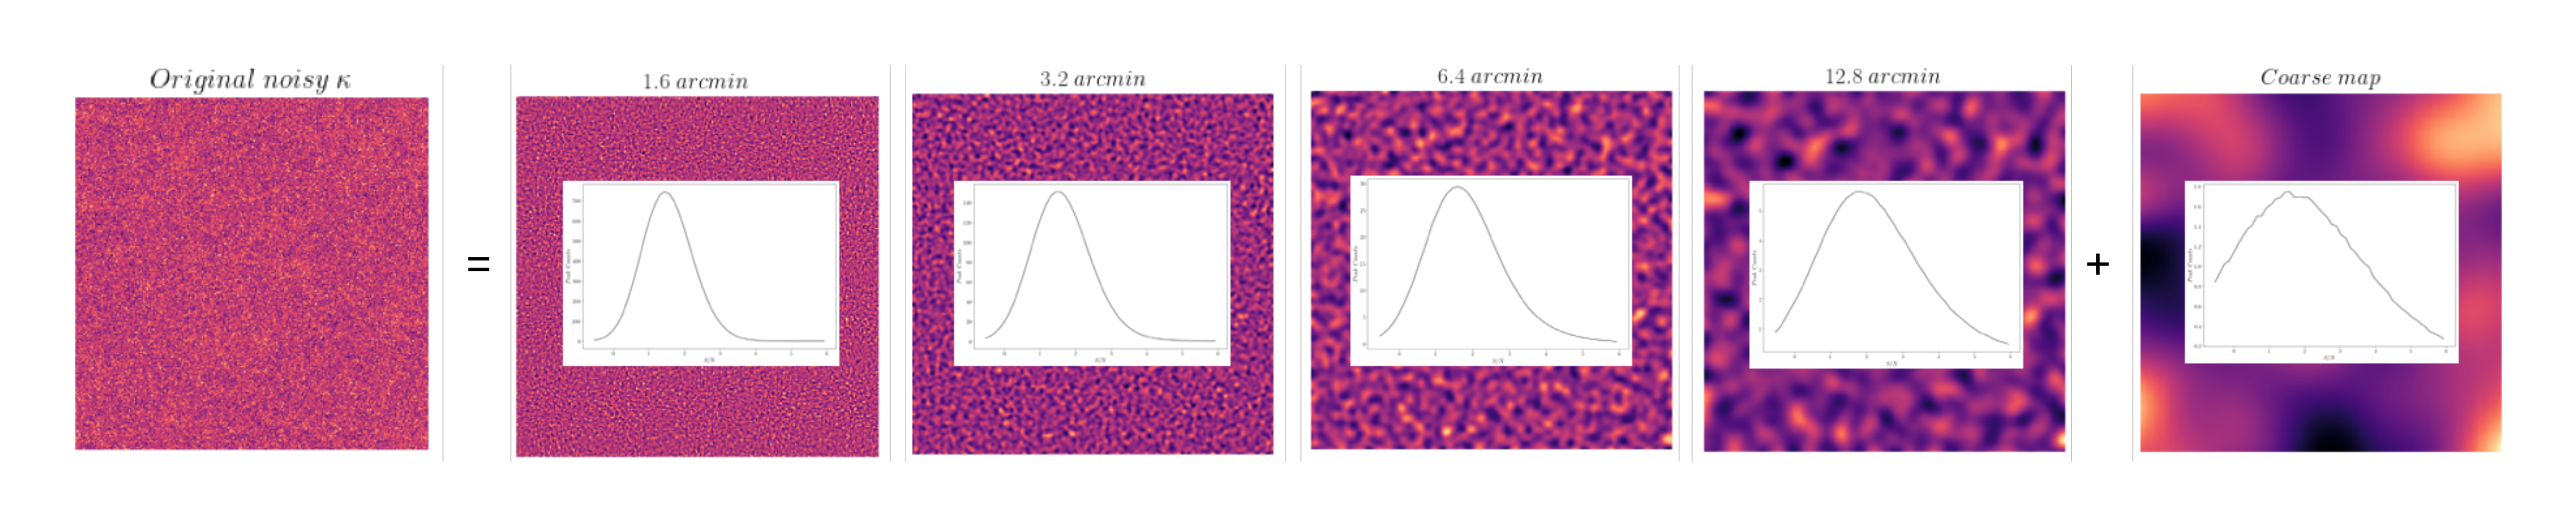
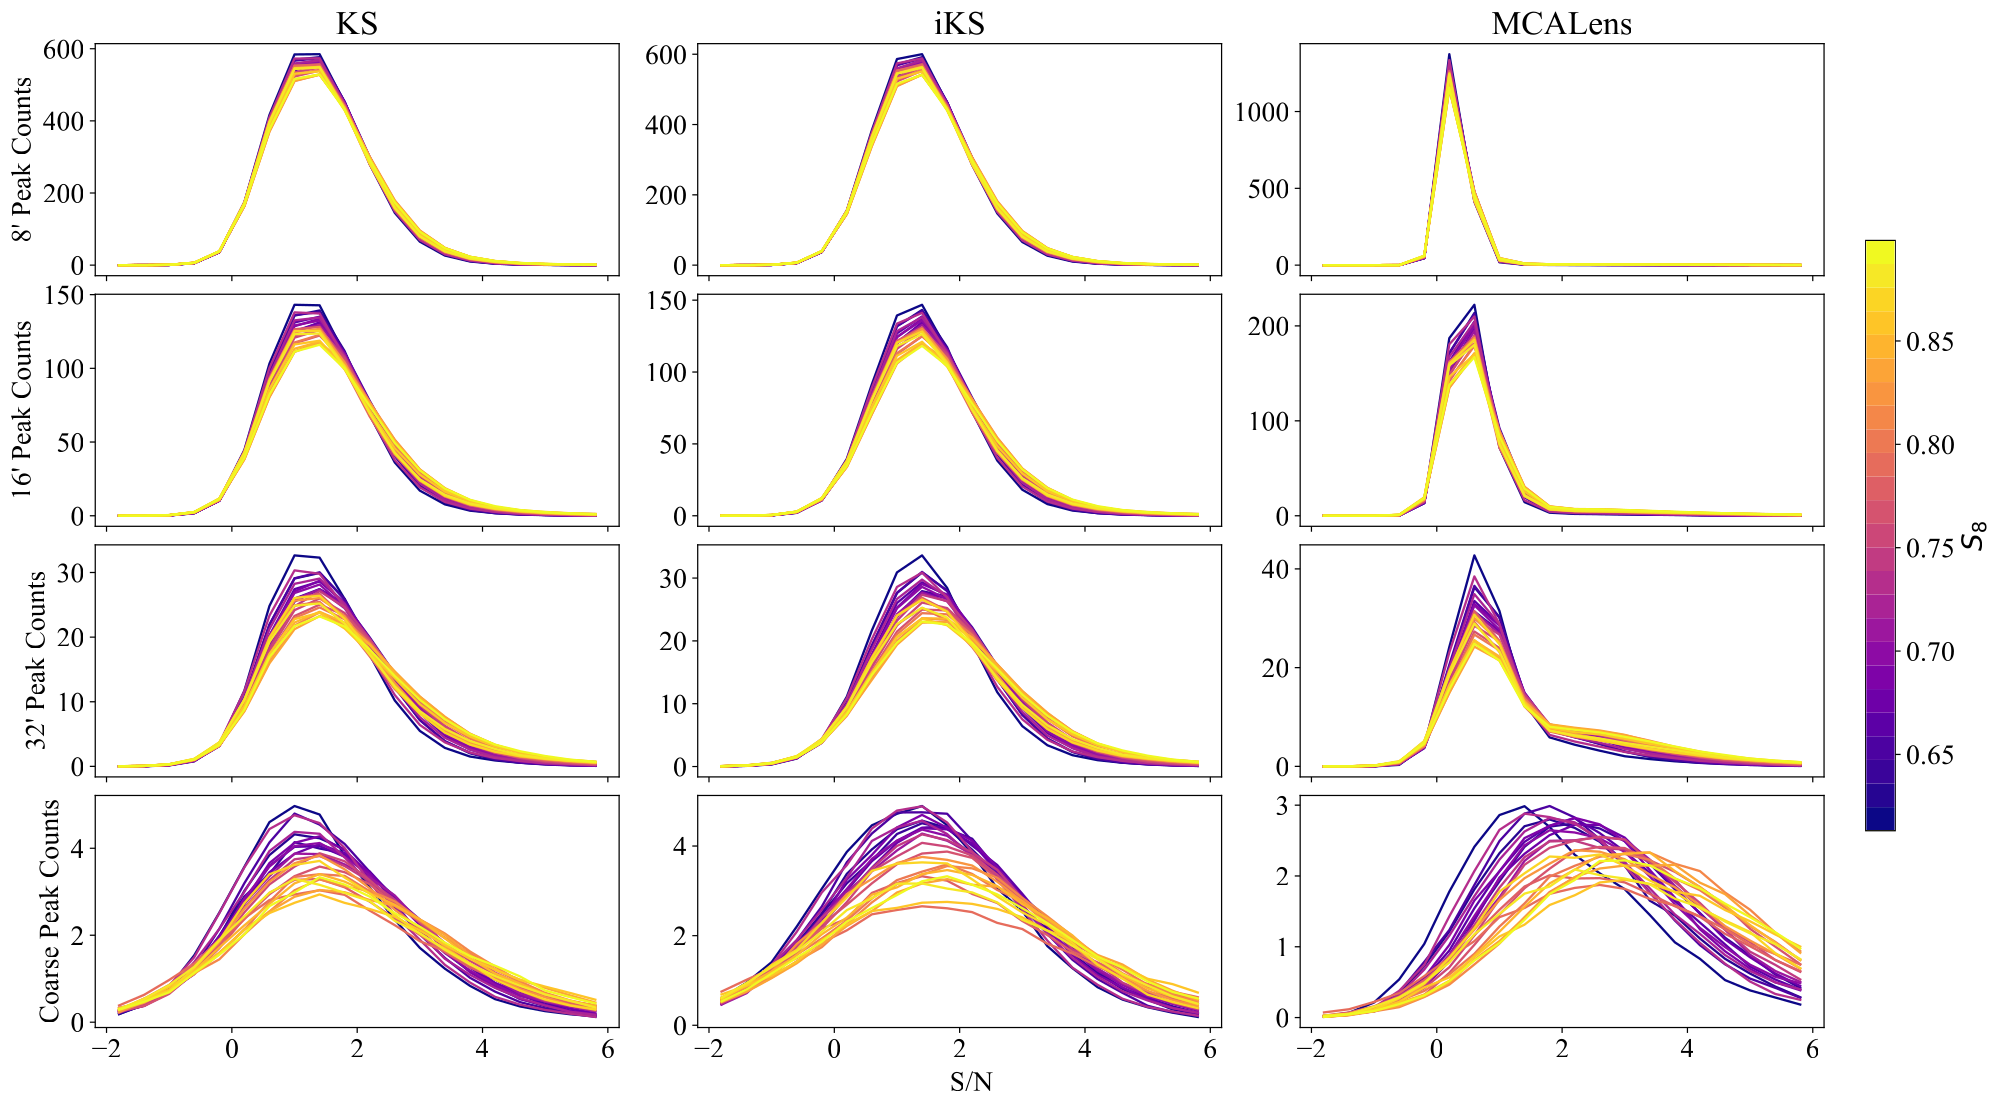
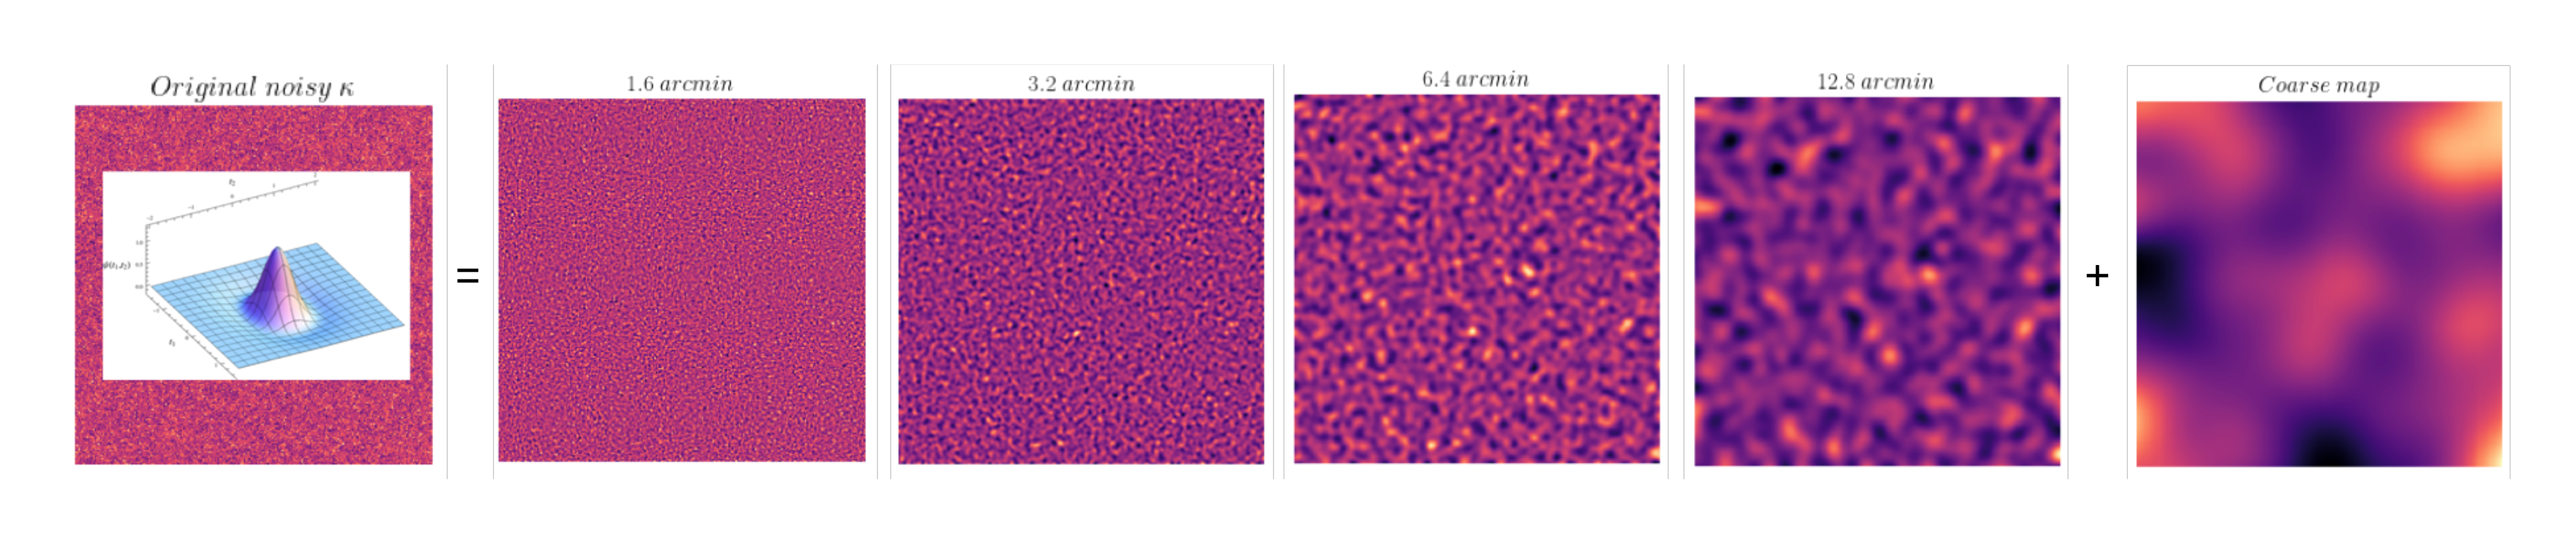
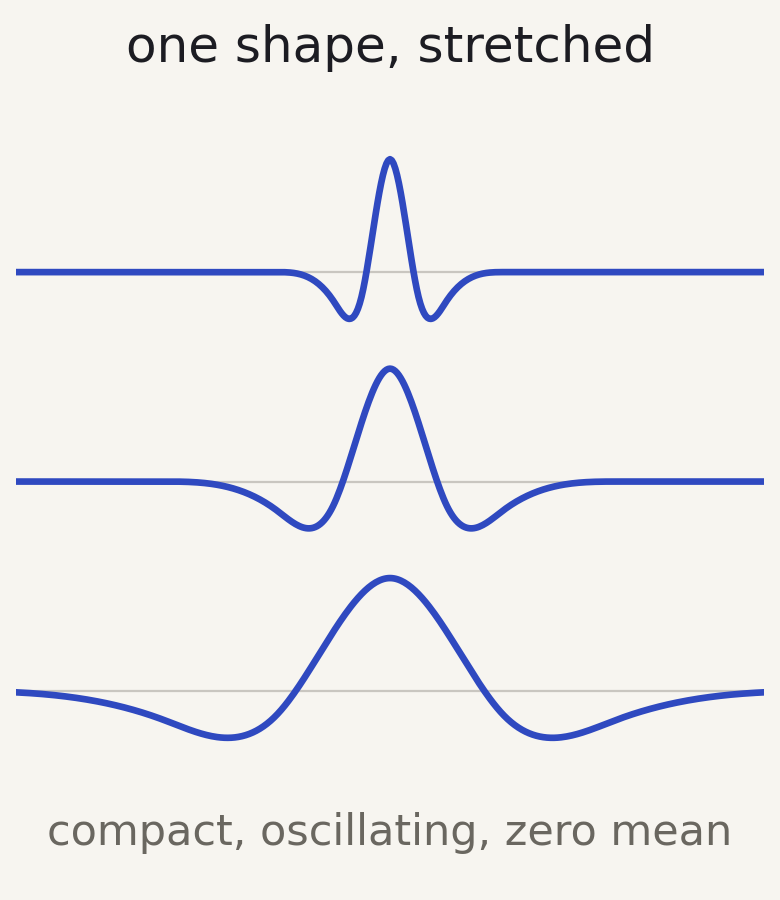
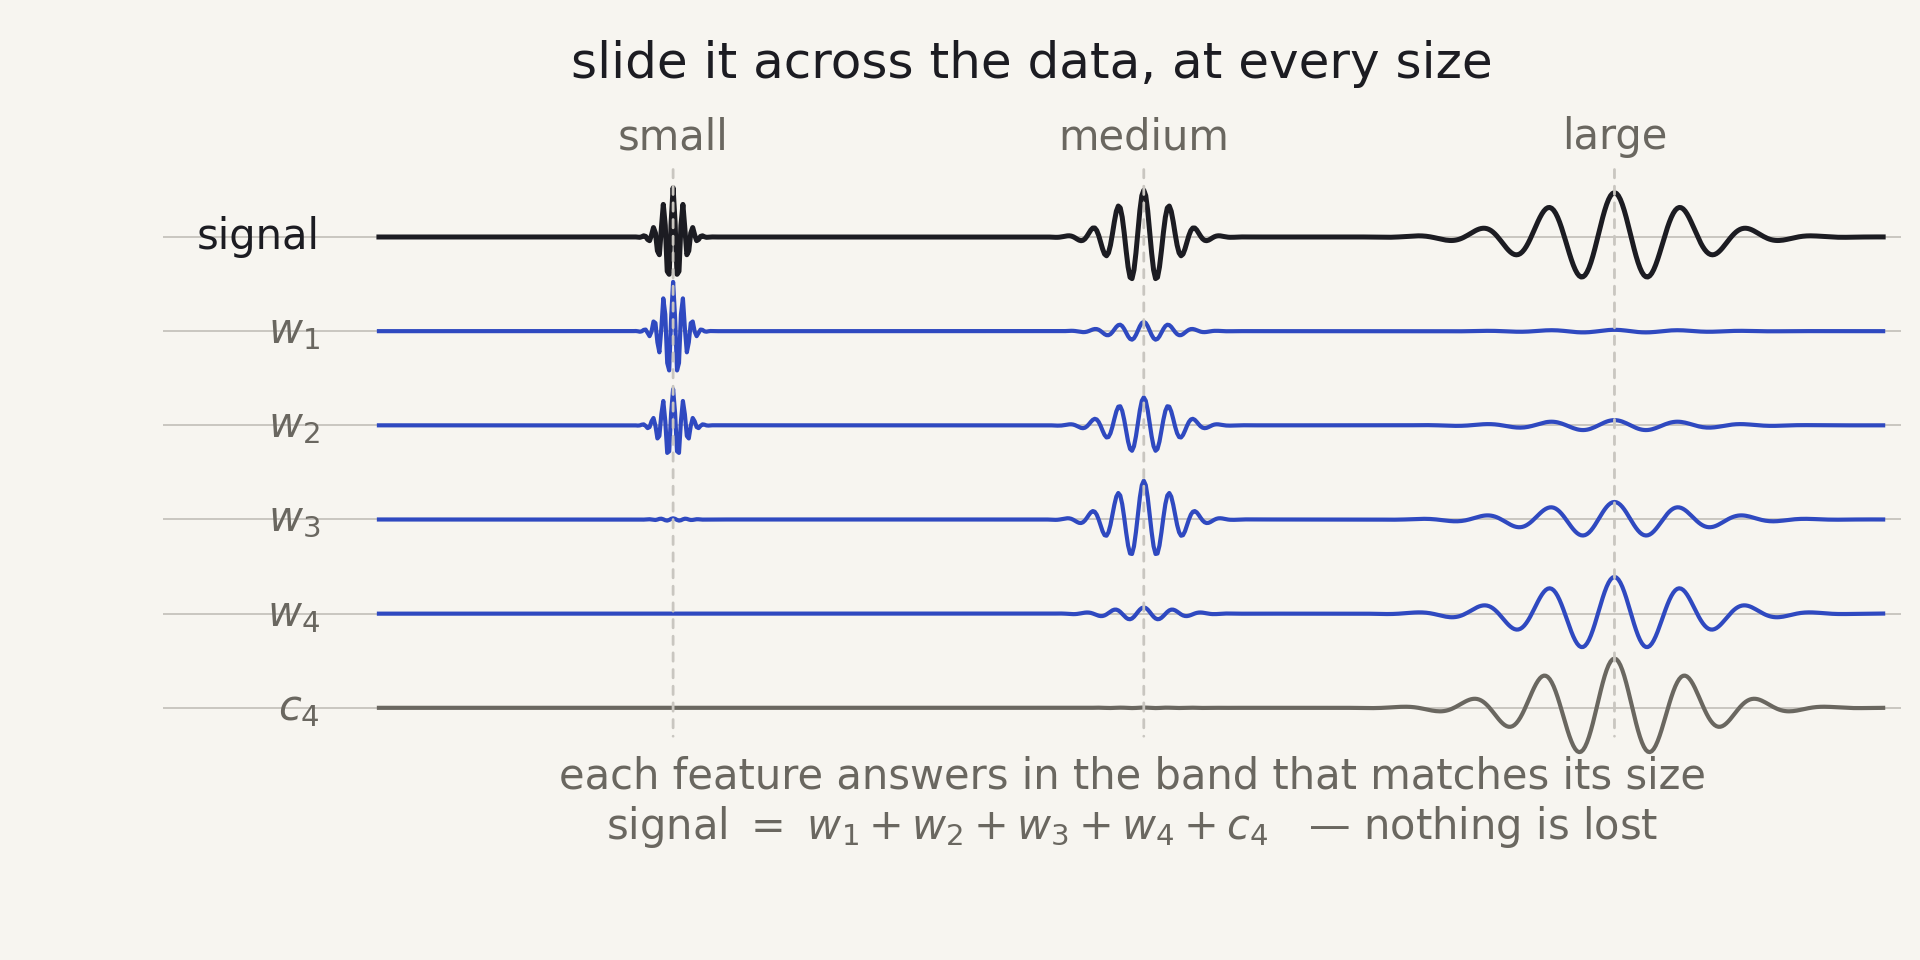
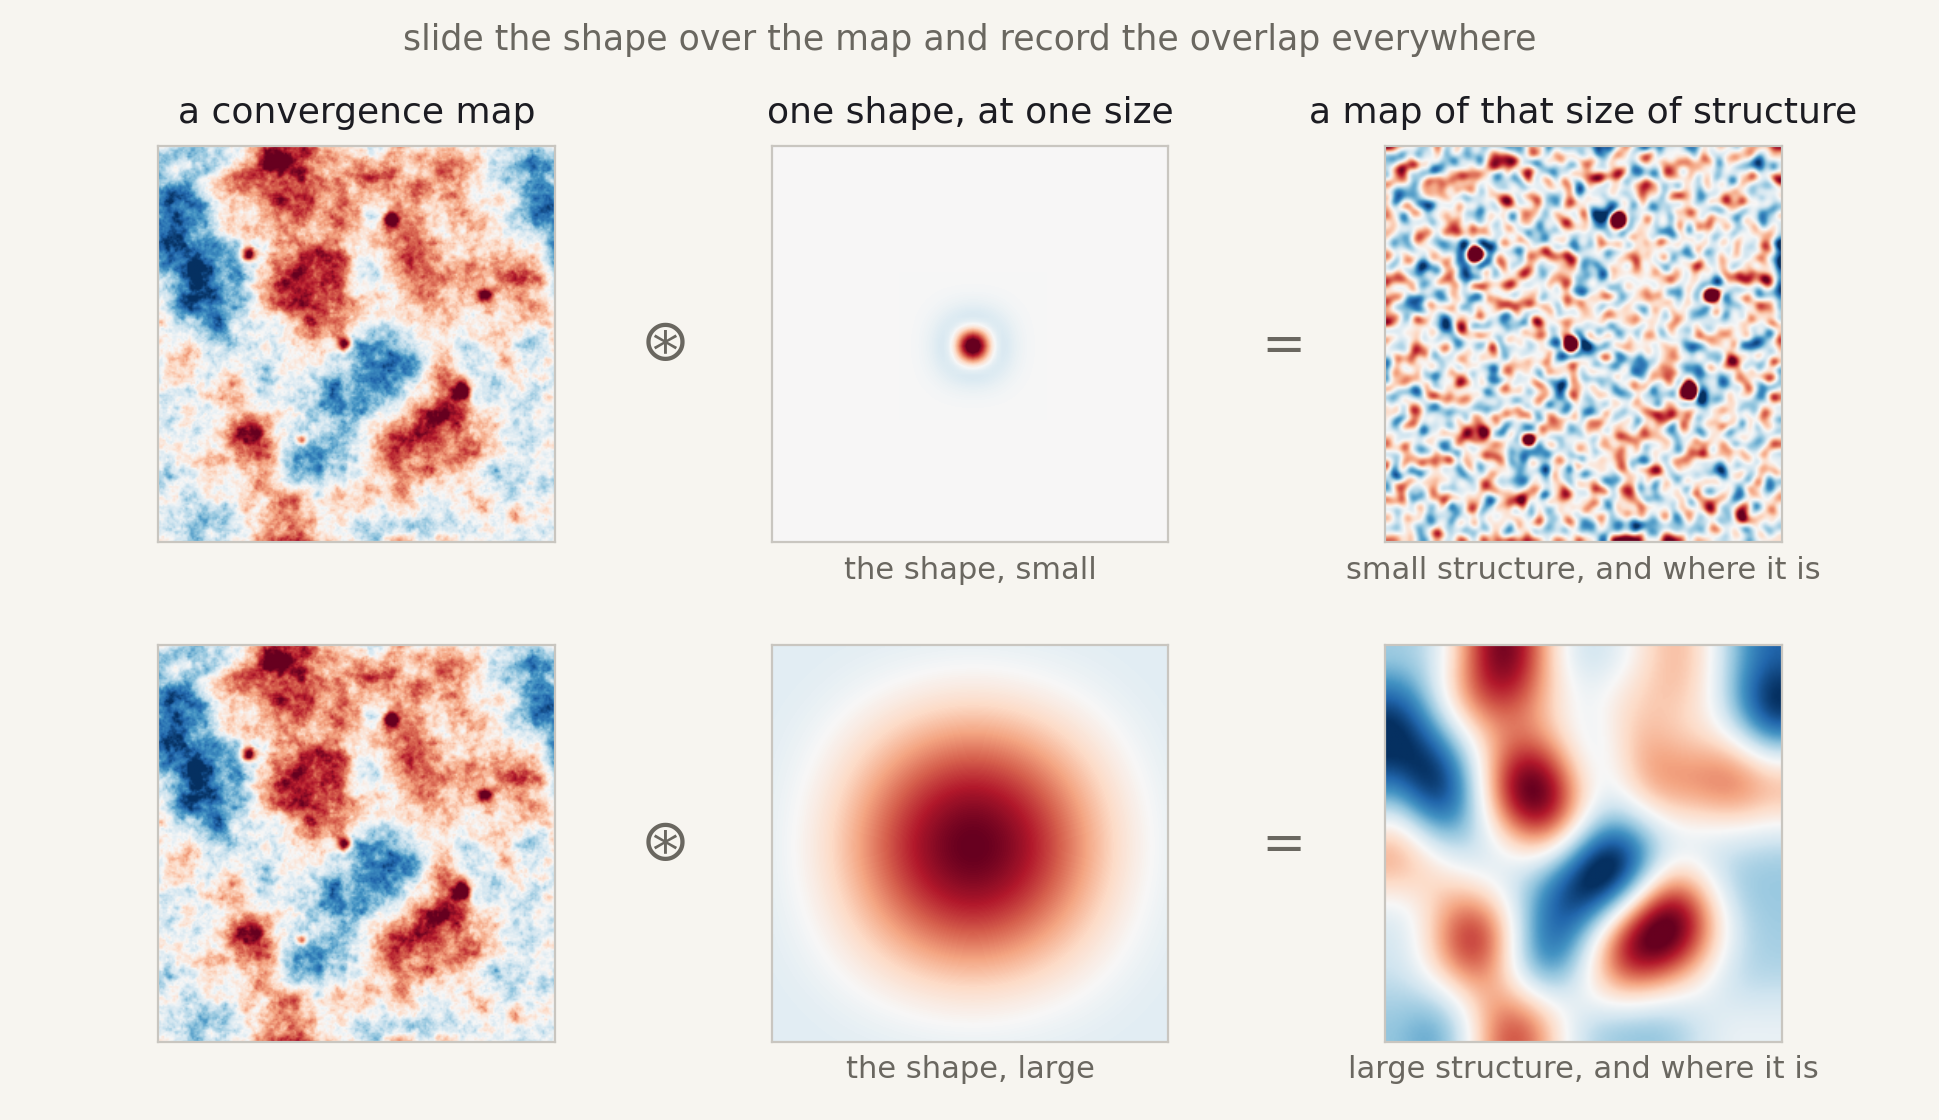
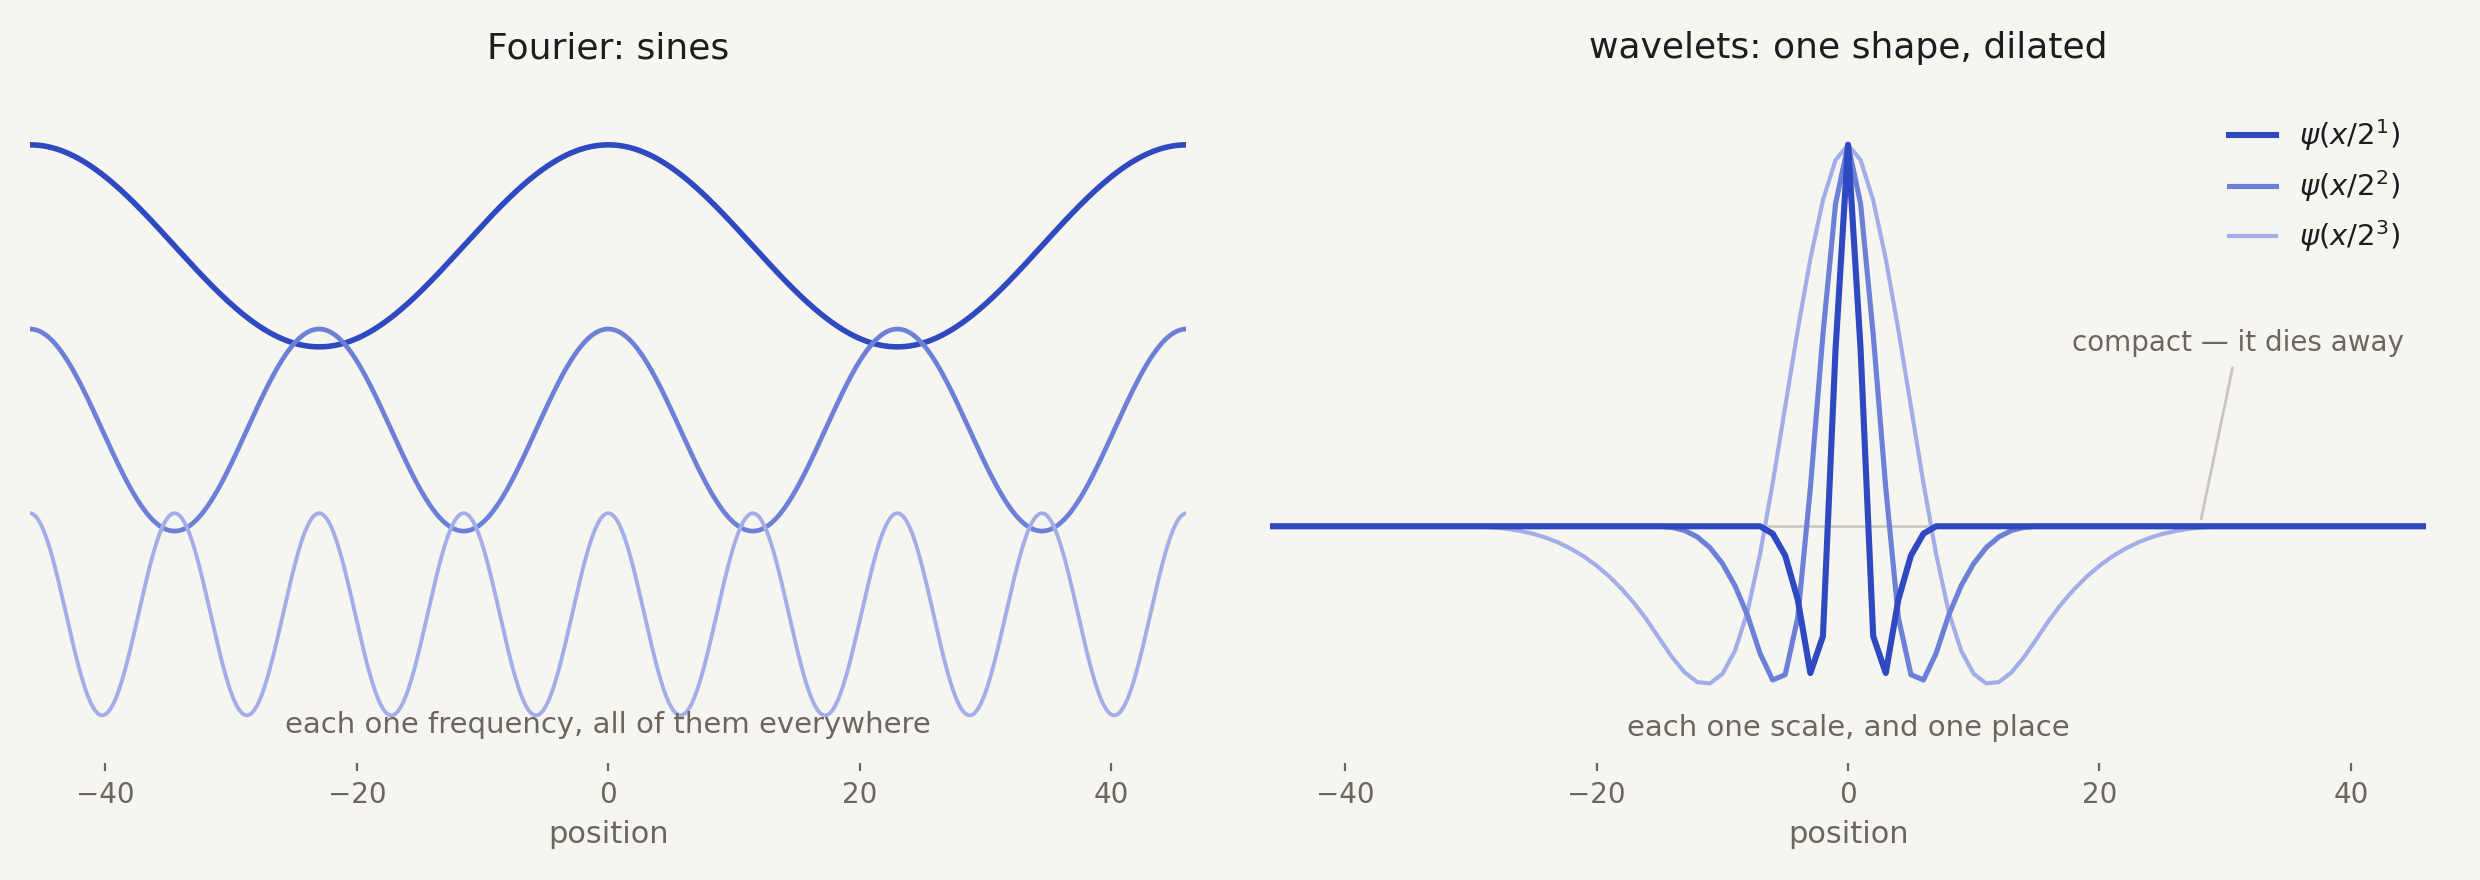
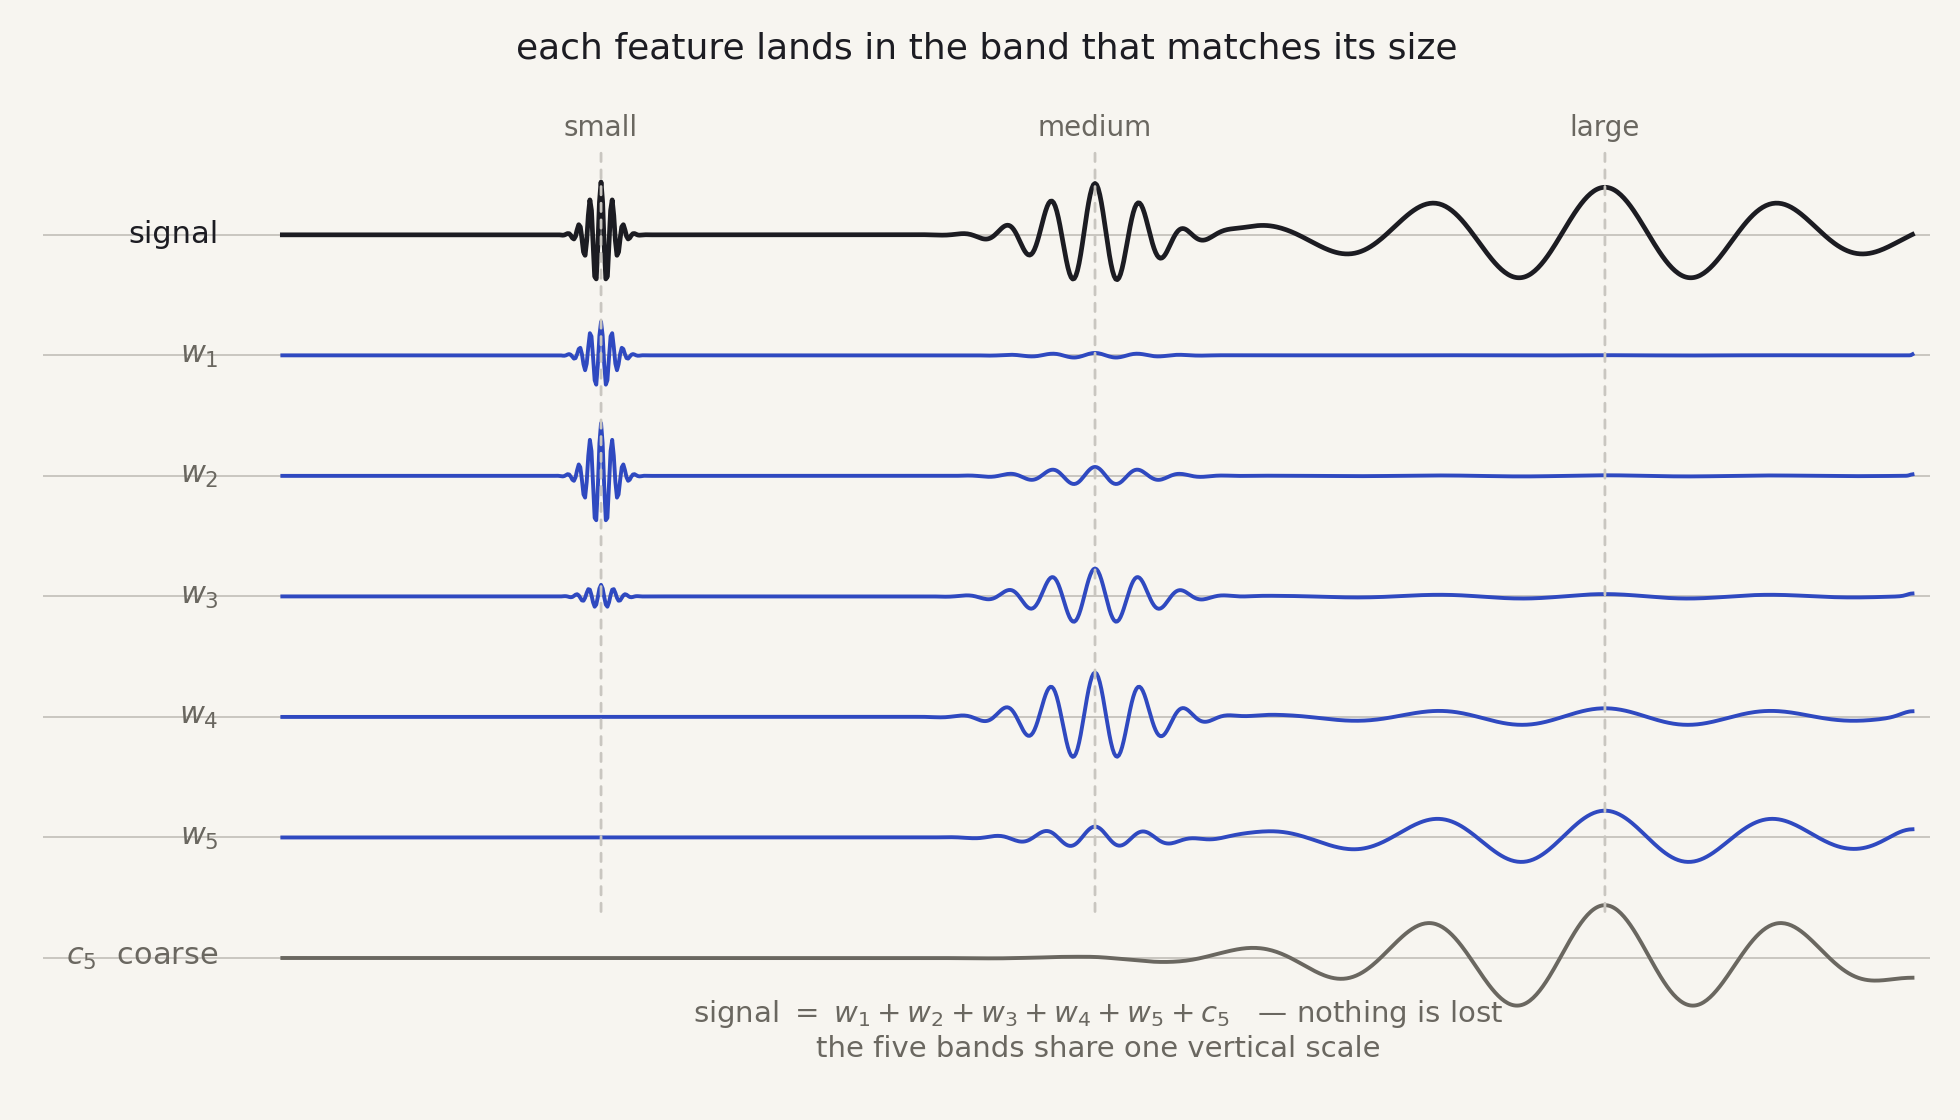
why wavelets for convergence maps
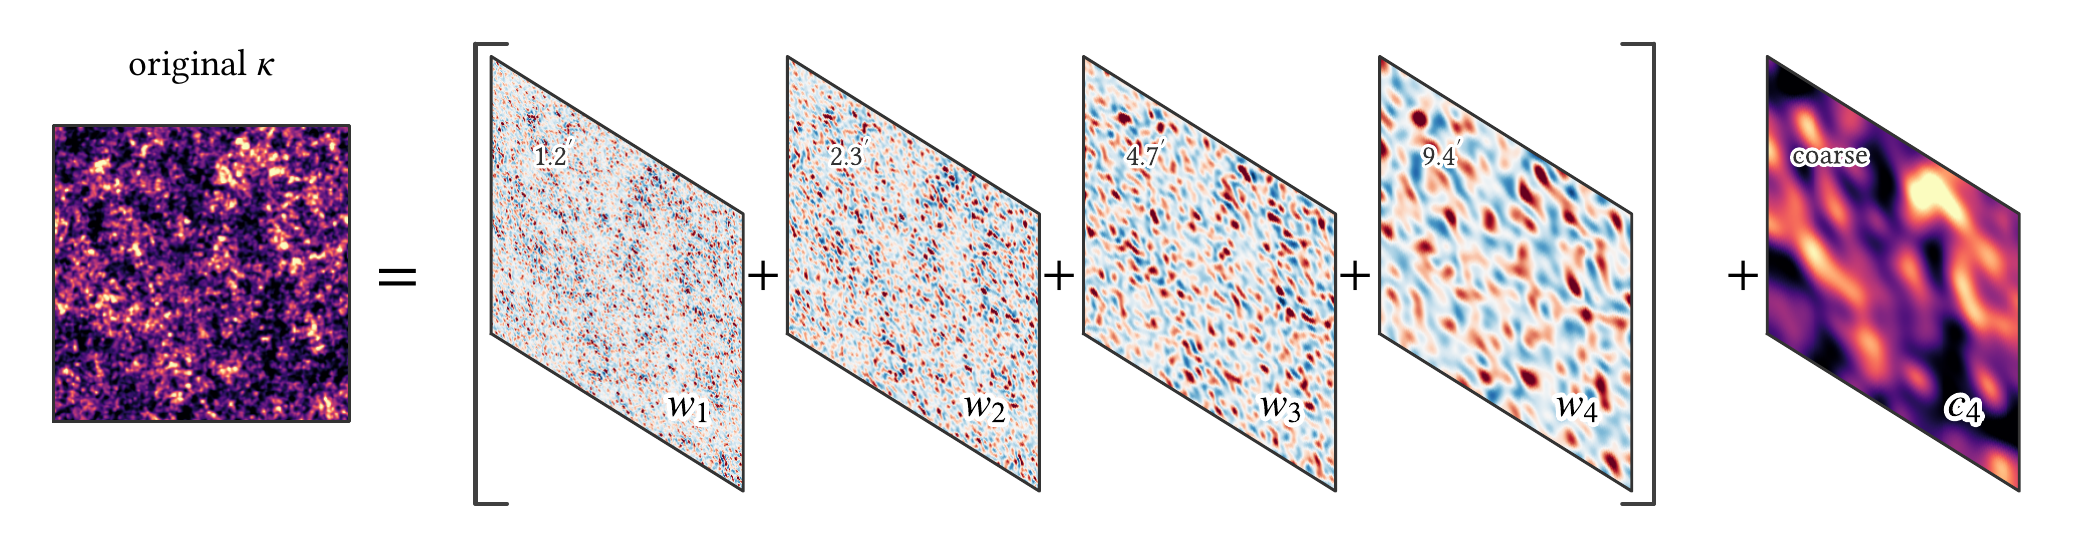
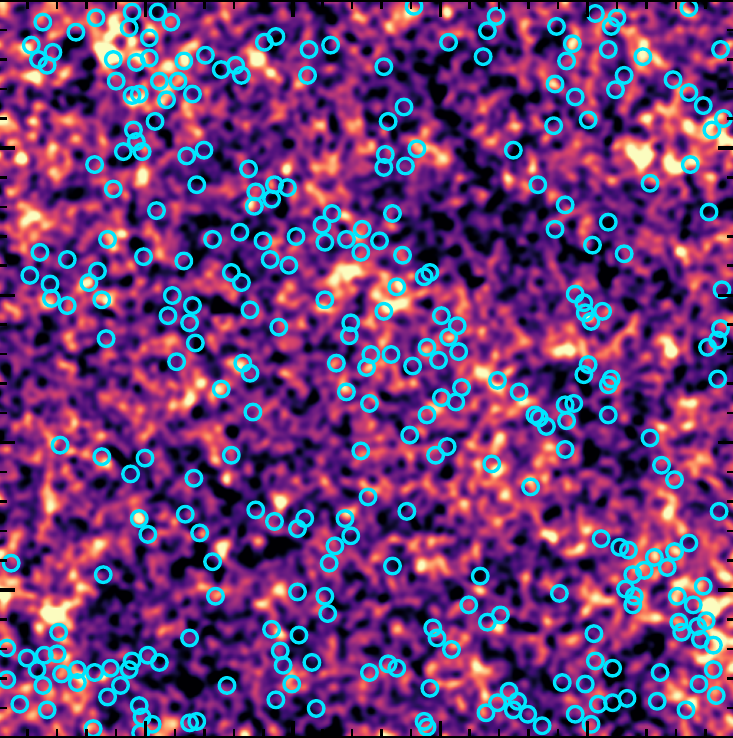
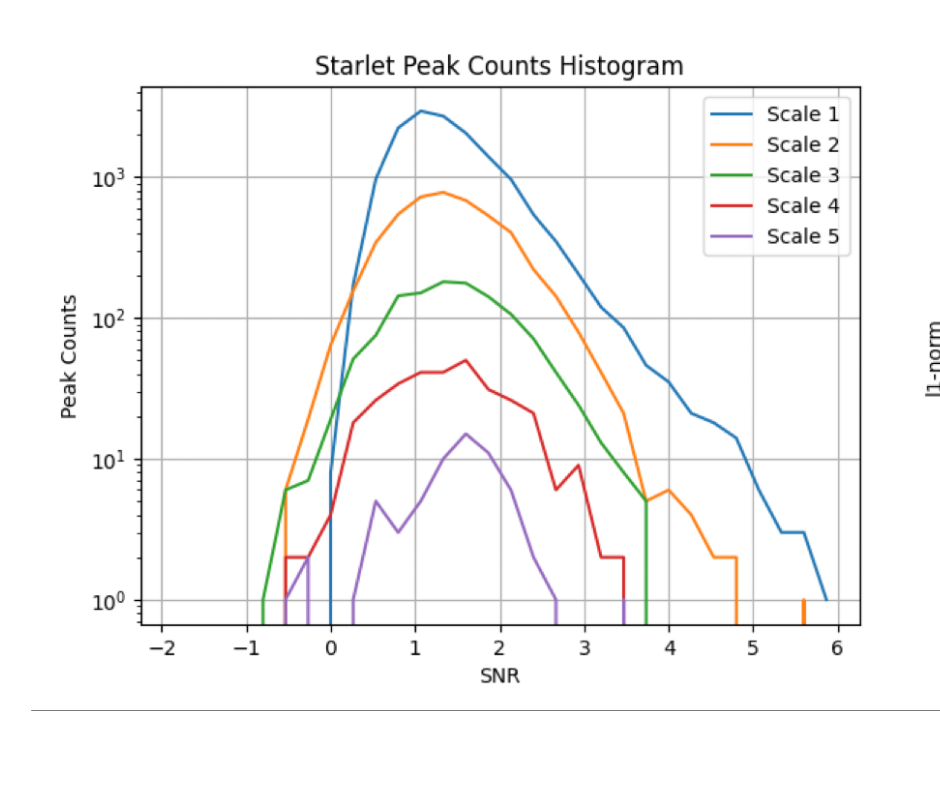
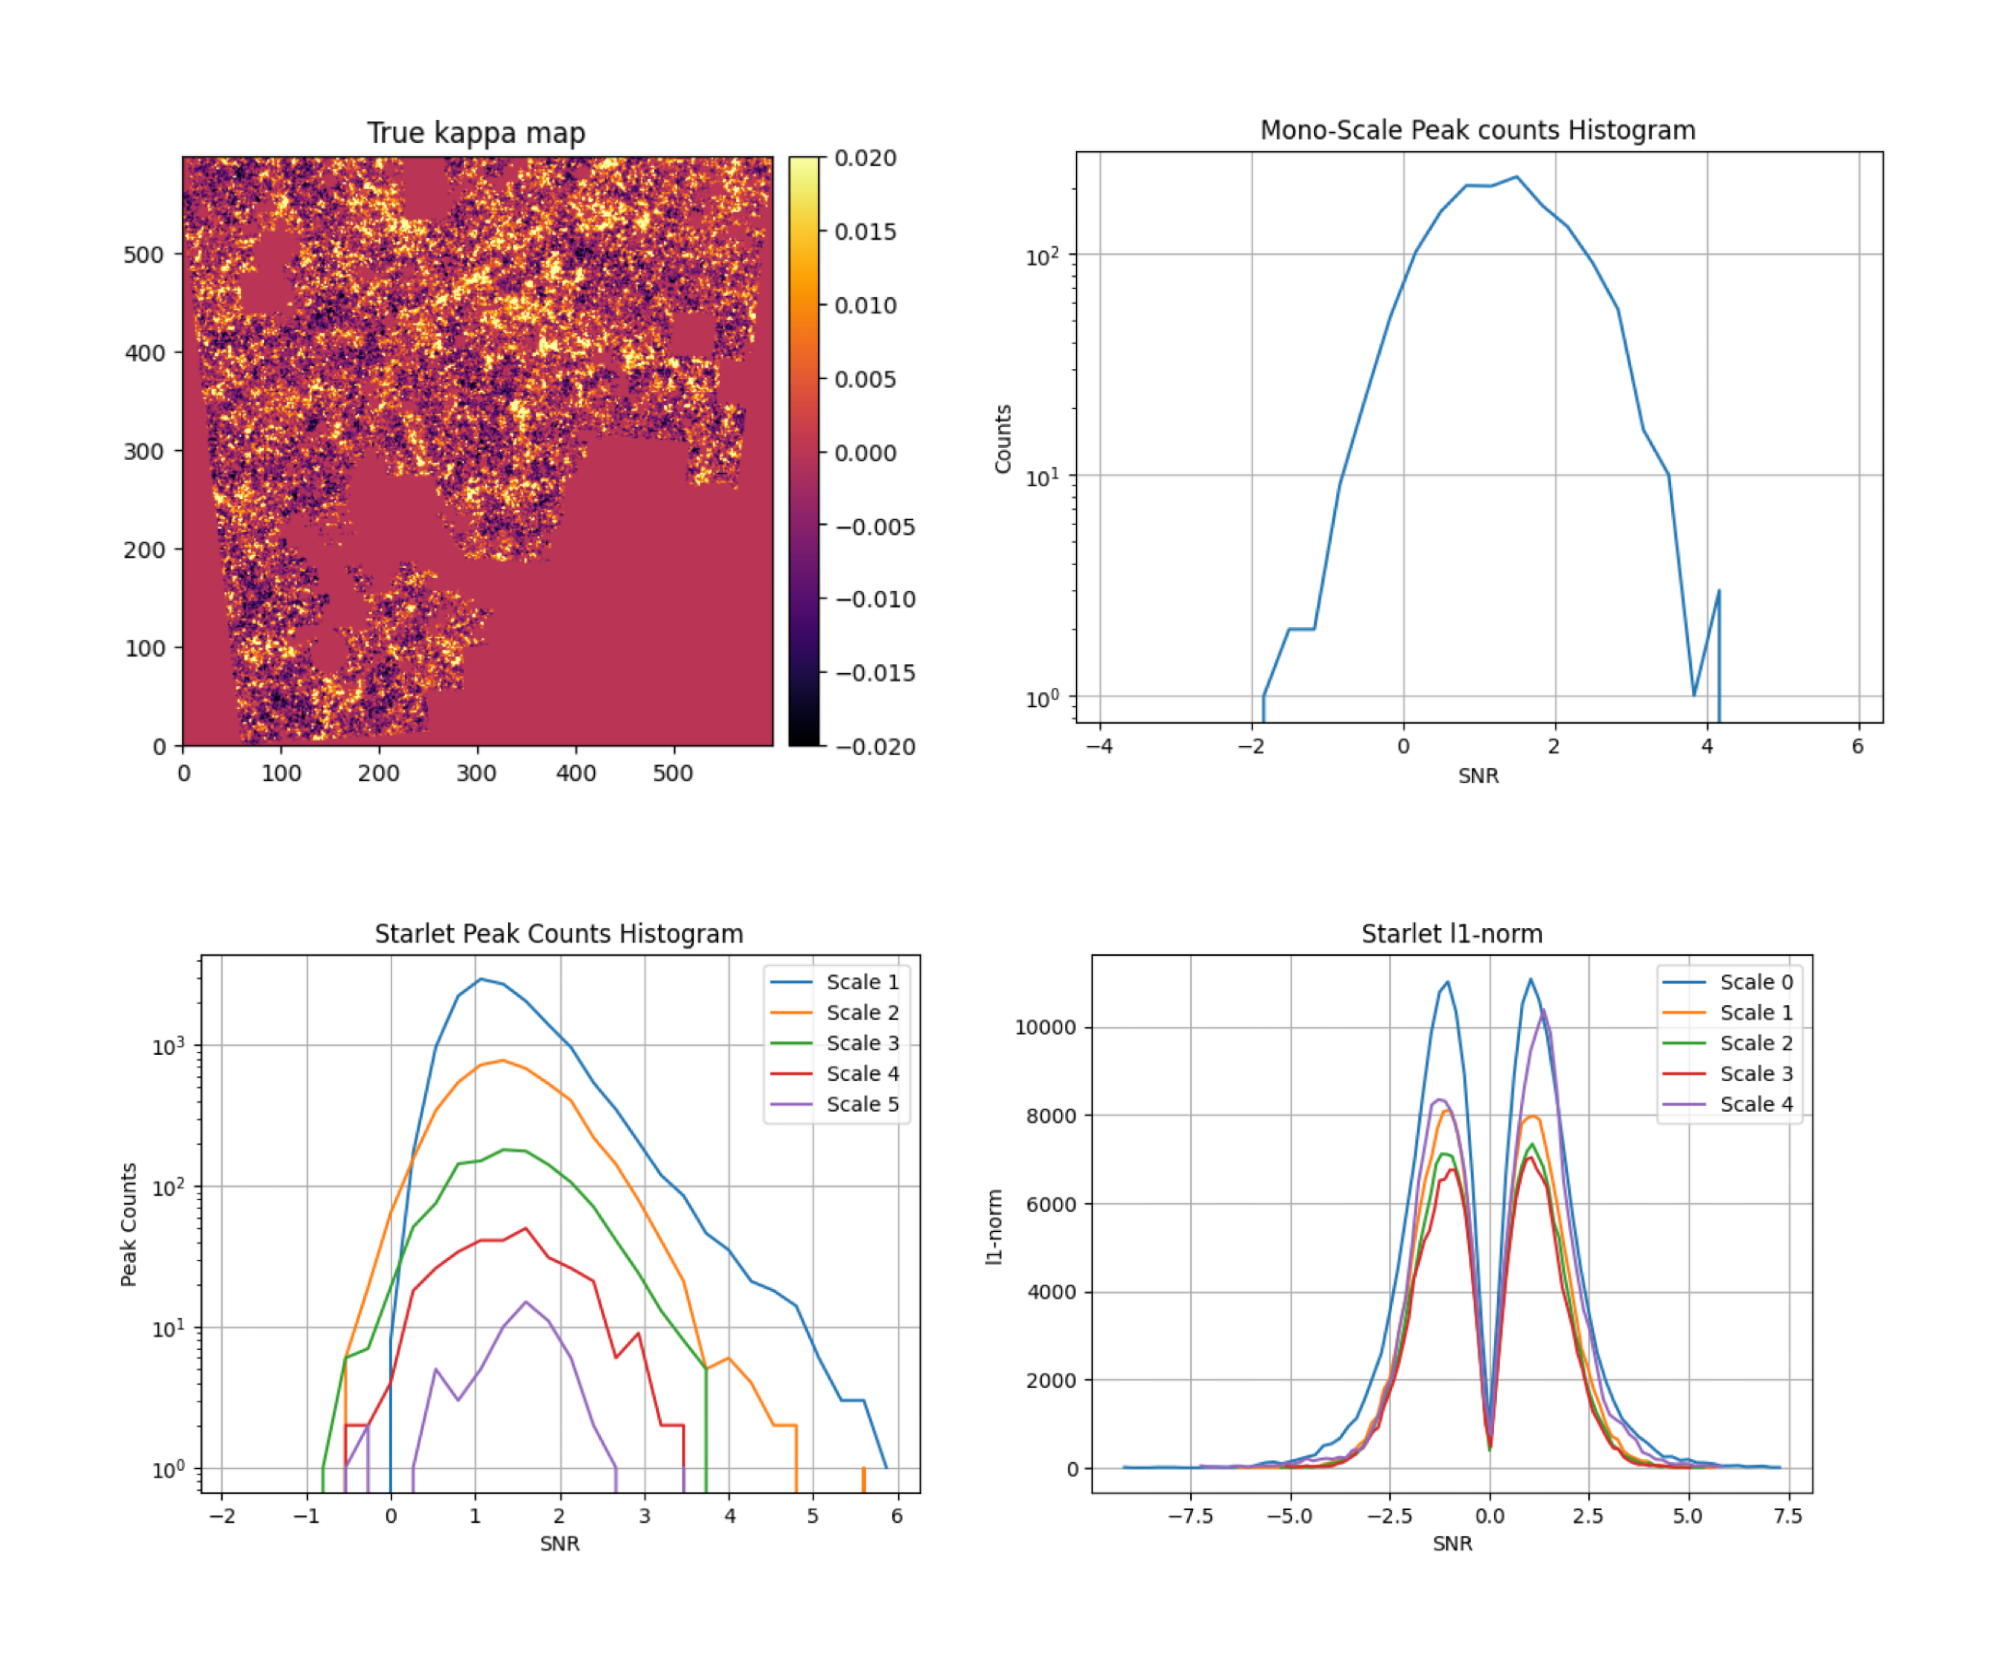
local maxima of the $\kappa$ field, counted per $\kappa$ bin → focus only on a subset of the field
$\mathcal{S}_{j,i}$ are the coefficients of scale $j$ whose $\kappa$ falls in bin $i$
sum of absolute coefficients per band and $\kappa$ bin → encodes information from every pixel (peaks, voids, ...)
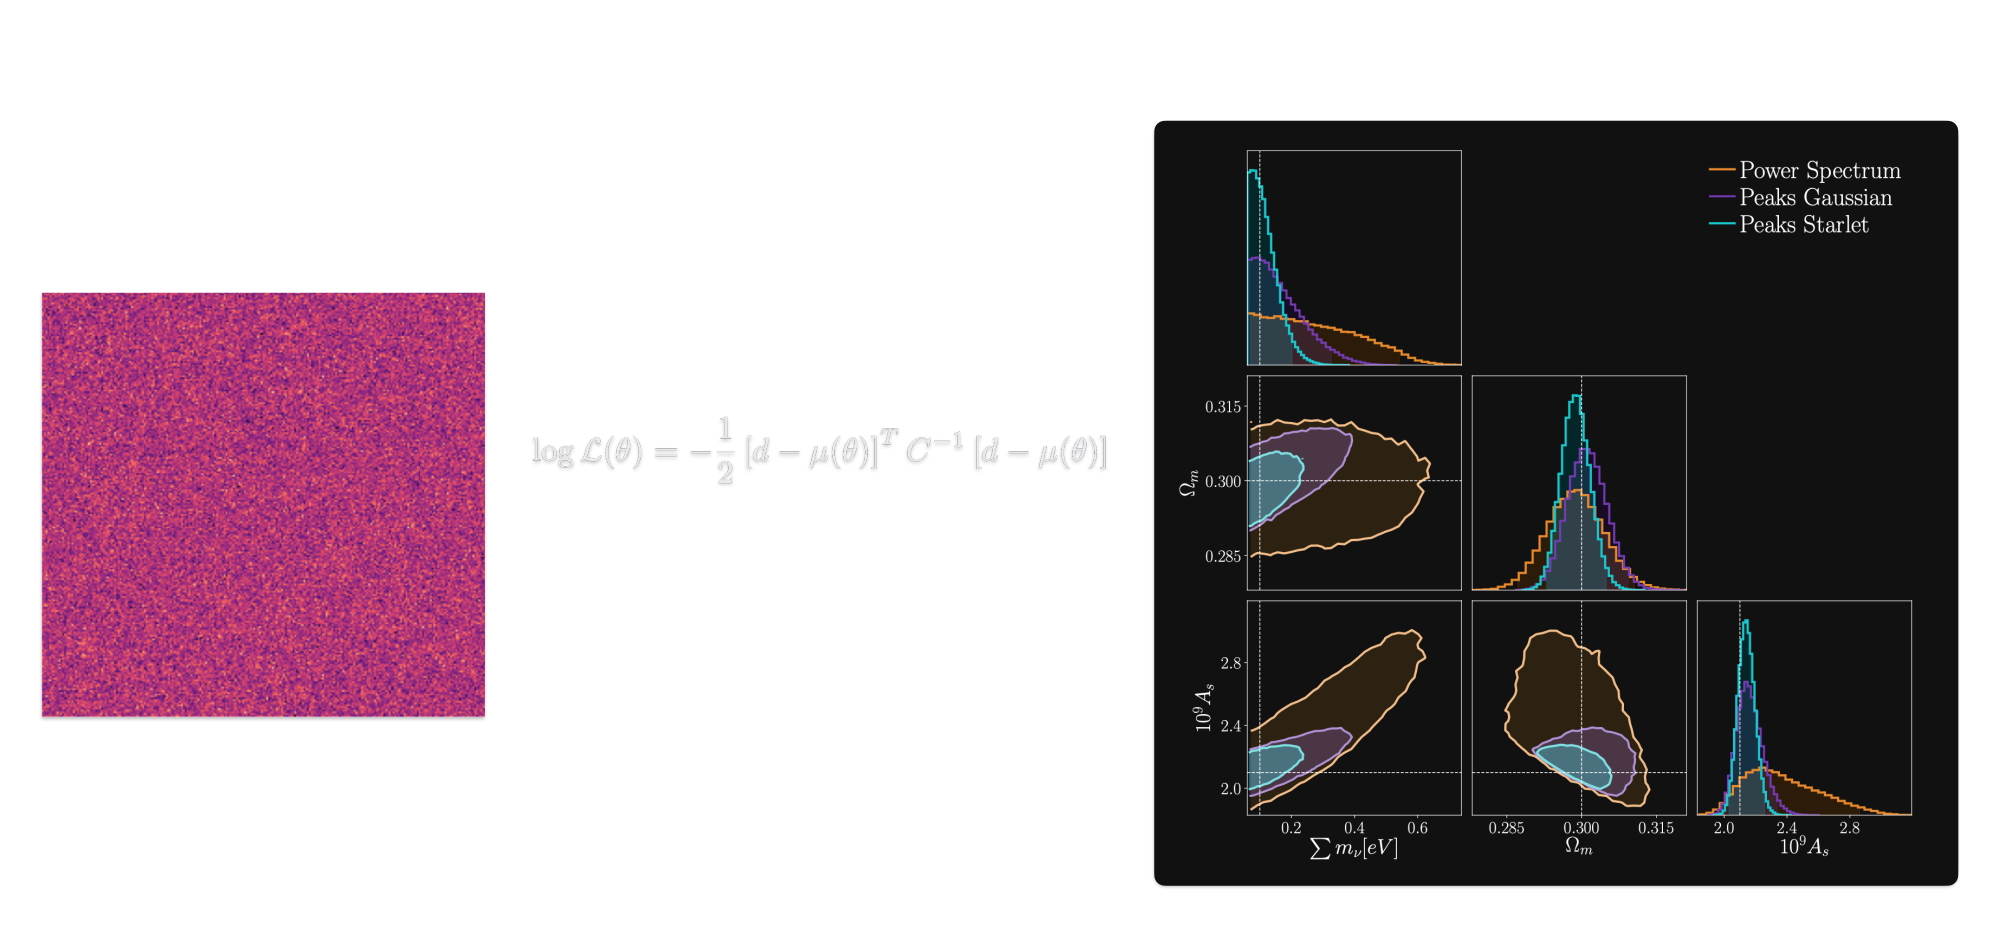
Bayes' theorem: the probability of the parameters given the data is proportional to the probability of the data given the parameters, times the prior.
The likelihood is usually assumed Gaussian in the data vector:
$$p(d \mid \theta) \;\propto\; \exp\!\left[-\tfrac{1}{2}\big(d - \underbrace{m(\theta)}_{\text{theory}}\big)^{\!\top} \underbrace{\mathbf{C}^{-1}}_{\text{covariance}} \big(d - m(\theta)\big)\right]$$
The posterior is then sampled with MCMC.
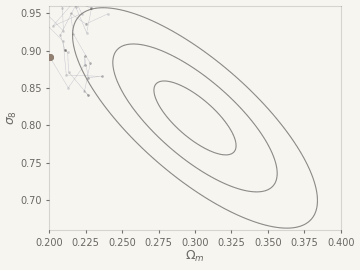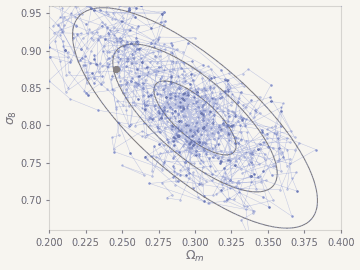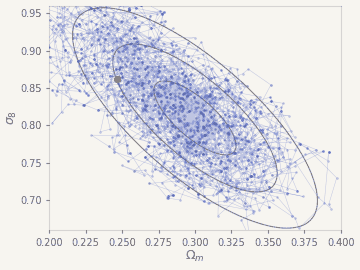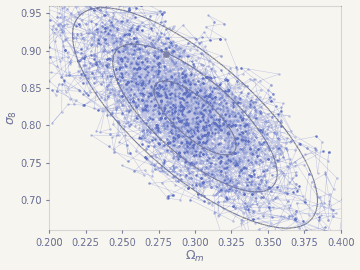
Learn the distribution from which a set of samples was drawn.
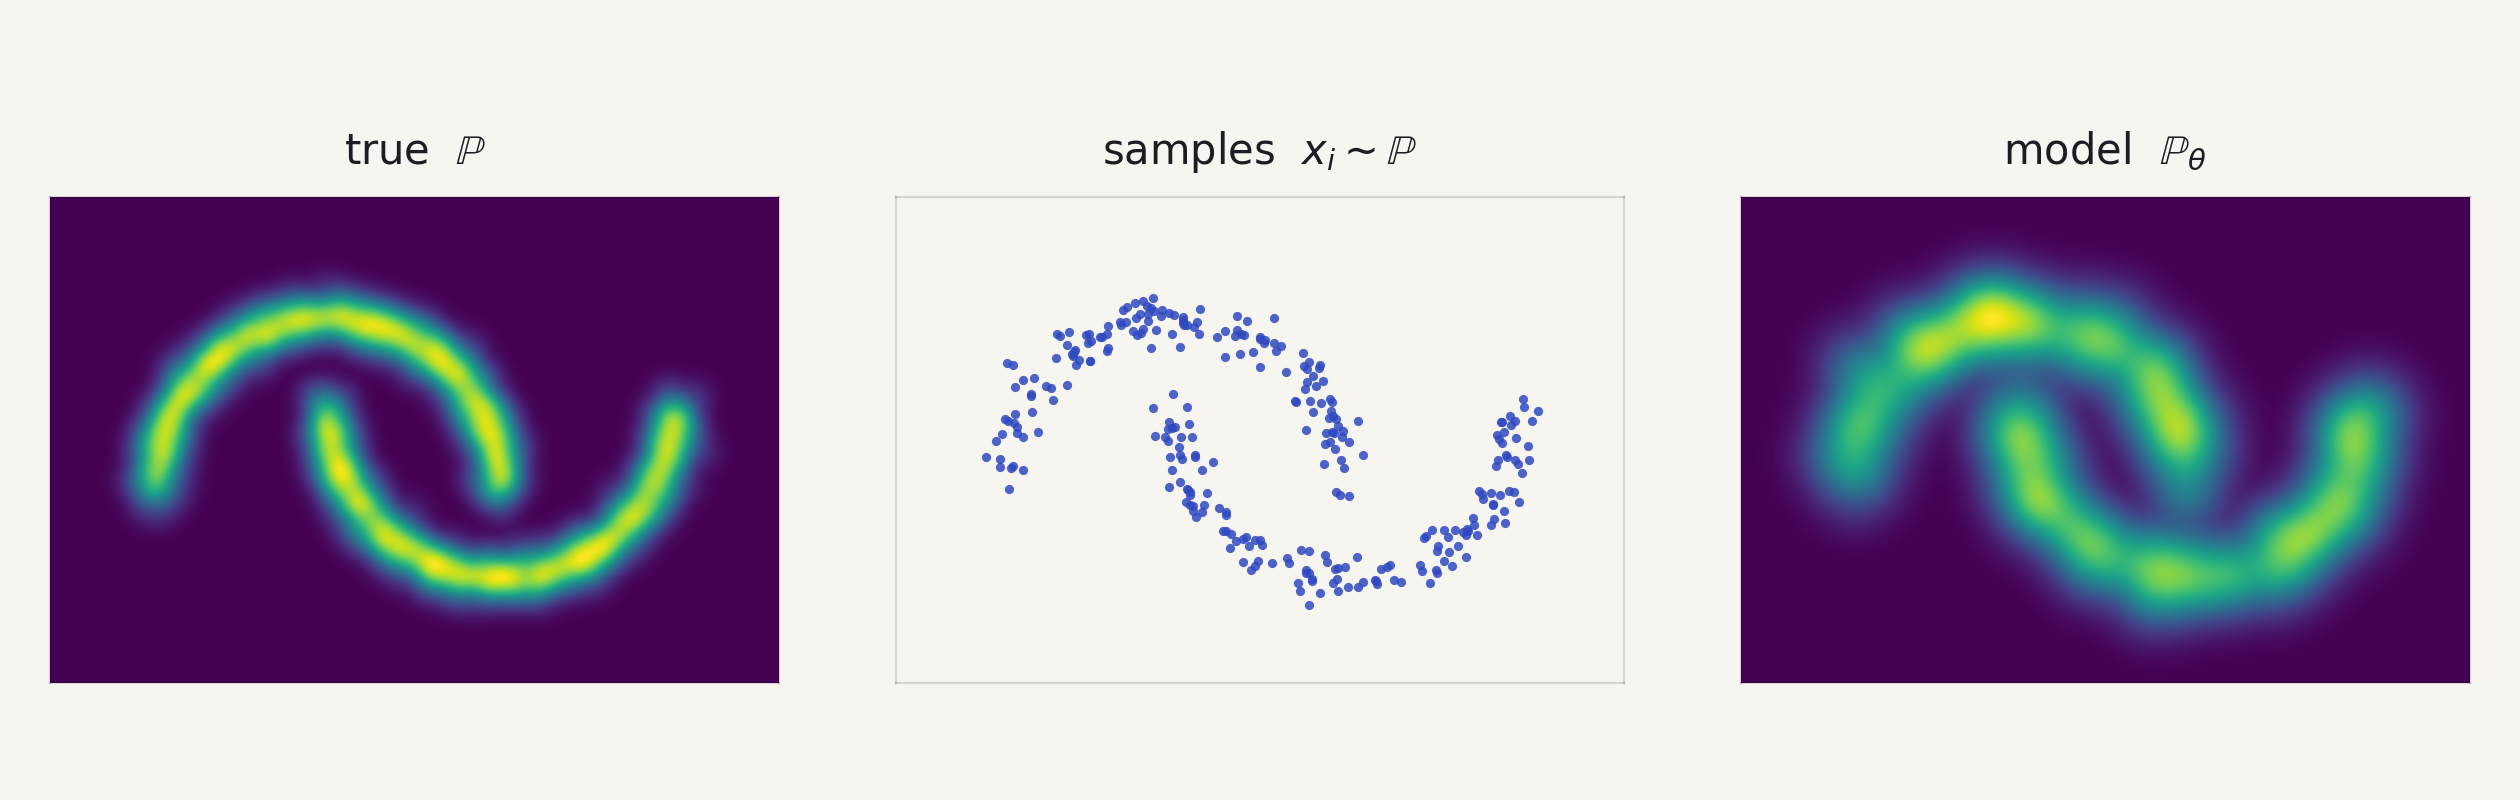
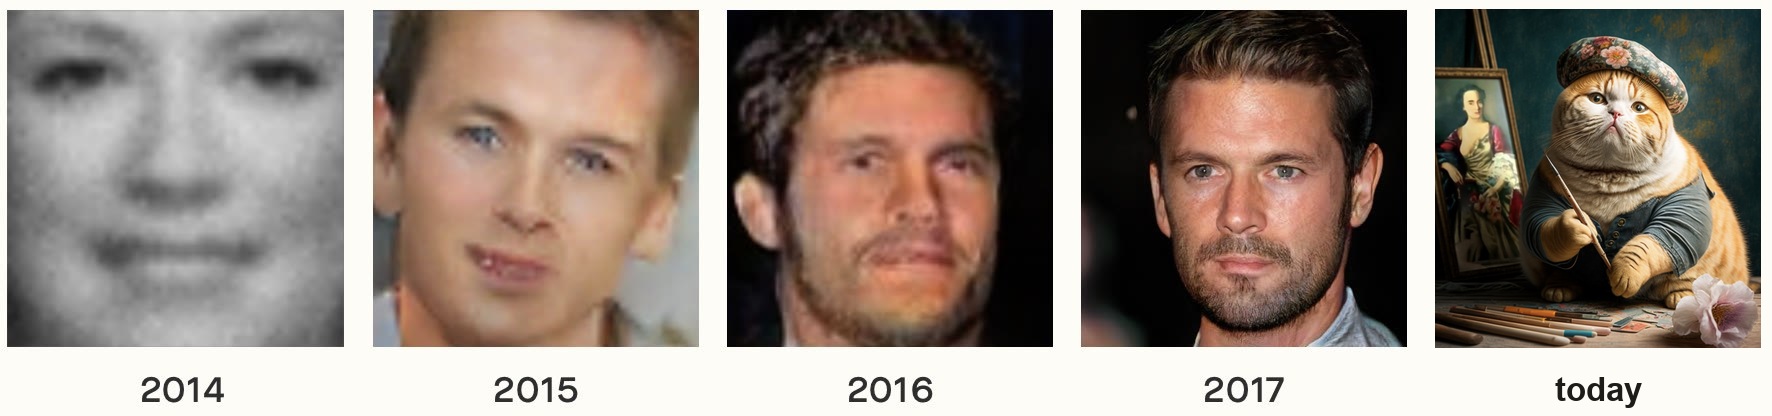
Learn $\mathbb{P}_\theta$, then sample from it.
2014–2017 panels adapted from Shirvani, Image Generation Models: A Technical History, arXiv:2603.07455
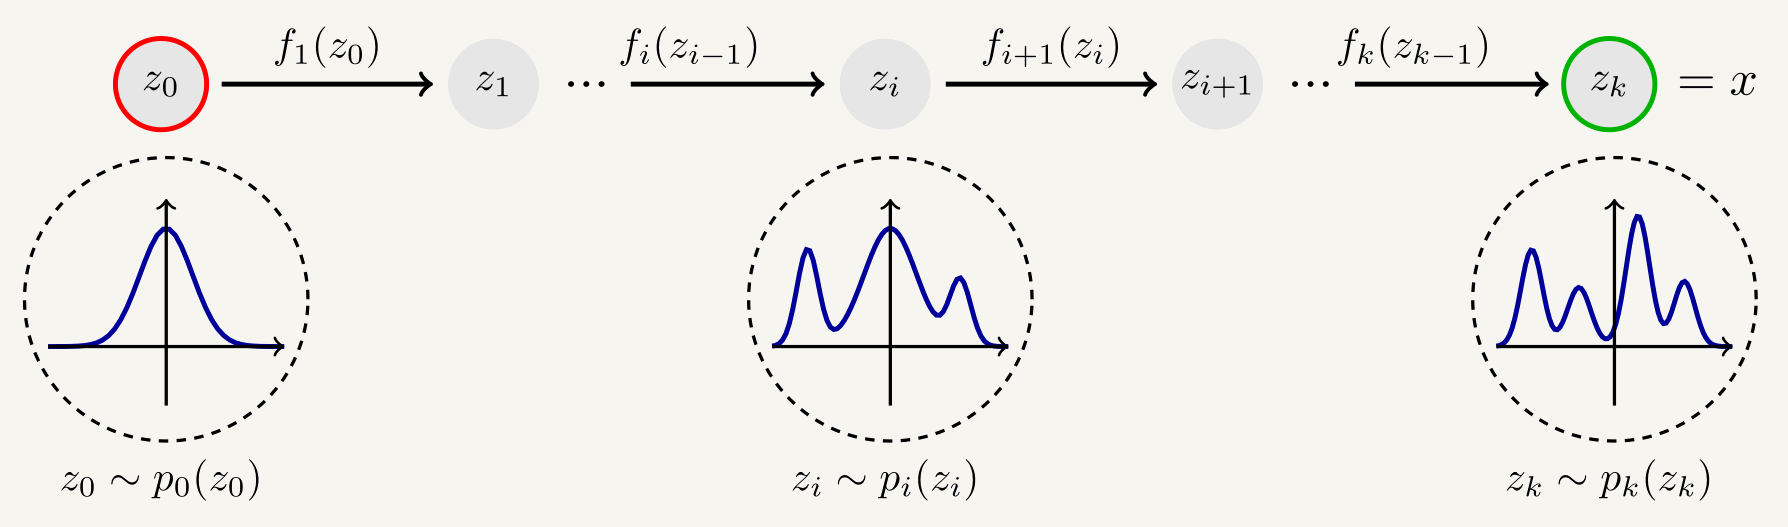
Start from a unit Gaussian and learn an invertible map to the target distribution. The density follows from the change of variables formula:
$$\log q_\phi(x) \;=\; \log p\big(f^{-1}(x)\big) \;+\; \log\left|\det \frac{\partial f^{-1}}{\partial x}\right|$$
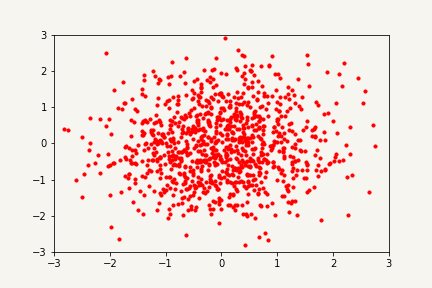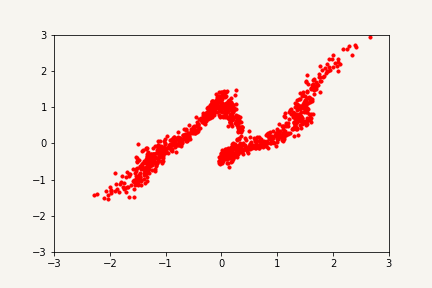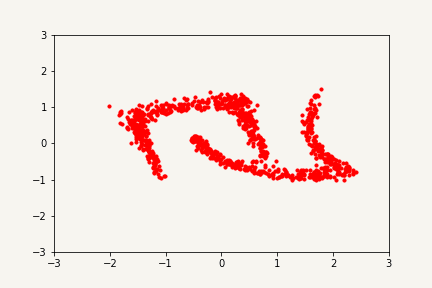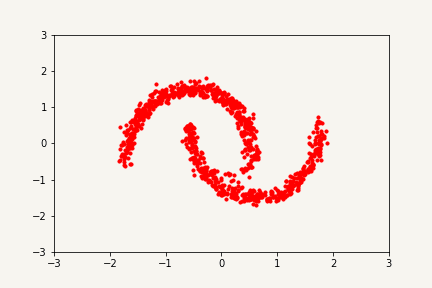
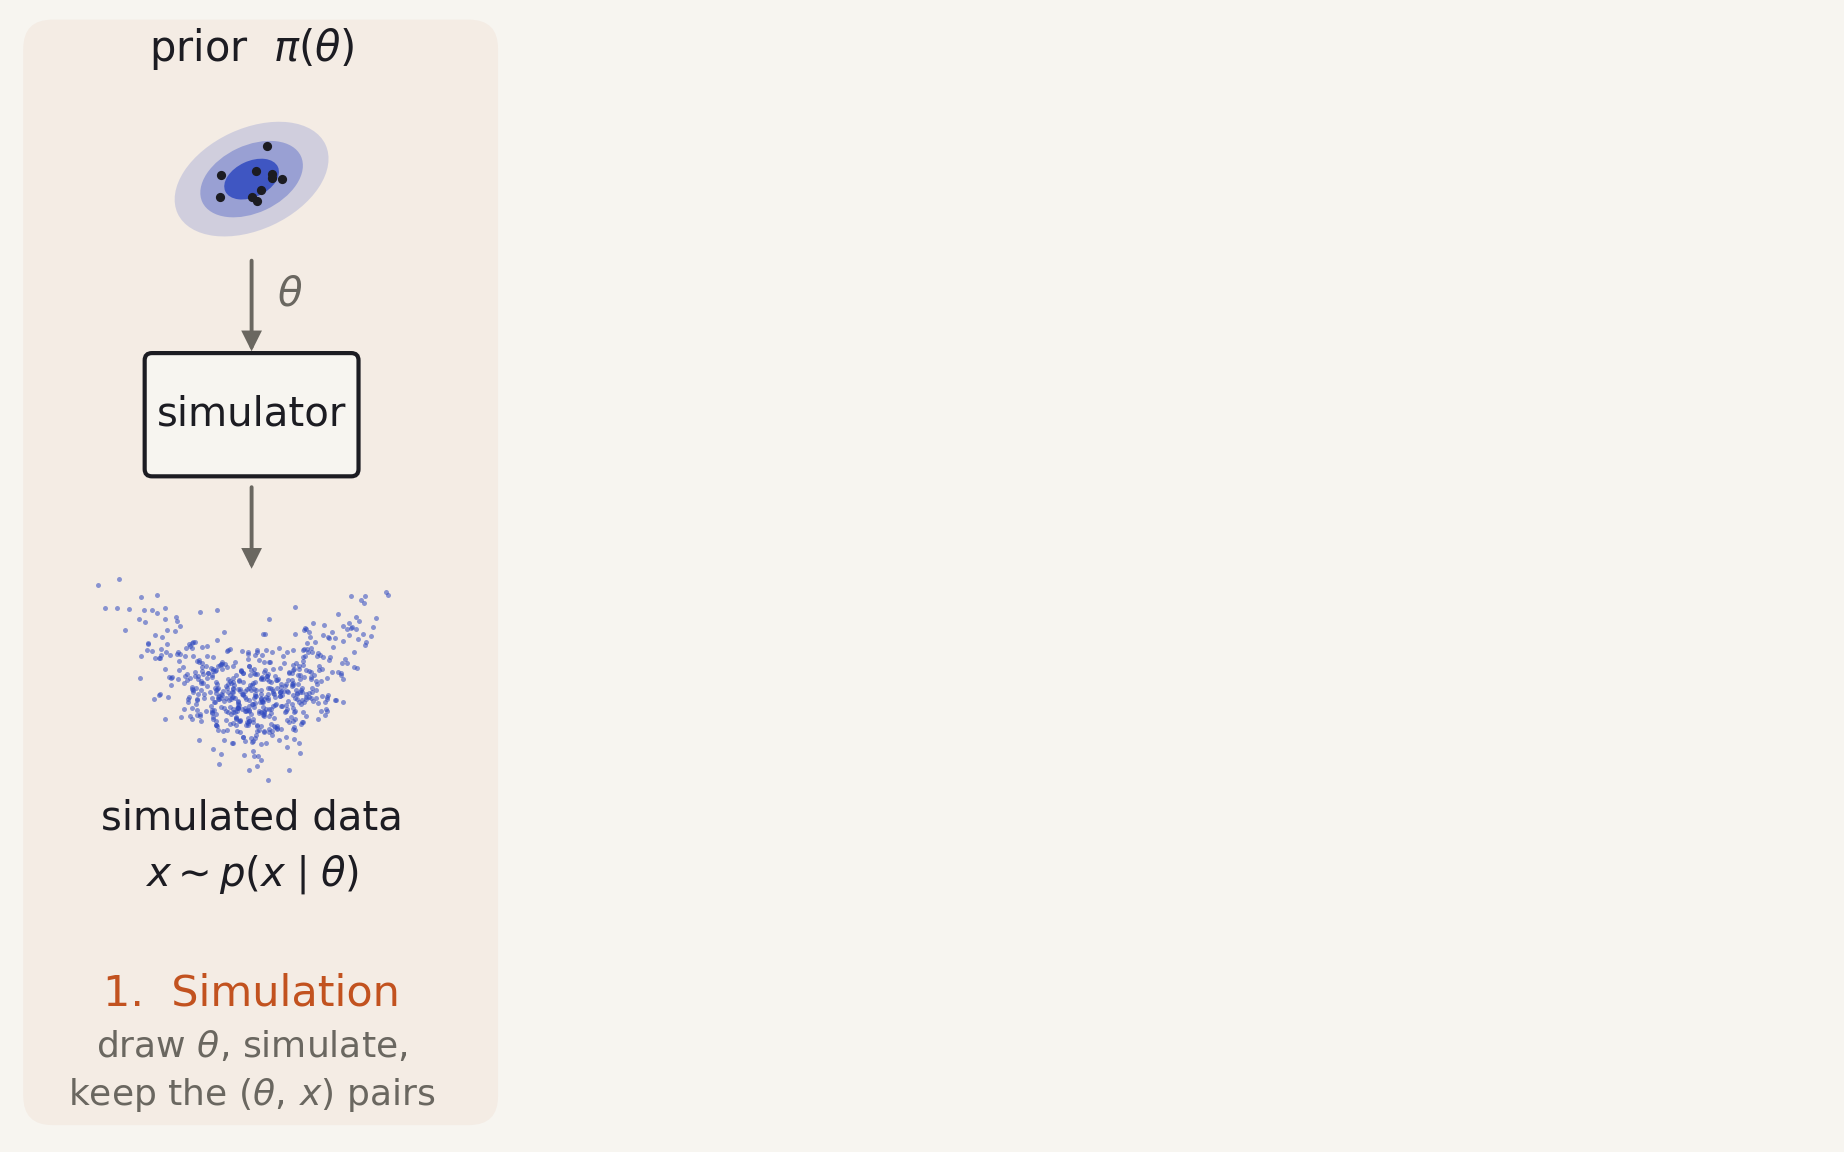
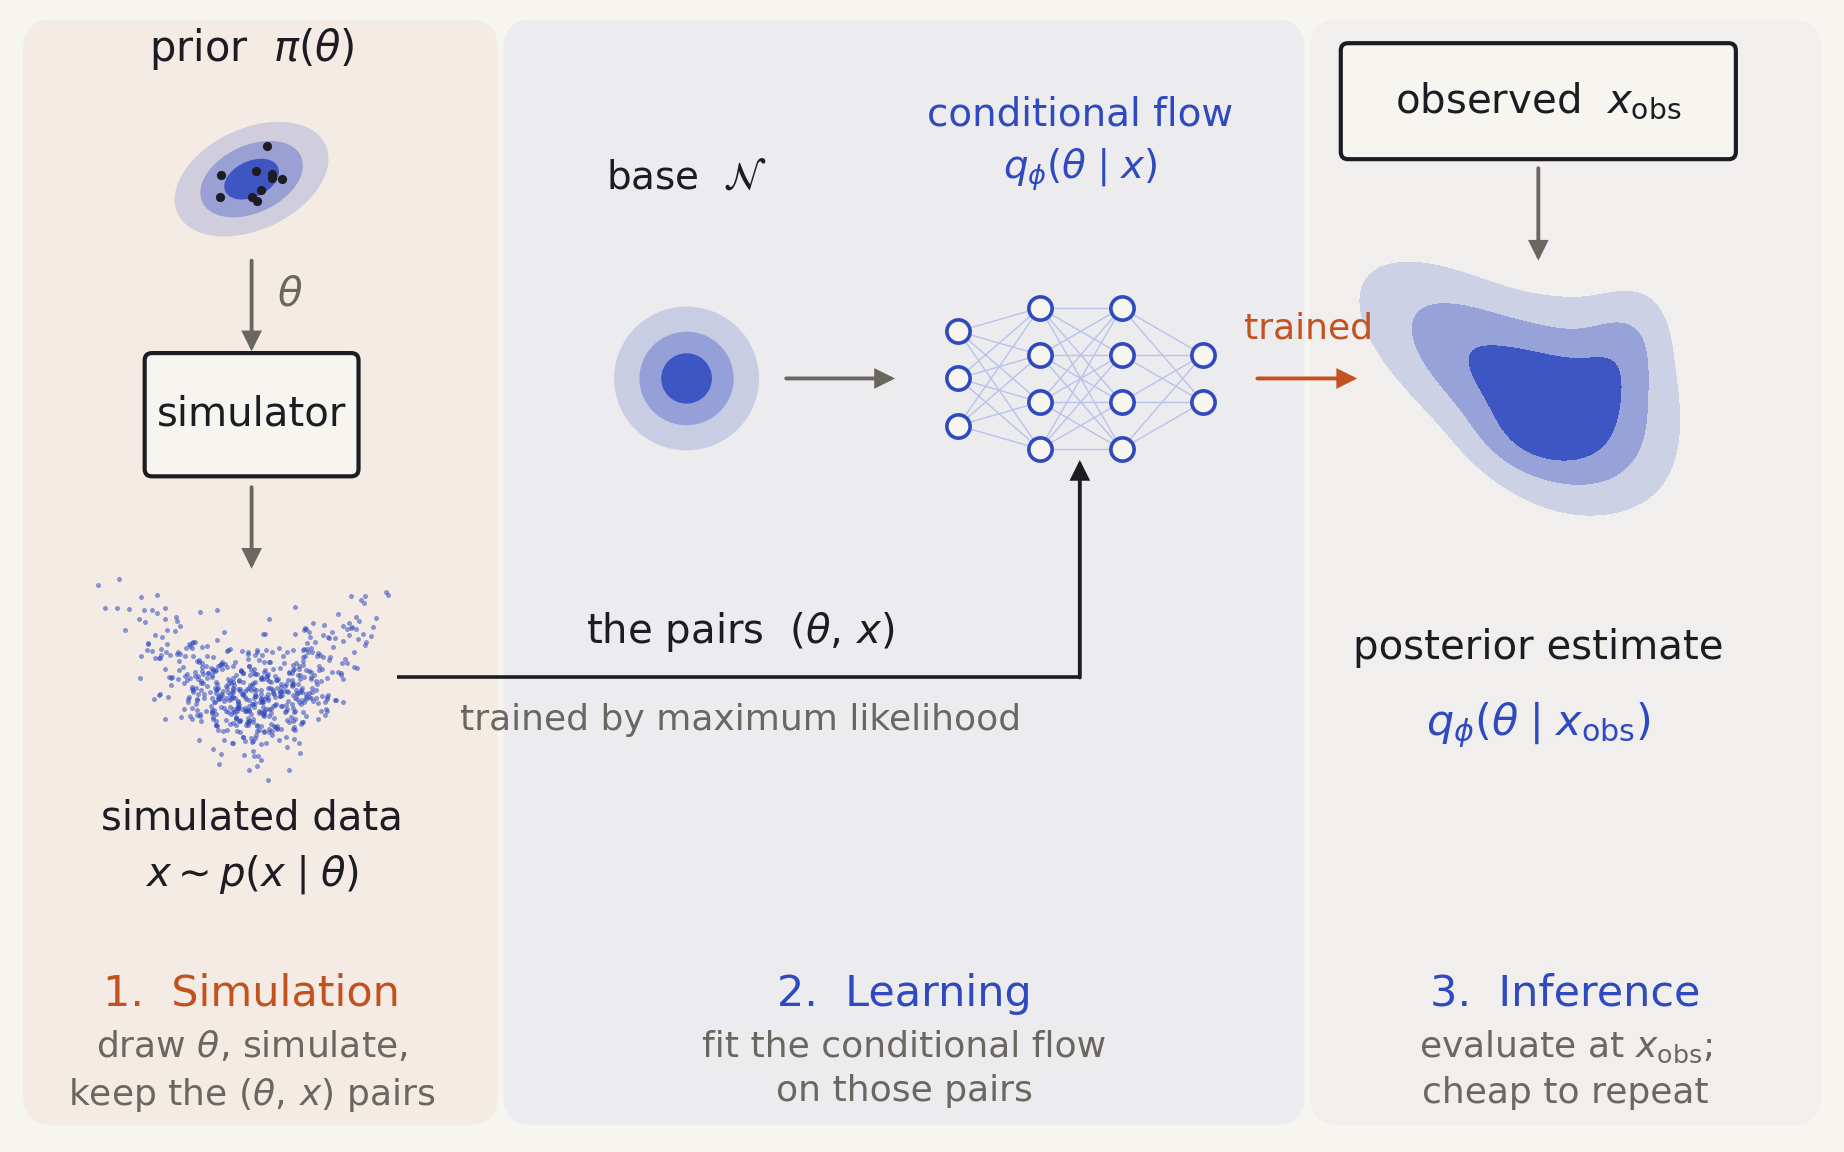
The likelihood $p(x \mid \theta)$ cannot be written down, but the simulator samples from it. The posterior is learned directly from simulated $(\theta, x)$ pairs.
Beating the power spectrum is "easy". The question is how close to all of it we can get.
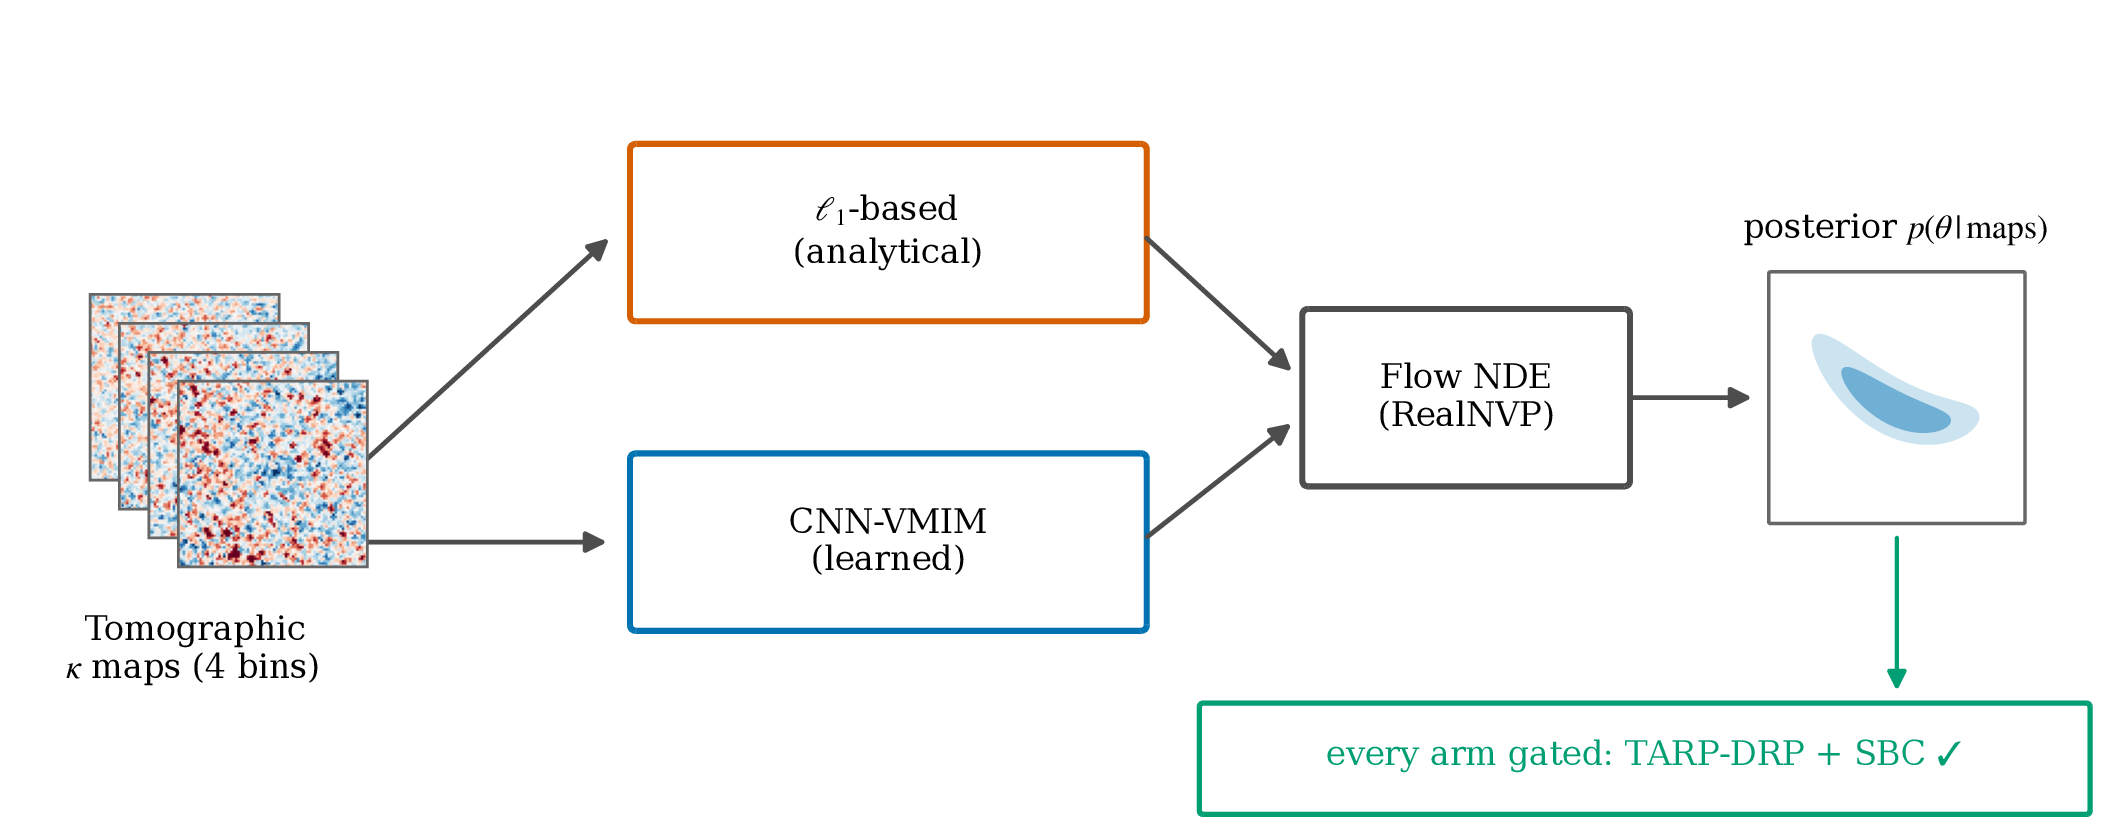
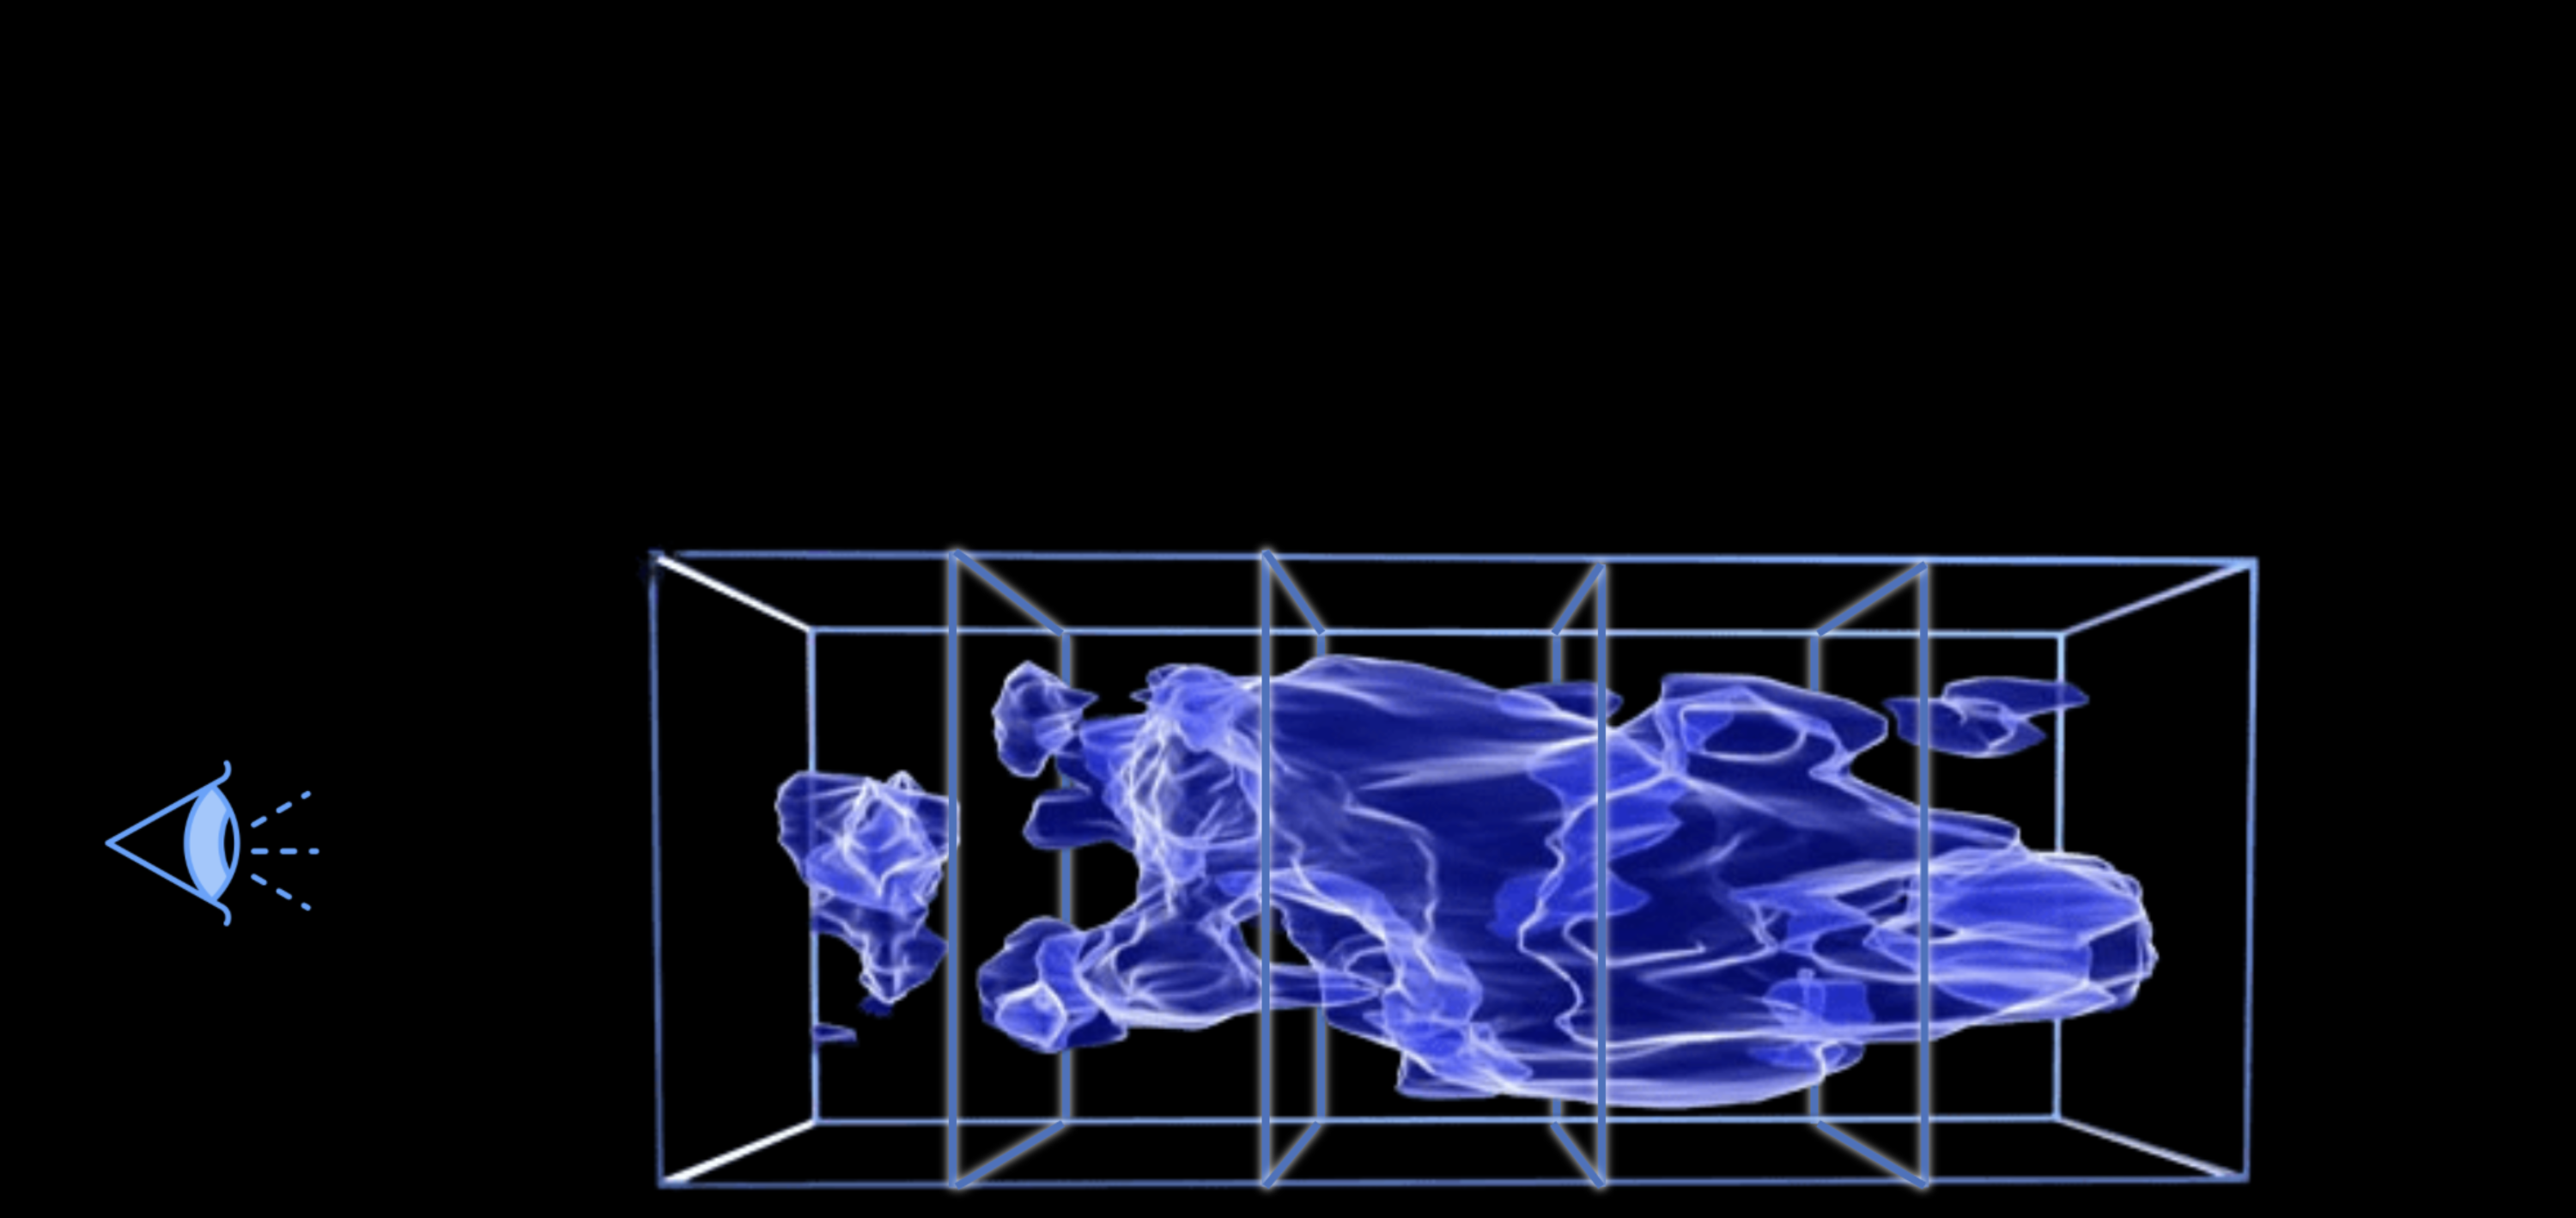
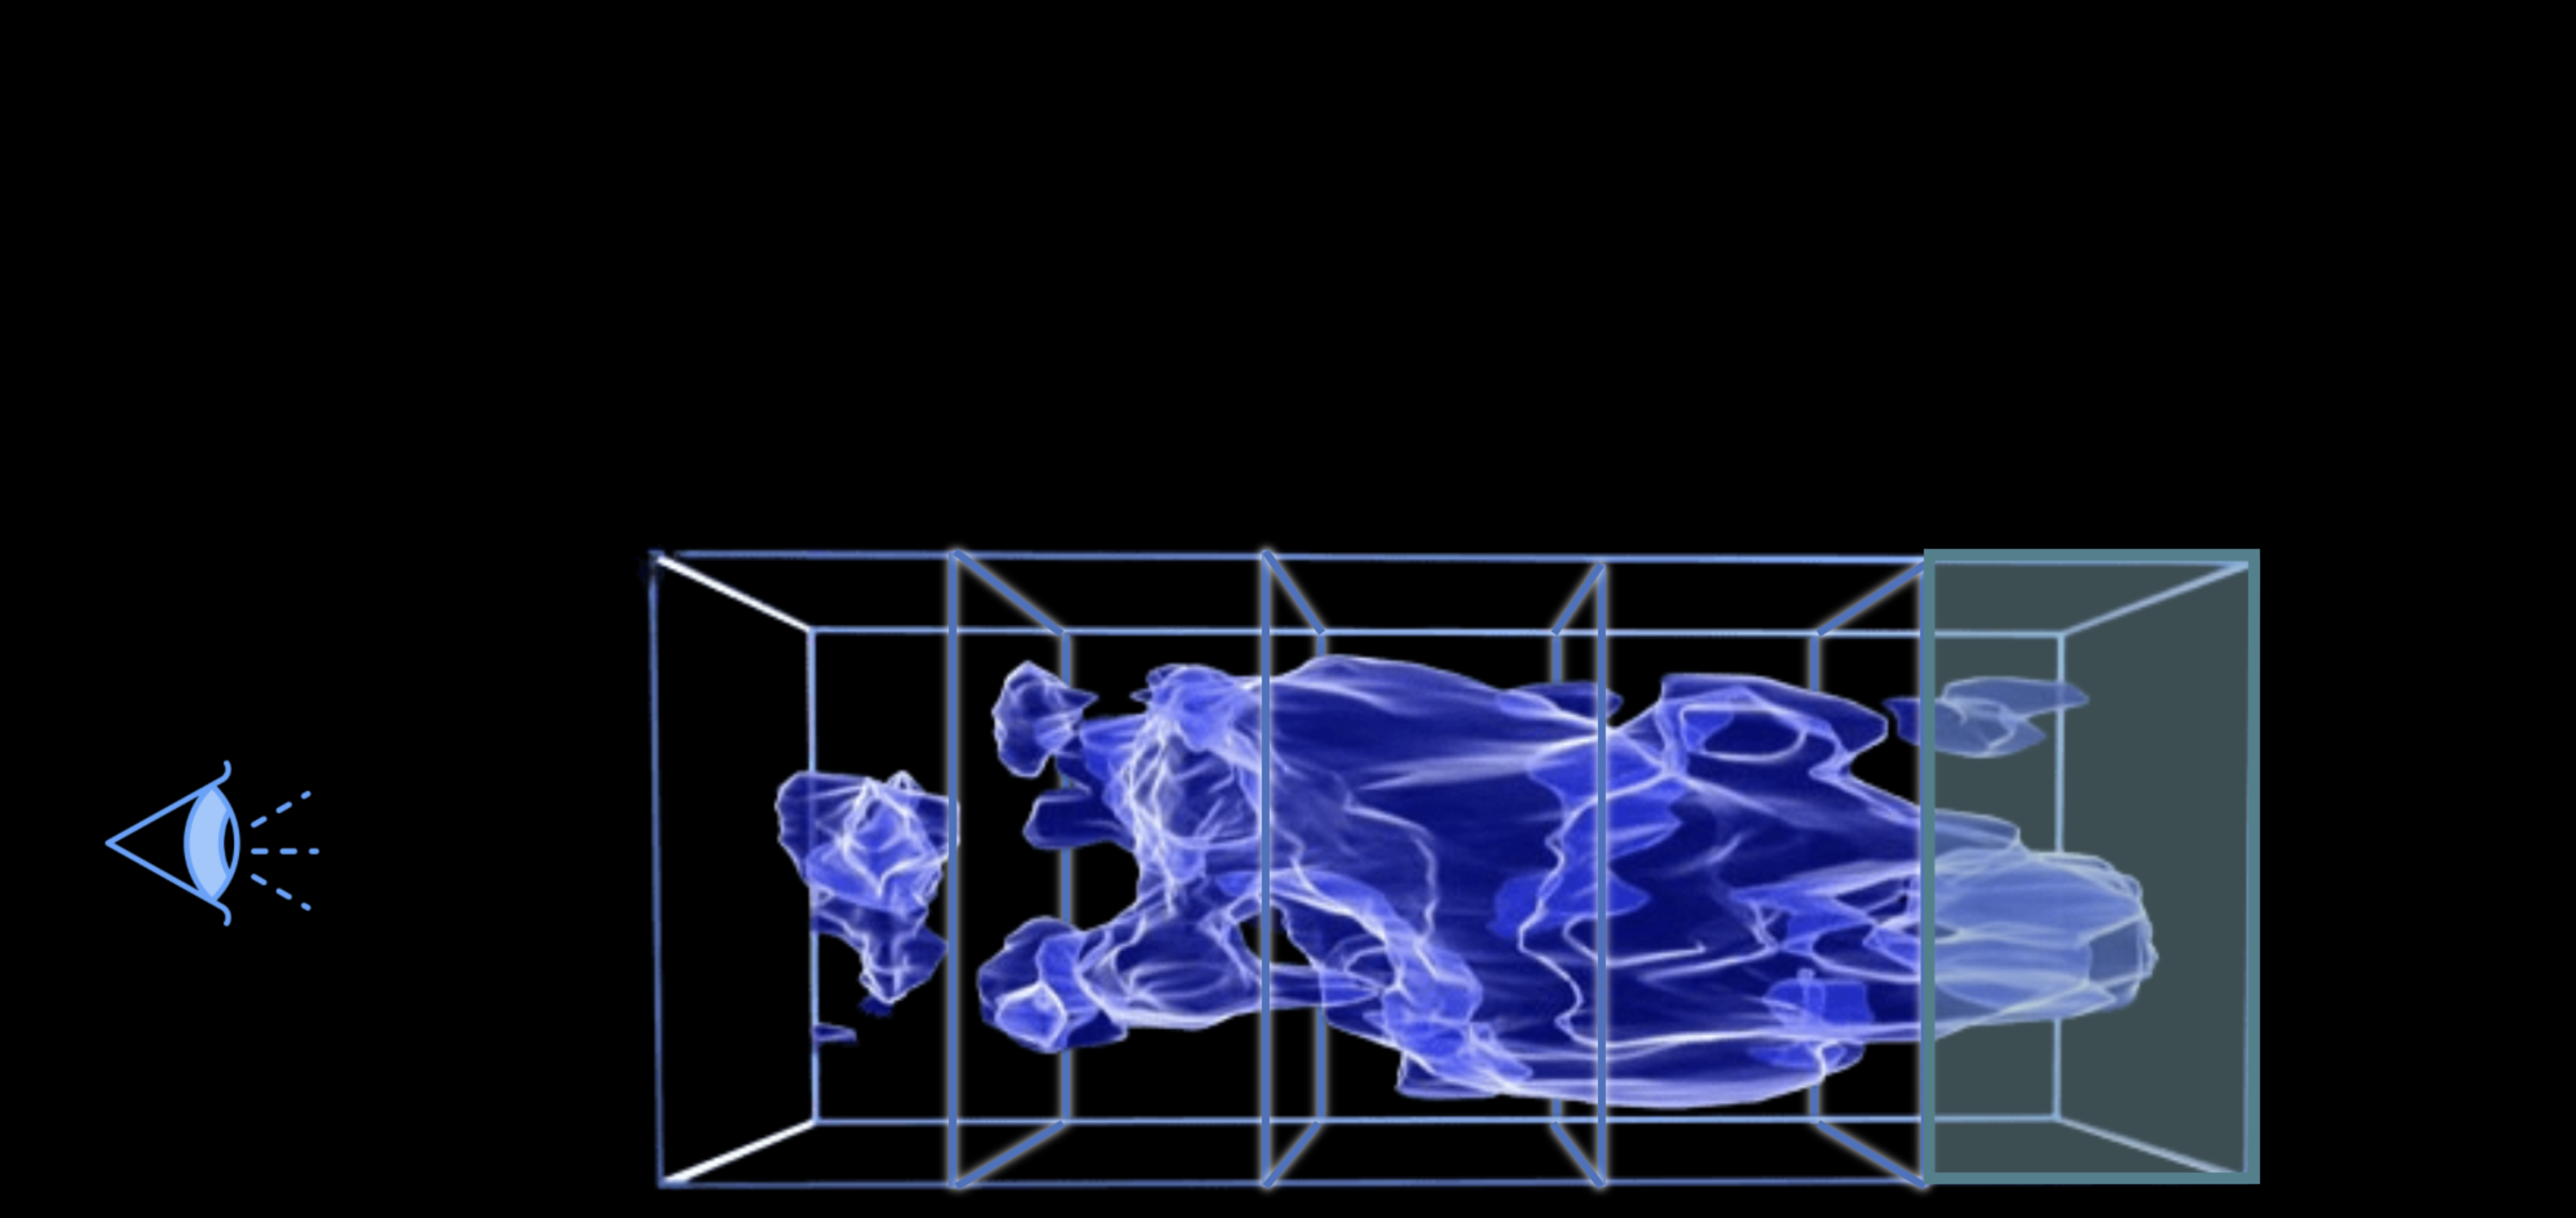
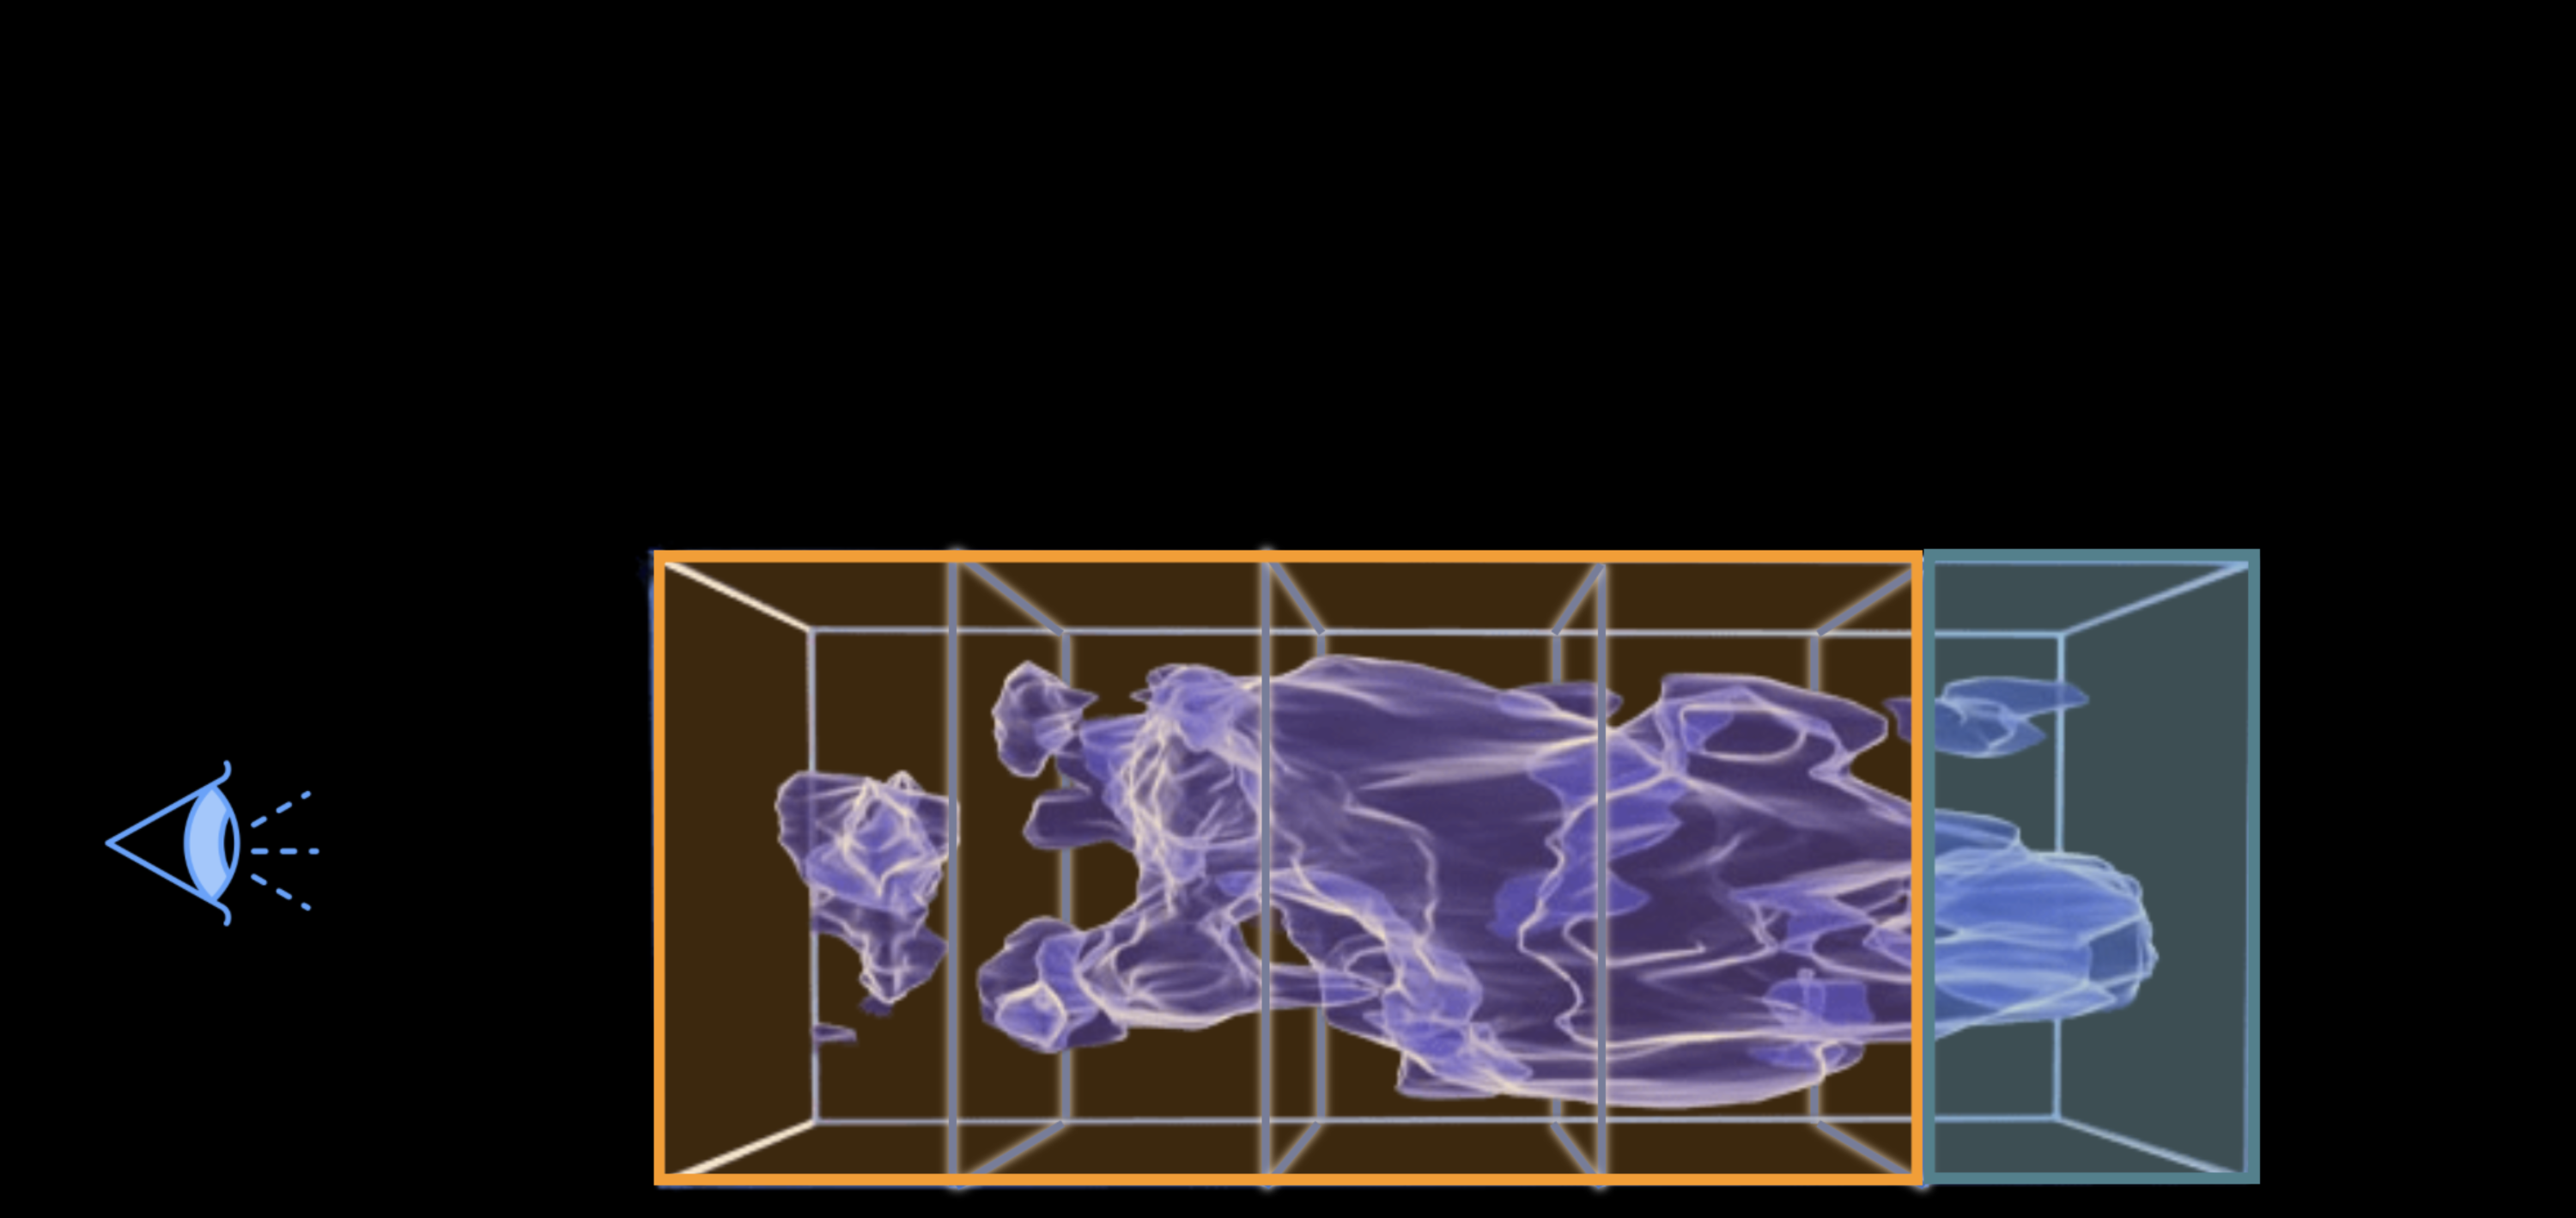
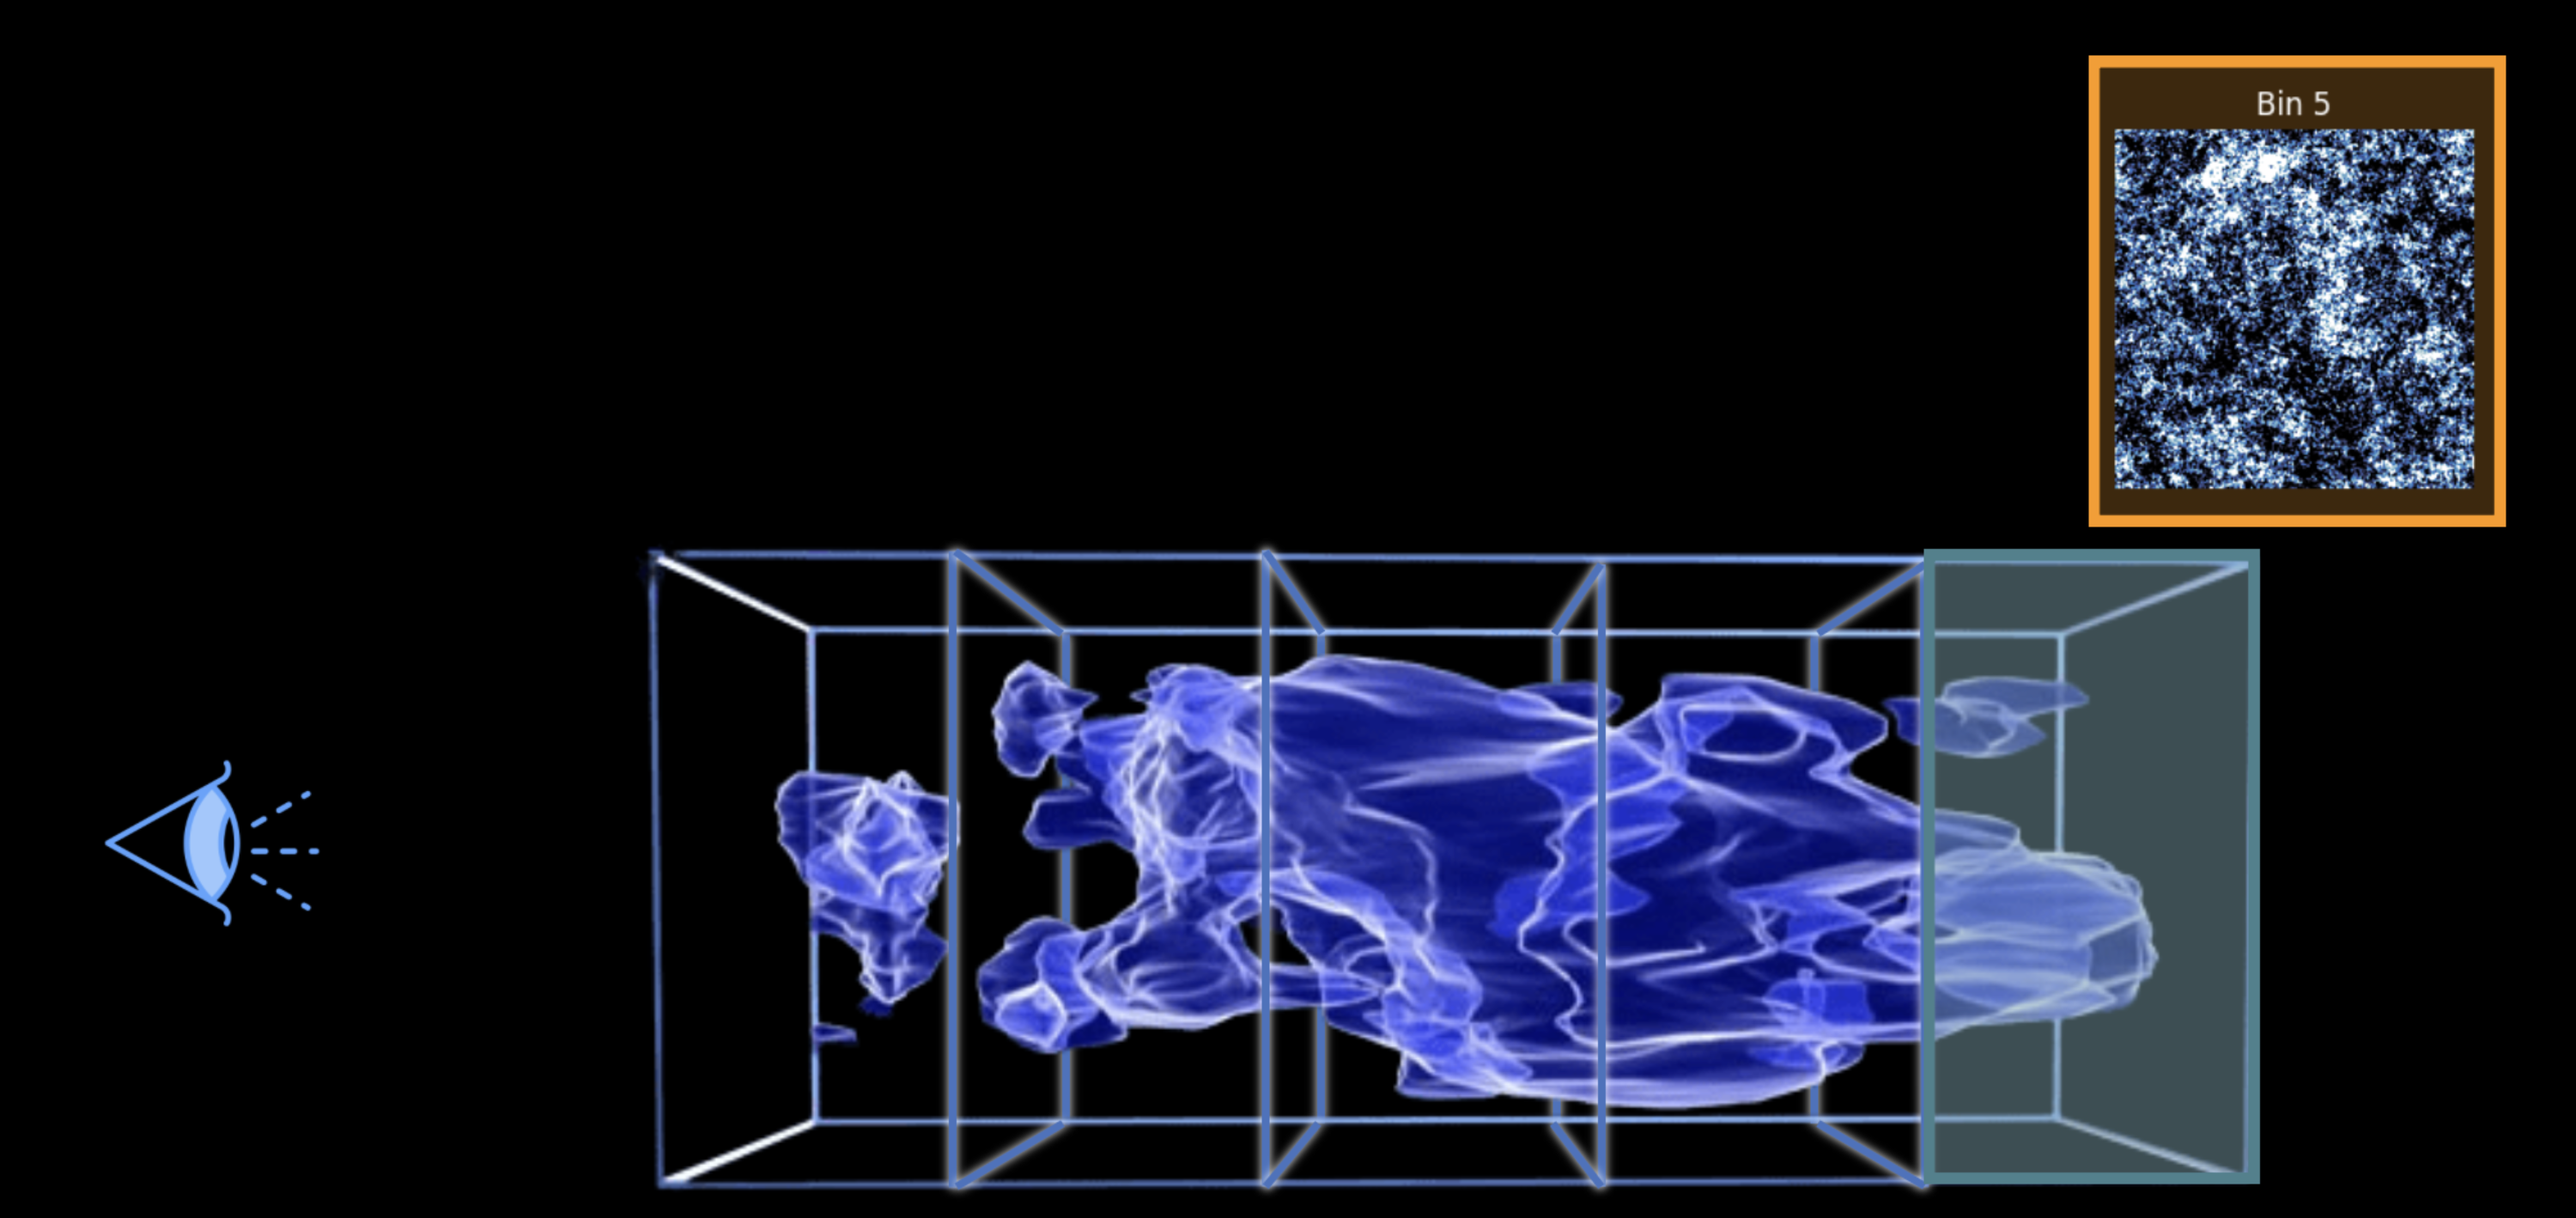
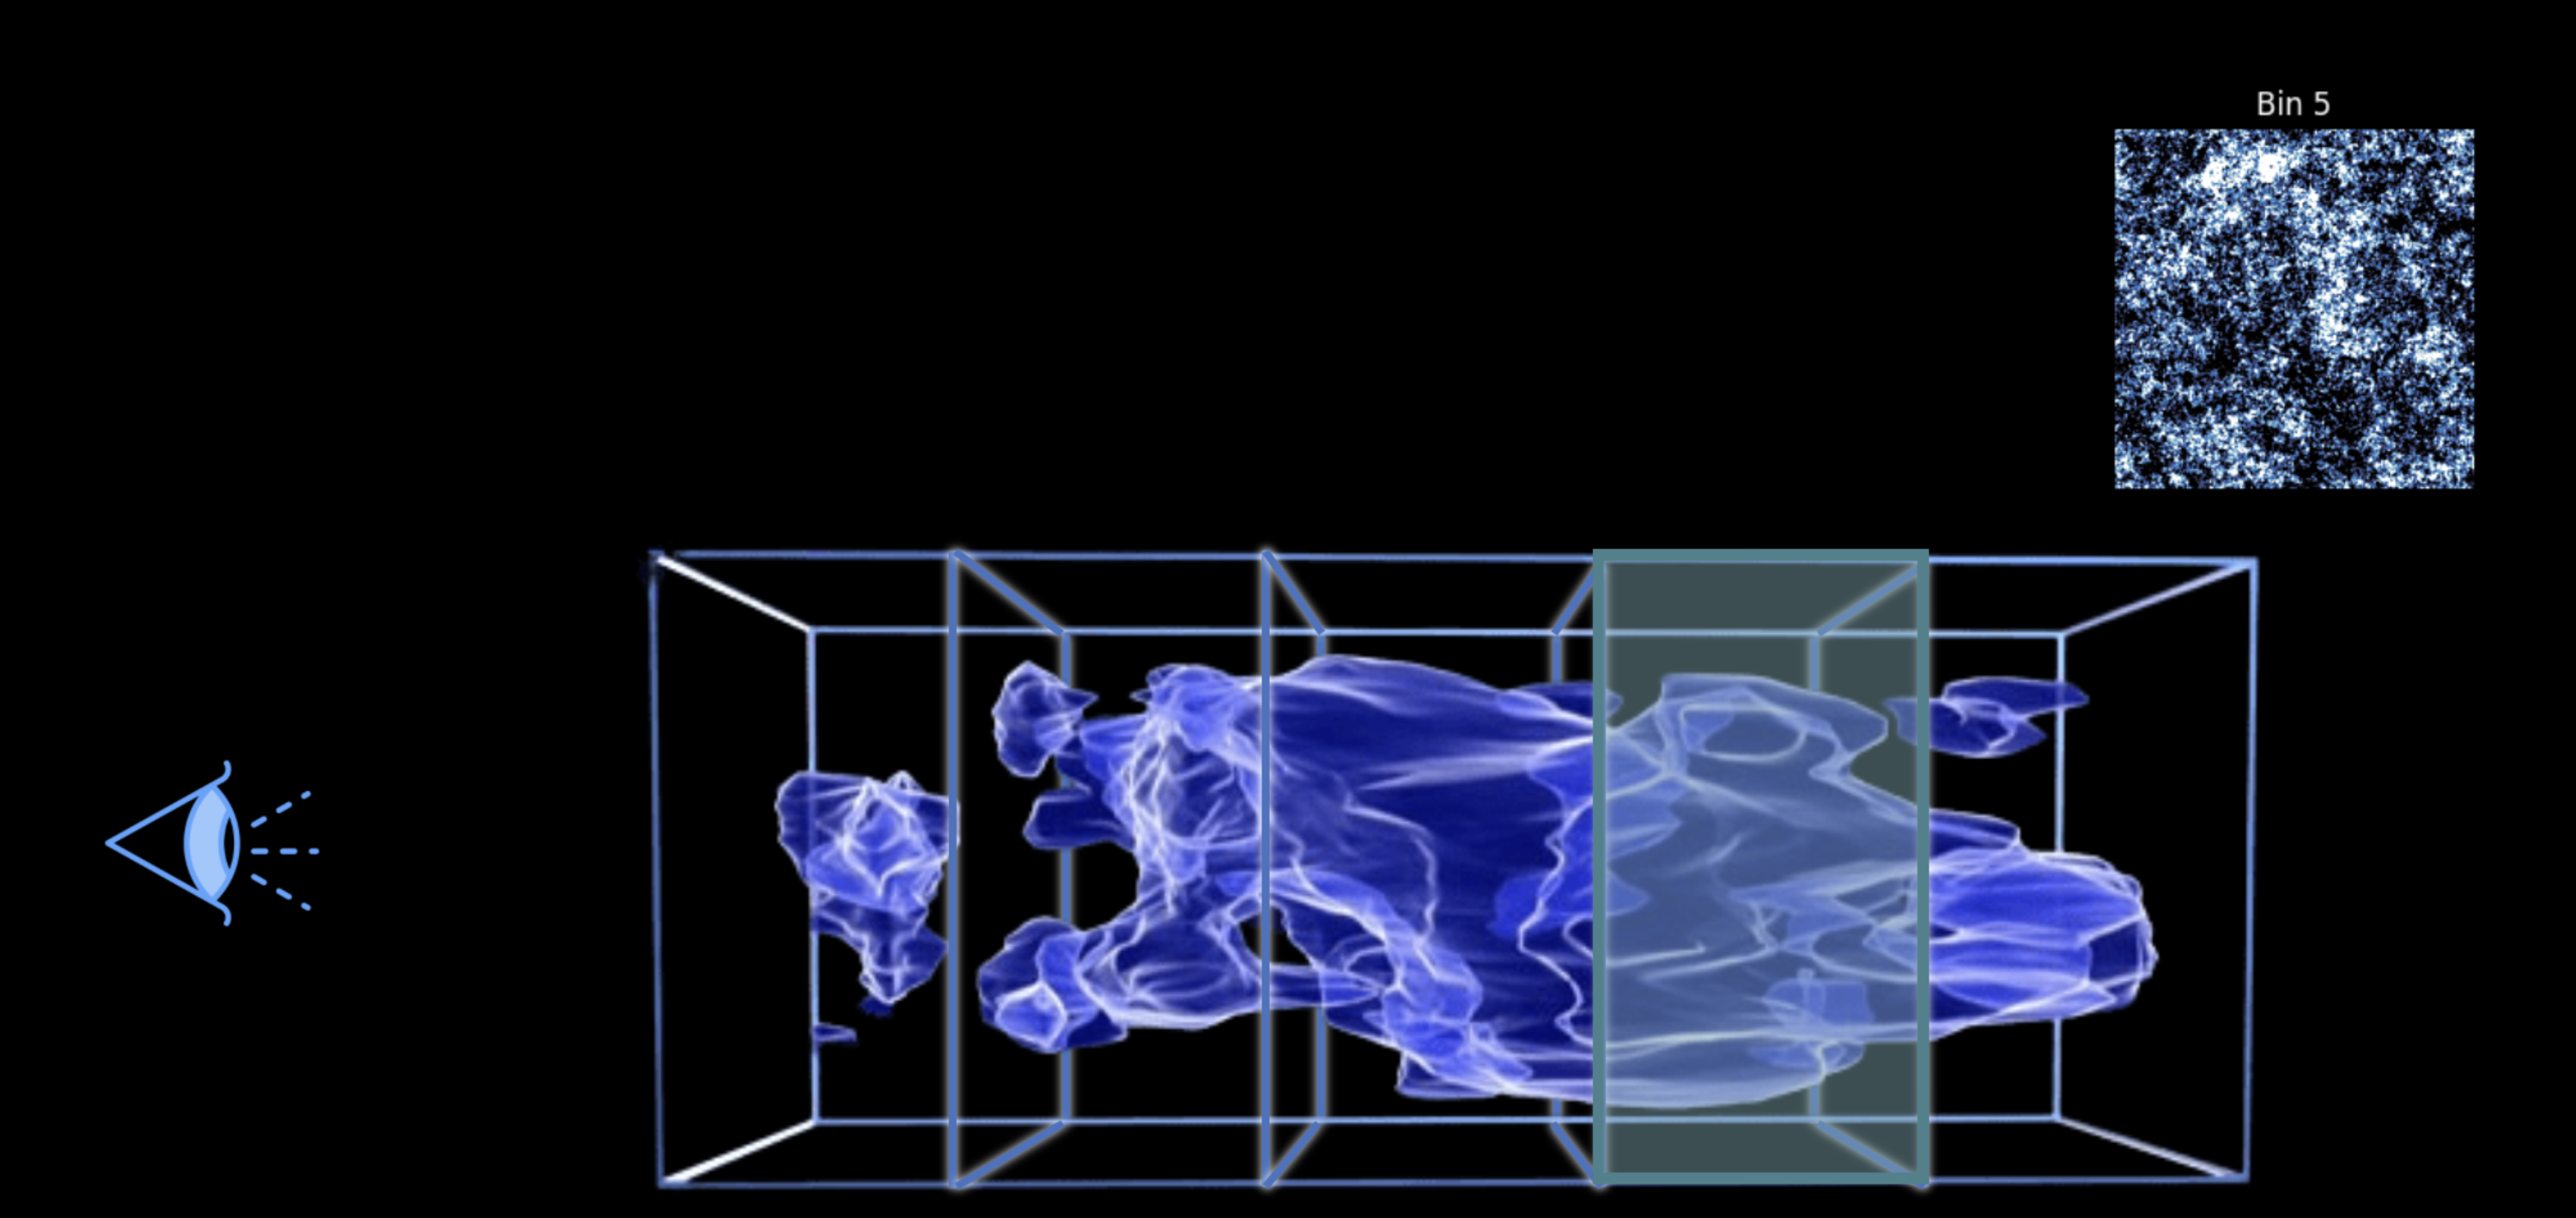
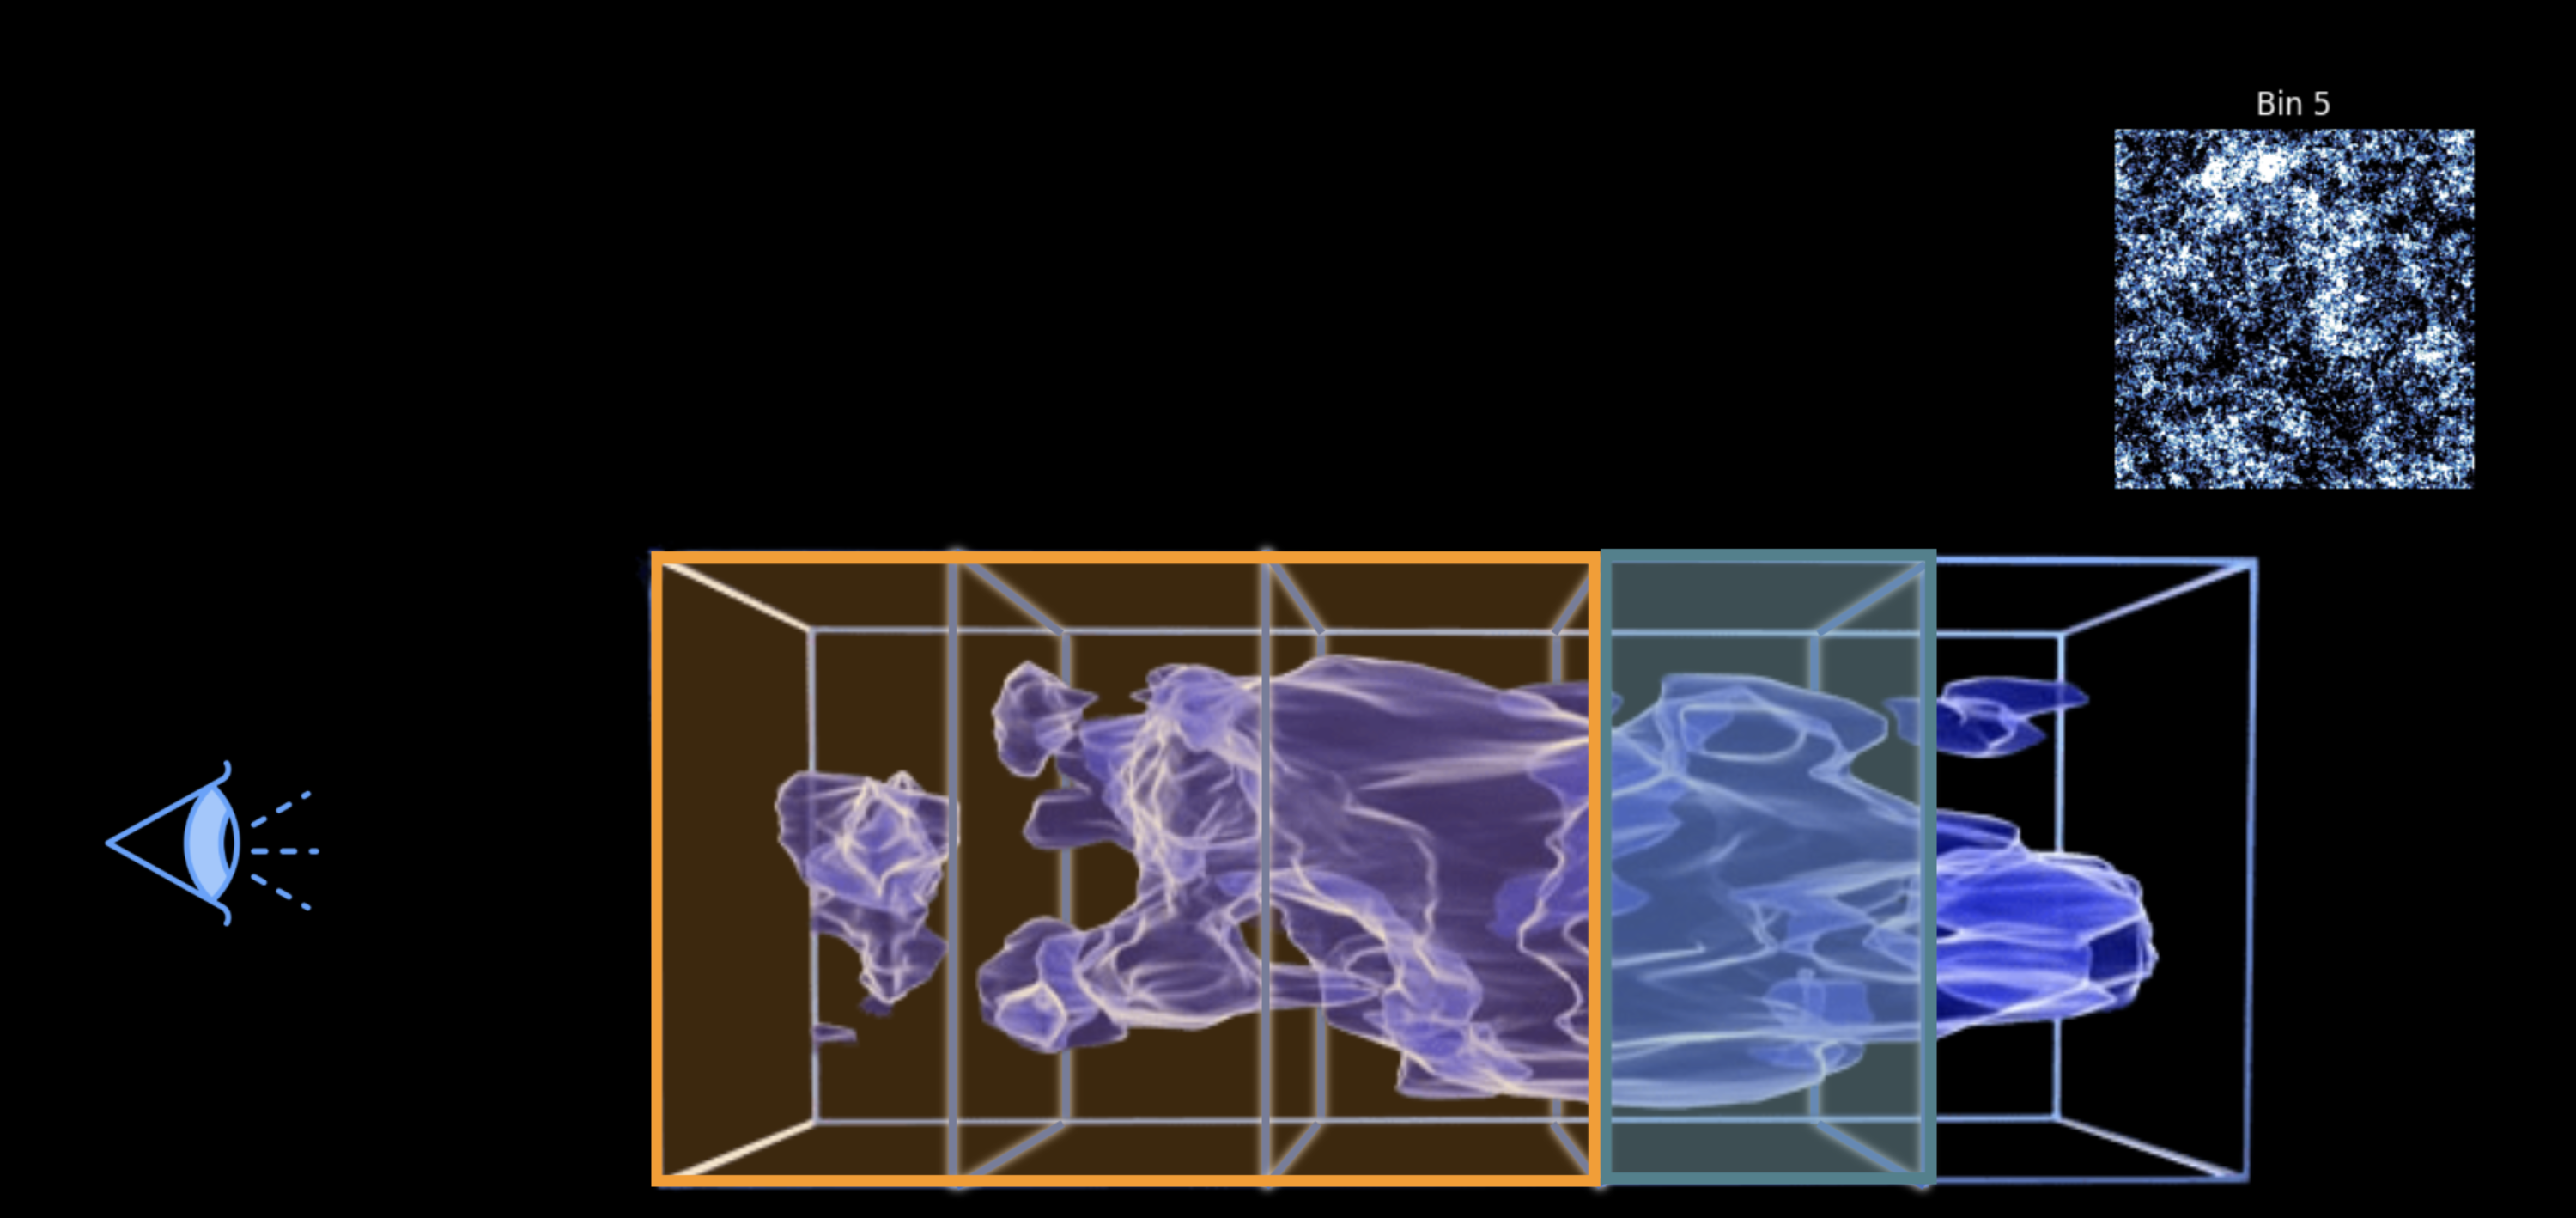
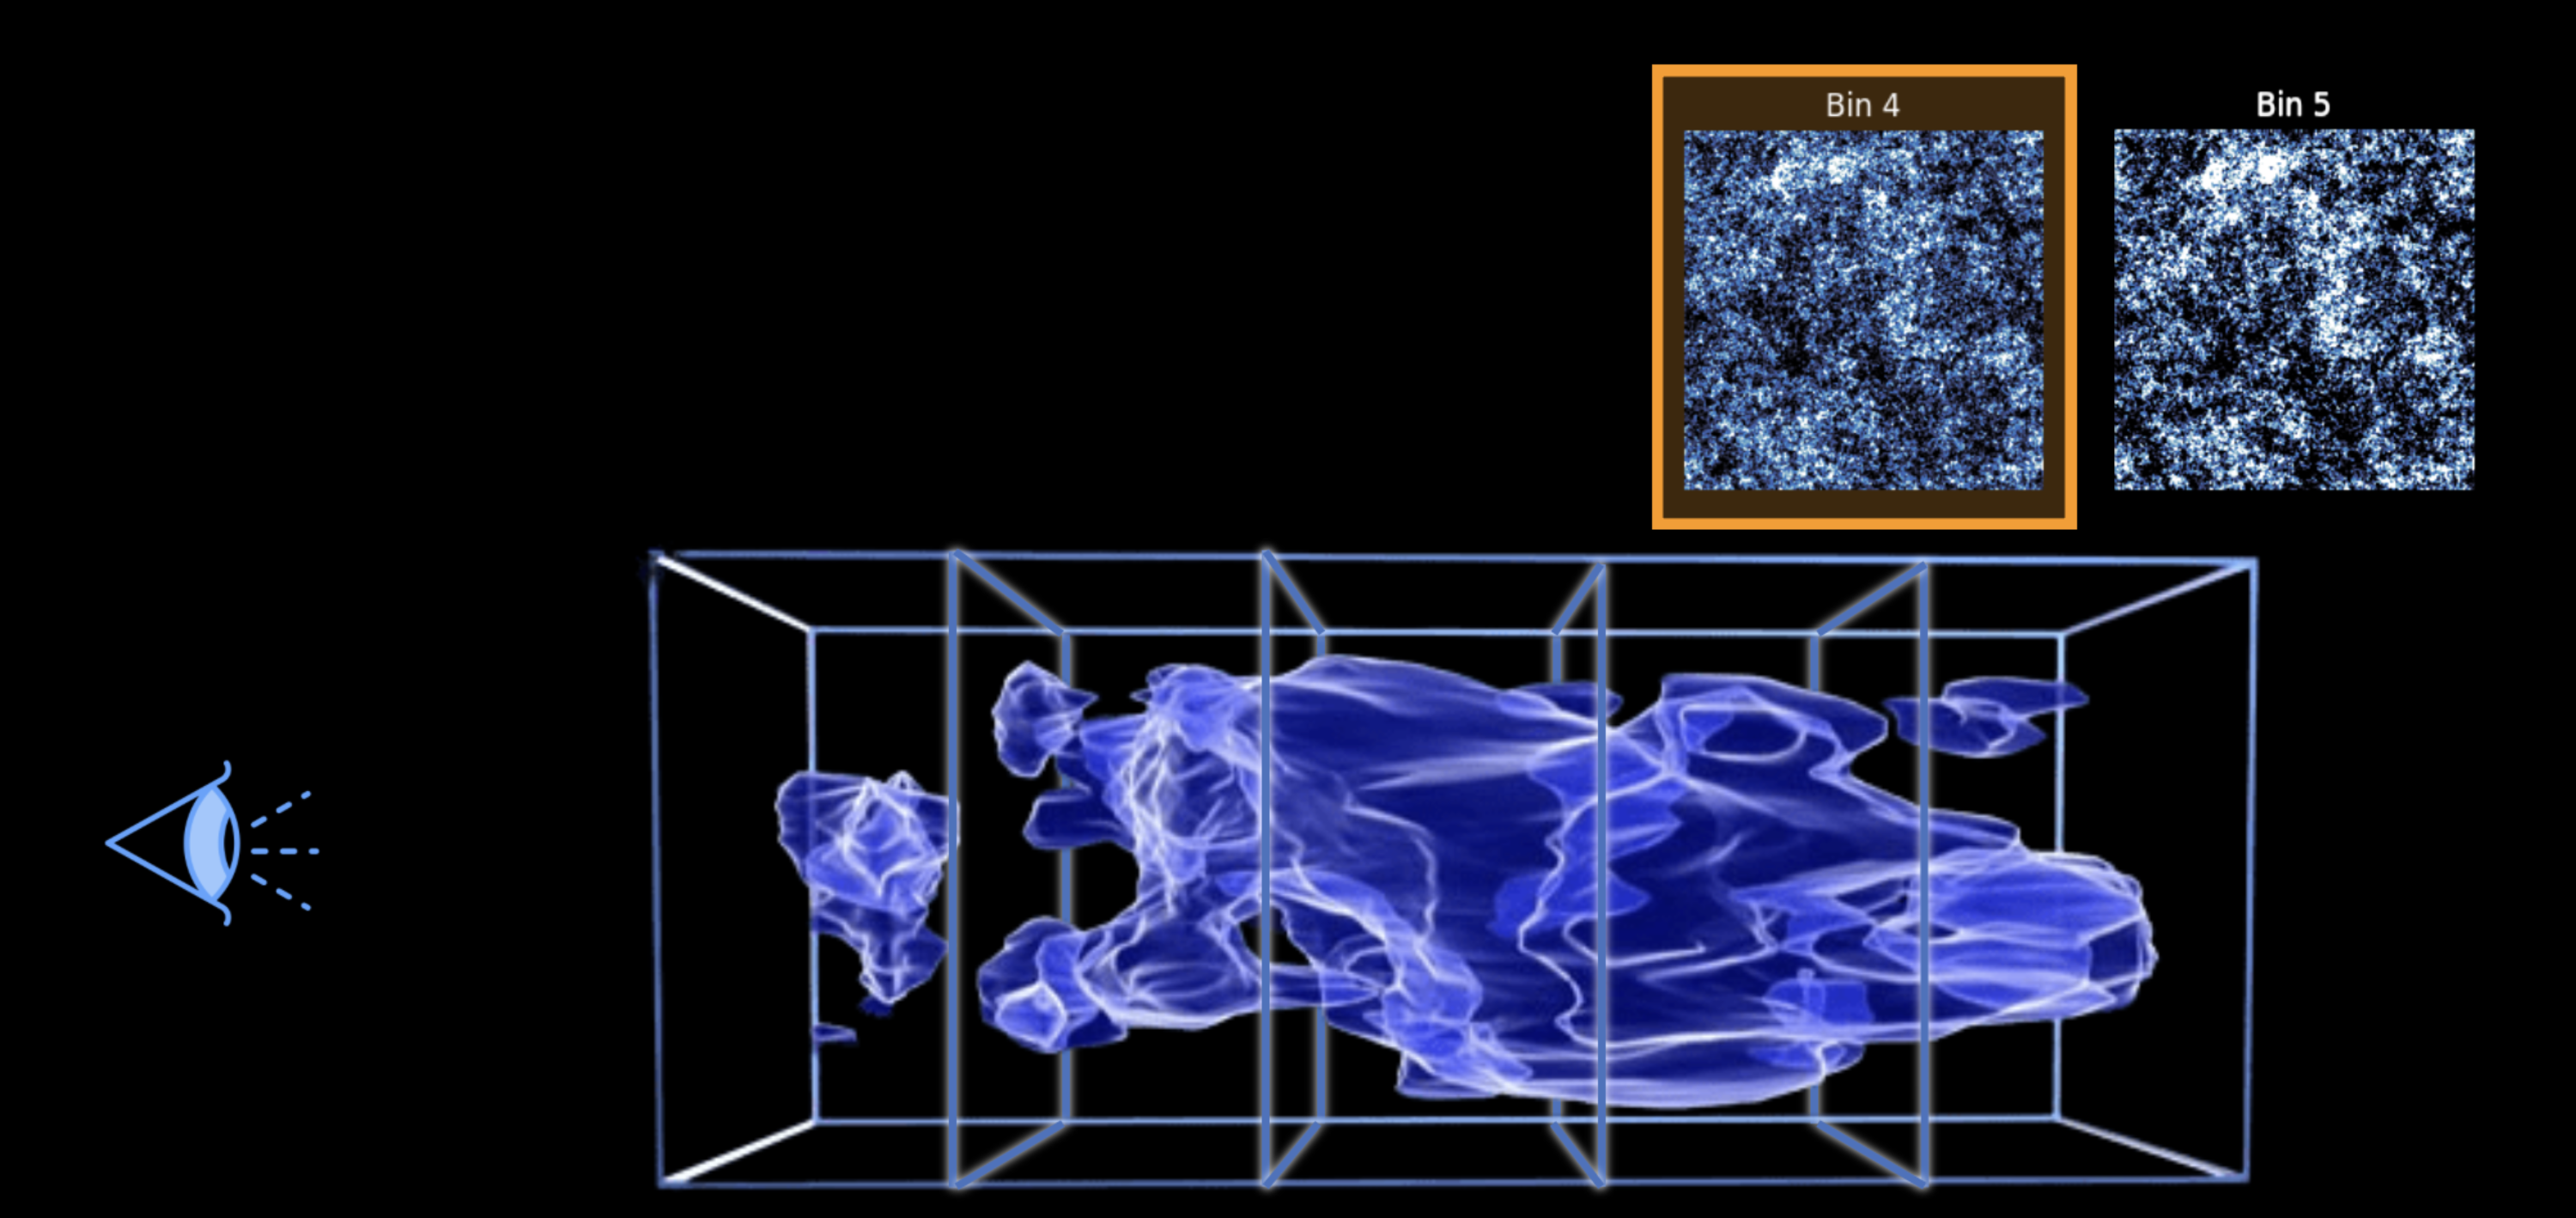
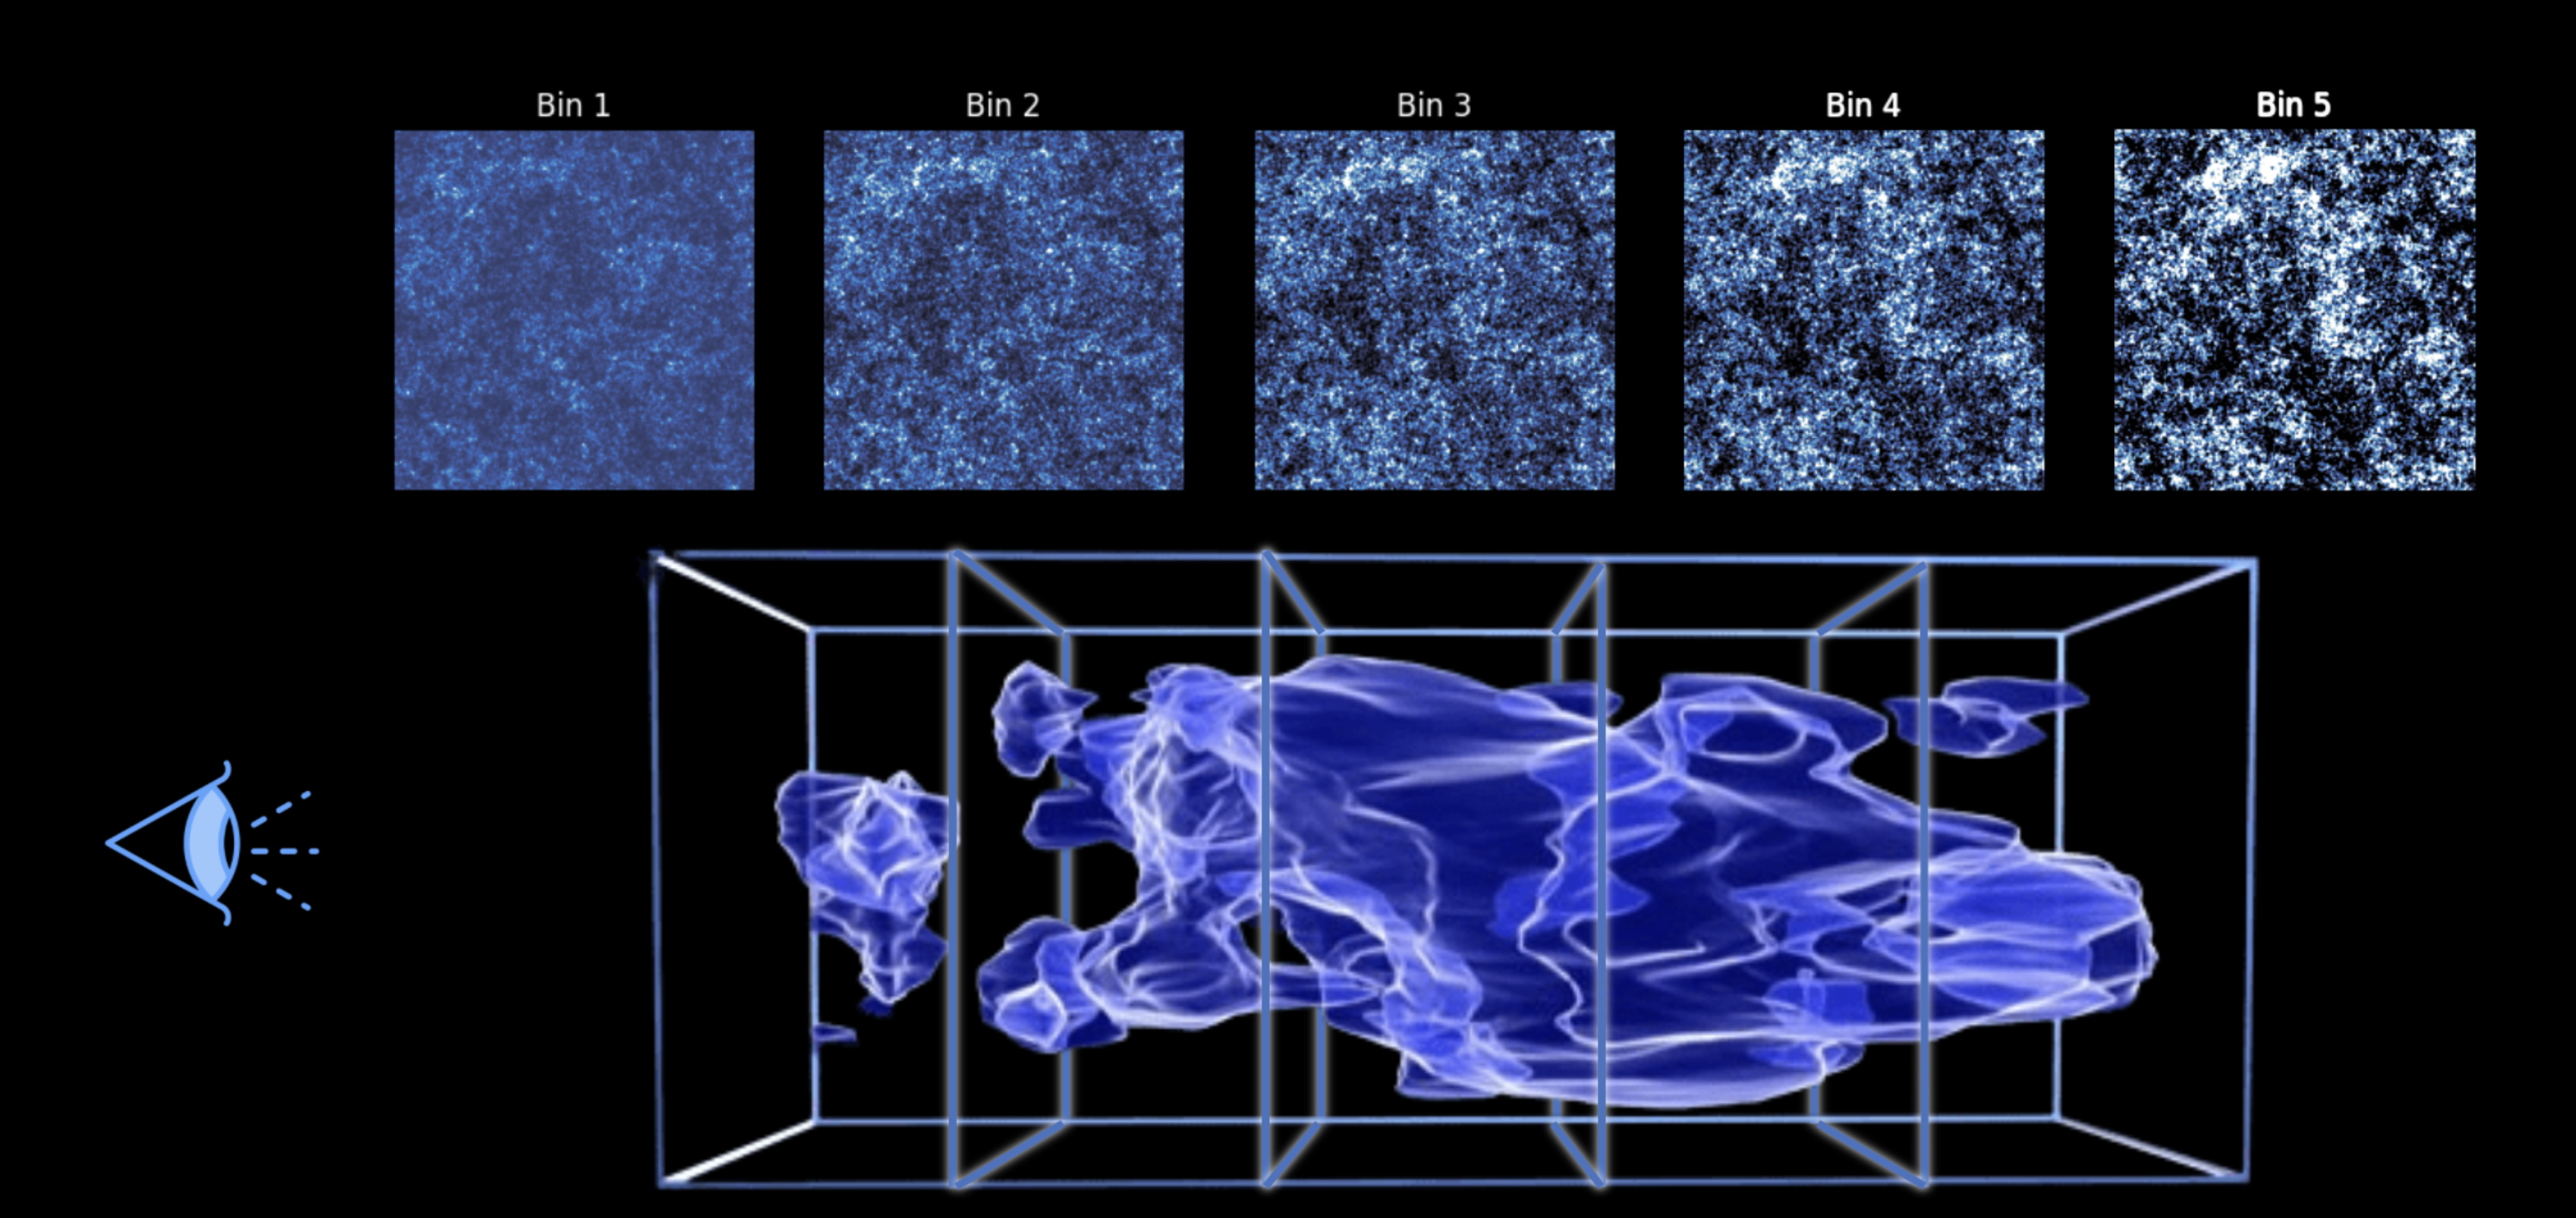
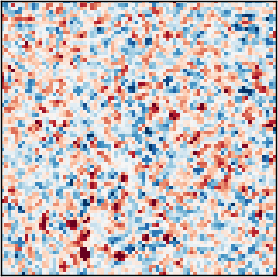
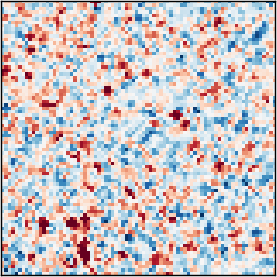
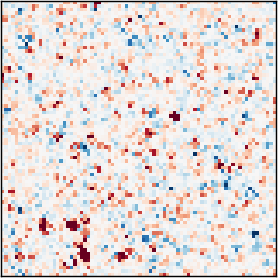
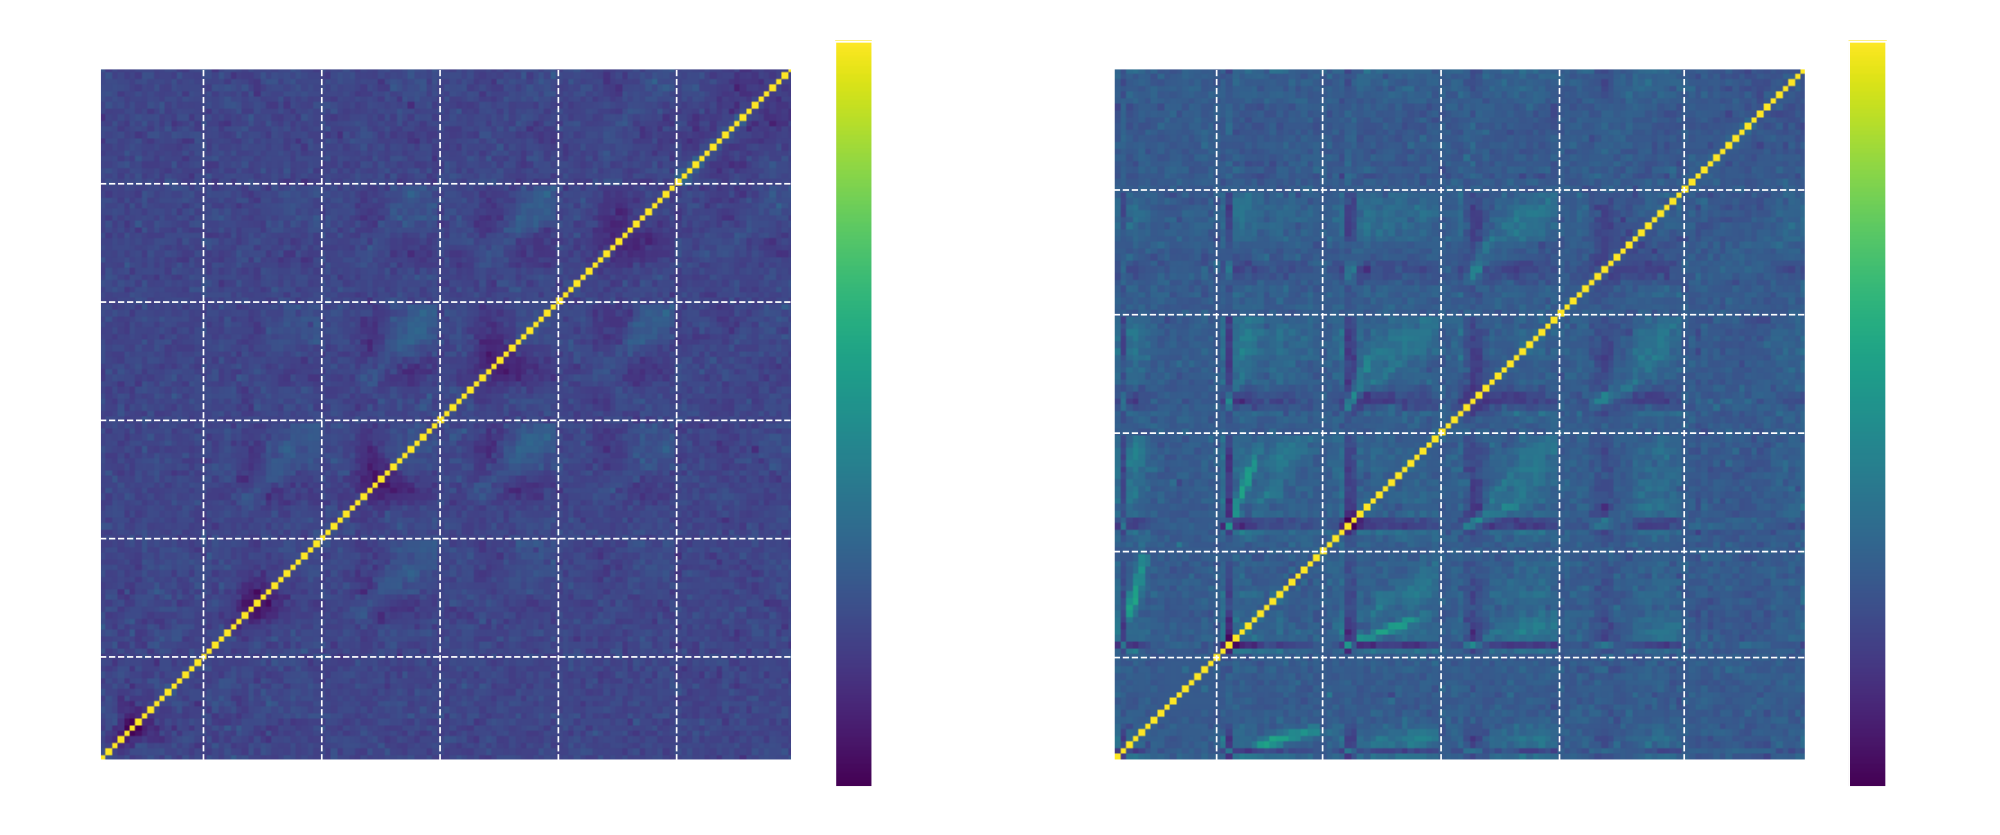
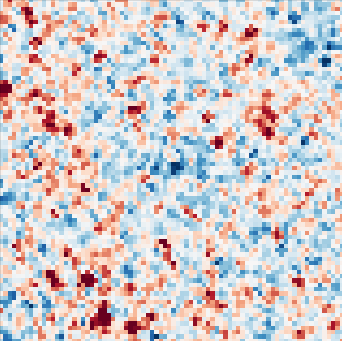
The pixel-wise product of two bins is strong only where both have structure. One map per bin pair, each analysed with the same ℓ1-norm.
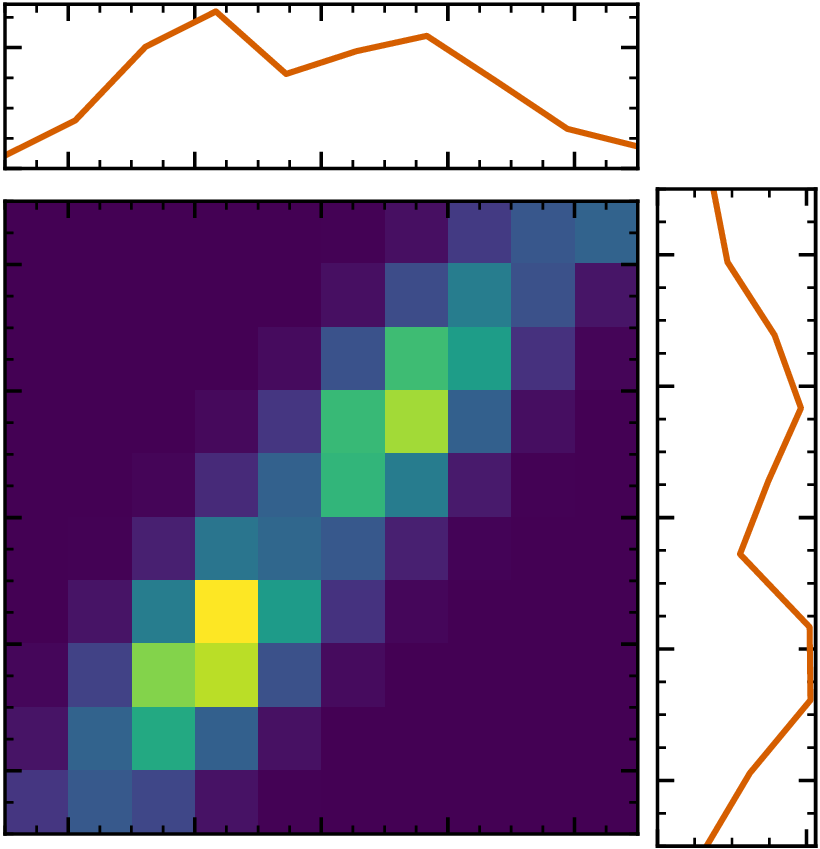 the per-bin
ℓ1-norm
each cell sums the ℓ1 weight of the pixels that fall in it
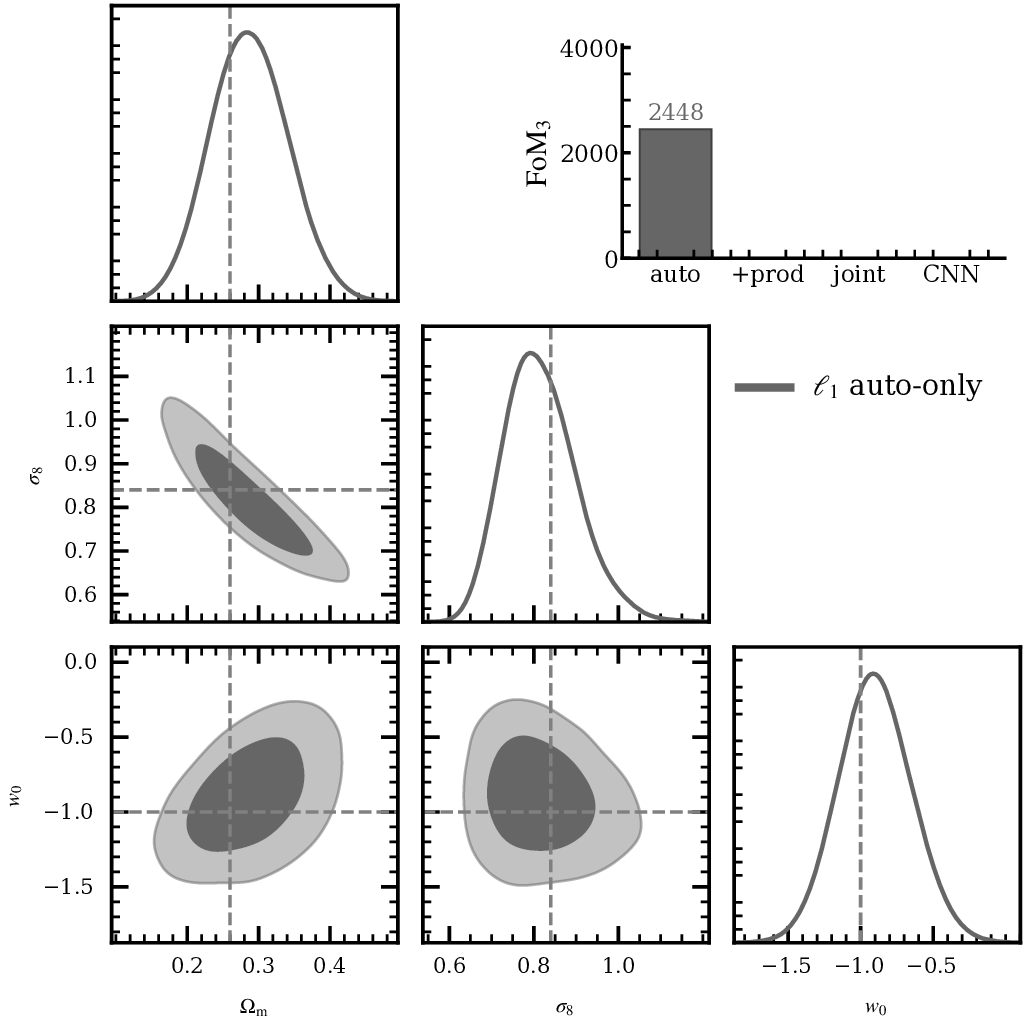
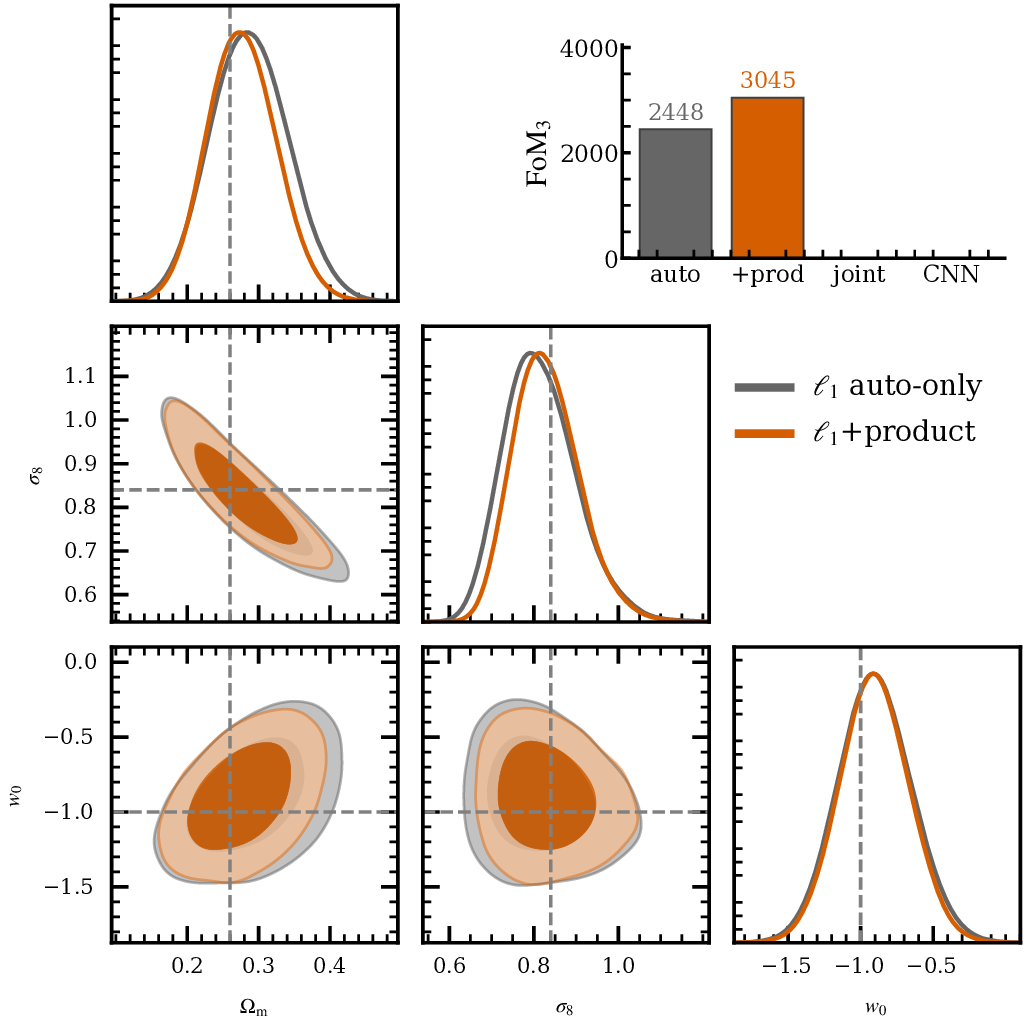
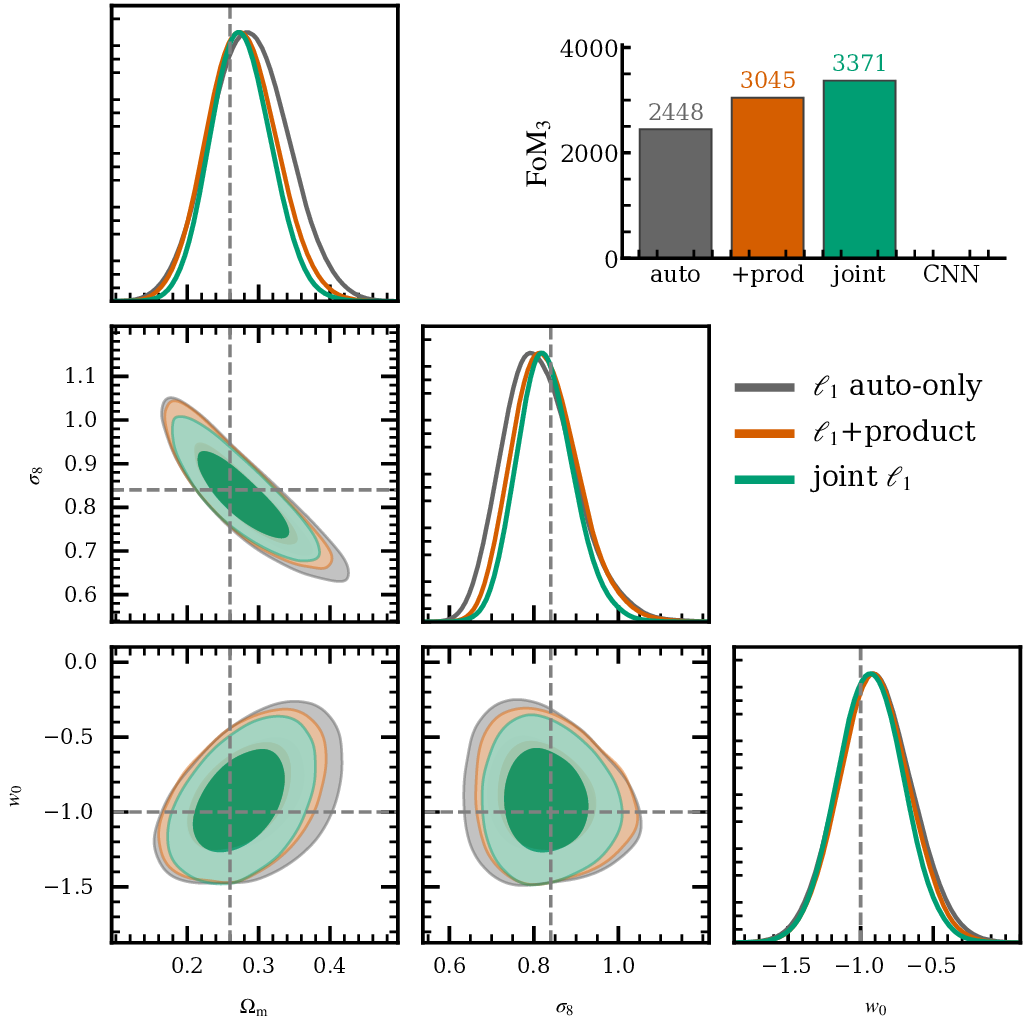
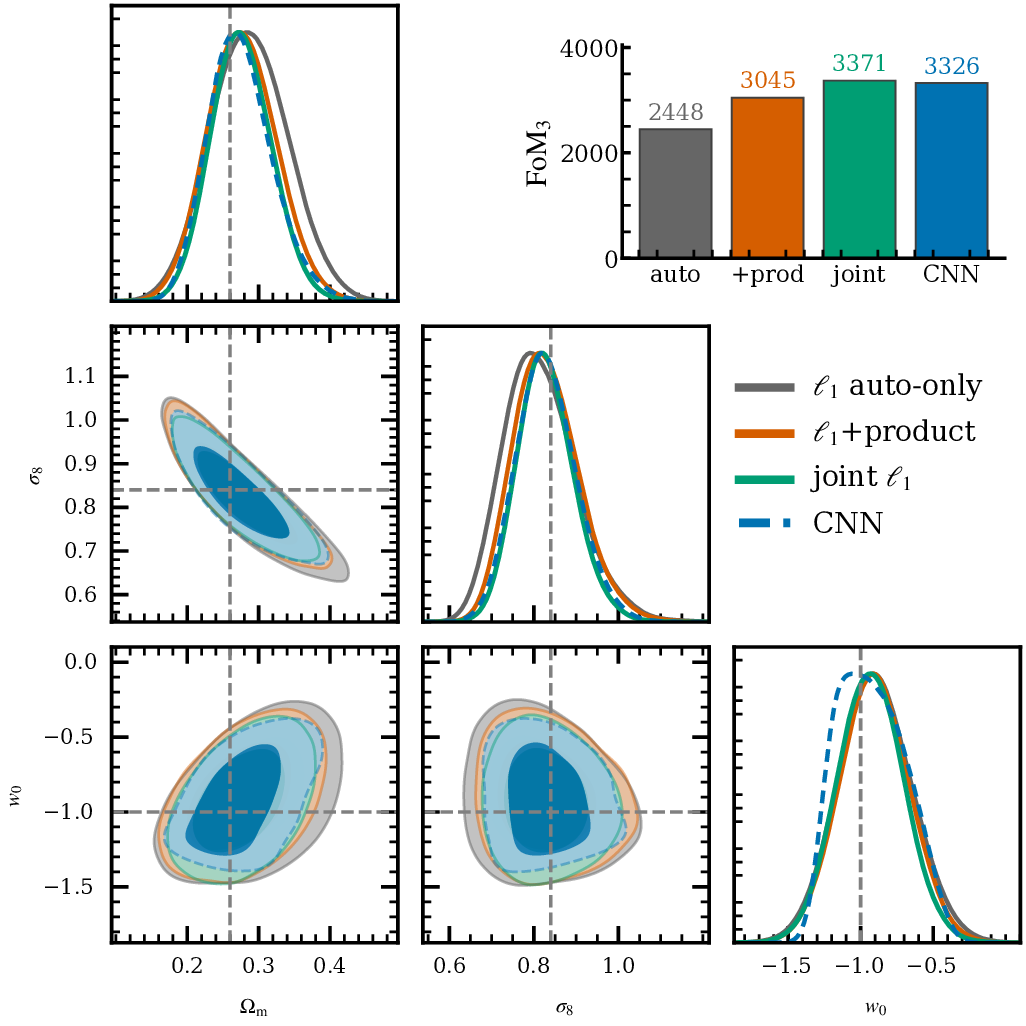
To be able to trust our HOS results we must investigate how they are affected by each systematic at the contour level.
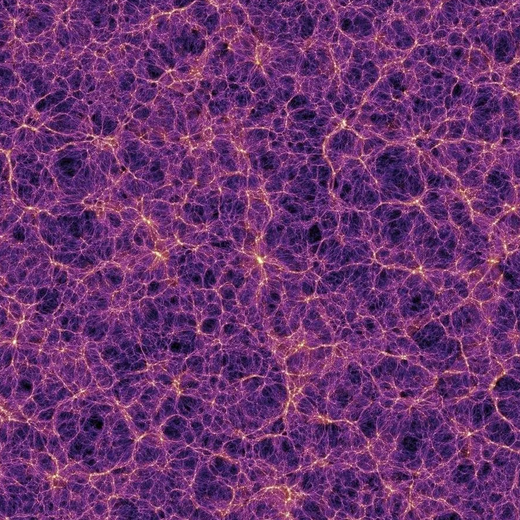
Illustris: baryonic feedback reshaping the cosmic web
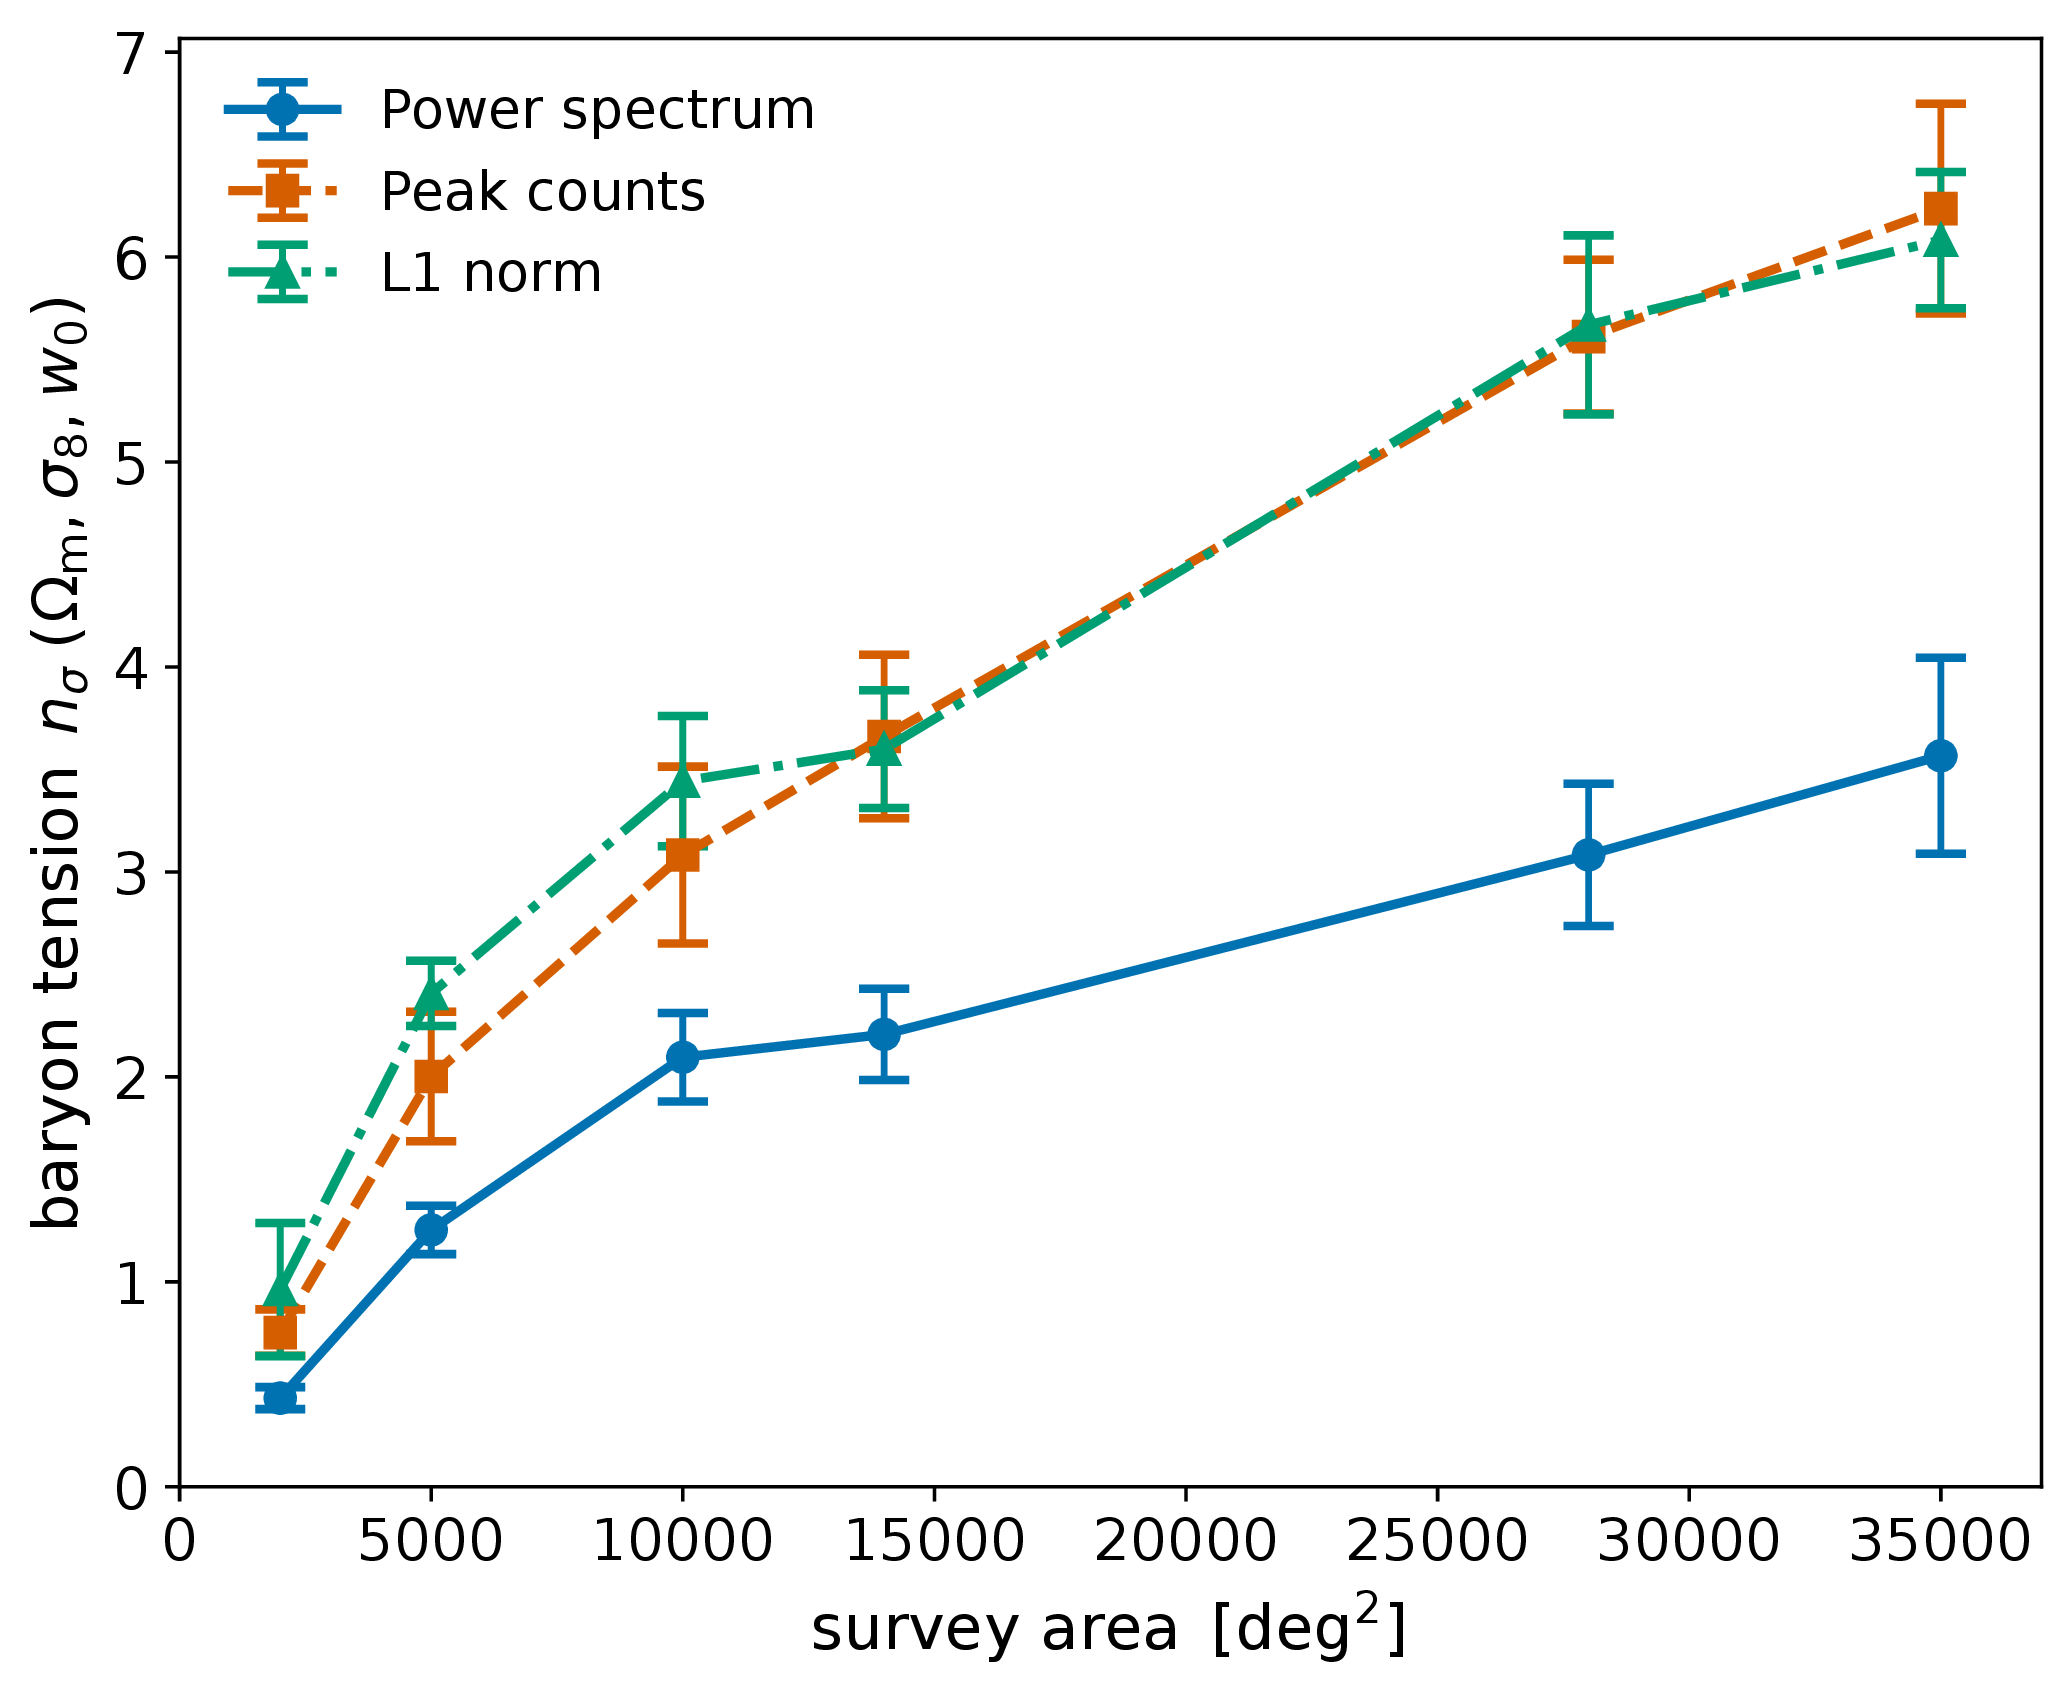
How much does unmodelled feedback bias our higher-order statistics, and how does that grow with survey area?
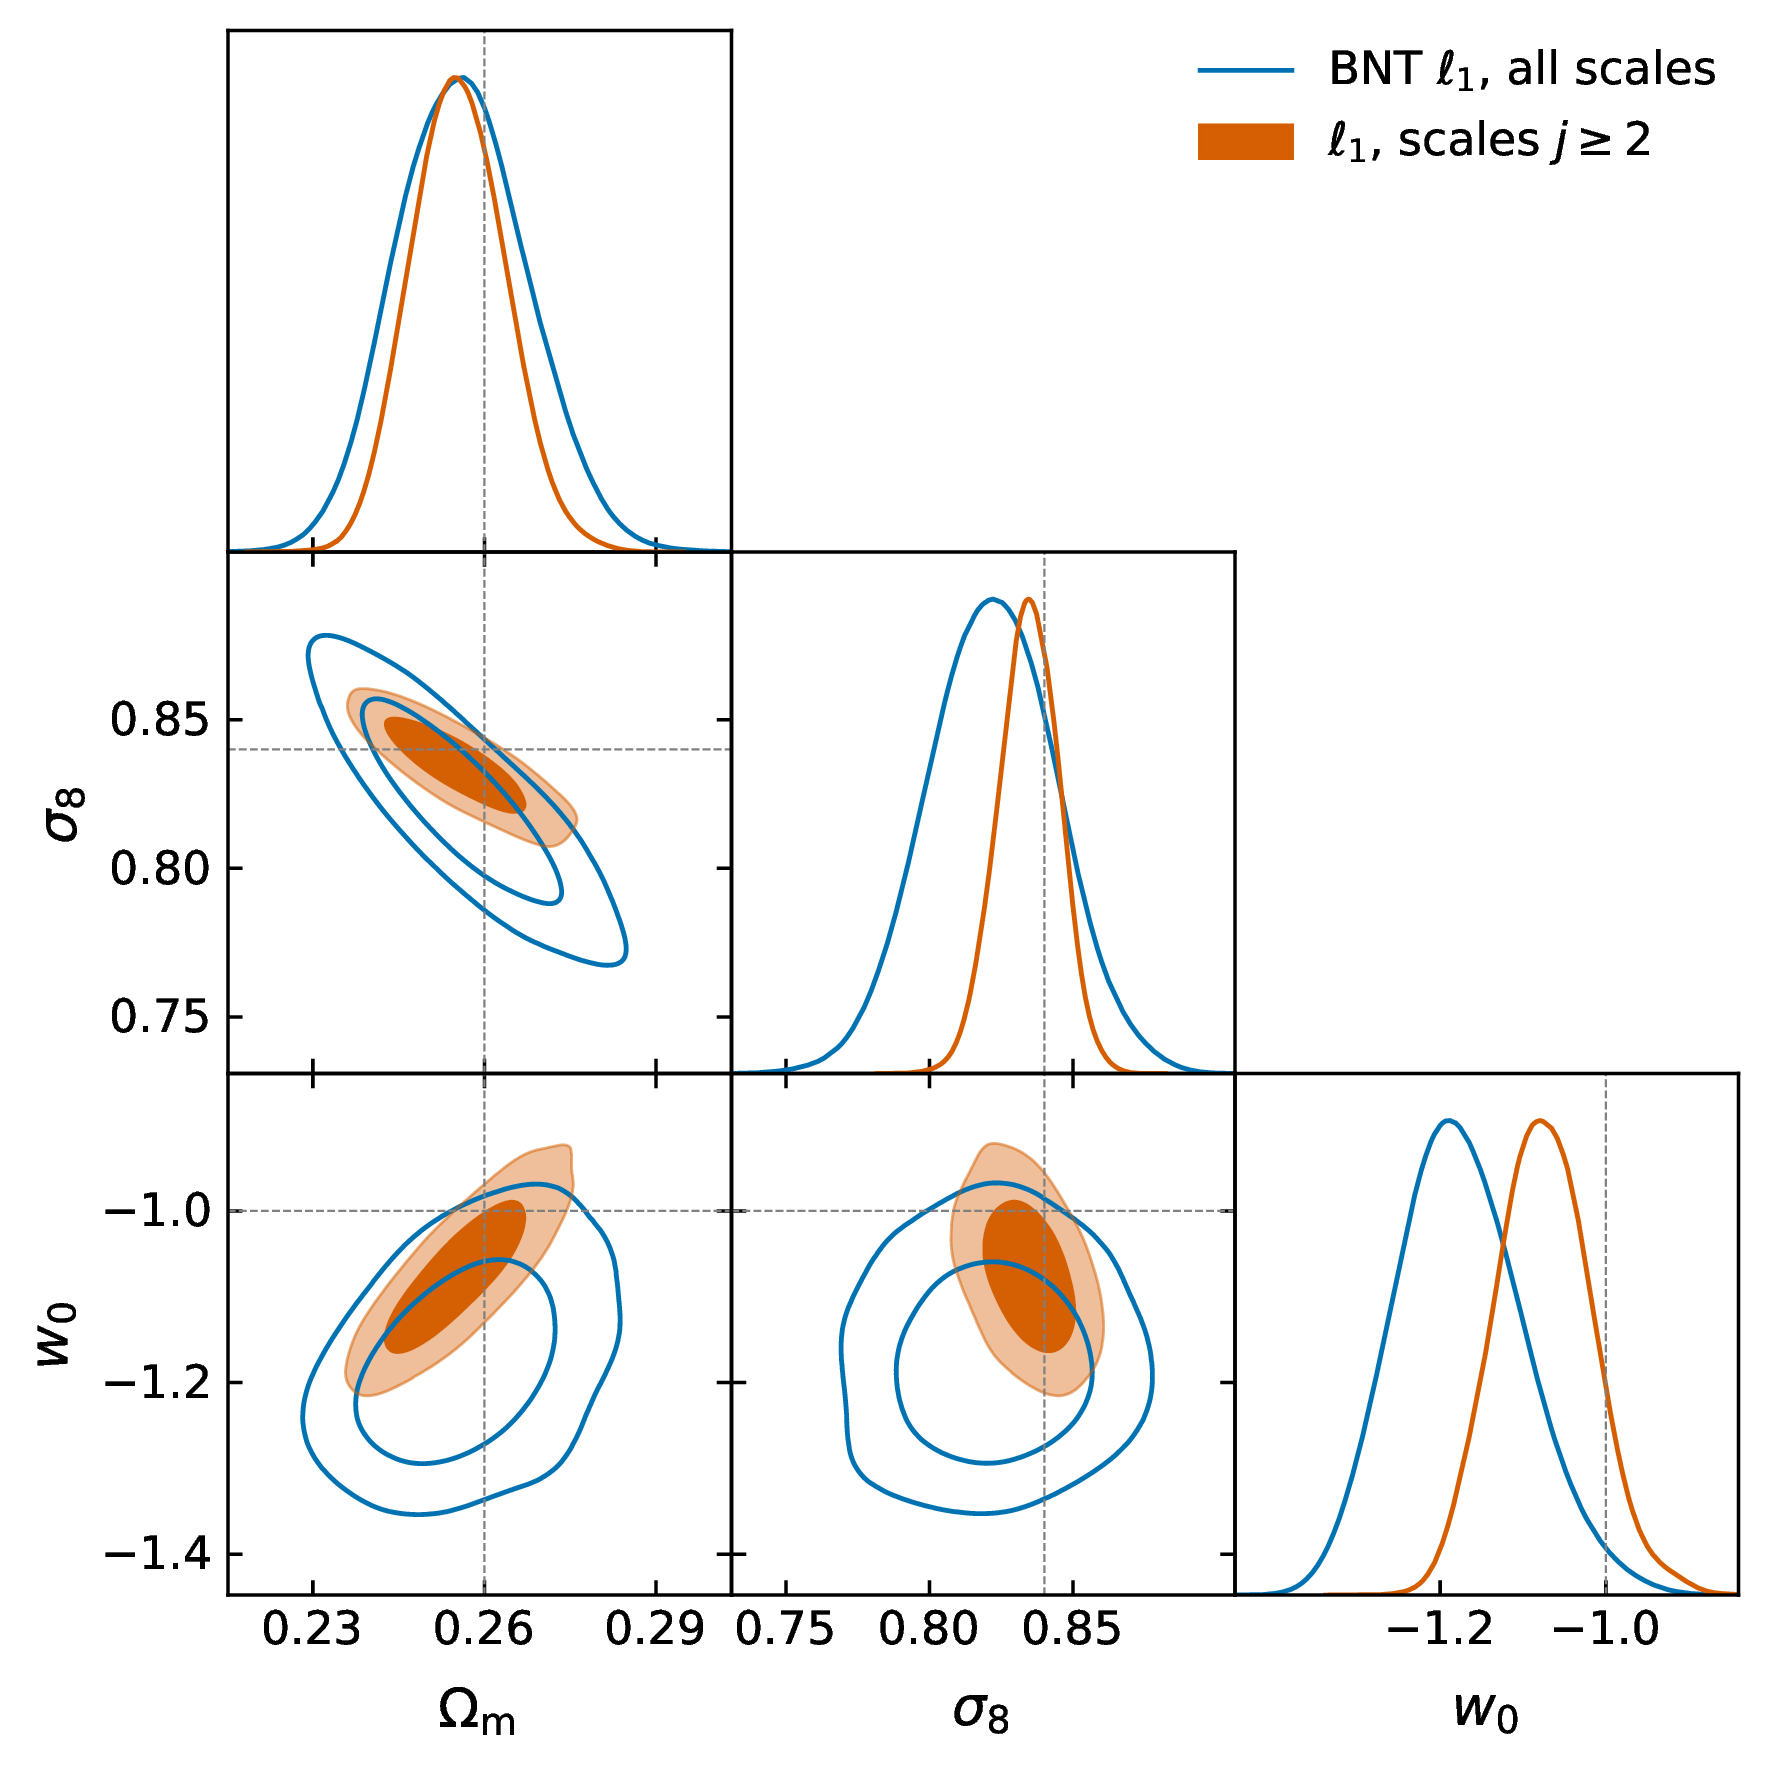
Once those scales are cut, is there any constraining power left to gain over the power spectrum?
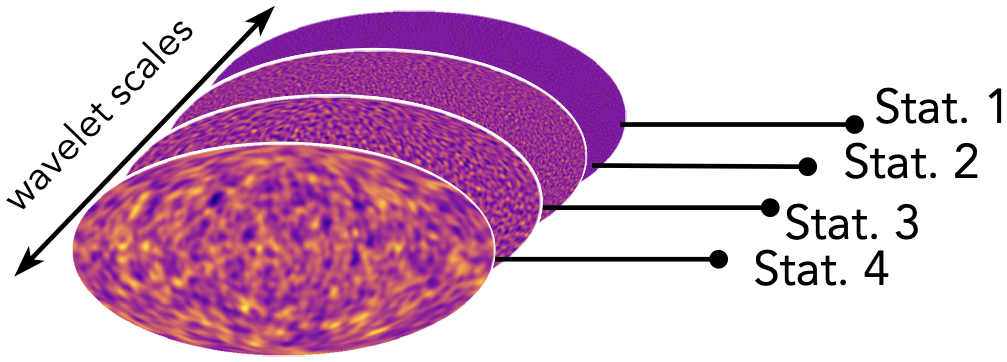
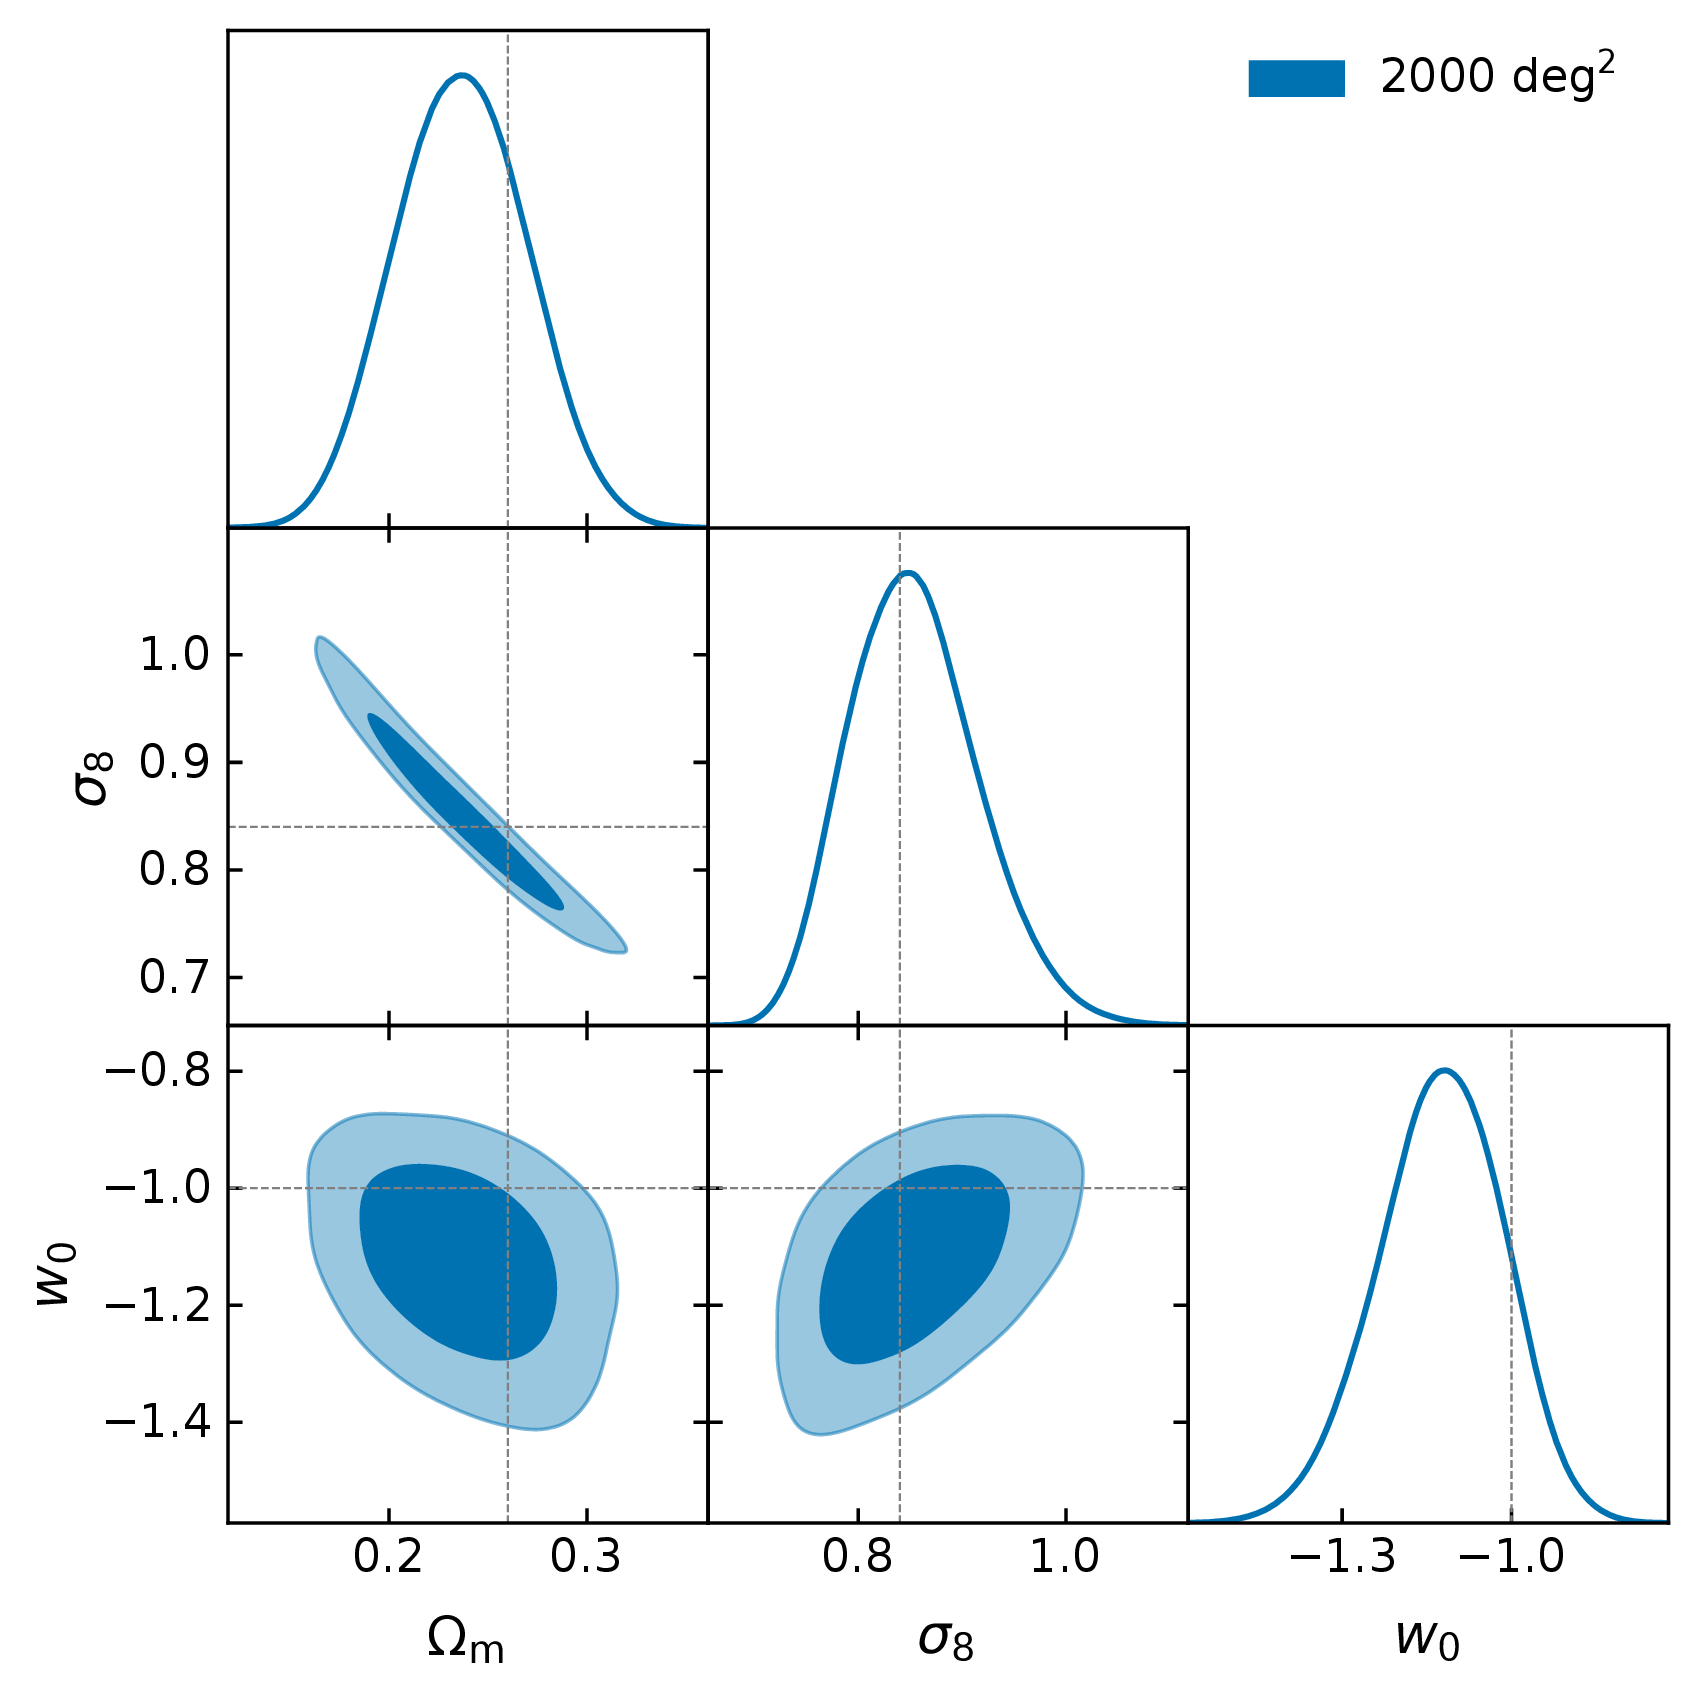
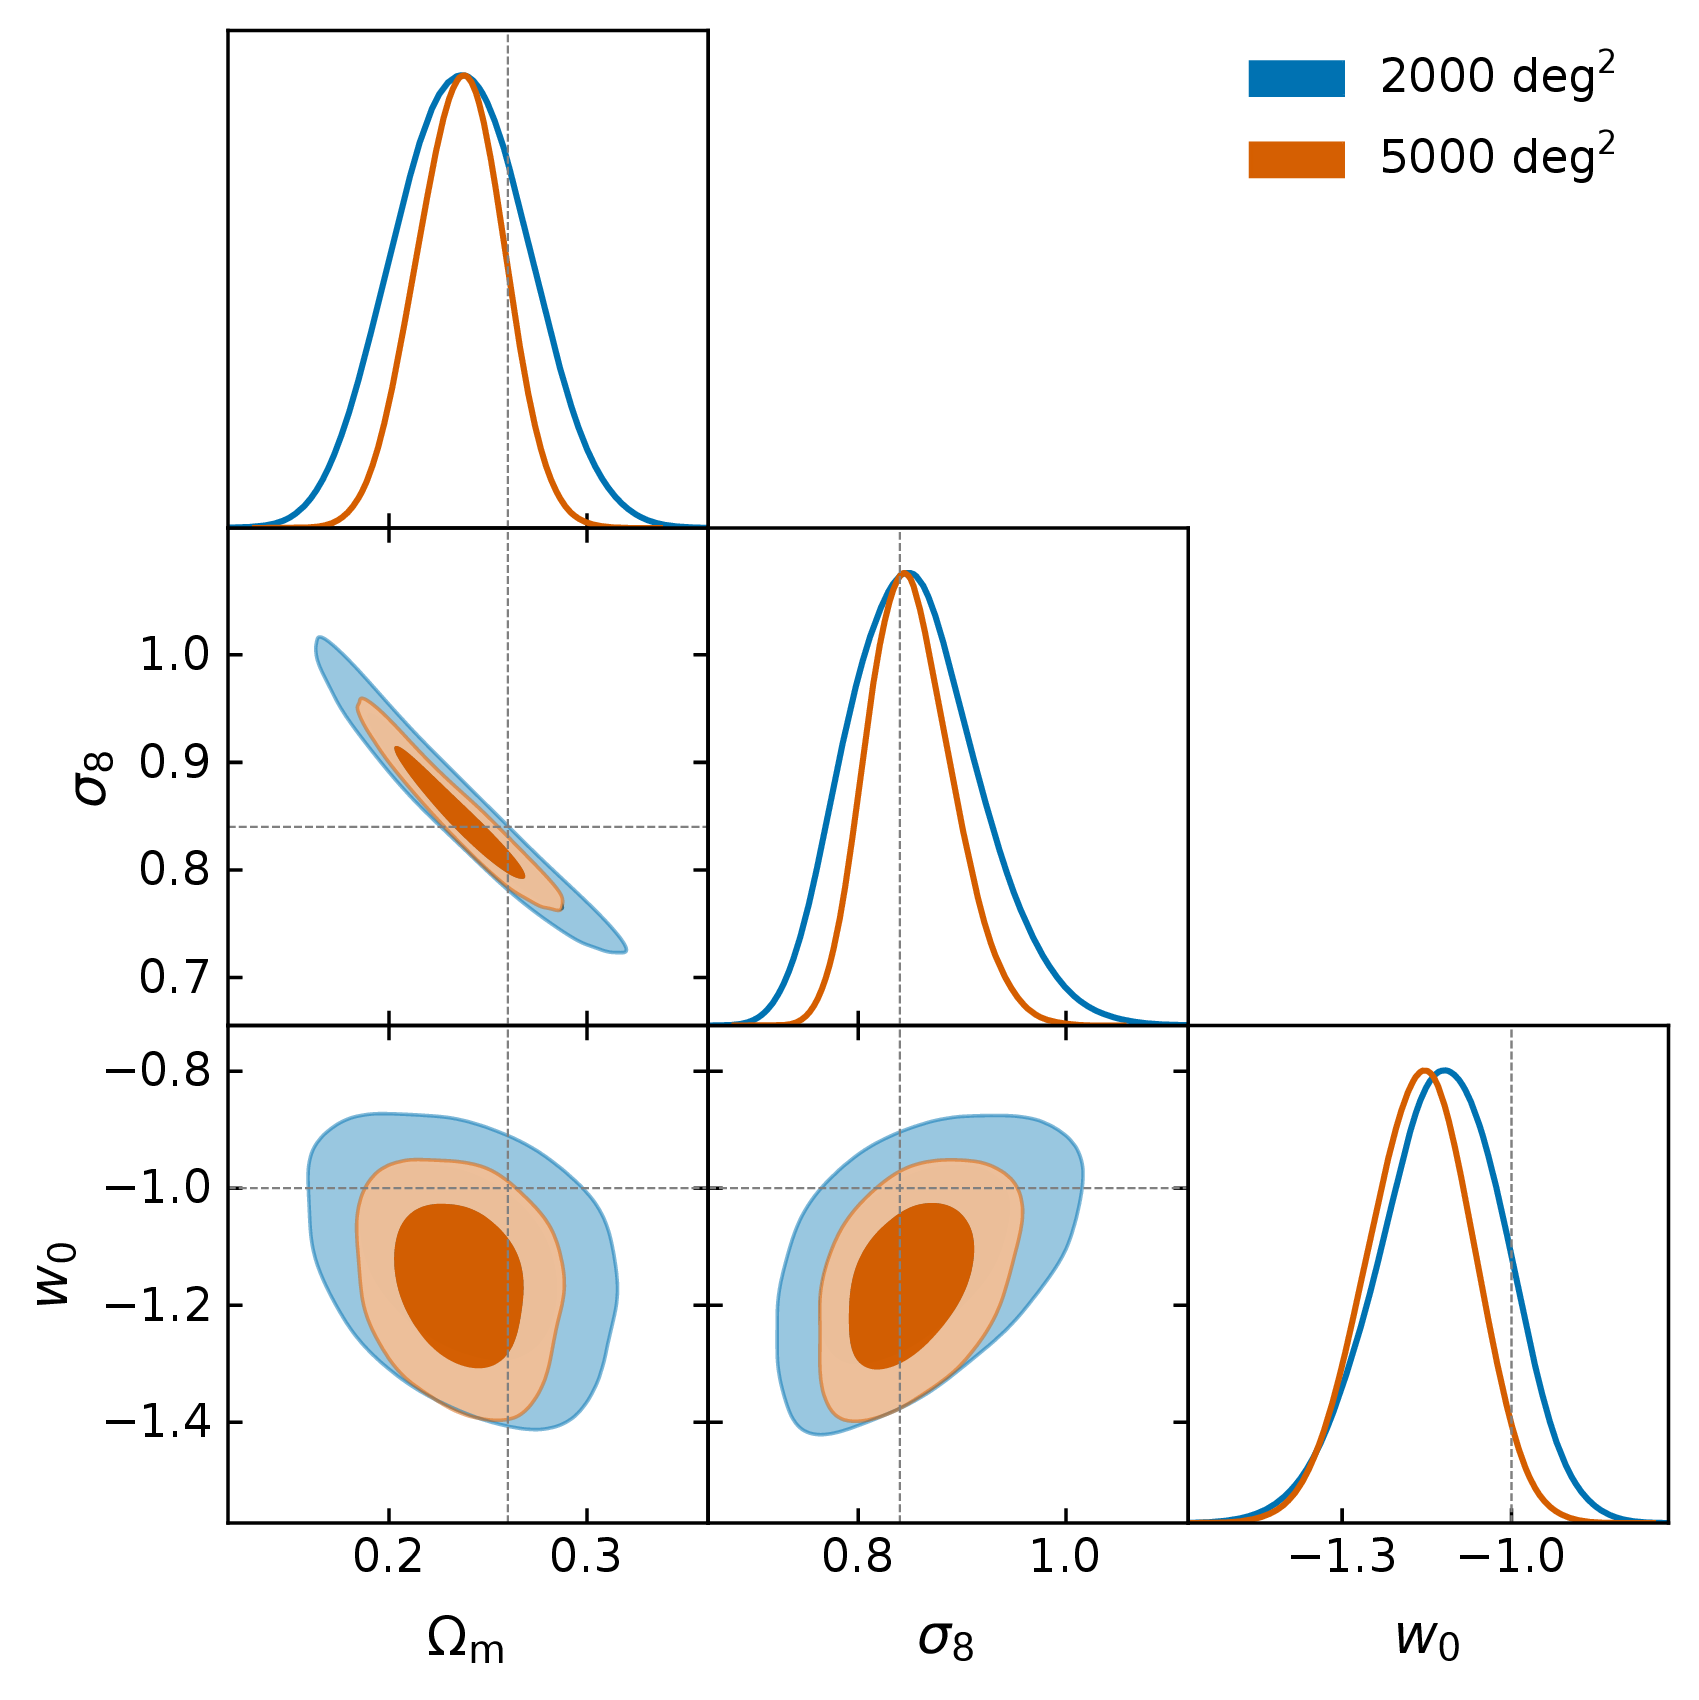
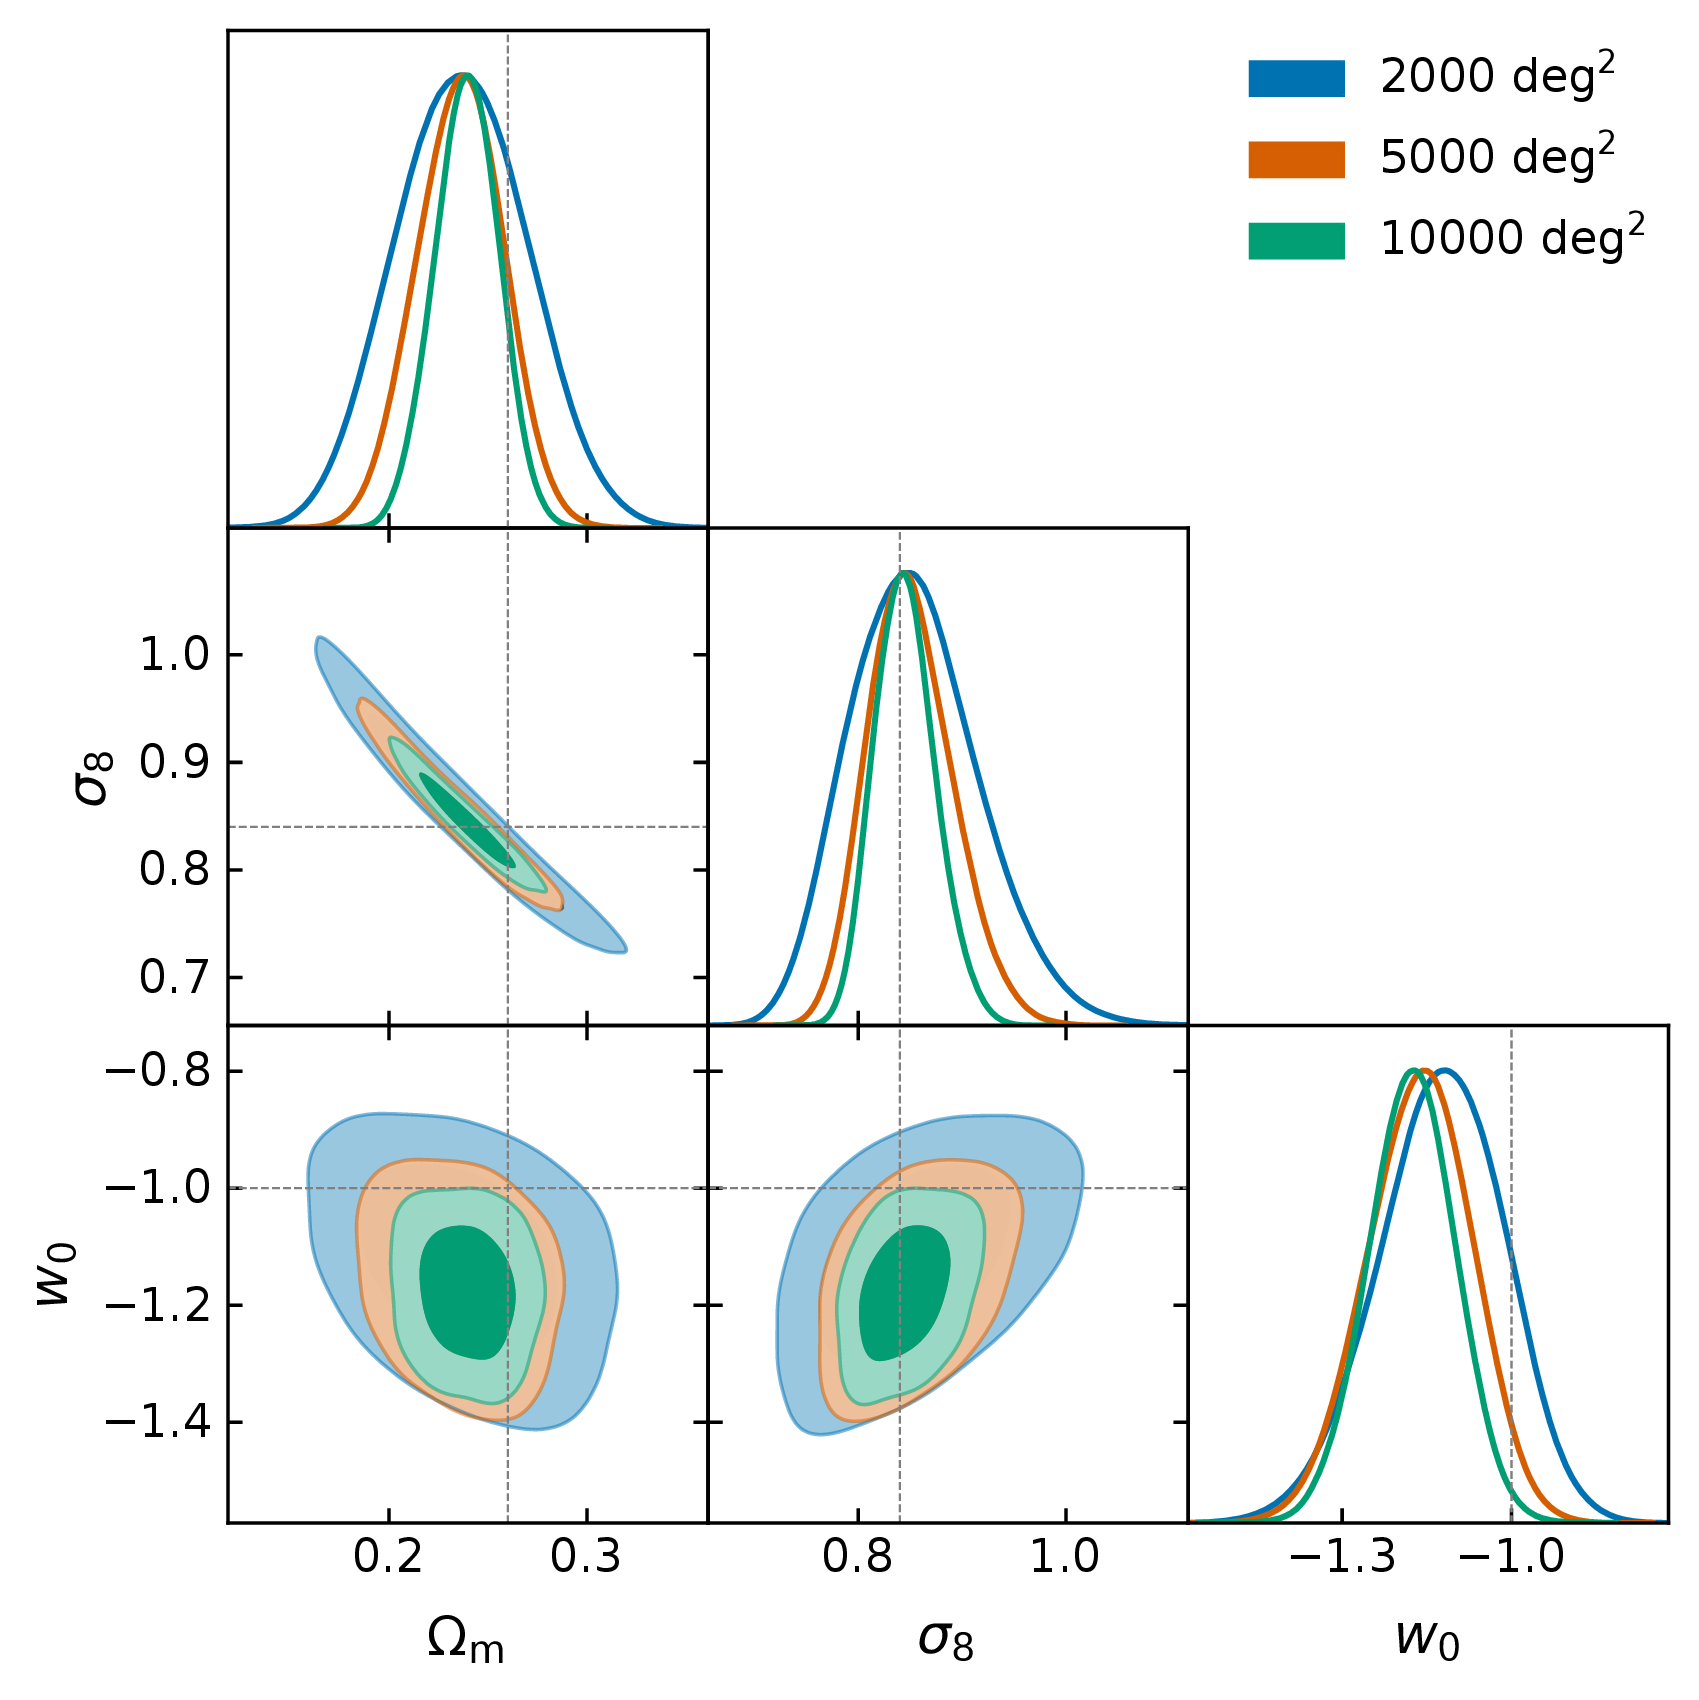
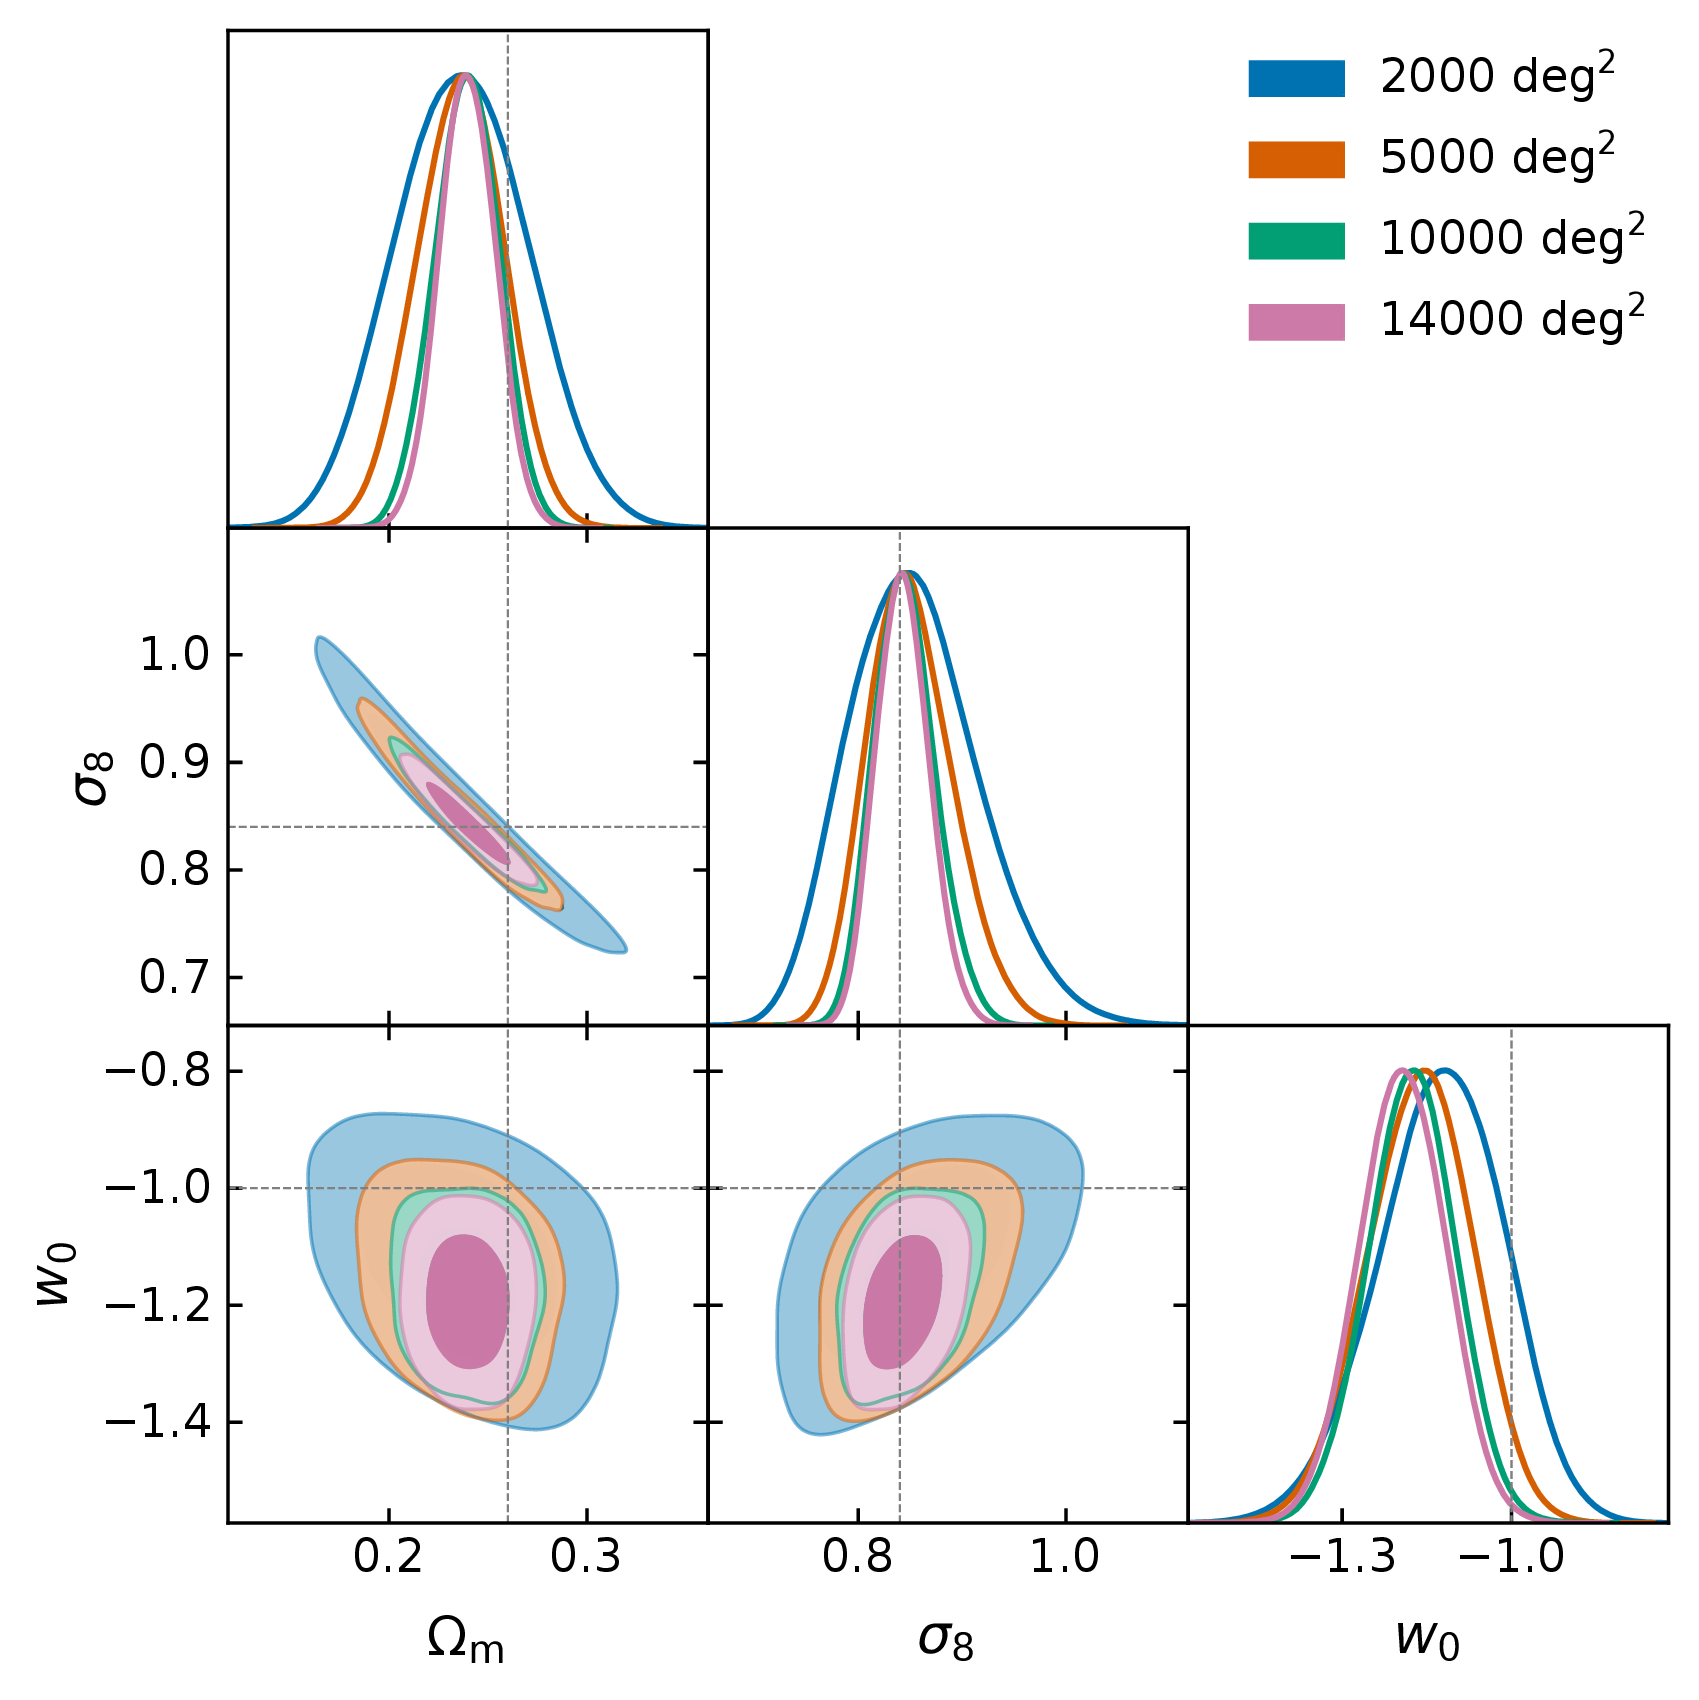
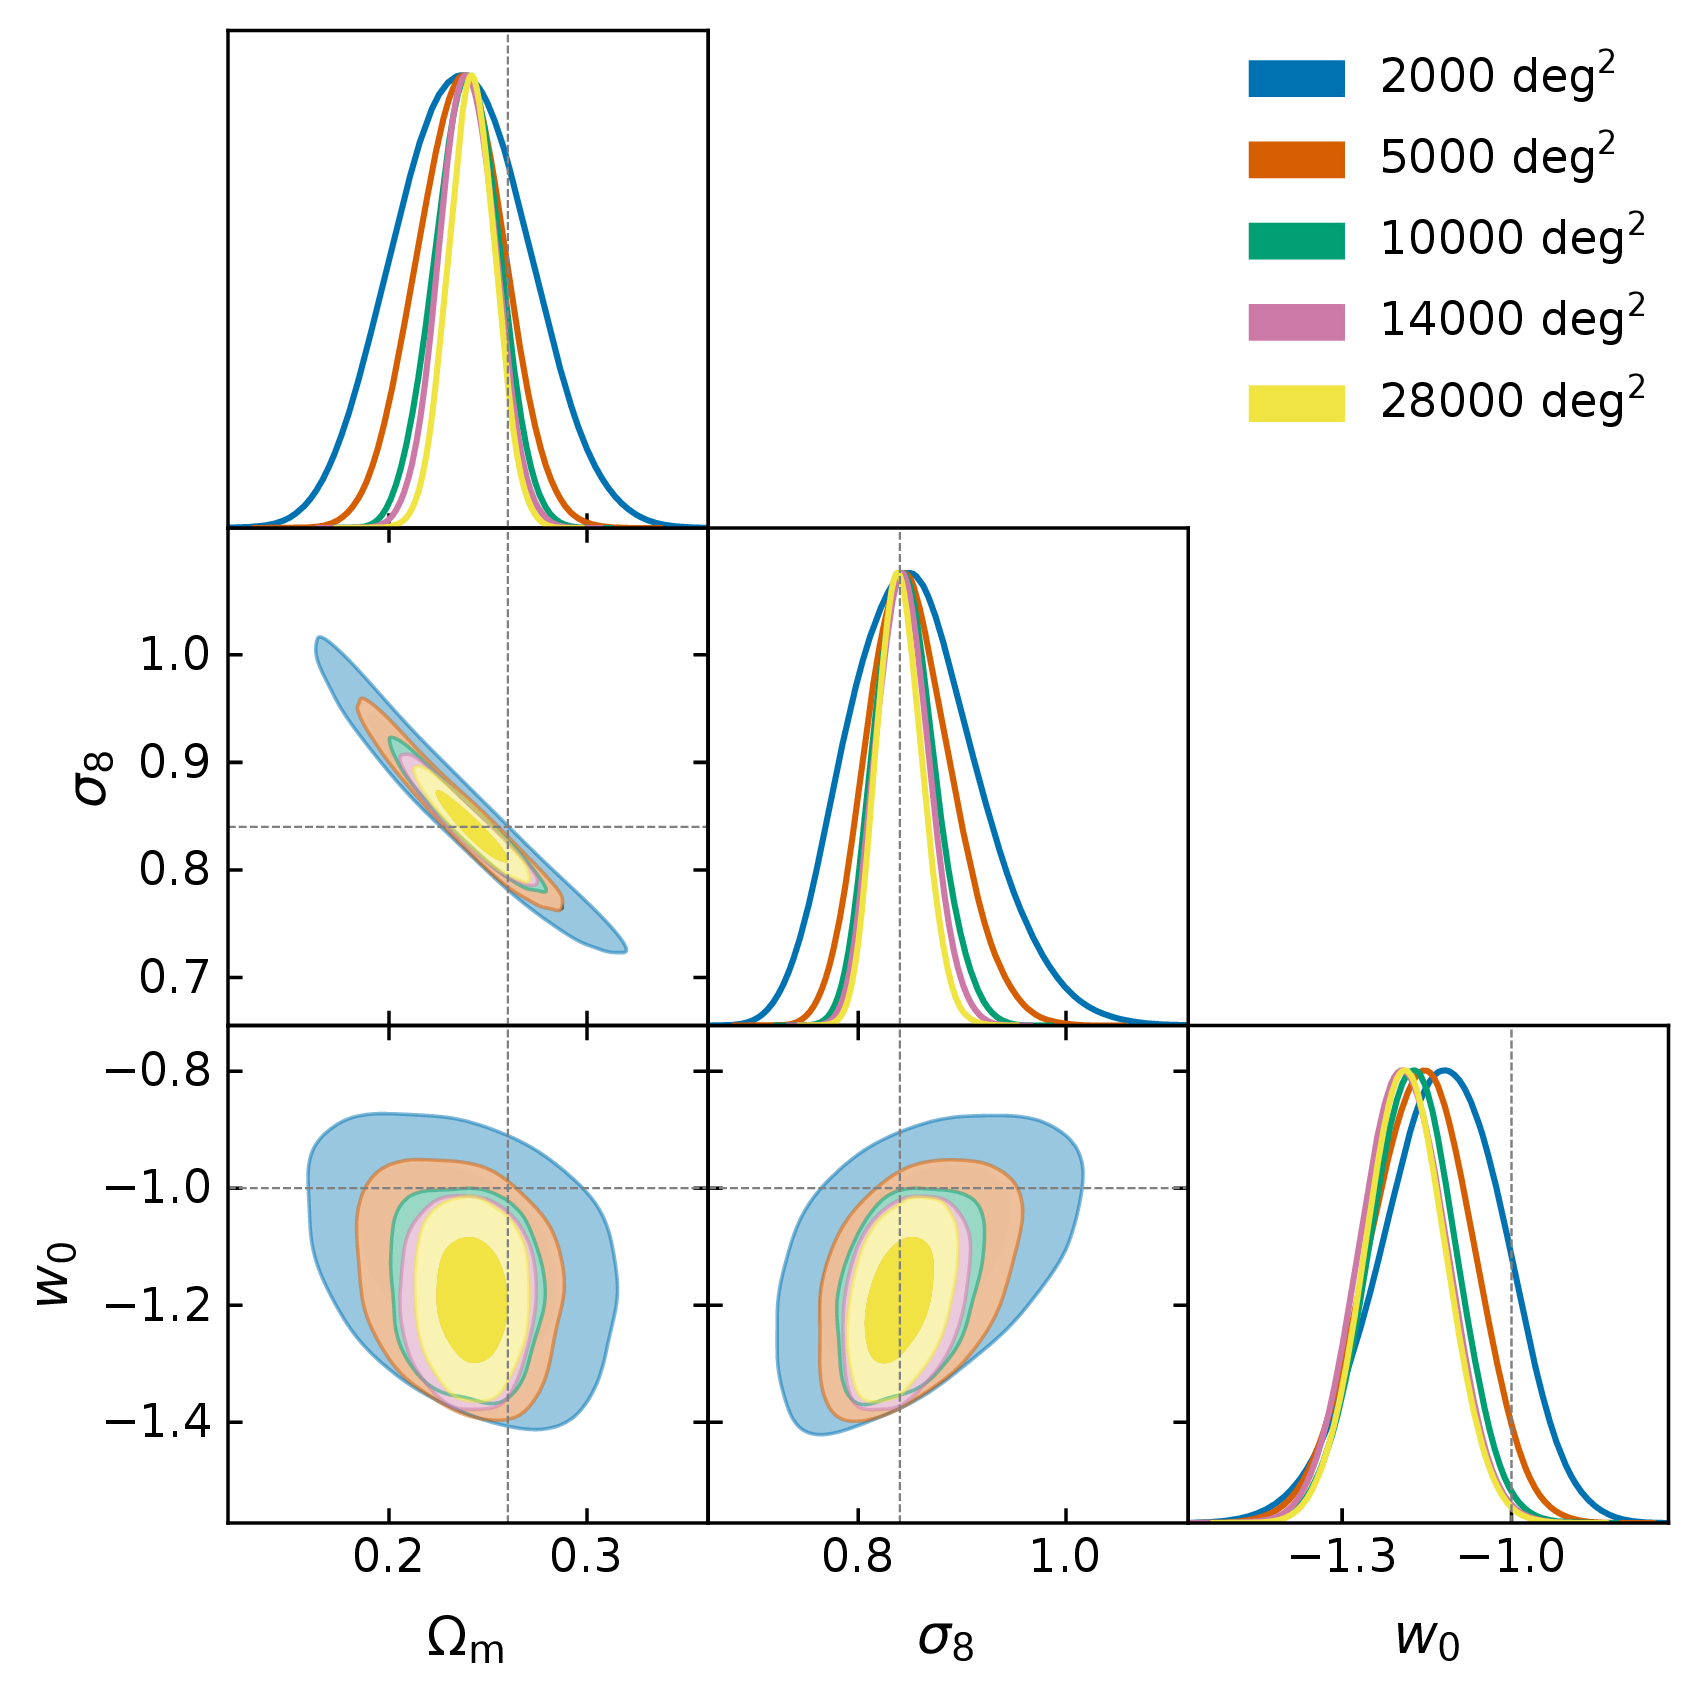
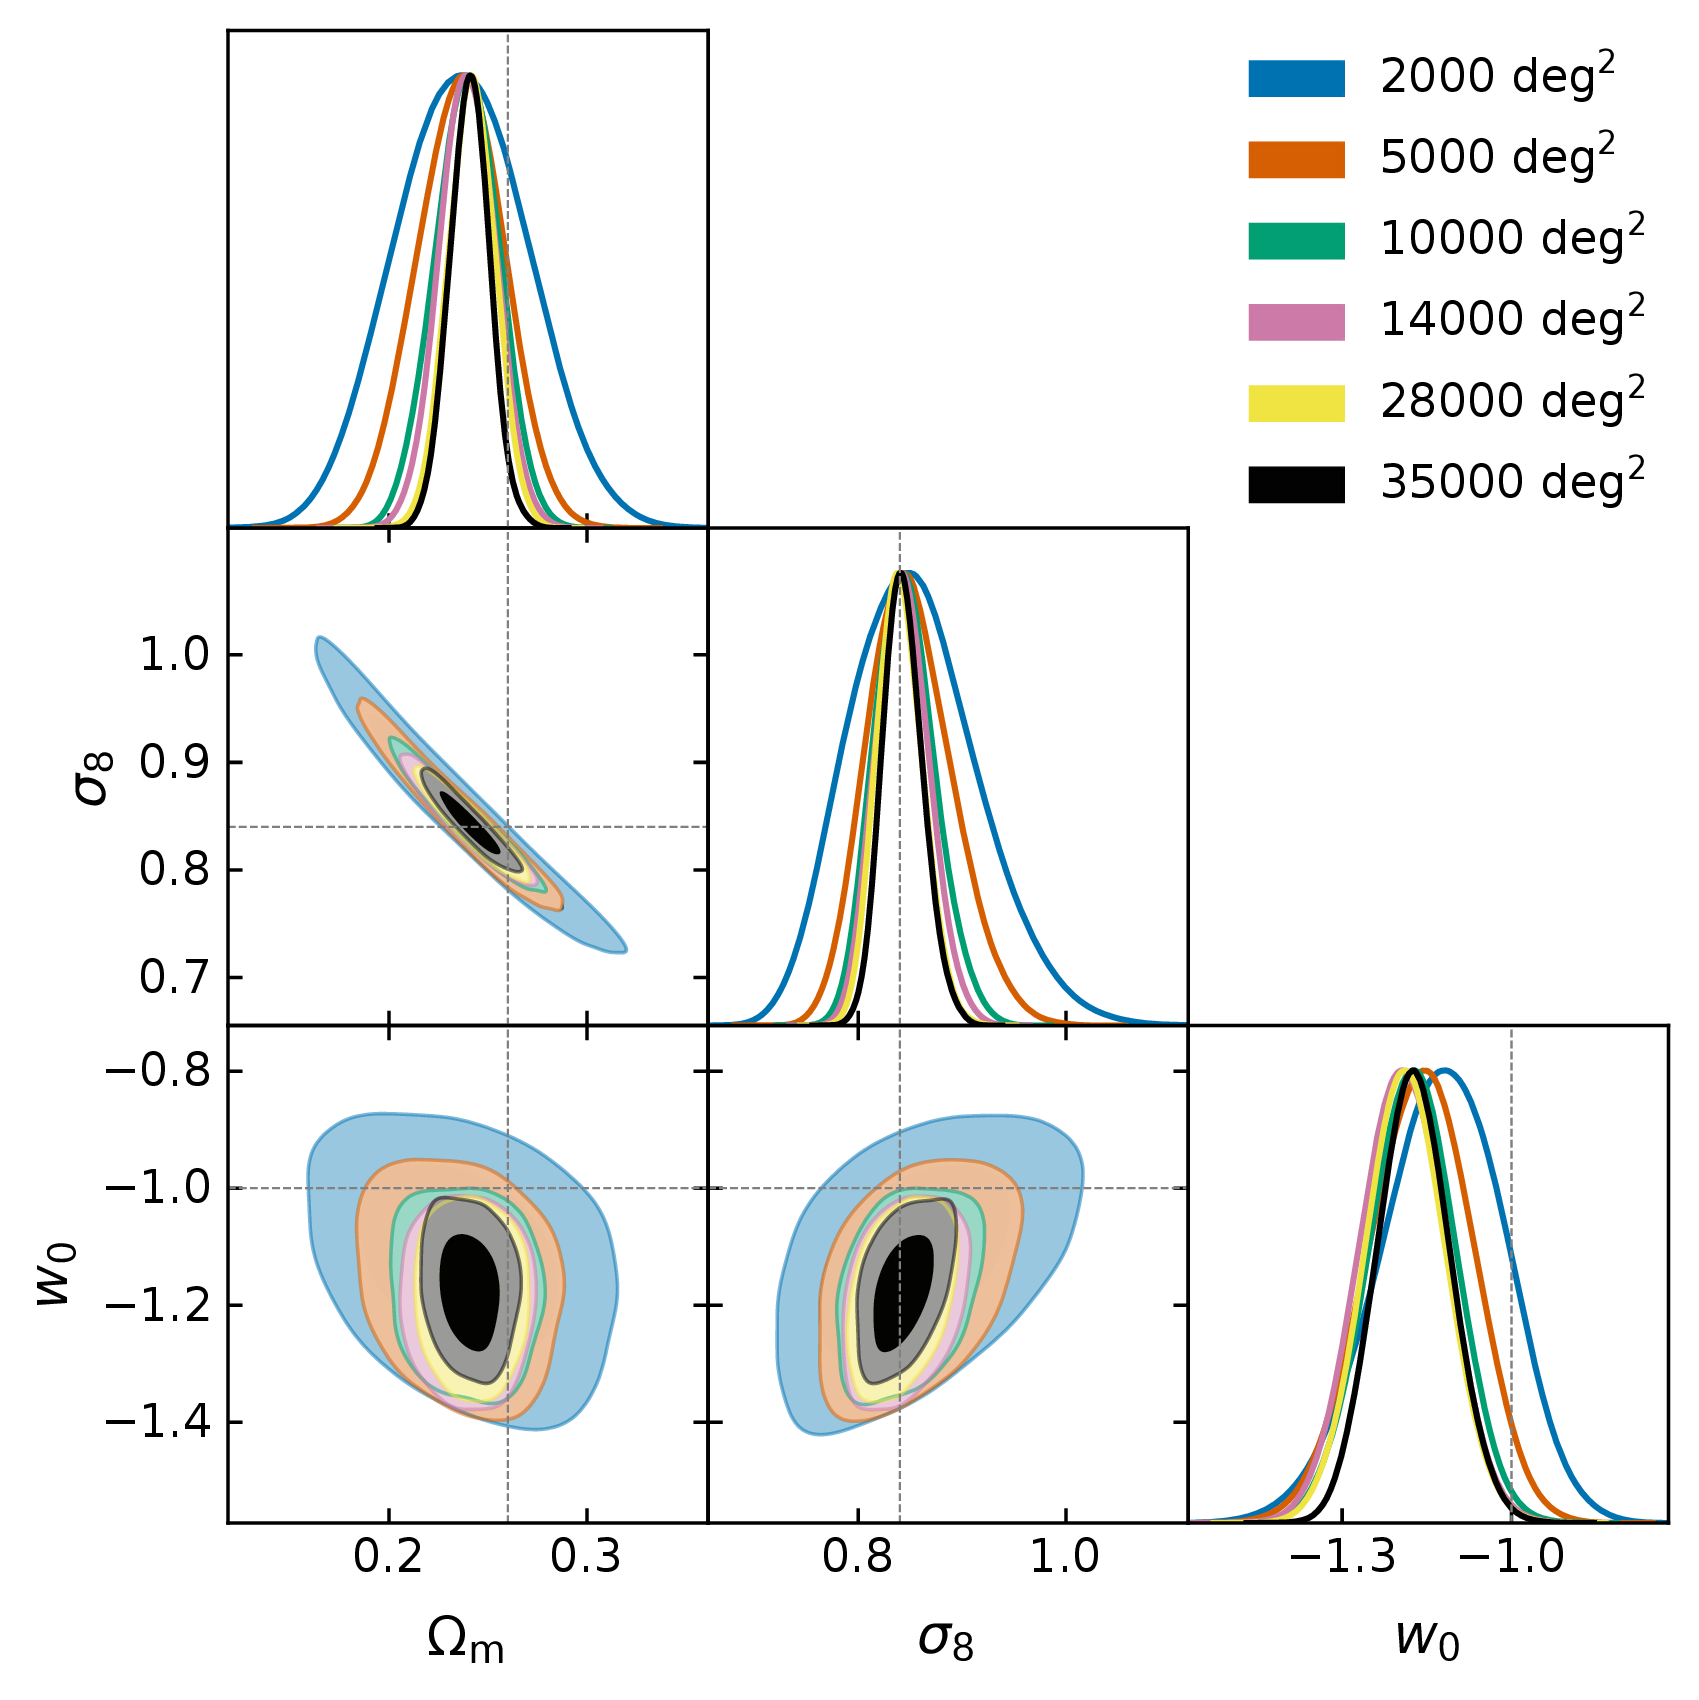
measured at full map resolution: $\ell_{\rm max}=1024$ for $C_\ell$, all four wavelet bands for the HOS
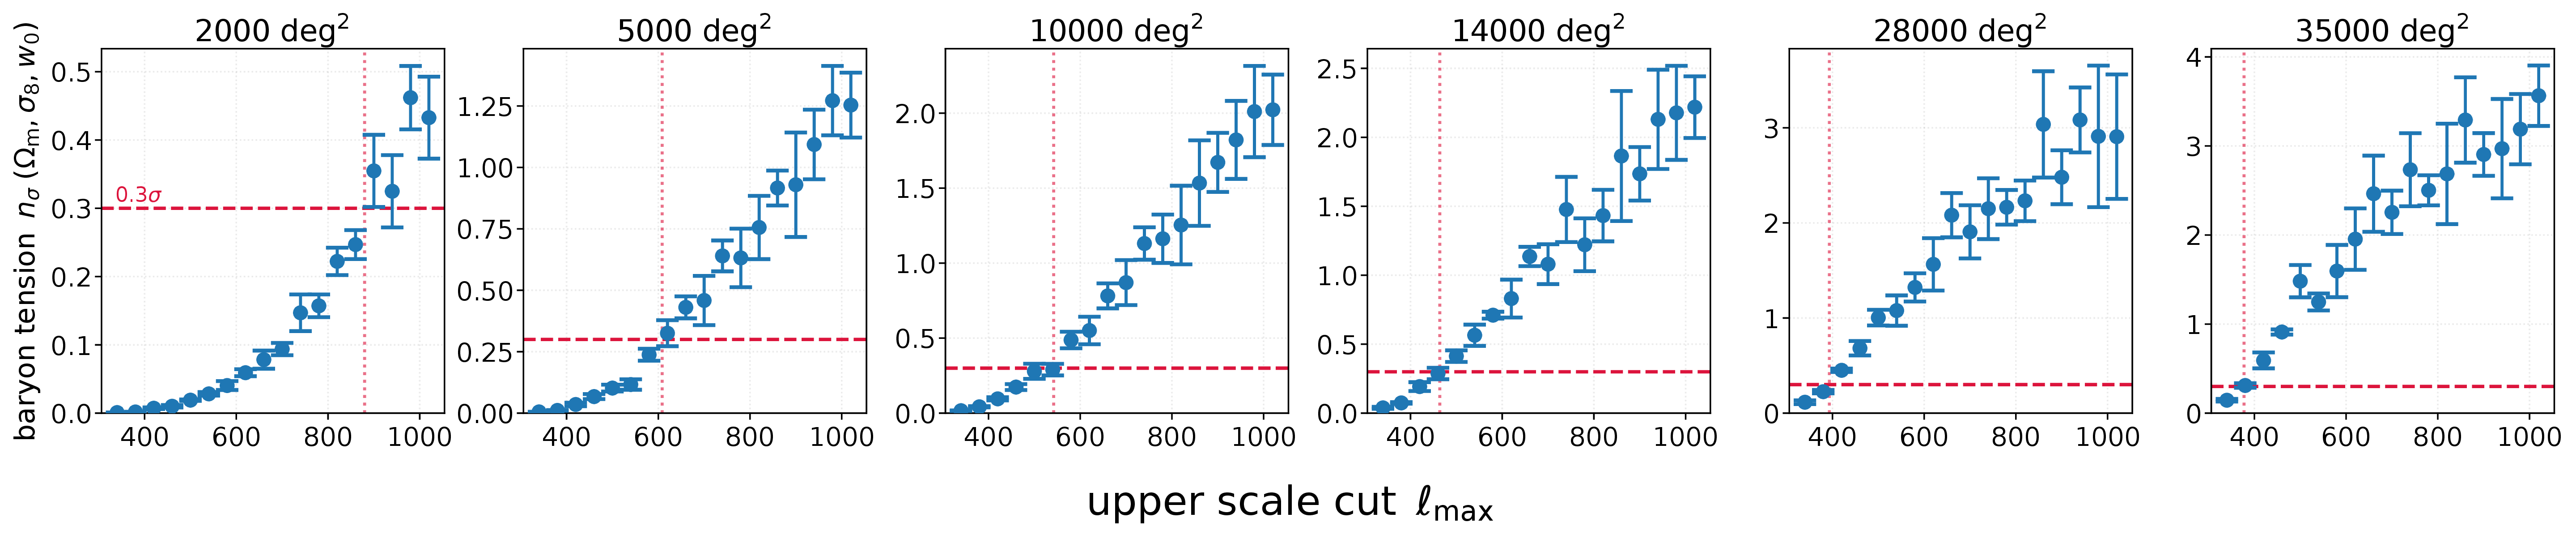
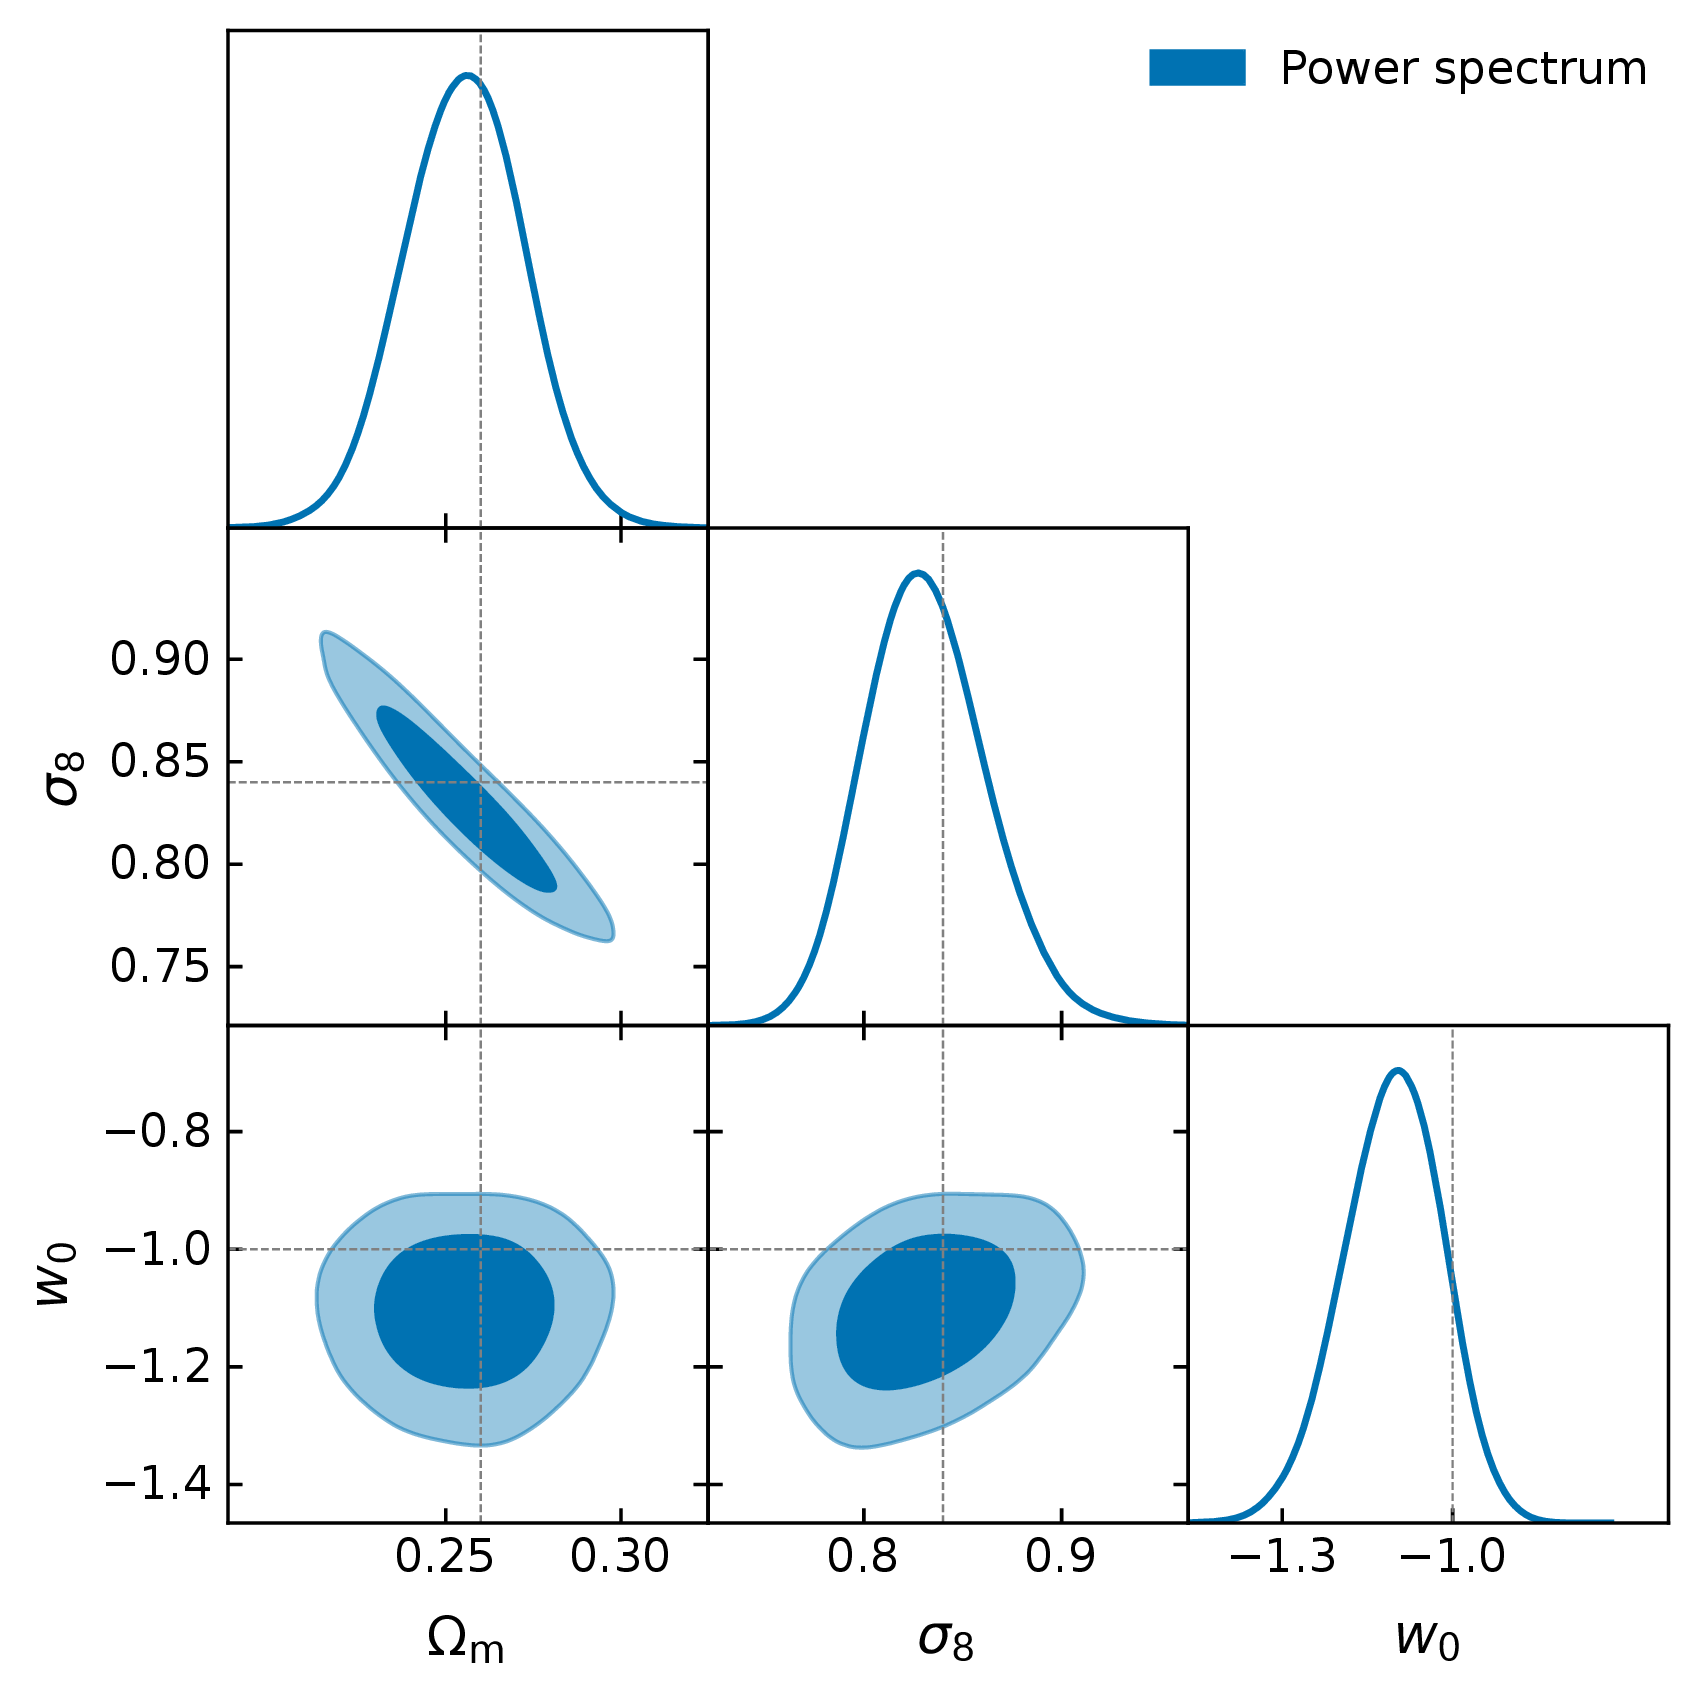
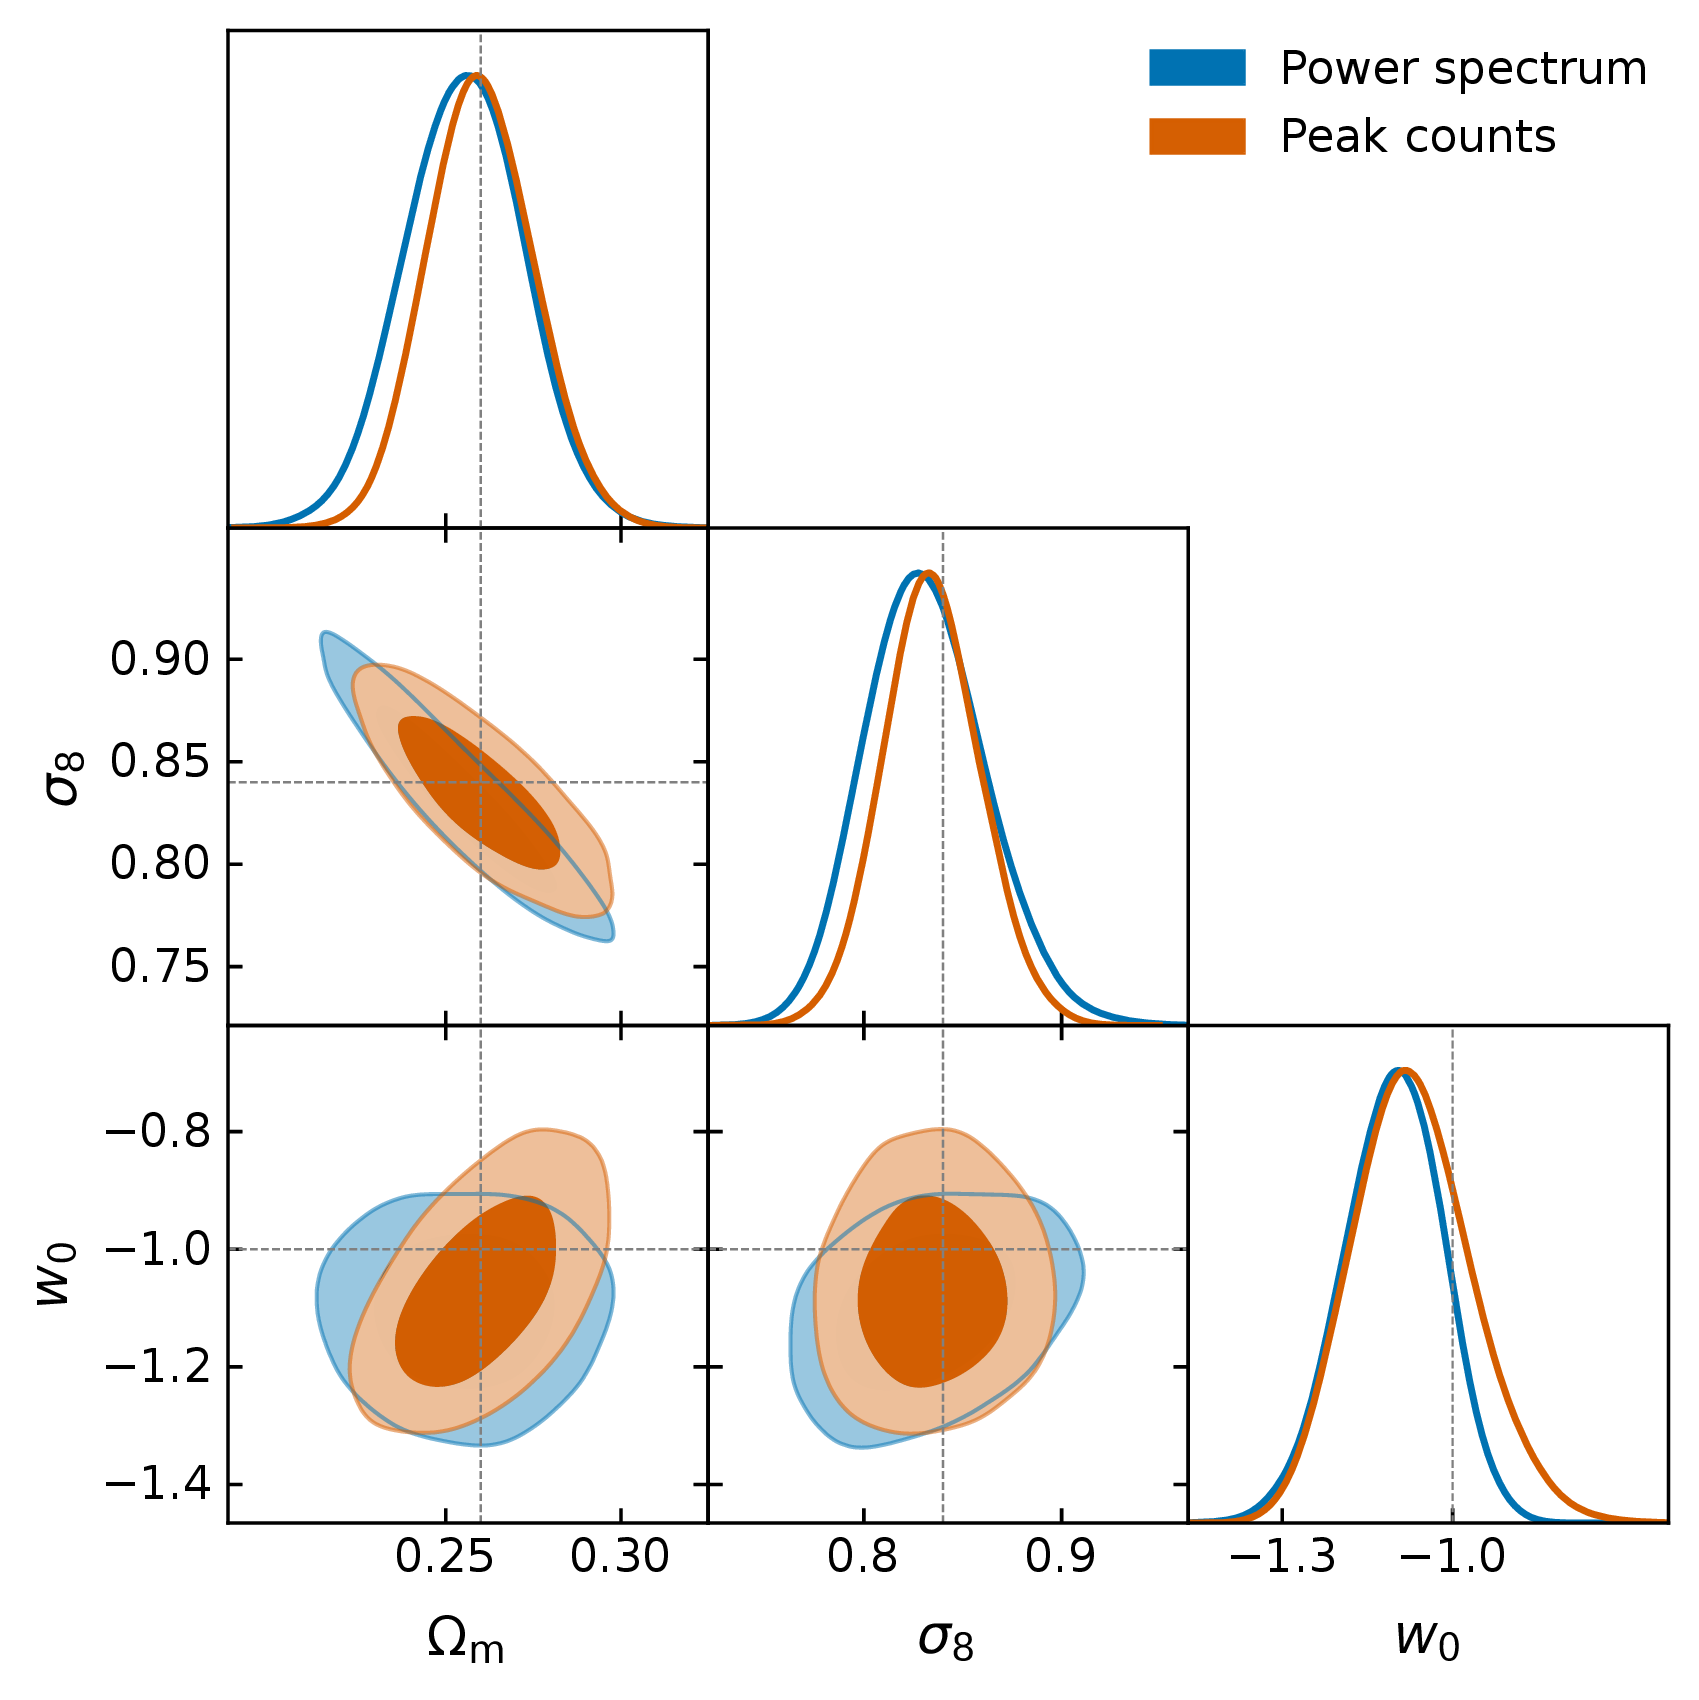
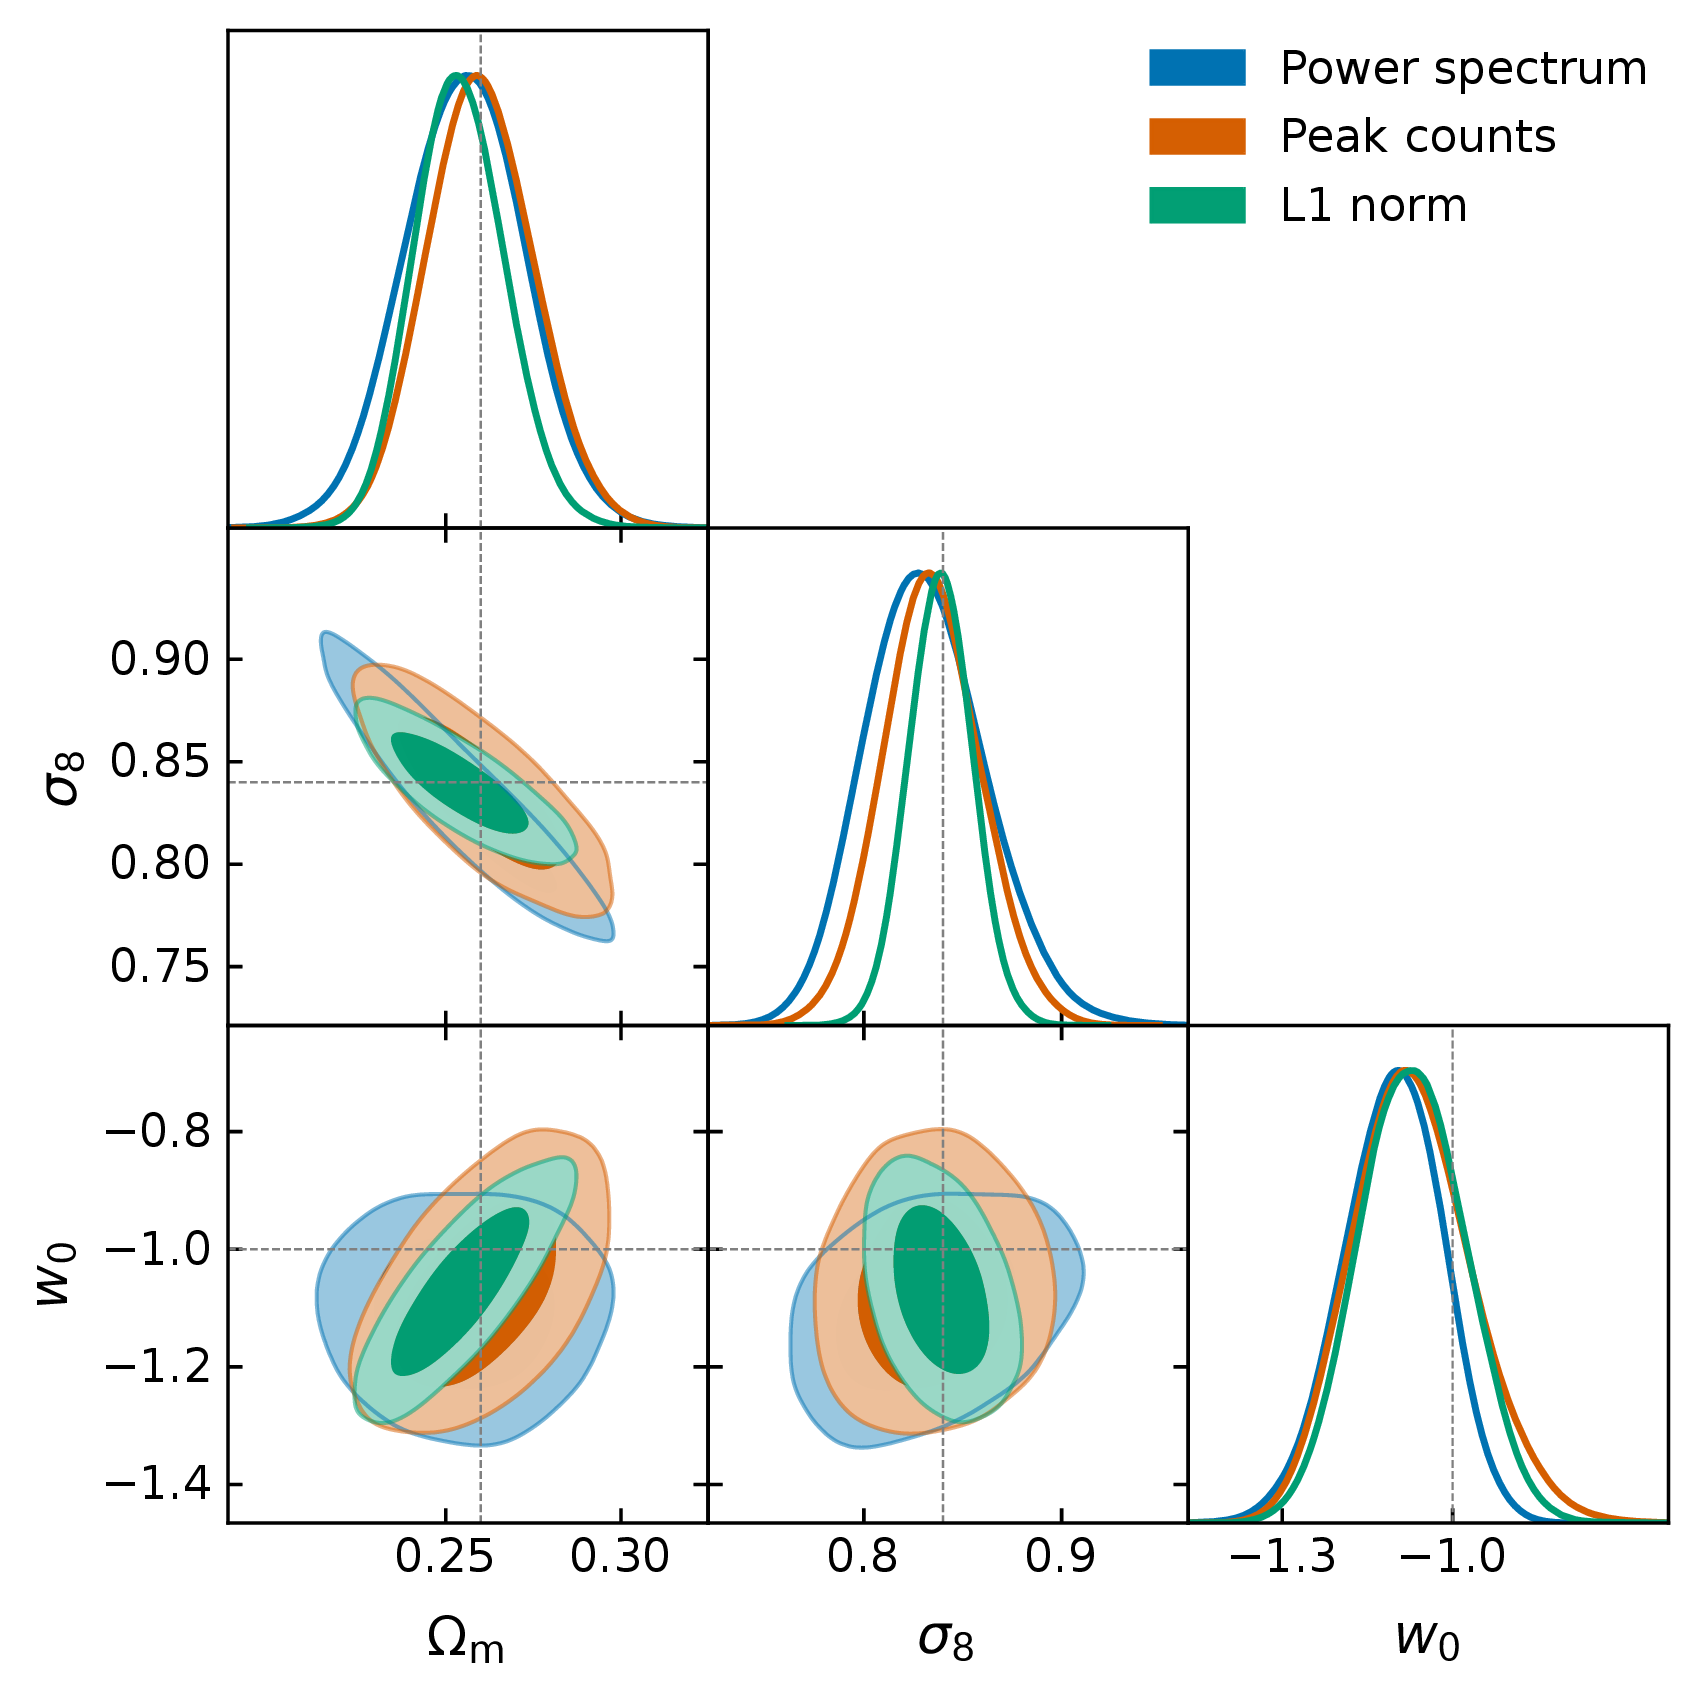
on baryon‑safe scales
and this is conservative
Several algorithms turn the shapes into a map of the mass distribution in the Universe. Does the choice matter for the cosmological results?
Can one algorithm be accurate and fast, with error bars we can trust, for a survey the size of Euclid?
A map is too big to compare with theory, so we reduce it to a few numbers, the summary statistics. How much cosmological information do they keep, and does it take a neural network?
The simulations leave out astrophysics we cannot model, on the small scales. Once those scales are removed, do these statistics still constrain the parameters better than the standard analysis?
Two about the map, two about the summary statistics.
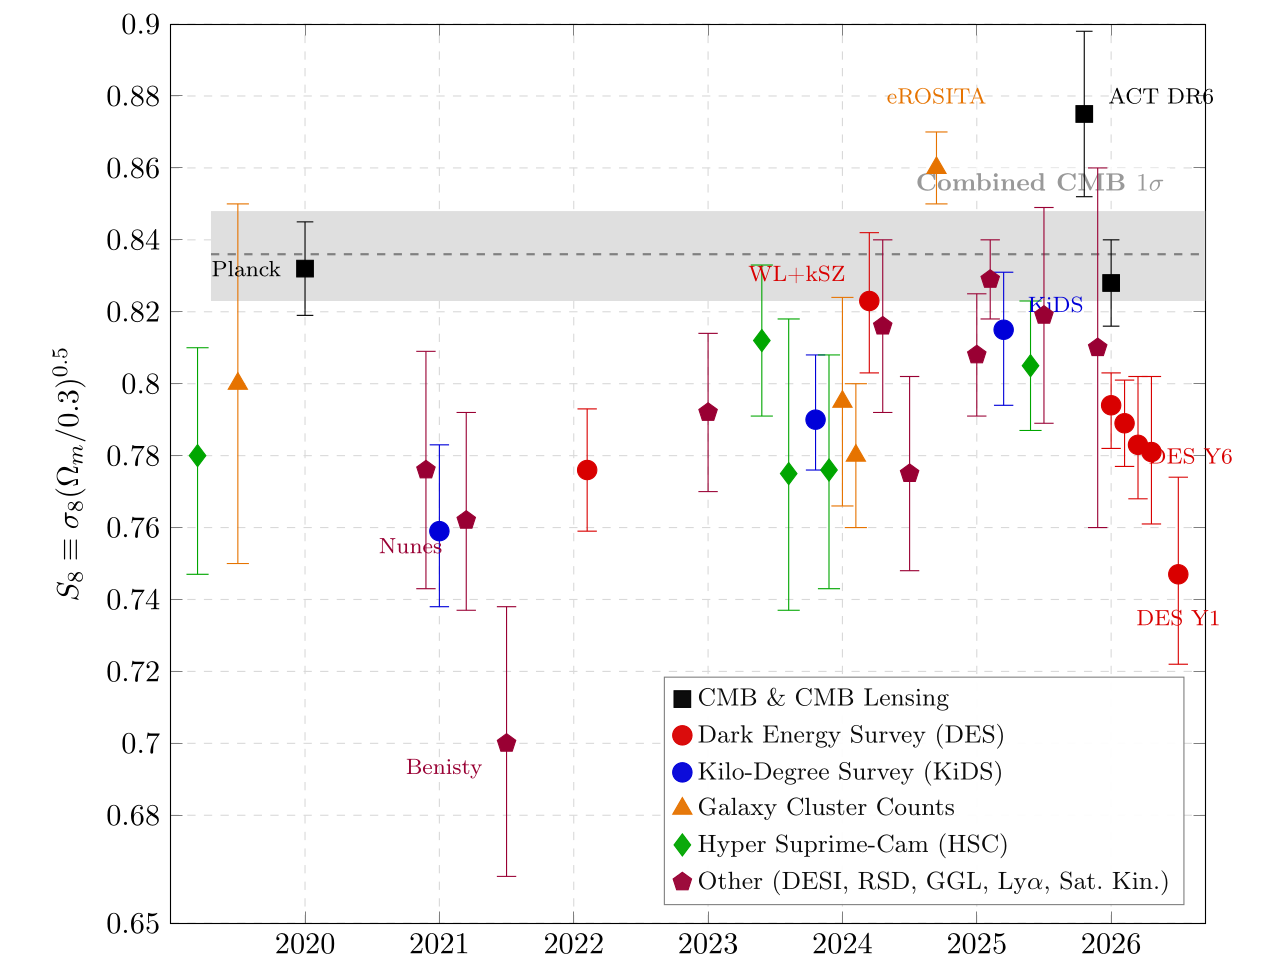
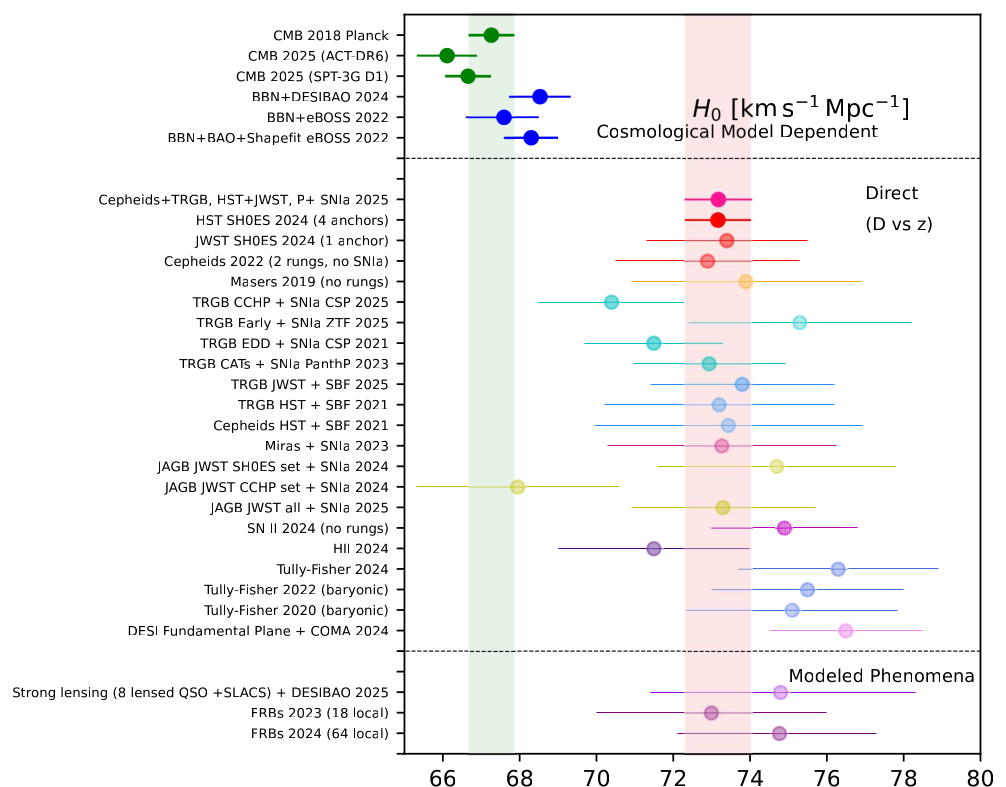
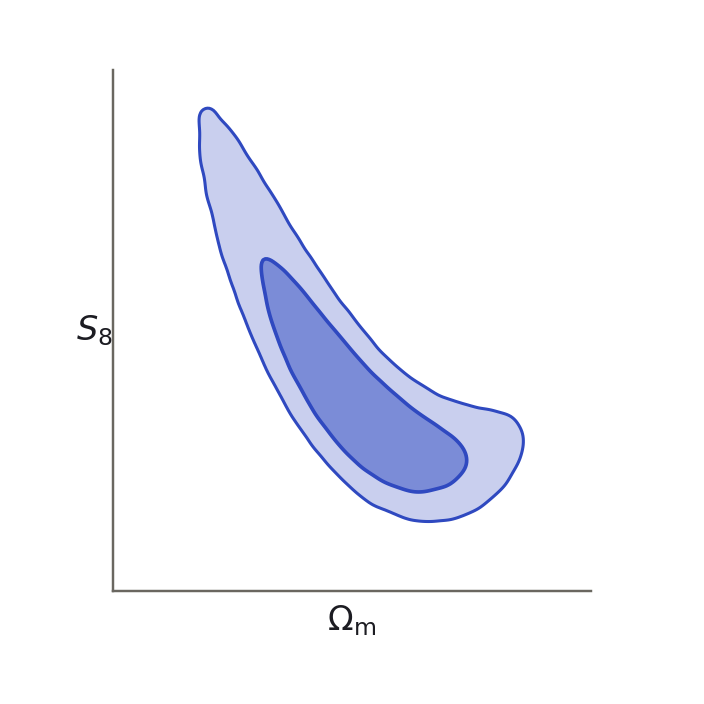
possible explanations new physics, a statistical fluctuation, or a systematic in the analysis
Whether a tension reflects new physics or an unrecognised systematic is settled by the analysis as much as by the data.
KiDS re-analysed with better shape and redshift calibration, and the tension fell below 1σ. And when the statistical errors shrink by an order of magnitude, that is what is left.
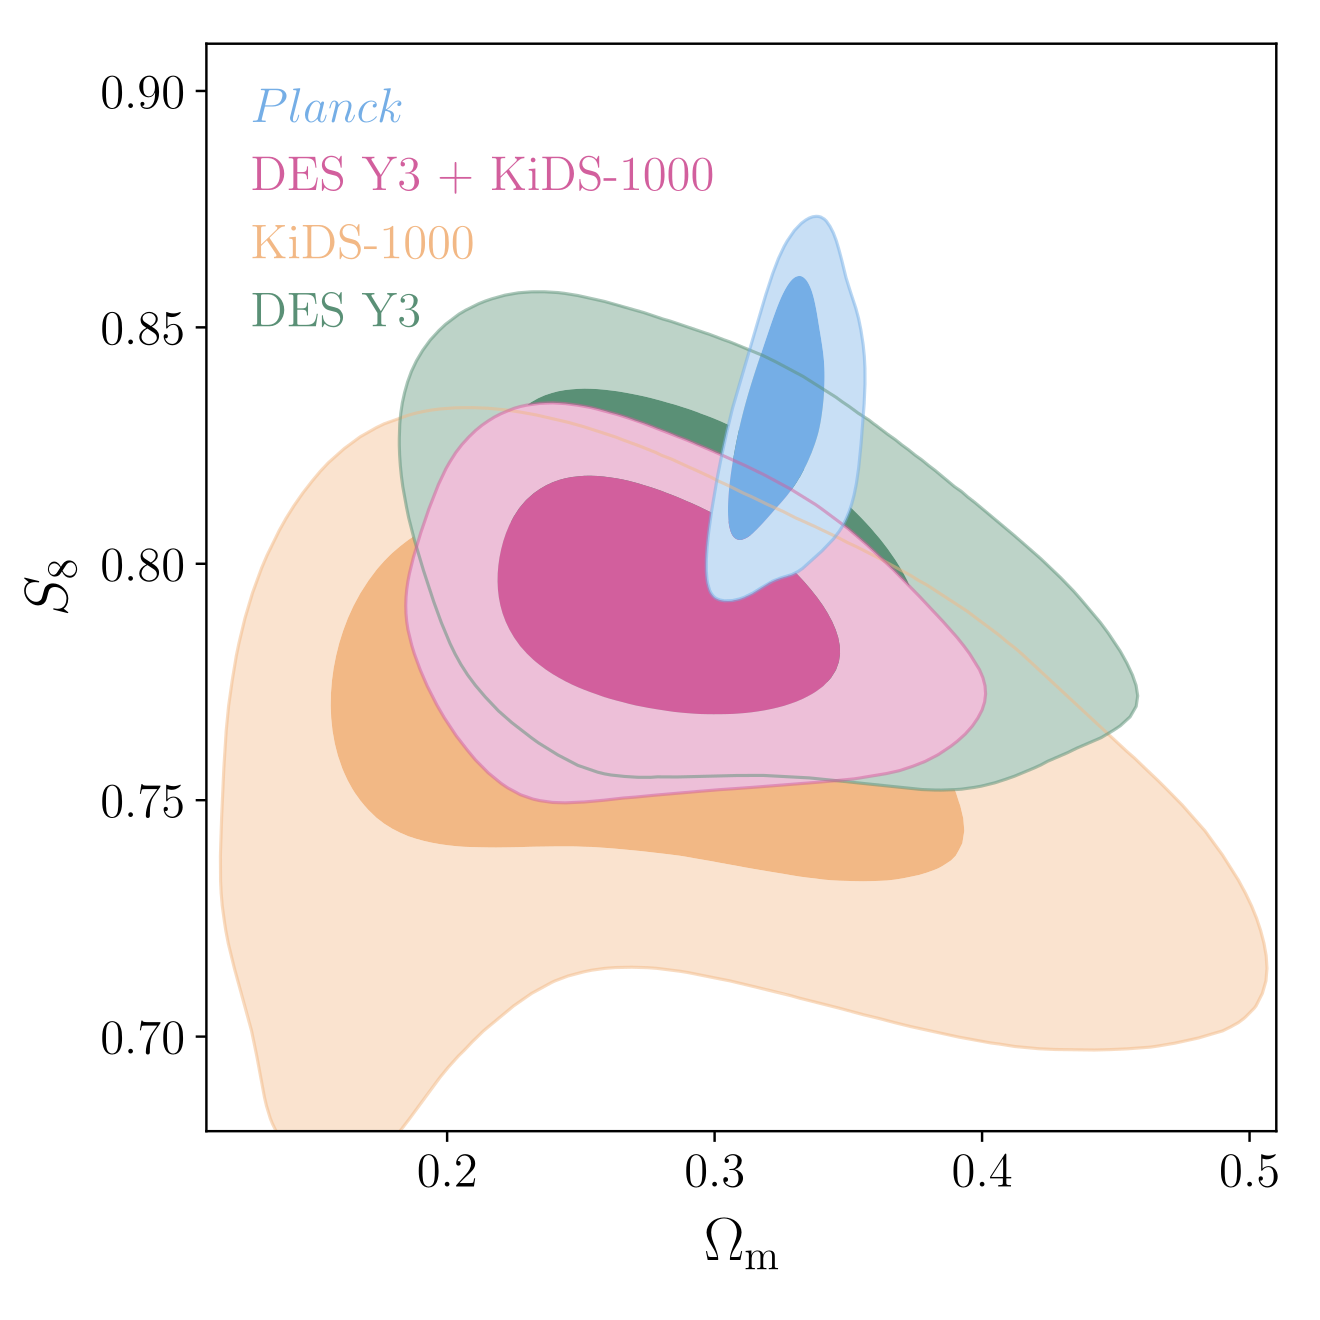
$S_8 \equiv \sigma_8\sqrt{\Omega_{\mathrm{m}}/0.3}$ — the combination cosmic shear measures best. The joint reanalysis sat 1.7σ below Planck.
Three ways to read a tension like this:
KiDS-Legacy re-analysed in 2025 and found $S_8 = 0.815$, below 1σ. It was the third one.
$A_s,\, n_s,\, f_{NL},\, \tau \ldots$
Statistics of initial conditions
$\Omega_m,\, \Omega_b,\, m_\nu \ldots$
Cosmic ingredients
$H_0,\, \Omega_\Lambda,\, w_0,\, w_a \ldots$
Expansion & dynamics
The simplest framework that fits almost all cosmological observations with a minimal parameter set.
But it is not without its challenges.
| Description | Param. | Value |
|---|---|---|
| Hubble parameter | $H_0$ | $67.66 \pm 0.42\ \mathrm{km\,s^{-1}\,Mpc^{-1}}$ |
| Total matter density | $\Omega_m$ | $0.3111 \pm 0.0056$ |
| Dark matter density | $\Omega_c h^2$ | $0.11933 \pm 0.00091$ |
| Baryon density | $\Omega_b h^2$ | $0.02242 \pm 0.00014$ |
| Dark energy density | $\Omega_\Lambda$ | $0.6889 \pm 0.0056$ |
| Power spectrum normalisation | $\sigma_8$ | $0.8102 \pm 0.0060$ |
| Spectral index | $n_s$ | $0.9665 \pm 0.0038$ |
| Reionisation optical depth | $\tau$ | $0.0561 \pm 0.0071$ |
| Sum of neutrino masses | $M_\nu$ | $< 0.12\ \mathrm{eV}$ |
Planck Collaboration, “Planck 2018 results. VI. Cosmological parameters”, A&A
Different cosmological probes capture different physical aspects of the Universe:
$\kappa$ is a projection of the matter field, so what lensing measures is how much matter there is and how clumped it is.
| parameter | what it is | lensing |
|---|---|---|
| $\Omega_m$ | the fraction of the Universe that is matter | strong |
| $\sigma_8$ | how clumpy that matter is, on $8\,h^{-1}$Mpc scales | strong |
| $S_8$ | $\sigma_8\sqrt{\Omega_m/0.3}$, the combination those two collapse into | what we measure |
| $w_0$ | the dark energy equation of state, $p = w\rho$ | moderate |
| $h$ | the expansion rate today | weak |
| $n_s$ | the tilt of the primordial power spectrum | weak |
| $\Omega_b$ | how much of that matter is baryons | weak |
The amplitude of $\kappa$ goes roughly as $\sigma_8\Omega_m^{0.5}$, so that combination is pinned and the two separately are not. Shape parameters are the CMB’s job.
Two are about the path light takes through a simulation. The third is about the projection integral in an analytic prediction.
| what it assumes | where it stands | |
|---|---|---|
| Born | the potential is read on the straight, undeflected ray | first order in $\Phi$; post-Born terms on $\kappa$ sit well below current errors |
| ray tracing | nothing: rays are deflected plane by plane, along their true path | keeps the lens–lens coupling; kept for the shear and the post-Born terms |
| Limber | only transverse modes reach the projection, $k = \ell / f_K(\chi)$ | better than a percent on Stage IV scales |
Our maps are Born: CosmoGridV1 sums lens planes along the straight ray. Limber enters only where an analytic $P_\kappa$ is needed, as in the Wiener prior; every statistic here is measured on maps.
Kaiser–Squires step by step, inpainting, mass mapping as an inverse problem, the Bayesian view of the prior, and MCALens.
Kaiser–Squires inverts in Fourier space, where a gap left at zero is not a local problem: it spreads over every mode. Border artefacts and E/B leakage follow.
A mask costs you sparsity: its cut edges are badly represented in the DCT and throw off spurious coefficients. So take the map with the fewest coefficients that still matches the data outside the mask.
$$\min_{\kappa}\; \lVert \Phi^{\mathsf{T}}\kappa \rVert_0 \quad \text{s.t.} \quad \lVert \kappa_{\rm obs} - \mathbf{M}\kappa \rVert_2 \le \sigma$$
$$\kappa^{\,n+1} \;=\; \Delta_{\Phi,\lambda_n}\!\left( \kappa^{\,n} + \mathbf{M}\big(\kappa_{\rm obs} - \kappa^{\,n}\big)\right)$$
Decompose, hard-threshold at $\lambda_n$, reconstruct, put the observed pixels back. Repeat. $\lambda_n$ starts at the largest coefficient and cools to zero over about a hundred iterations, so the strong coefficients go in first and the faint detail last.
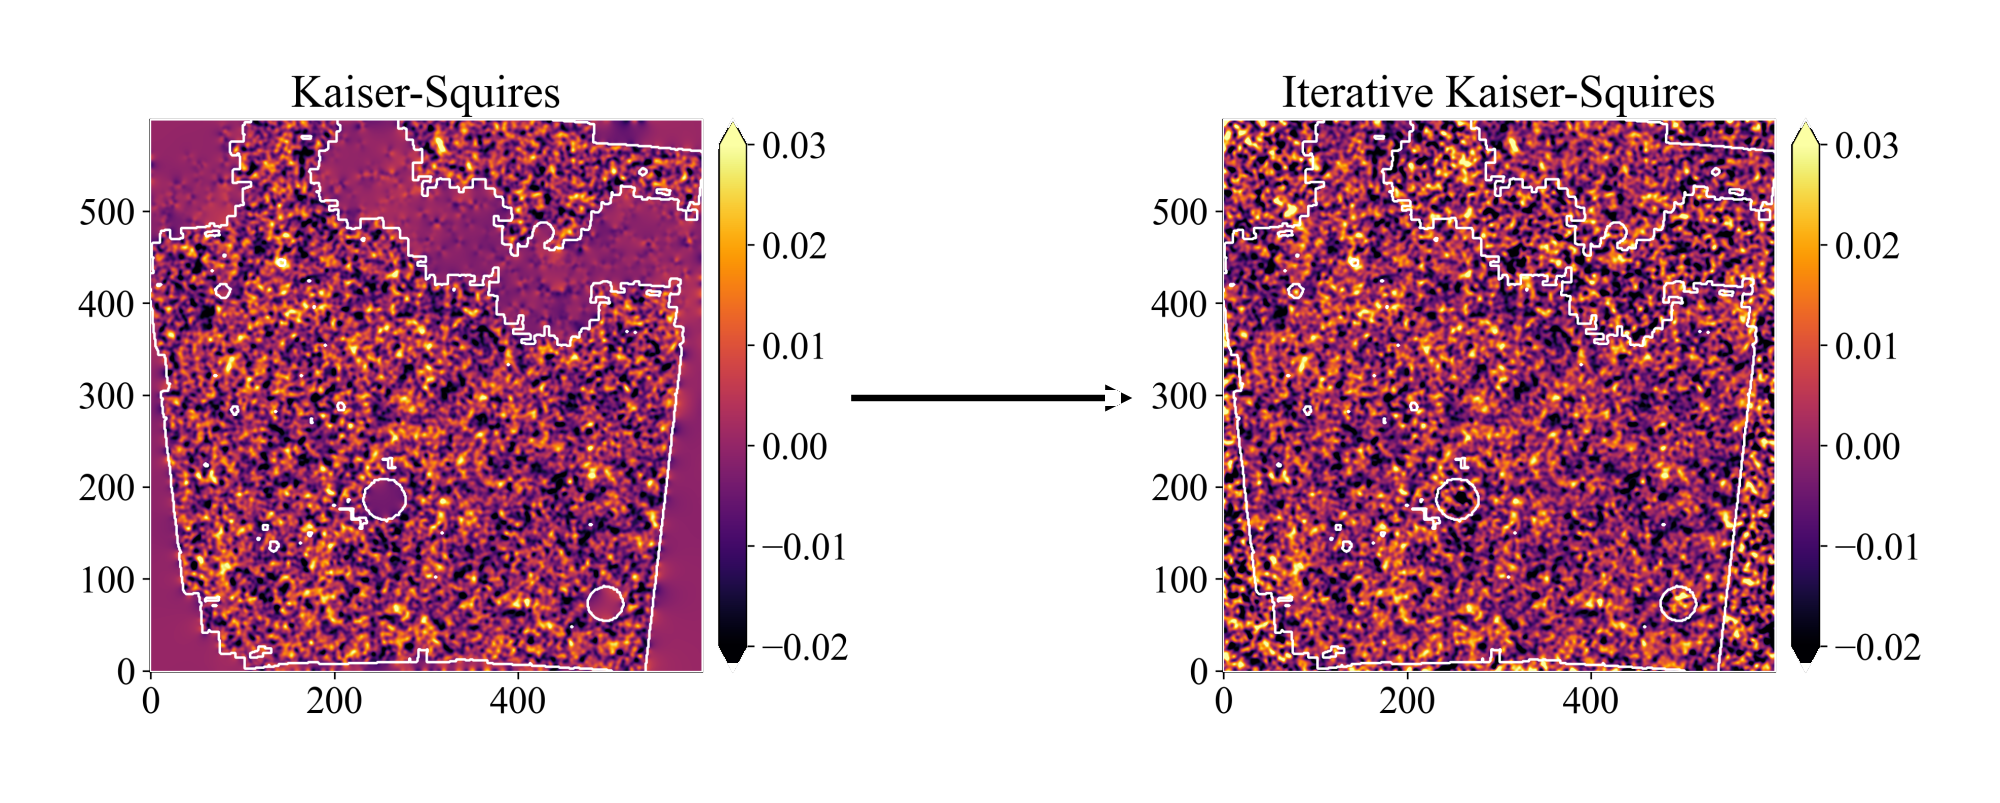
Pires et al. tried wavelets, curvelets and their combinations. Wavelets fit an isolated halo better. But most of a κ map is the texture between the haloes, and there the DCT wins.
Pires et al. 2009 · Elad et al. 2005
Inpainting is preprocessing, so it bolts onto any method: inpainted Wiener, sparse recovery and MCALens variants all exist. A method with its own prior can instead put $\mathbf{M}$ in the forward operator and let the reconstruction fill the gap.
The posterior probability of a map given the shear is proportional to the likelihood of the shear given the map, times the prior on the map.
The same structure returns in Part 3, with the cosmological parameters as the unknown and no explicit likelihood.
The same structure returns in Part 3, with the cosmological parameters as the unknown and no explicit likelihood.
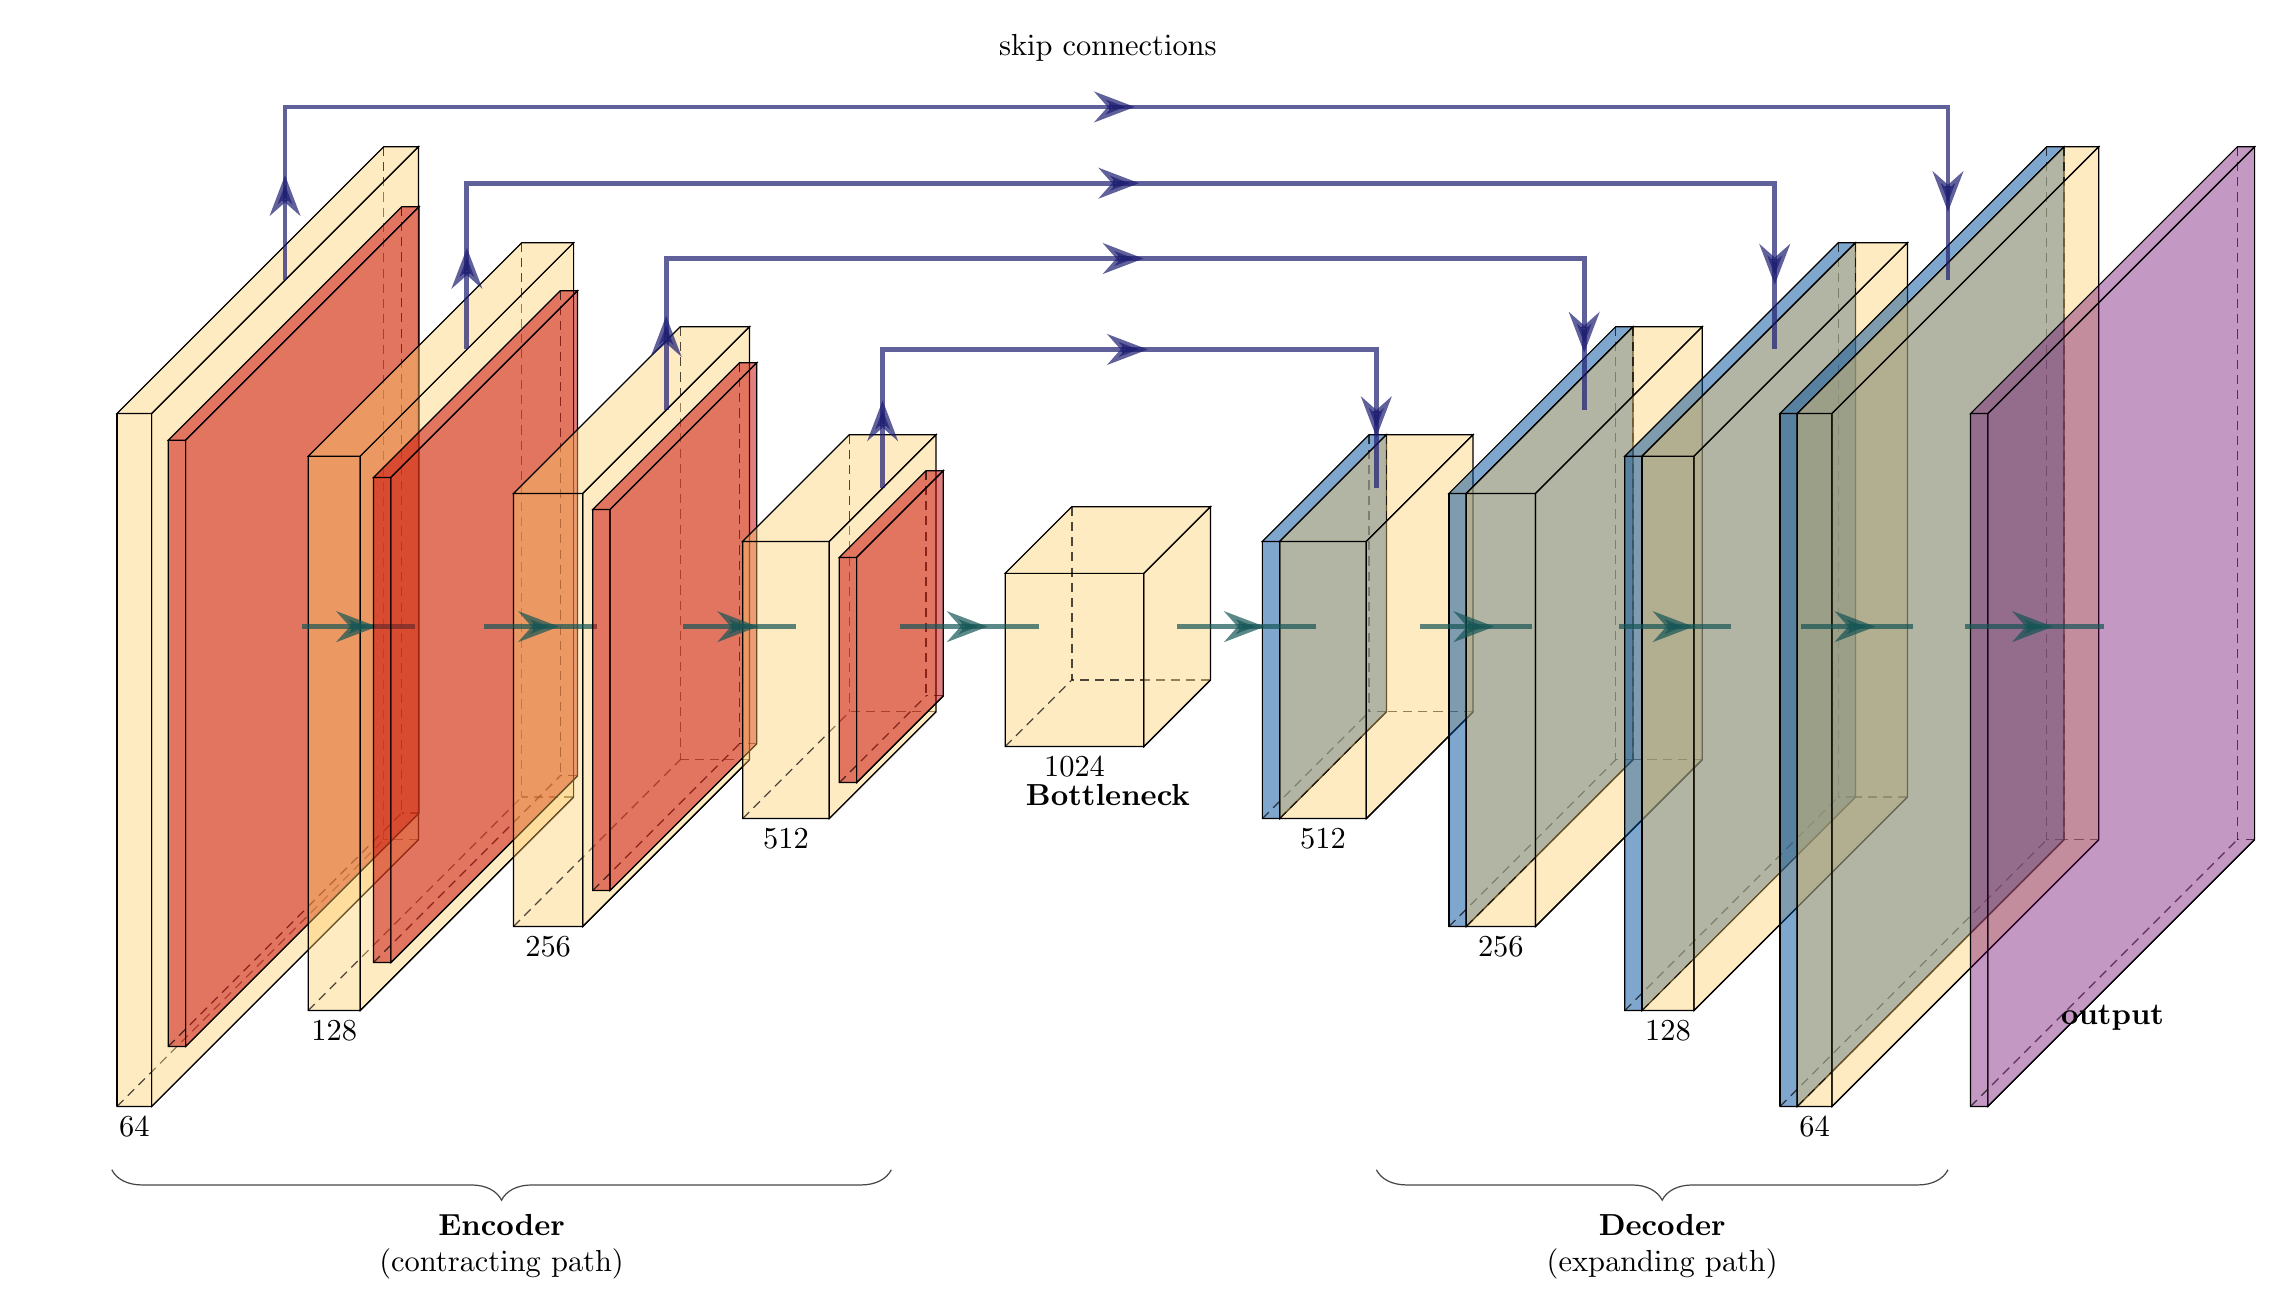
The denoiser and the transformer it is built from, the residual variant, the per-pixel uncertainties and their conformal calibration, and the implementation.
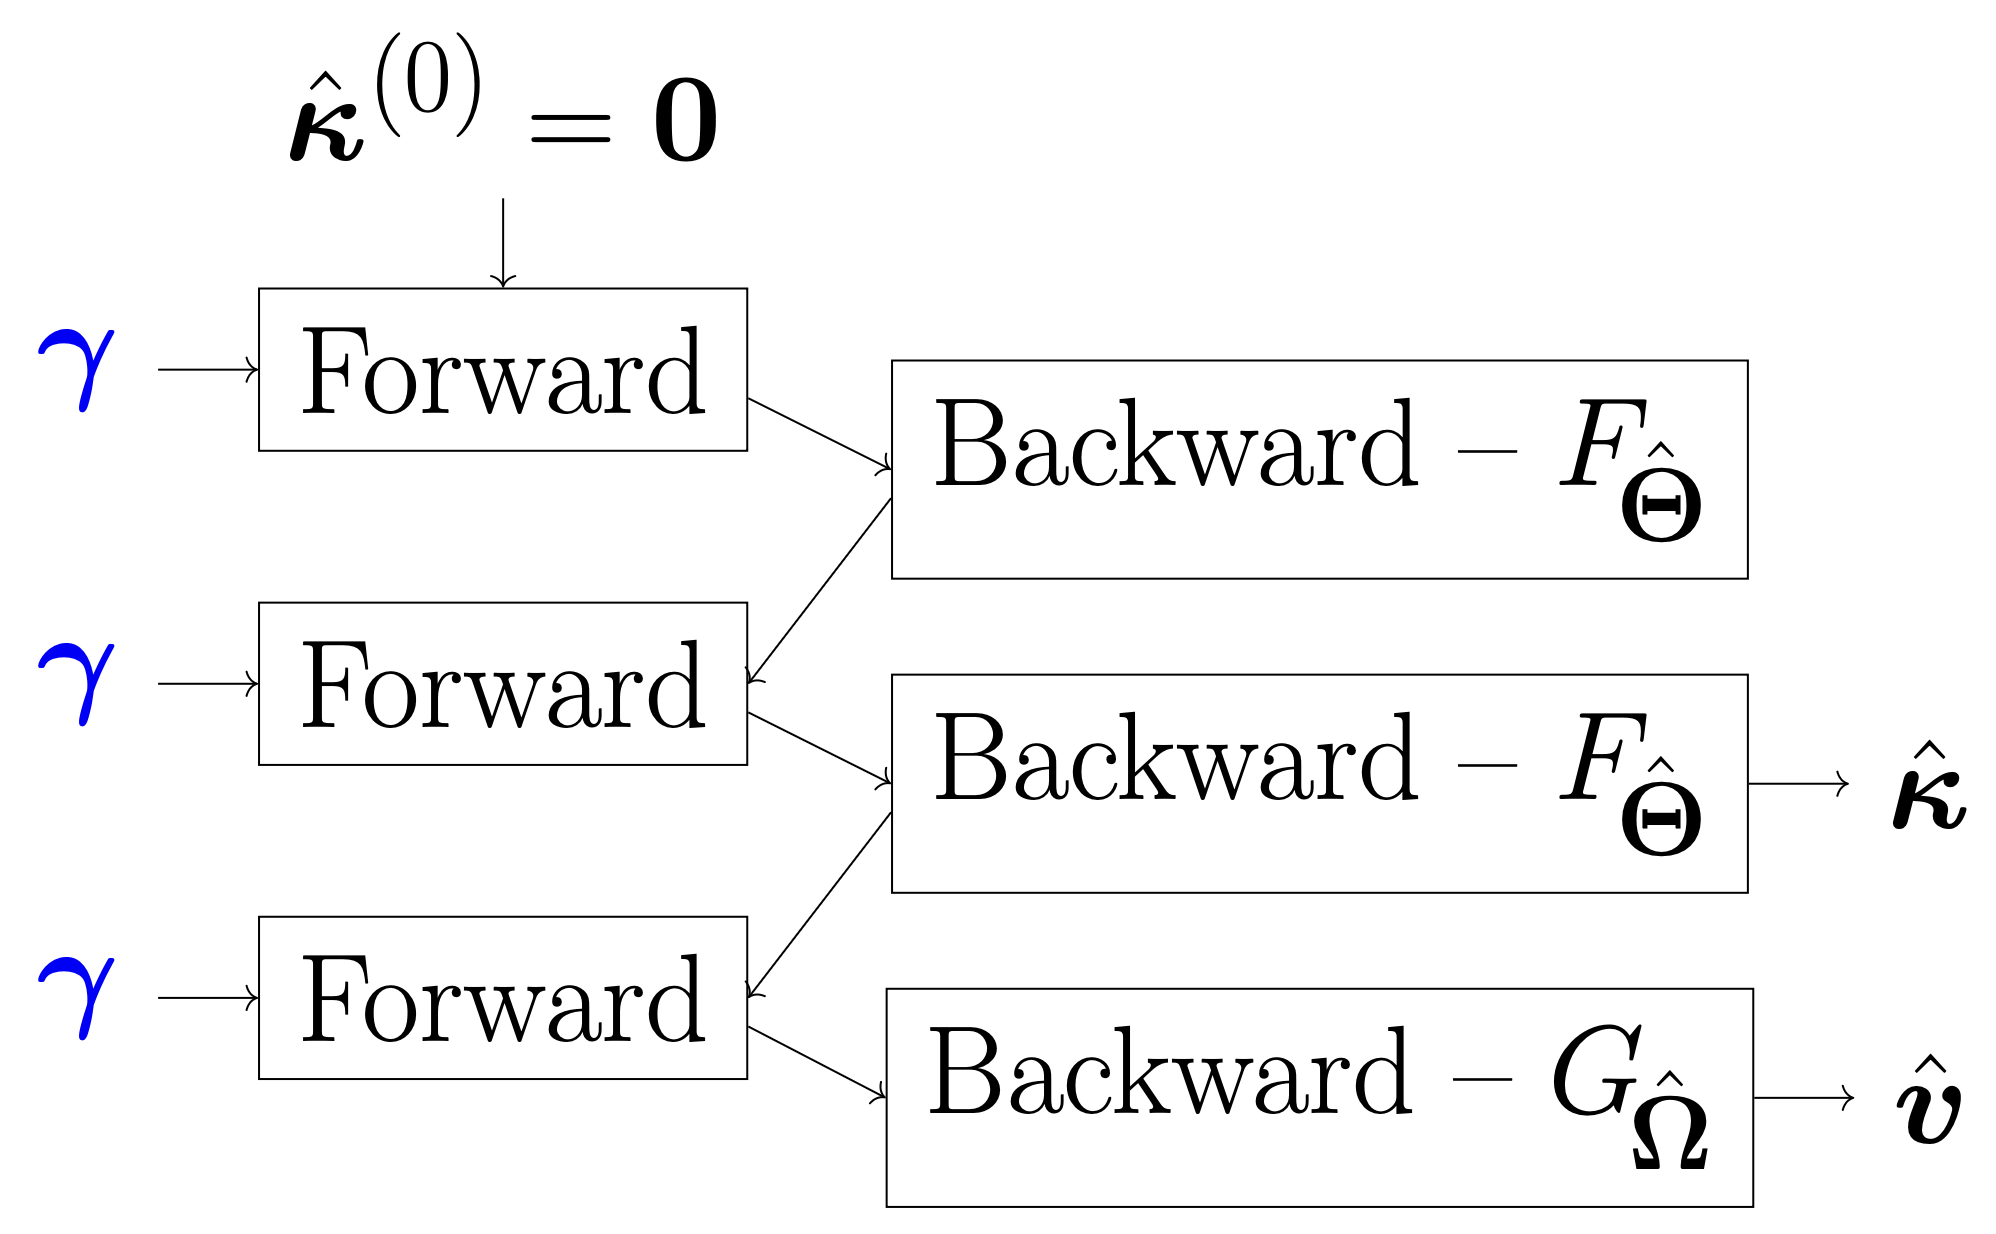
The forward step carries the physics. The denoiser only has to know what a plausible convergence field looks like.
SUNet: a U-Net whose blocks are Swin-Transformer blocks rather than convolutions, with 7.2 M parameters. The noise level σ goes in as an extra input channel, so one model covers a range of noise instead of one level.
Take a simulated κ, add white Gaussian noise, ask for the κ back.
$$\hat\theta \;=\; \arg\min_{\theta}\; \frac{1}{n} \sum_i \big\lVert D_{\theta}\big(\kappa_i + n_i\big) - \kappa_i \big\rVert^2$$
σ is drawn uniformly over 0 to 0.2. No shear, no mask and no survey enter the training set.
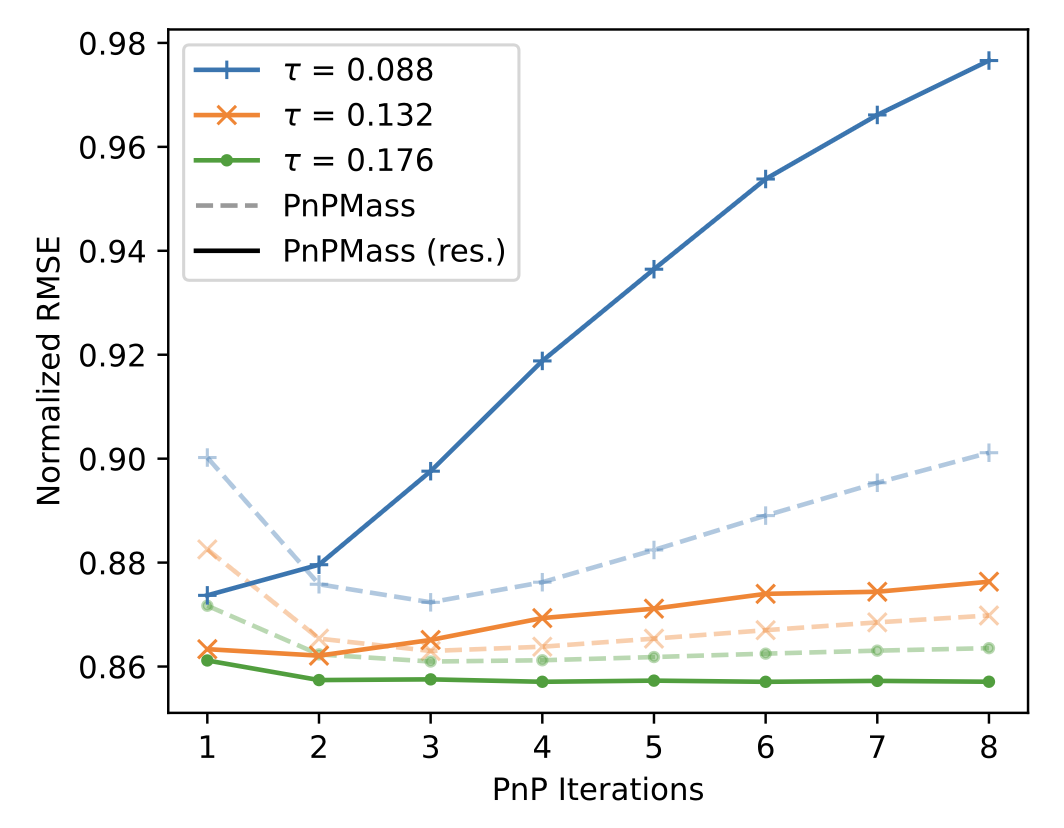
The forward step may use any linear operator. PnPMass takes $\mathbf{B} = \mathbf{A}^{\!\top}\Sigma^{-1/2}$, which whitens the residual before adding it back. The denoiser then sees κ plus white noise of width $\tau$, whatever mask and galaxy density went into $\Sigma$. A MAP step would use $\Sigma^{-1}$, and the noise would arrive coloured.
Leterme, Tersenov, Fadili & Starck 2026, A&A 710, A292
What survives is the scalar $\tau$, whose usable range depends on $\Sigma$. DeepMass needs the full covariance, and a retraining for every footprint.
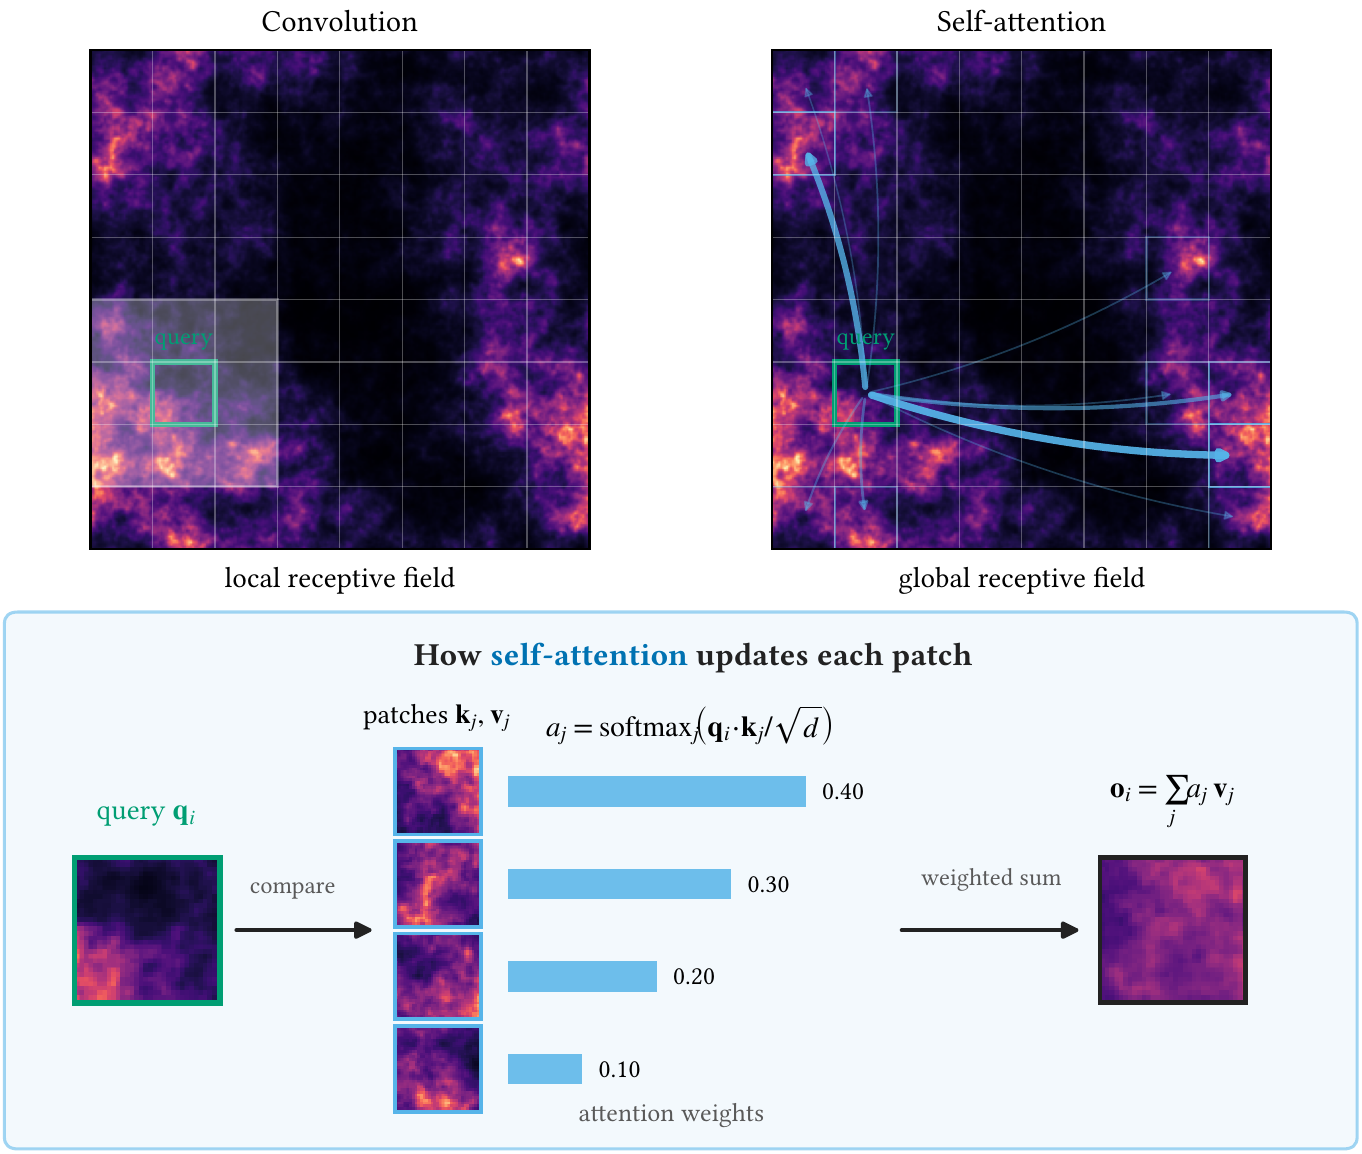
Cut the map into patches. Compare one patch with all the others, turn the comparisons into weights, and replace it with the weighted average of the rest.
The weights come from the content of the patches, not from where they sit, so the network learns which distant regions belong together. A convolution can only ever look at a fixed neighbourhood.
Comparing every pair costs time growing as the square of the number of patches. The Swin variant keeps attention inside local windows that shift between layers, so global reach is rebuilt over several layers.
Vaswani et al. 2017 · Liu et al. 2021
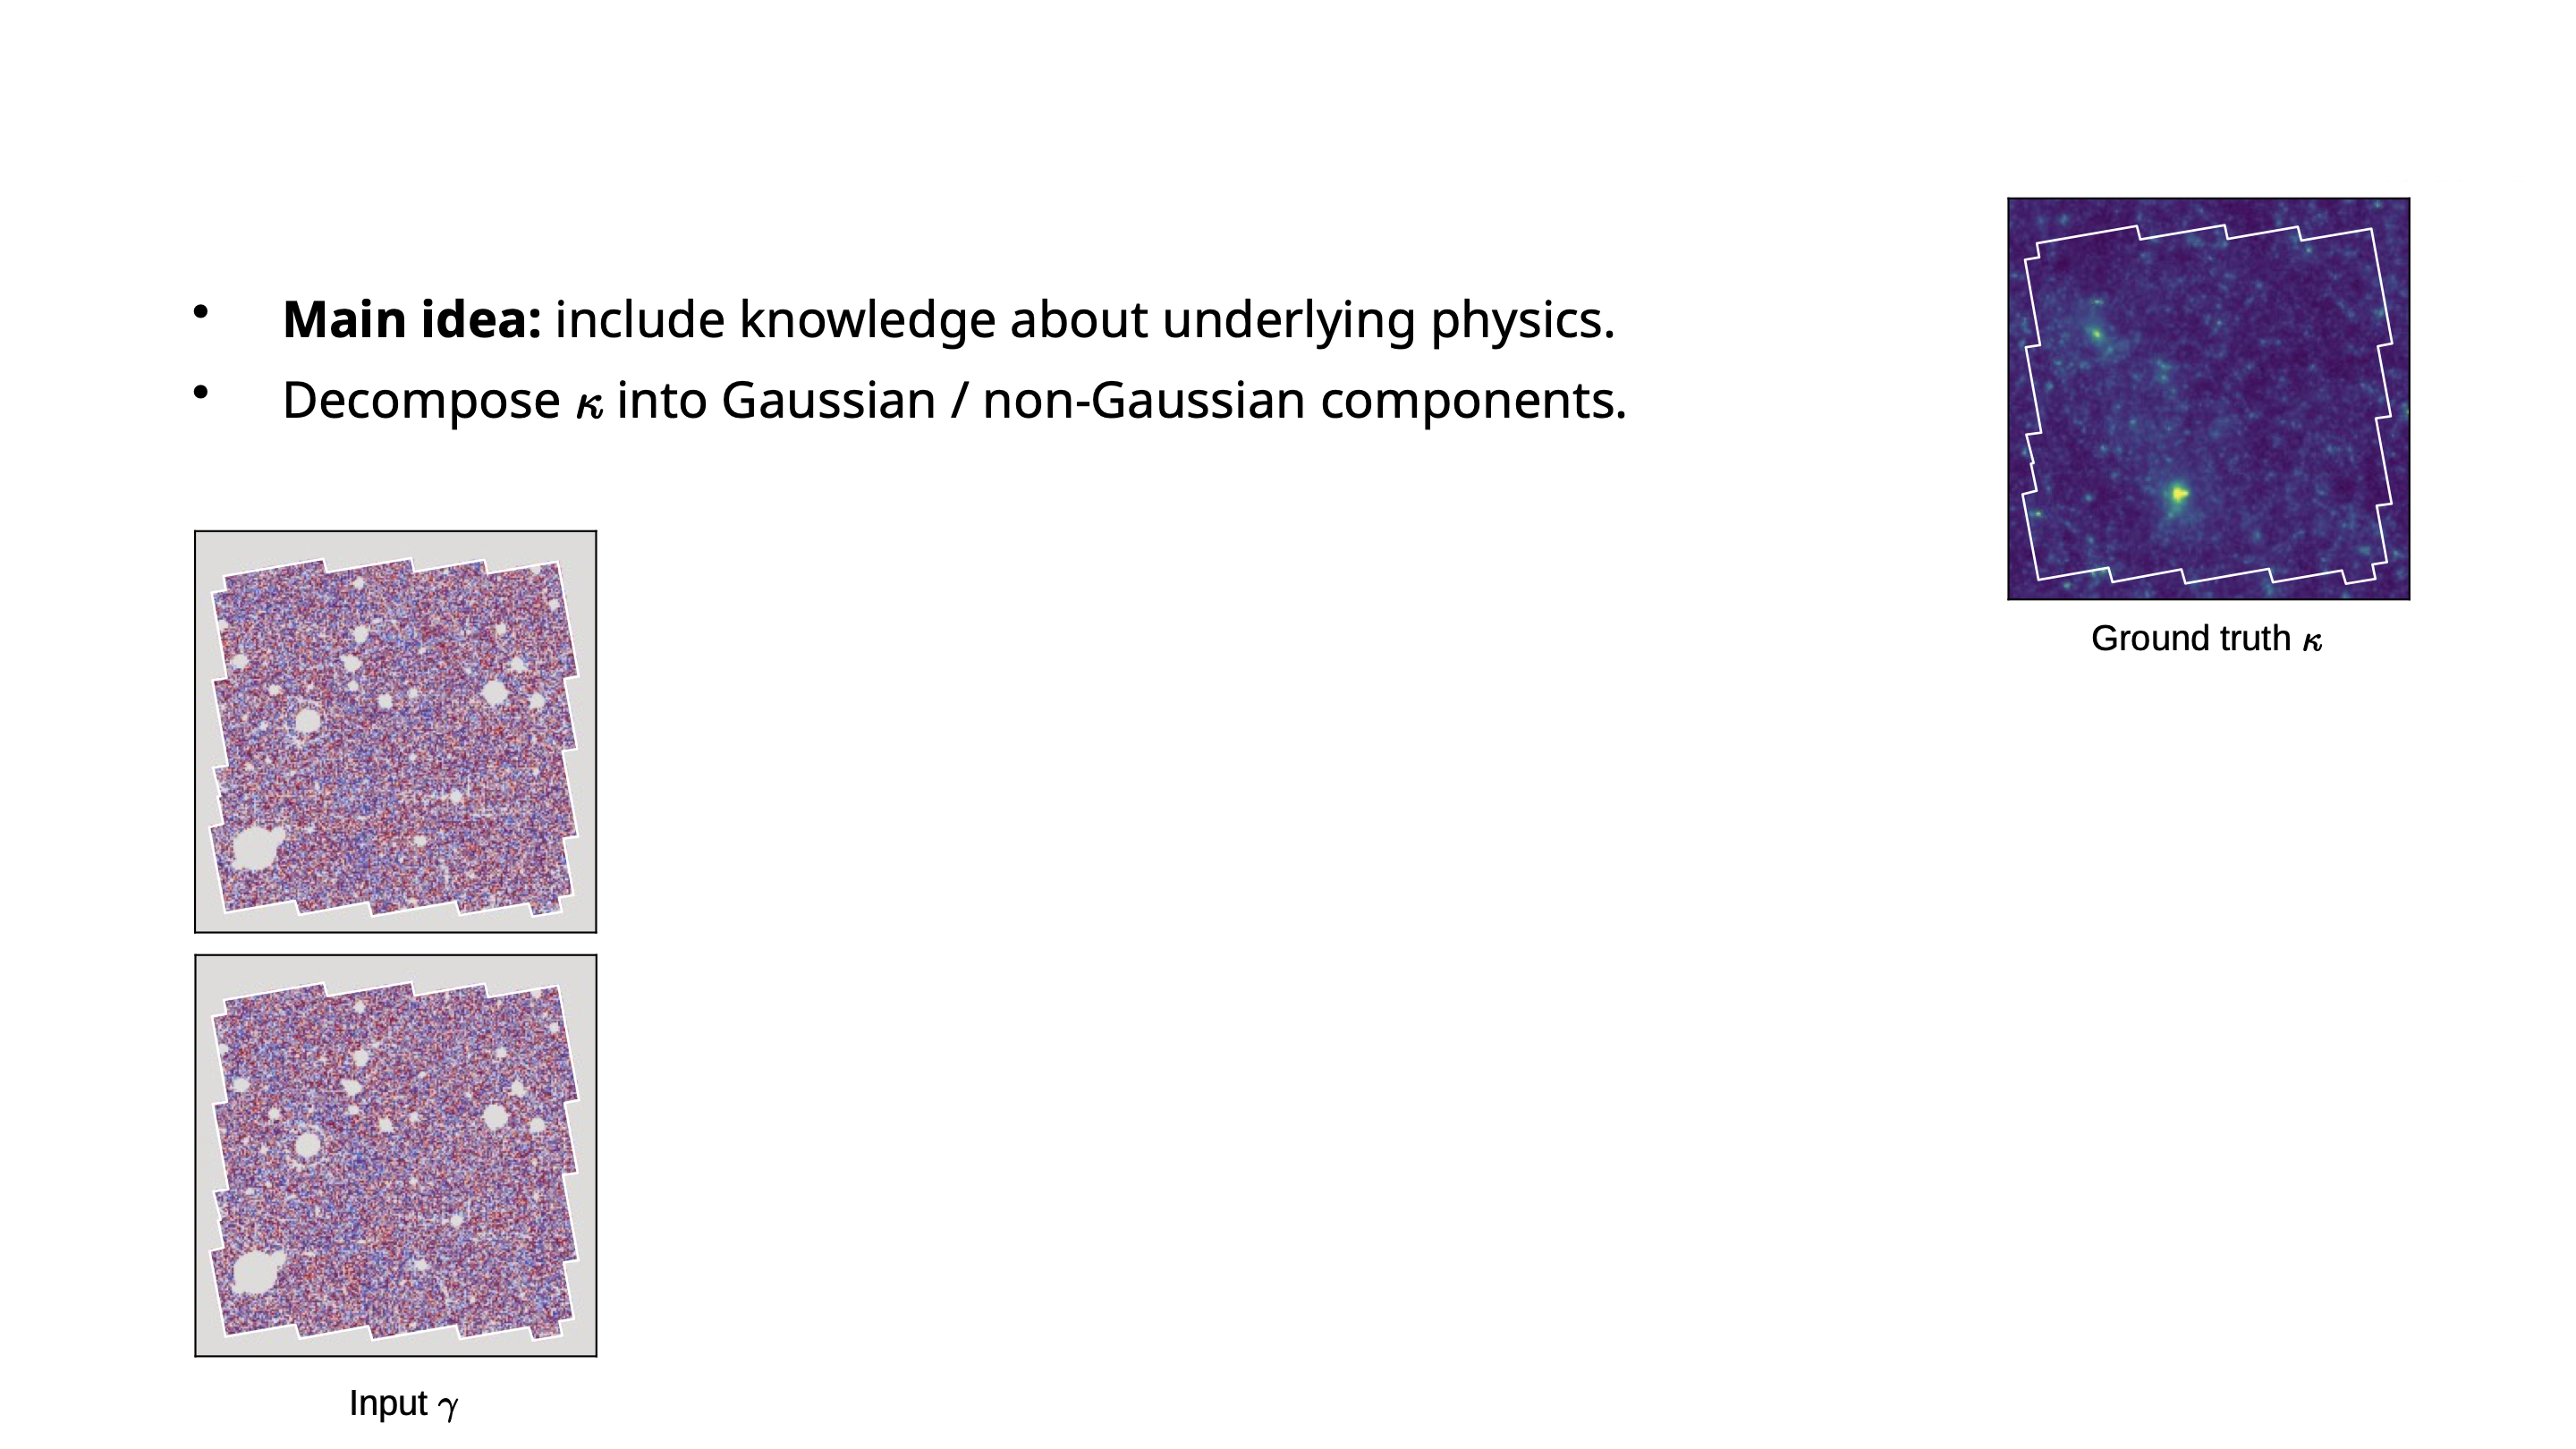
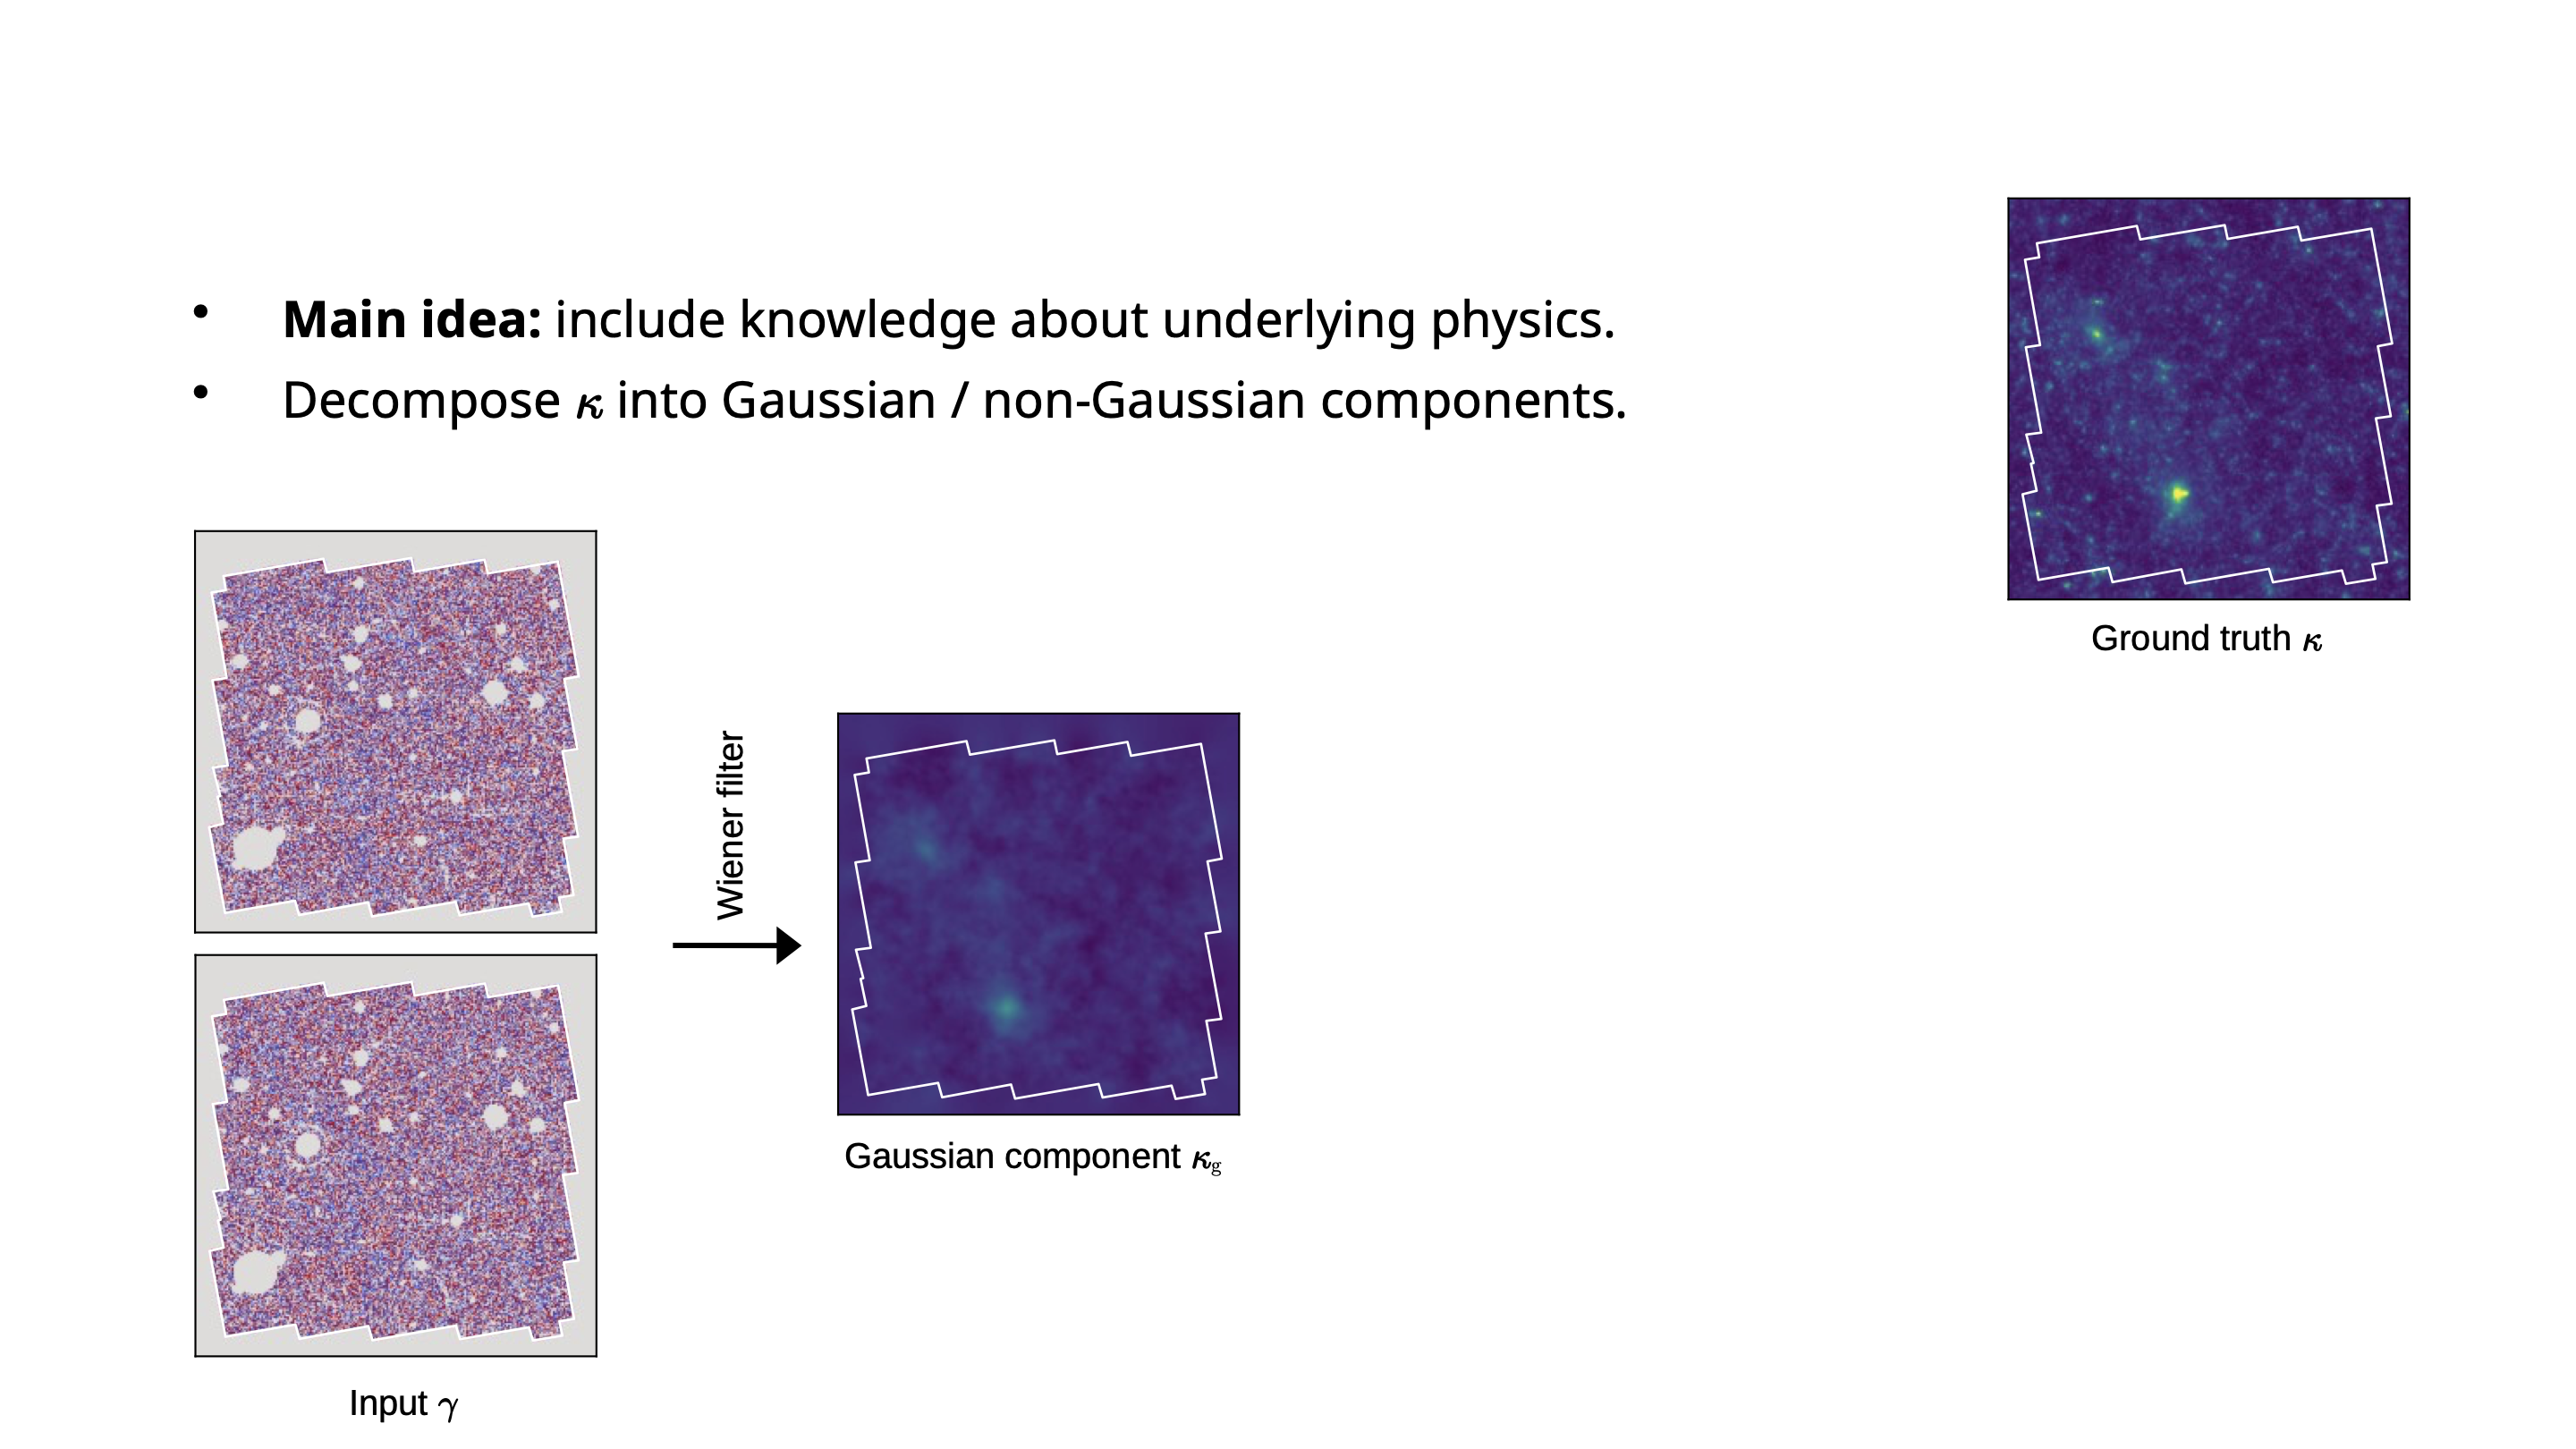
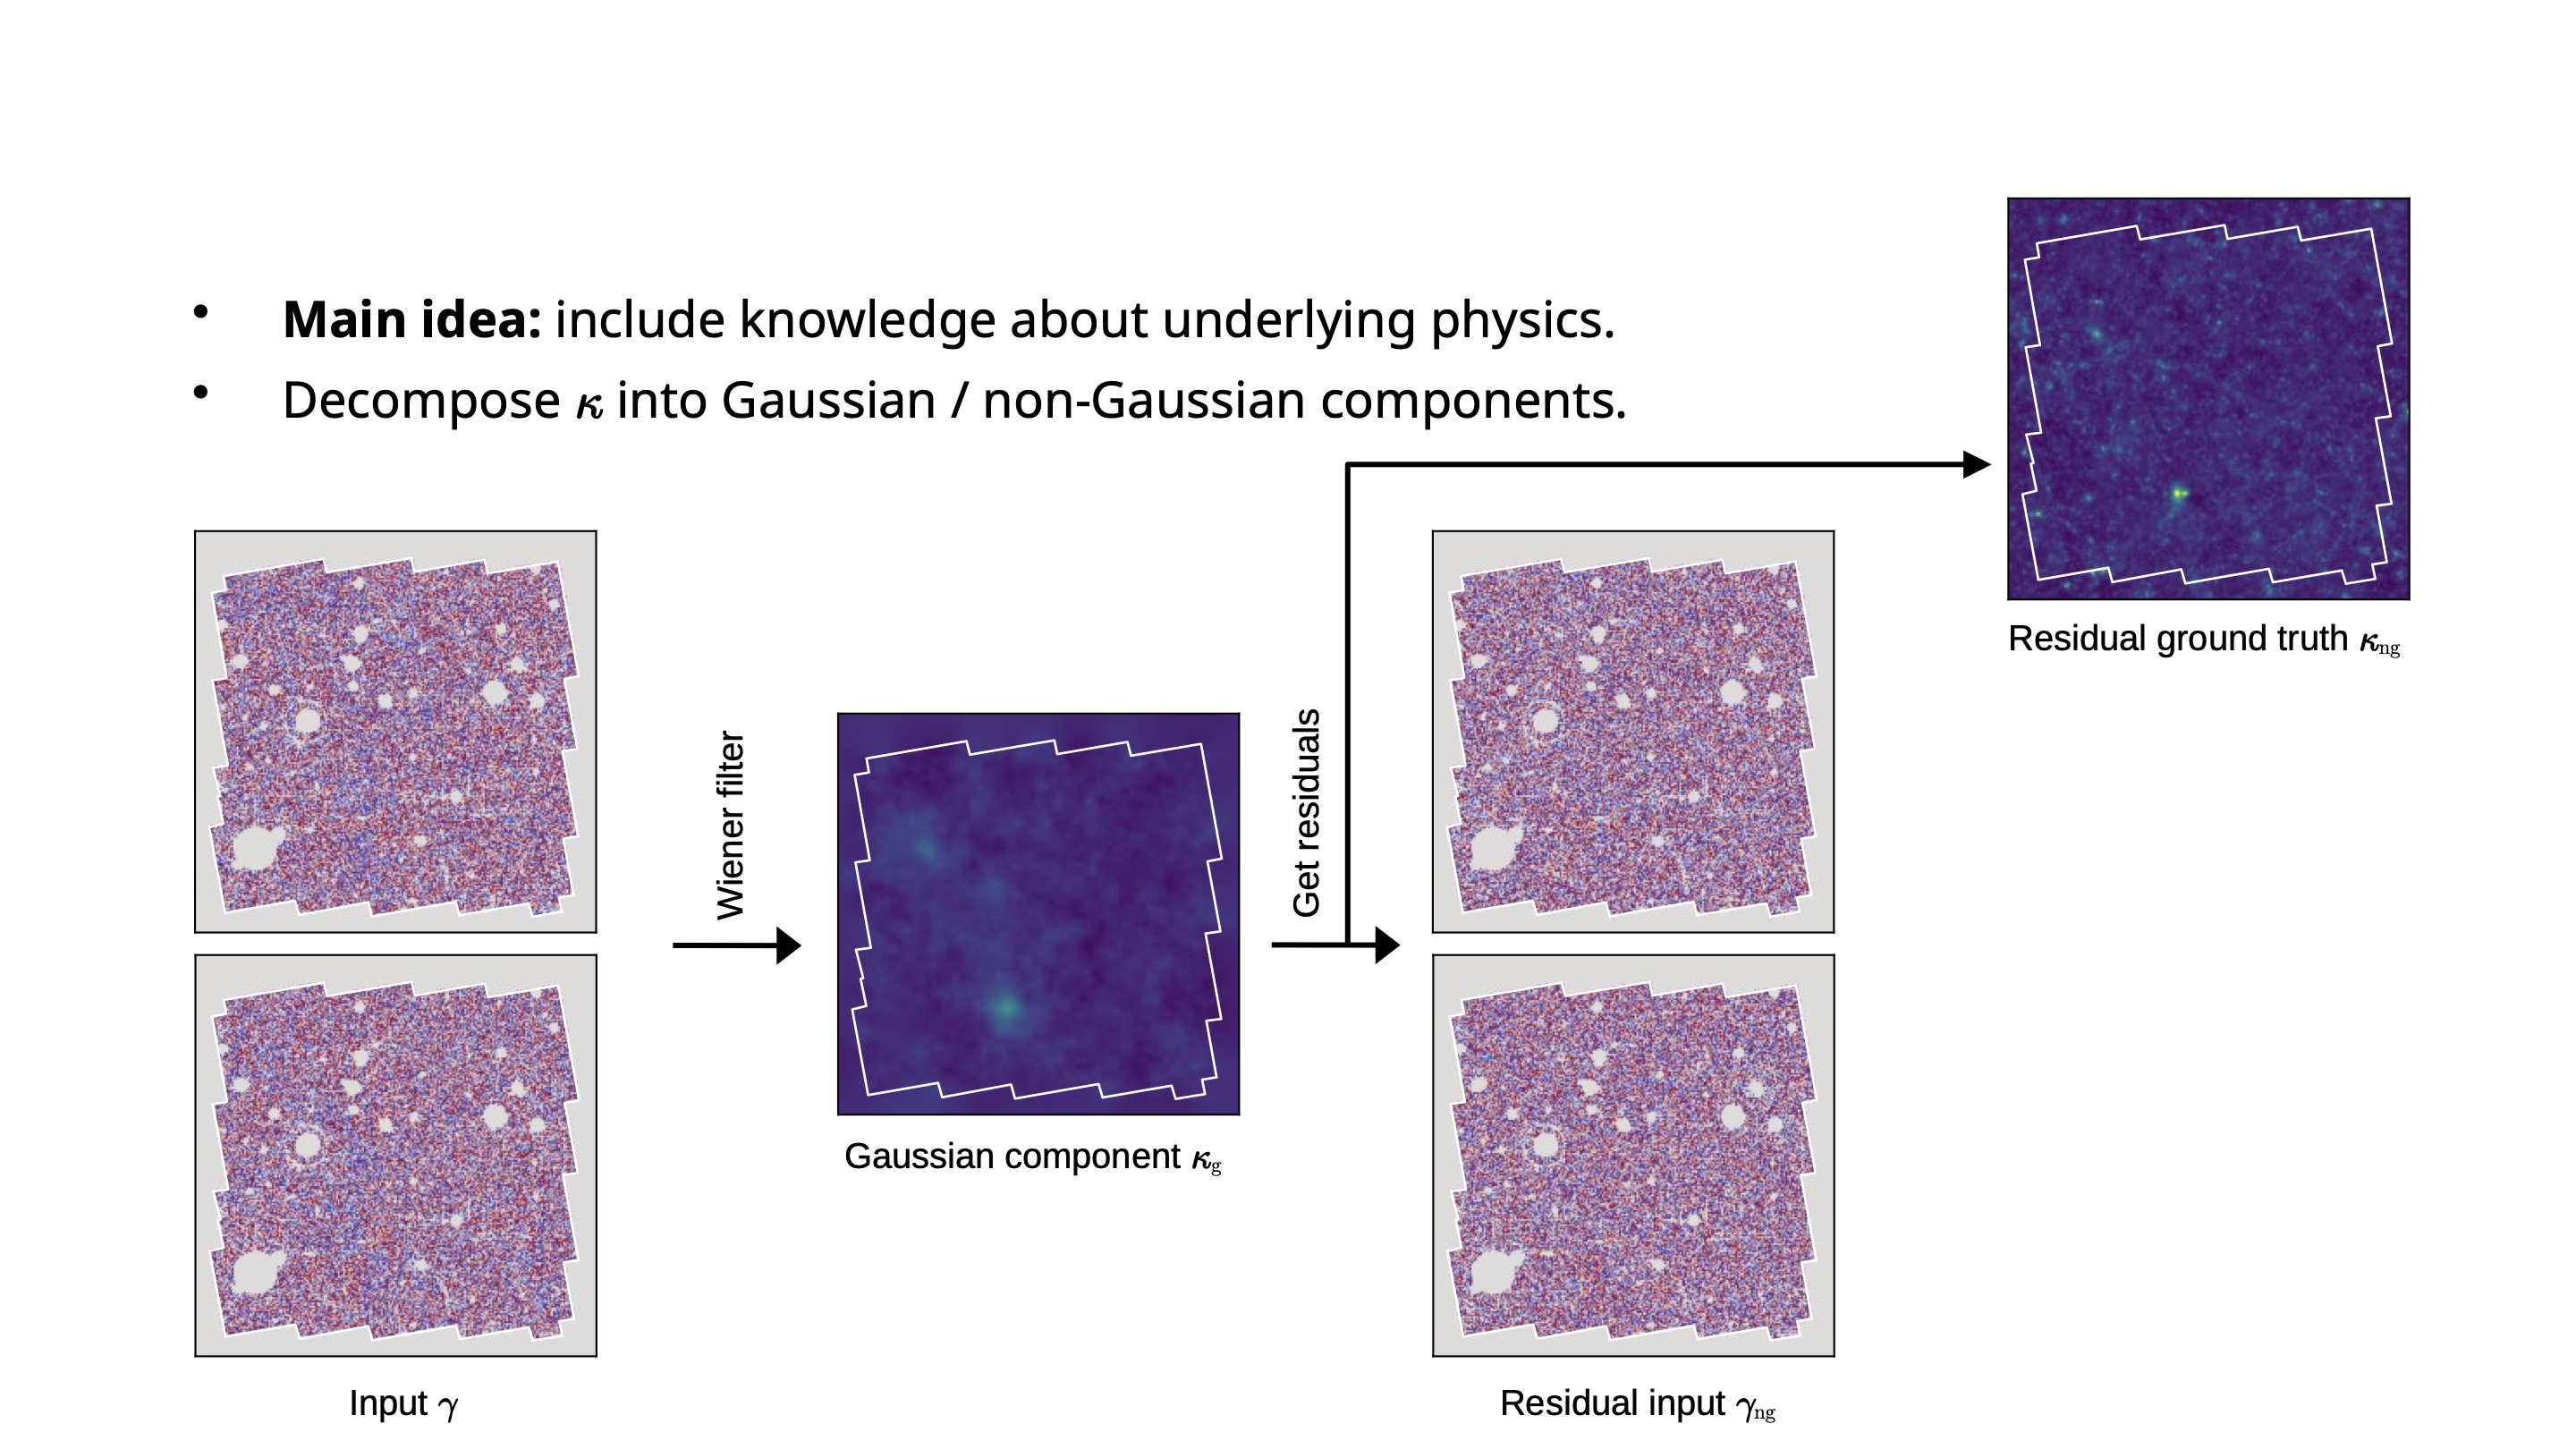
where the spread comes from The posterior spread comes from the noise and the mask (Part 1), and from the learned prior that selects one map. The predicted variance has to account for both.
first — predict the error
Train $G_{\Omega}$ on the squared residual of the reconstruction,
$$\min_{\Omega}\ \mathbb{E}\left[\left\| G_{\Omega}(\gamma) - \big(\kappa - F_{\Theta}(\gamma)\big)^{2} \right\|_2^{2}\right]$$
whose minimiser is the posterior variance, pixel by pixel. One forward pass, no sampling.
then — calibrate it
The variance predicted by a network is not calibrated.
Conformal quantile regression rescales it pixel by pixel on a held‑out calibration set, so that the intervals reach the target coverage.
The result is a coverage guarantee that holds whether or not the network is well specified.
A network's error bar comes out the wrong size, and nothing tells you by how much. This is how you fix it.
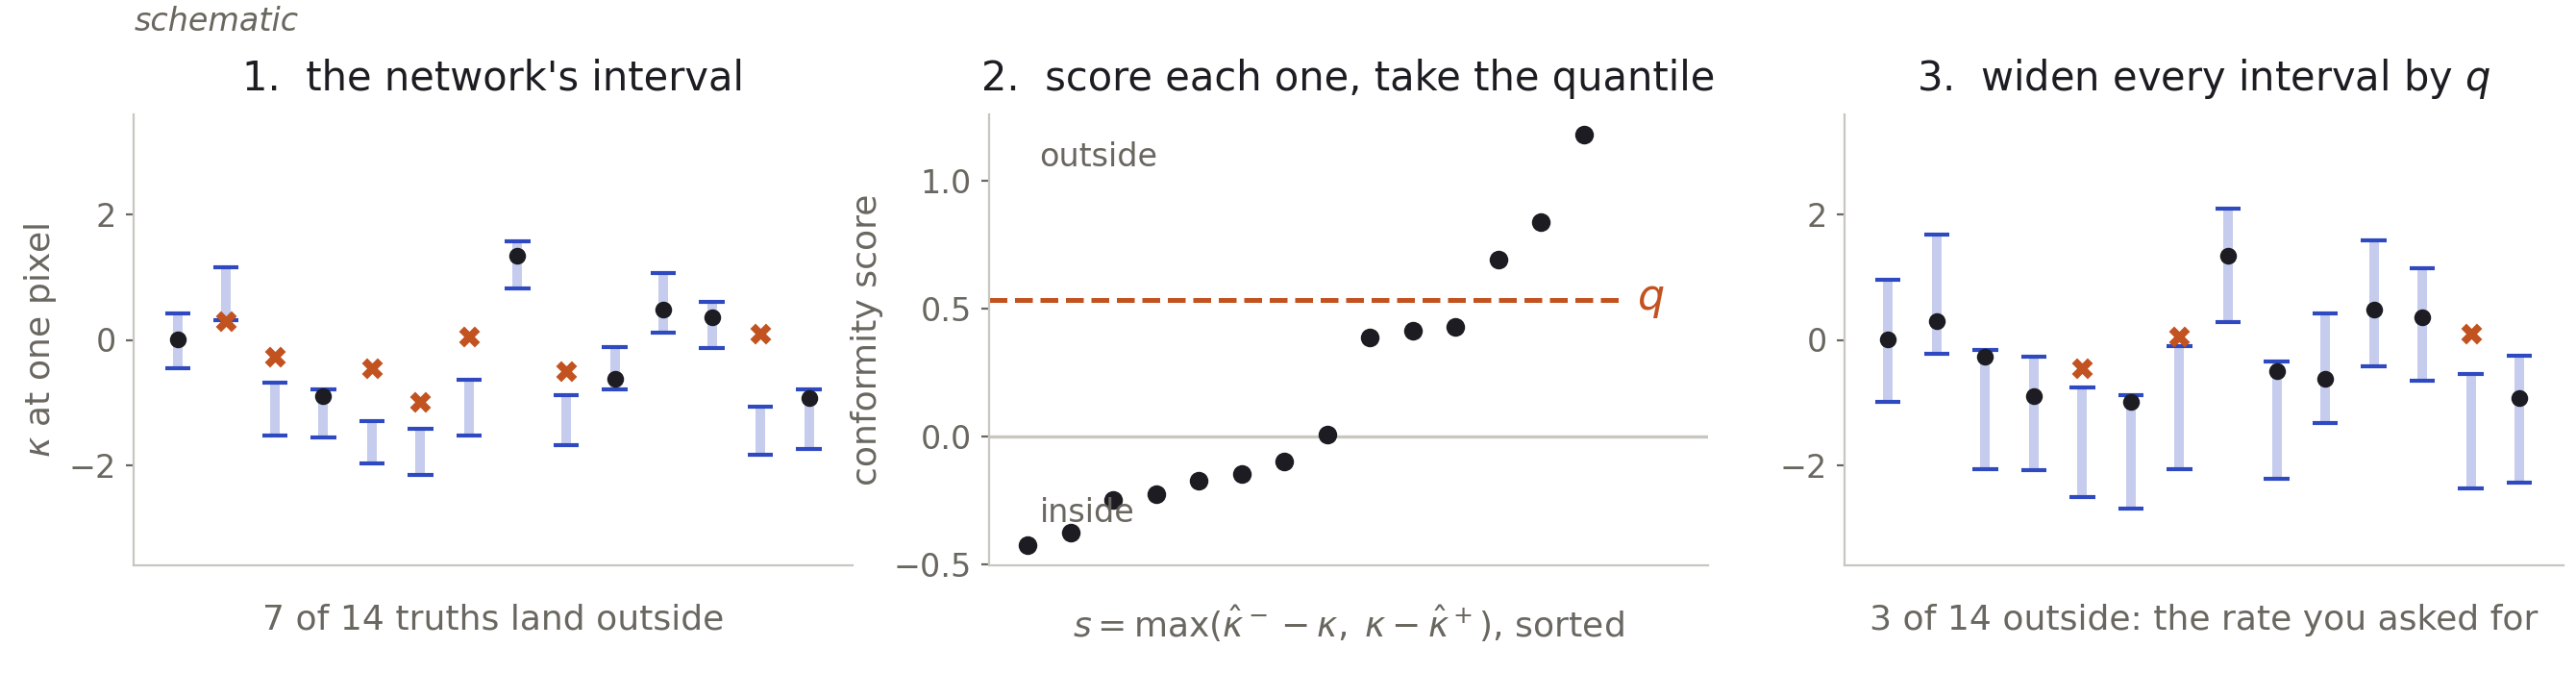
$$\alpha - \tfrac{1}{n+1} \;\le\; \mathbb{P}\big\{\kappa \notin [\hat\kappa^-,\, \hat\kappa^+]\big\} \;\le\; \alpha$$
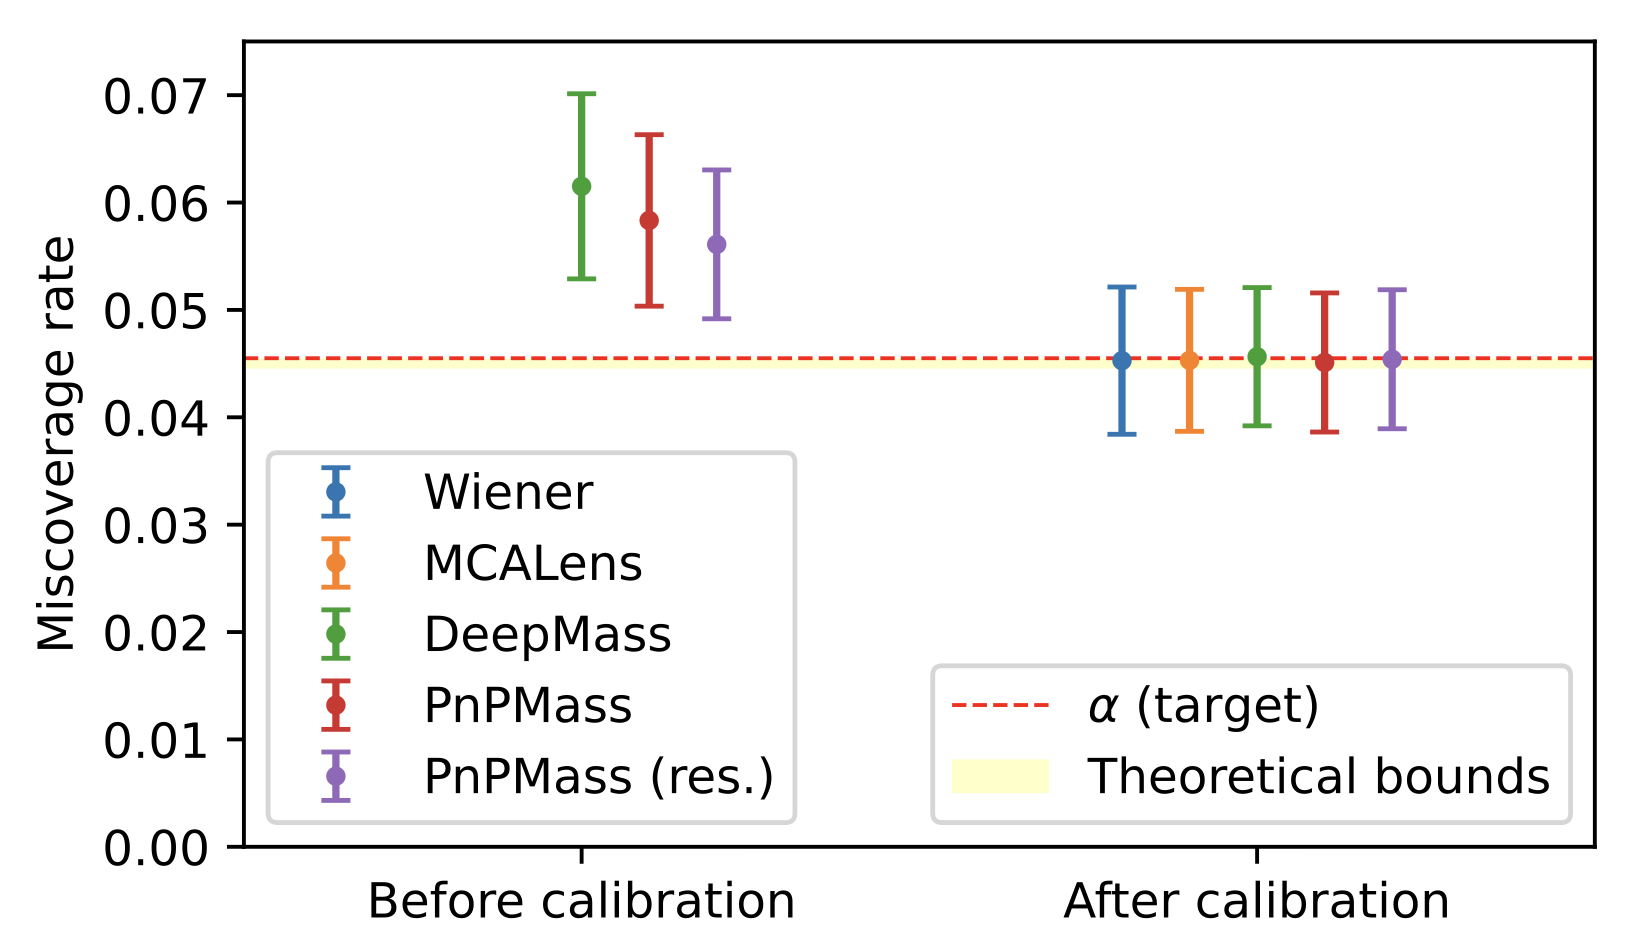
That fraction falls outside, whatever produced the bar. The calibration set can be small, nothing has to be Gaussian, and the network does not have to be right. The one condition is exchangeability: calibration maps and real data drawn on equal terms.
The guarantee is marginal: an average over many maps, not a promise about the one in front of you. Some regions do worse than the average, and peaks are the known case — the Wiener bars miss there systematically even after calibration.
Here: $2\sigma$, so $\alpha \approx 4.55\%$, from 1024 calibration maps. The correction sets a minimum size for that set: 21 maps at $2\sigma$, 370 at $3\sigma$, 15 787 at $4\sigma$.
Romano et al. 2019 · Leterme, Tersenov, Fadili & Starck 2026
Kaiser–Squires step by step, the Bayesian reconstruction stack, sparse recovery, the MCALens algebra, and the PnPMass implementation. Here for questions.
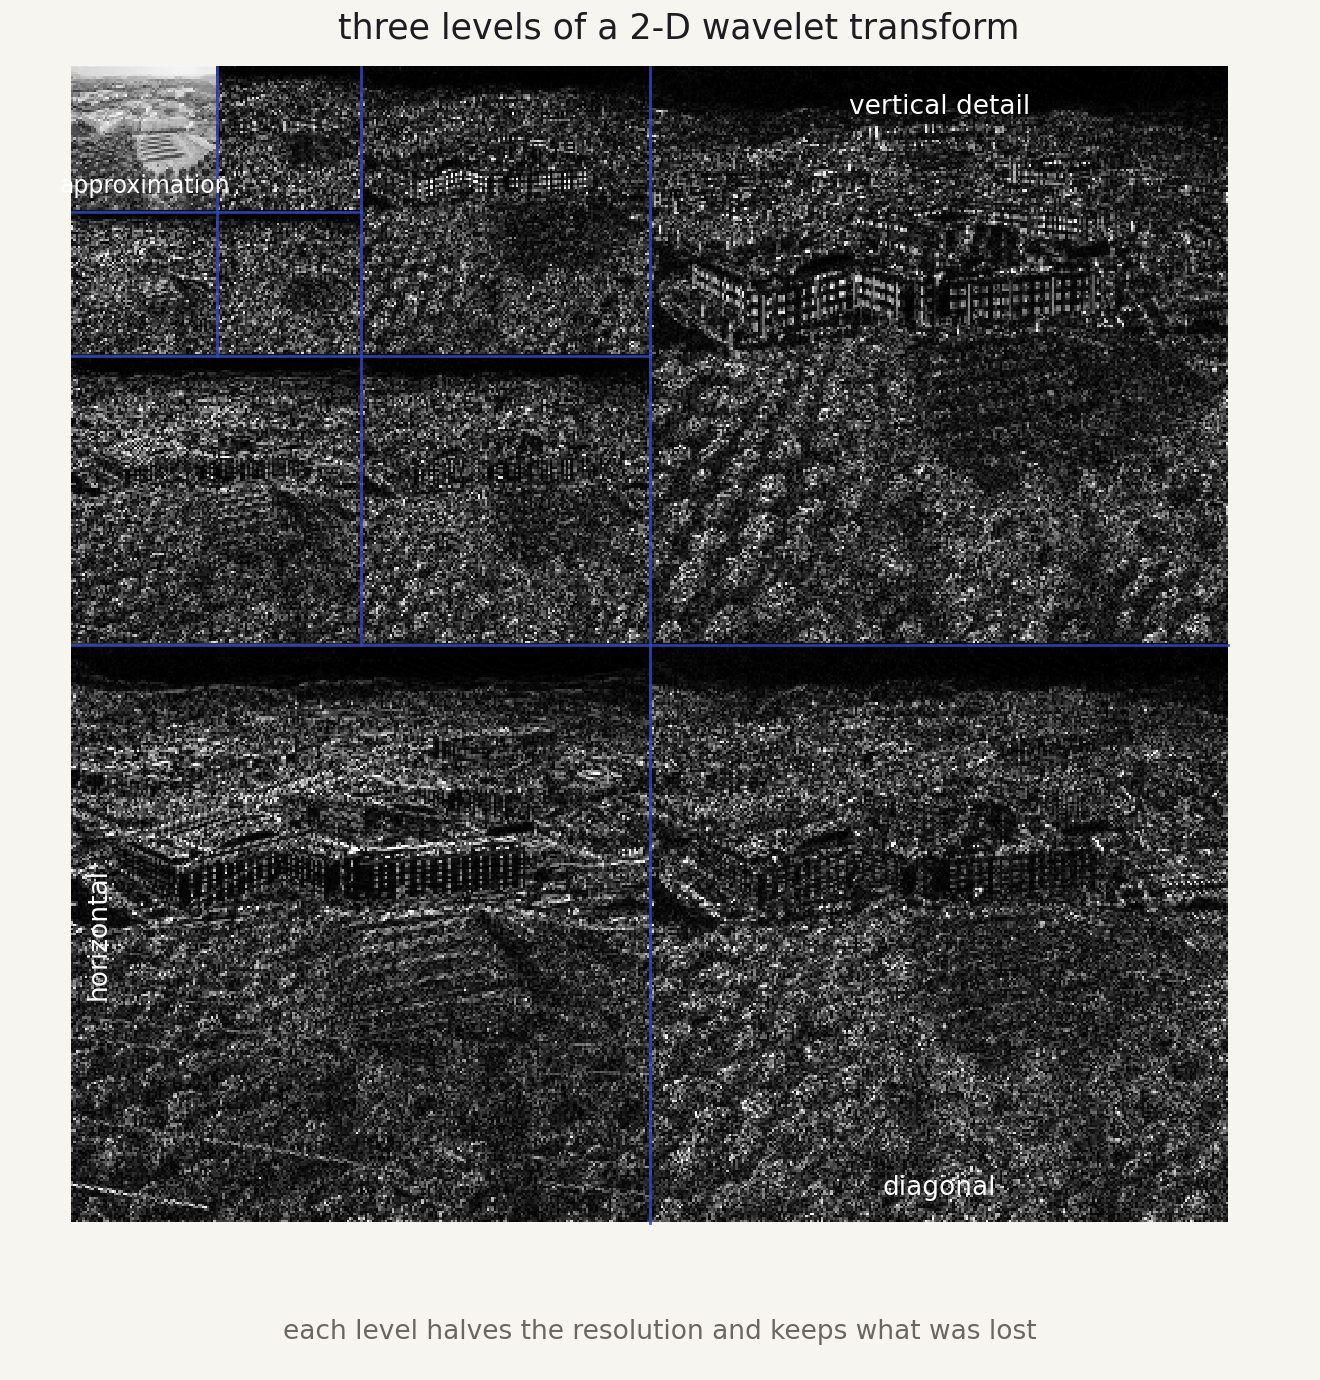
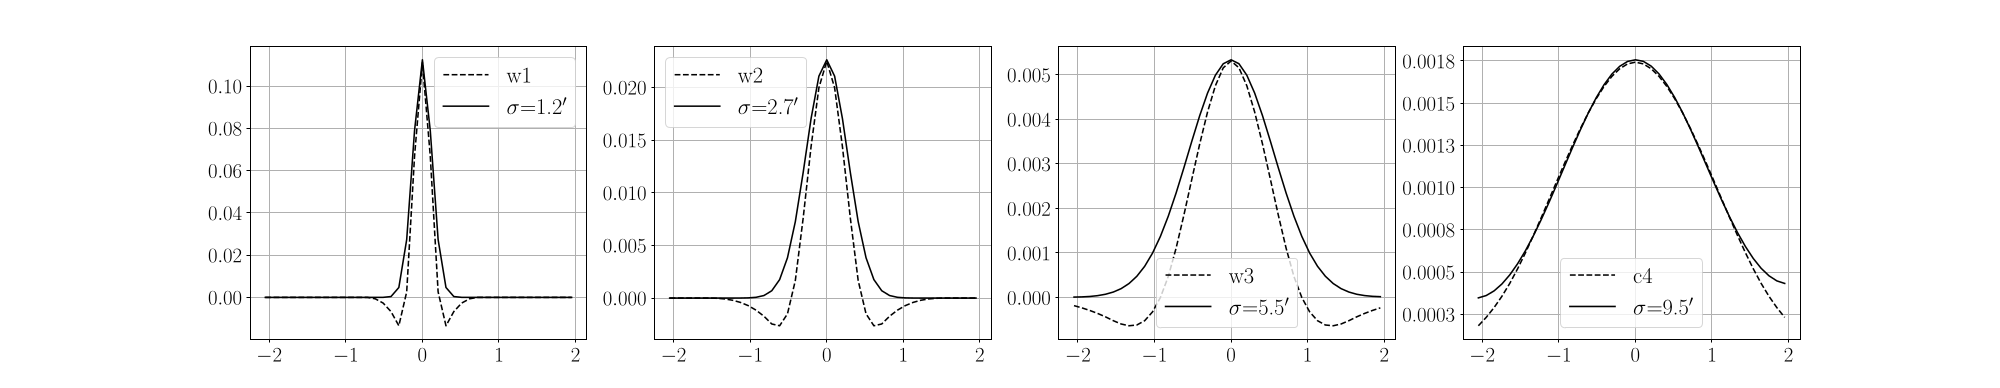
In two dimensions each level splits into vertical, horizontal and diagonal details, and recurses on what is left.
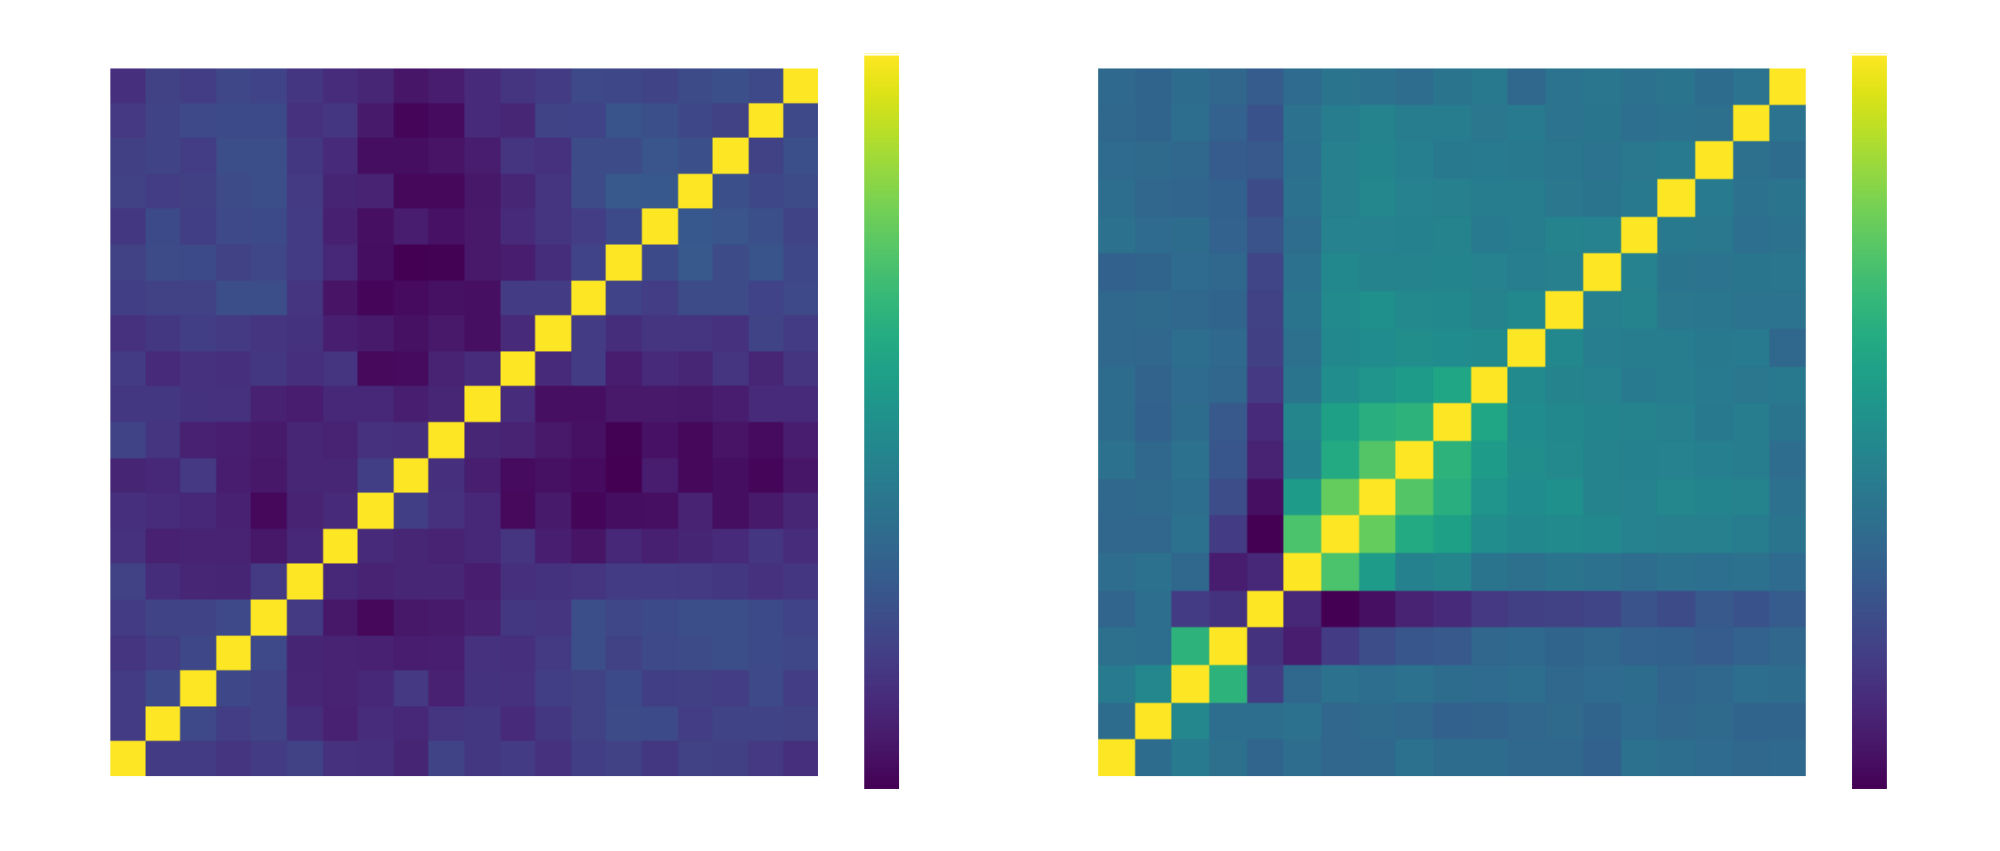
The bands are band-passes and adjacent ones overlap in multipole, so the covariance comes out nearly diagonal rather than diagonal.
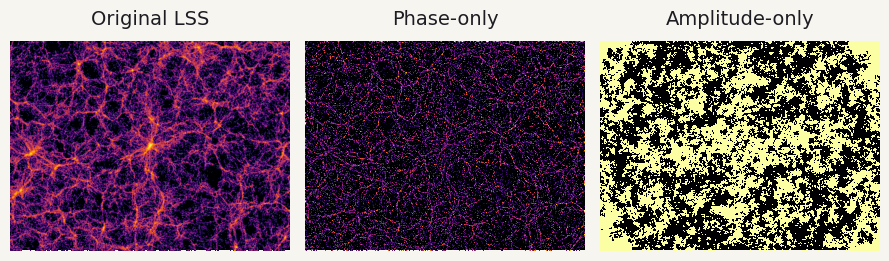
A peak is a local maximum of $\nu = \dfrac{\left(\mathcal{W} \ast \kappa\right)(\theta_{\rm ker})}{\sigma_n^{\rm filt}}$ , the signal-to-noise field of the filtered map.
$$\ell_1^{j,i} = \sum_{u=1}^{\textrm{\# coef}(\mathcal{S}_{i,j})} \left| \mathcal{S}_{j,i}[u] \right| = \| \mathcal{S}_{j,i} \|_1$$
$$\delta = \frac{\rho - \bar\rho}{\bar\rho}, \qquad \delta \ge -1 \;\; (\rho \to 0), \qquad \delta \to +\infty \;\; (\rho \gg \bar\rho)$$
→ $\ell_1$ maximizes cosmological signal-to-noise on non-Gaussian structure.
Ajani, Starck & Pettorino 2021, the paper that defines the starlet ℓ1‑norm.
Bin edges are still a choice in both cases, and our derivatives with respect to cosmology are finite differences on simulations either way.
Which makes it a measurement rather than an argument. The coverage card in Part 2 is the answer.
| comoving size [$h^{-1}$Mpc] | |||
|---|---|---|---|
| angular scale | $z=0.1$ | $z=0.3$ | $z=0.6$ |
| 1′ | 0.09 | 0.25 | 0.46 |
| 10′ | 0.9 | 2.4 | 4.6 |
| 20′ | 1.7 | 4.9 | 9.1 |
| 1° | 5.1 | 15 | 27 |
| structure | |||
| galaxy halo | 0.1 – 0.3 | ||
| cluster, $R_{200}$ | 1 – 2 | ||
| $\sigma_8$ sphere, non-linear scale | 8 | ||
| linear regime | ≳ 63 | ||
| BAO, sound horizon $r_d$ | 99 | ||
Comoving, for $\Omega_m = 0.26$, $h = 0.674$. The BAO sound horizon is 147 Mpc, which is the 99 above once divided by $h$.
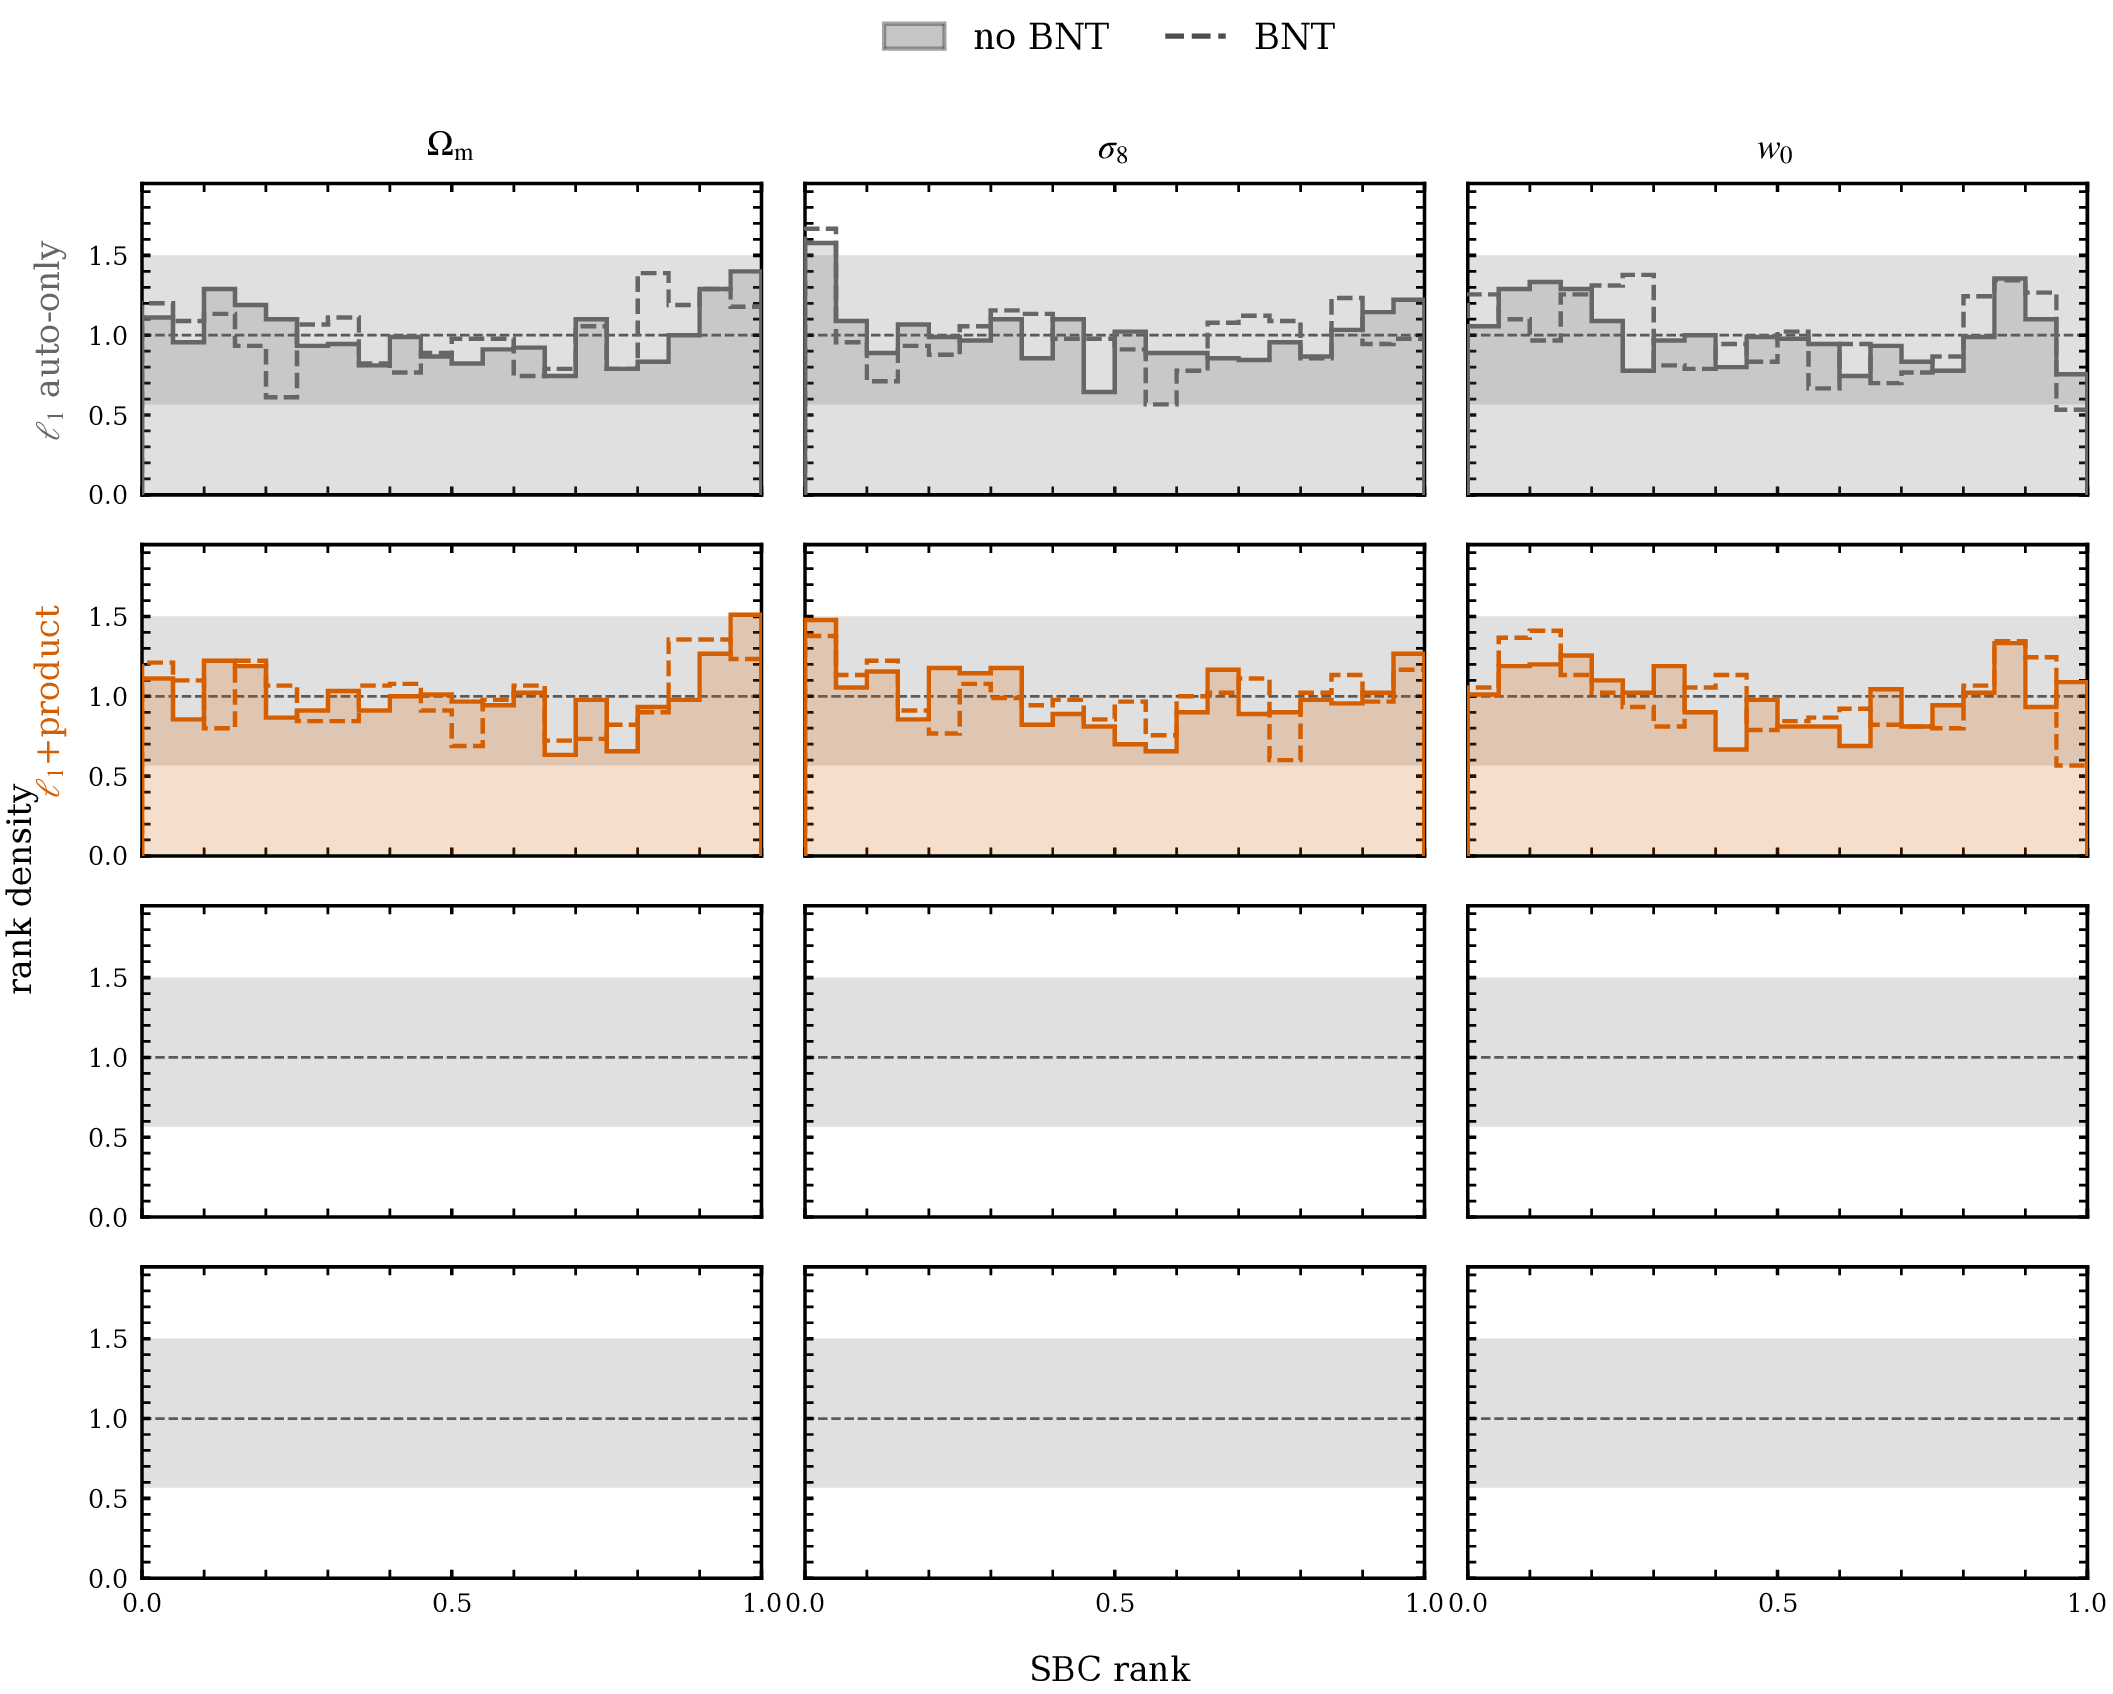
The analytical ℓ1-norm vs a learned CNN, calibration, and the answer to the BNT puzzle.
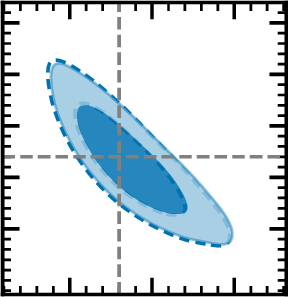
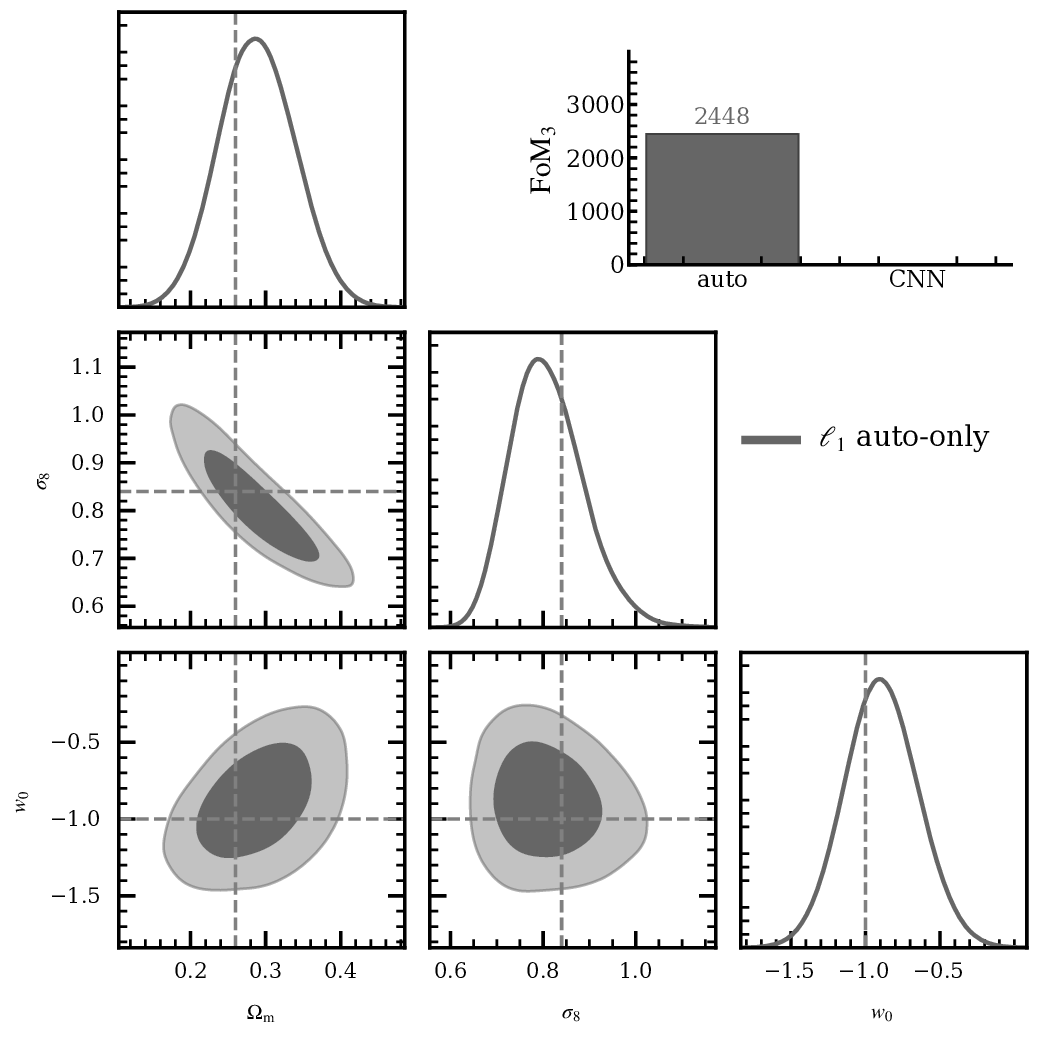
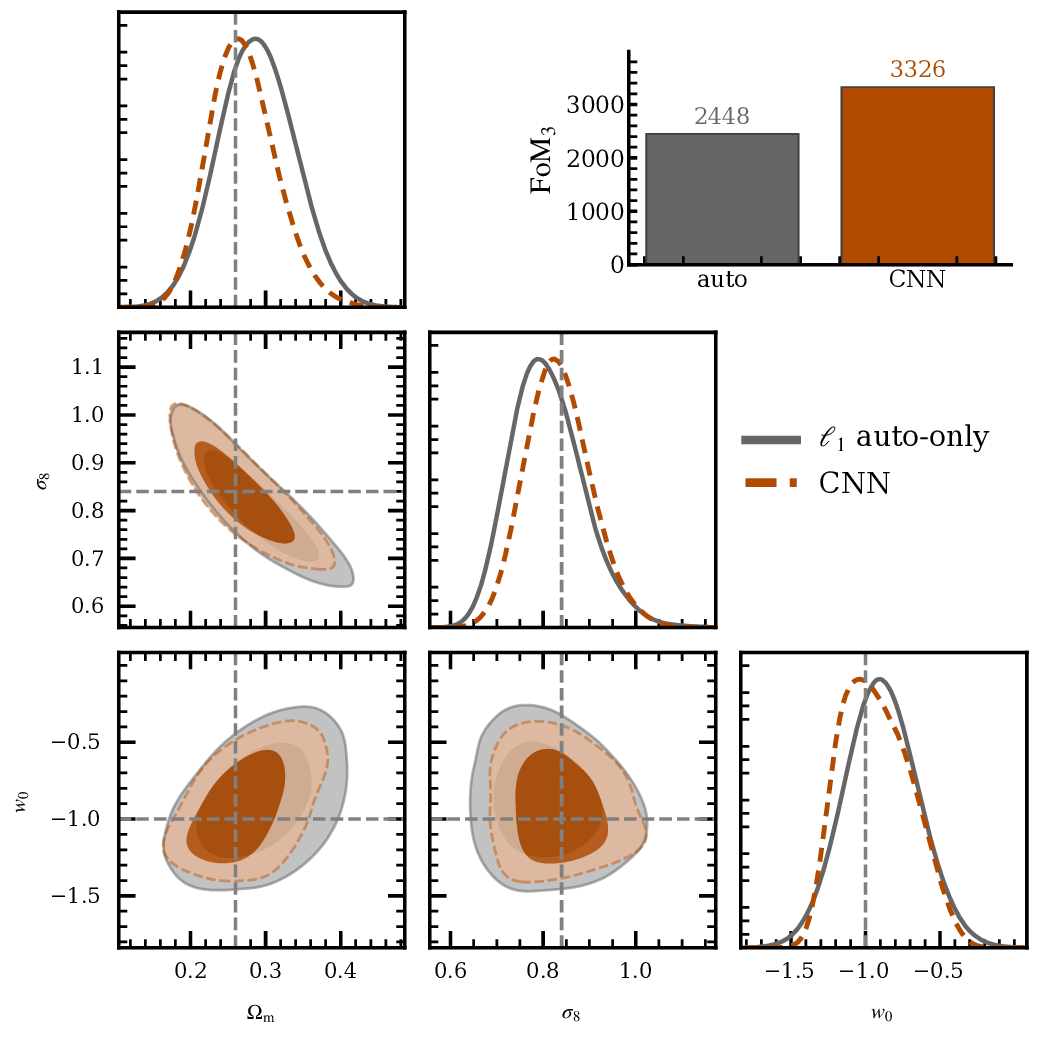
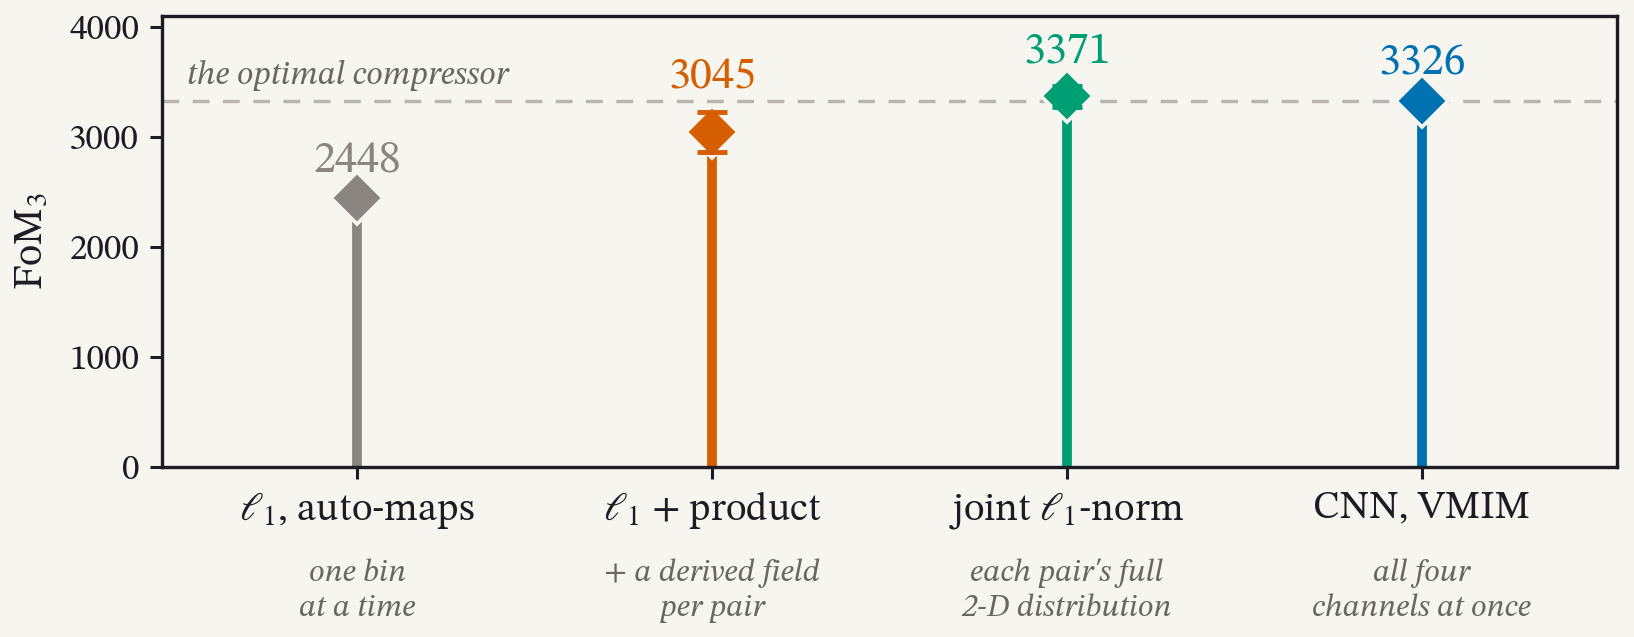
three-parameter figure of merit, matched pipeline
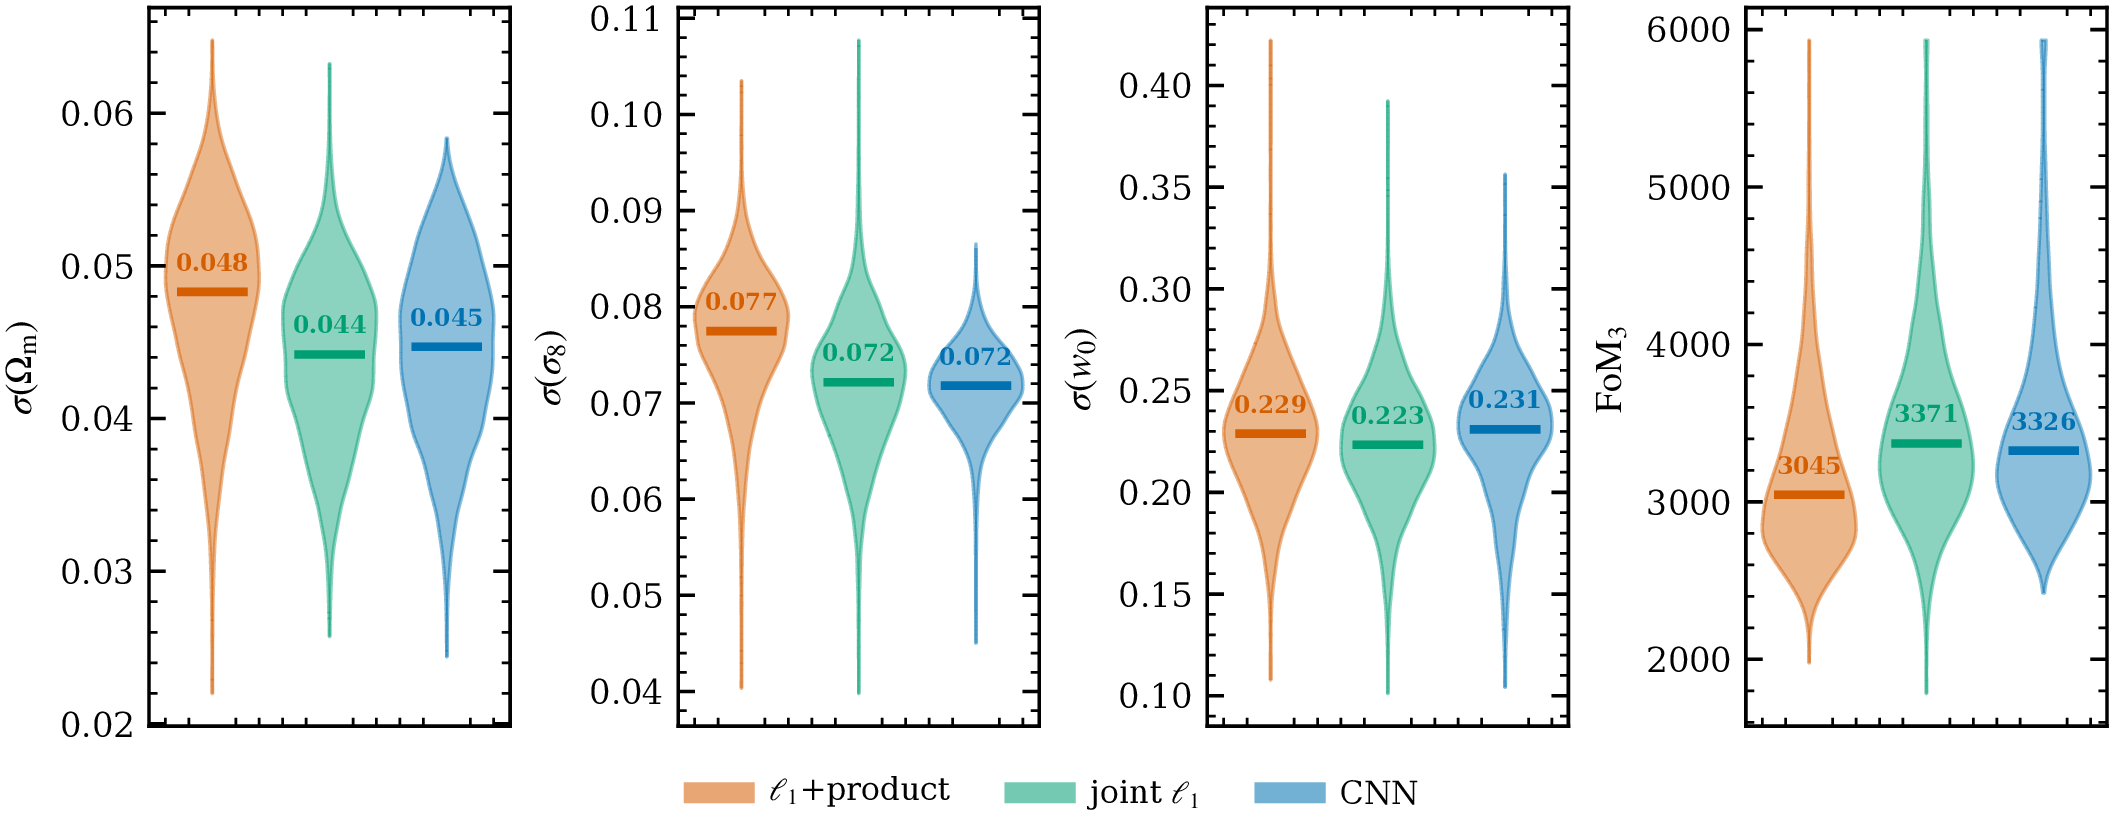
One advantage of the compressor remains: it reads the bins jointly by construction. This matters in the nulled frame.
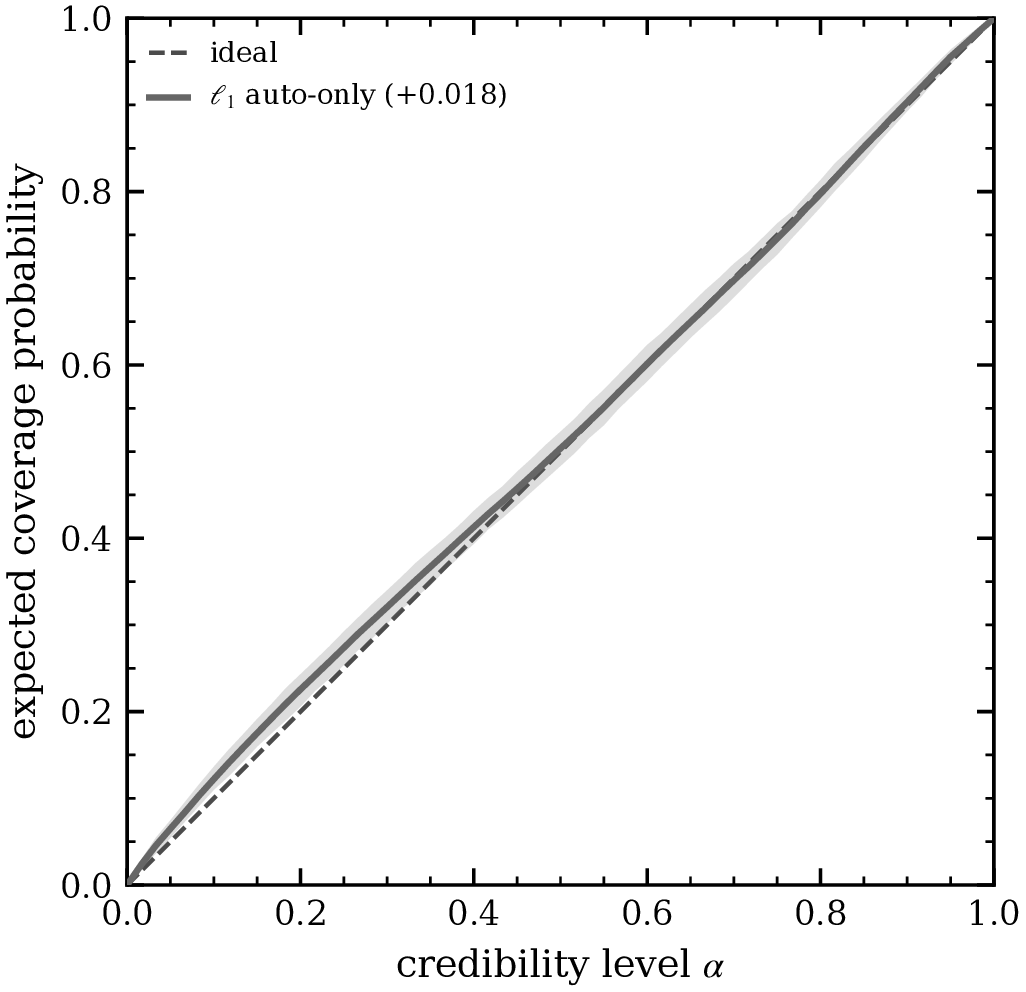
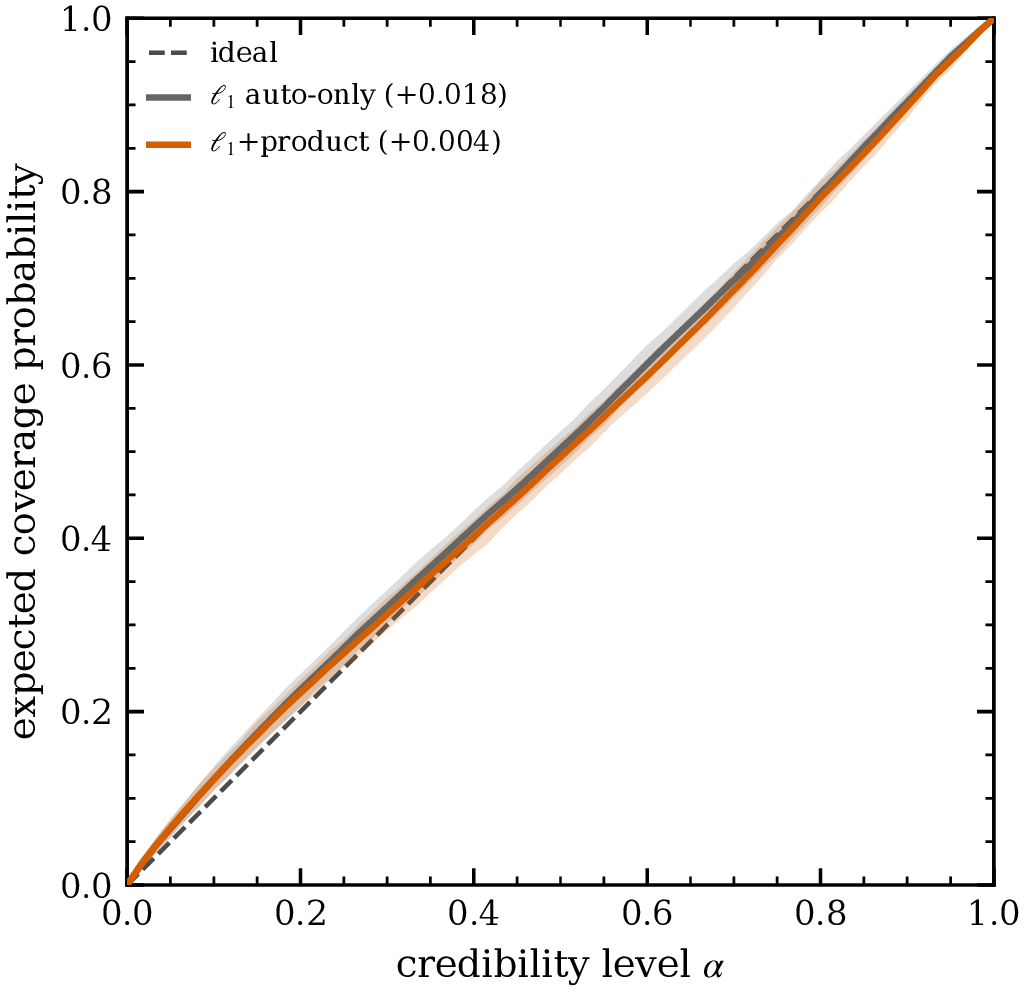
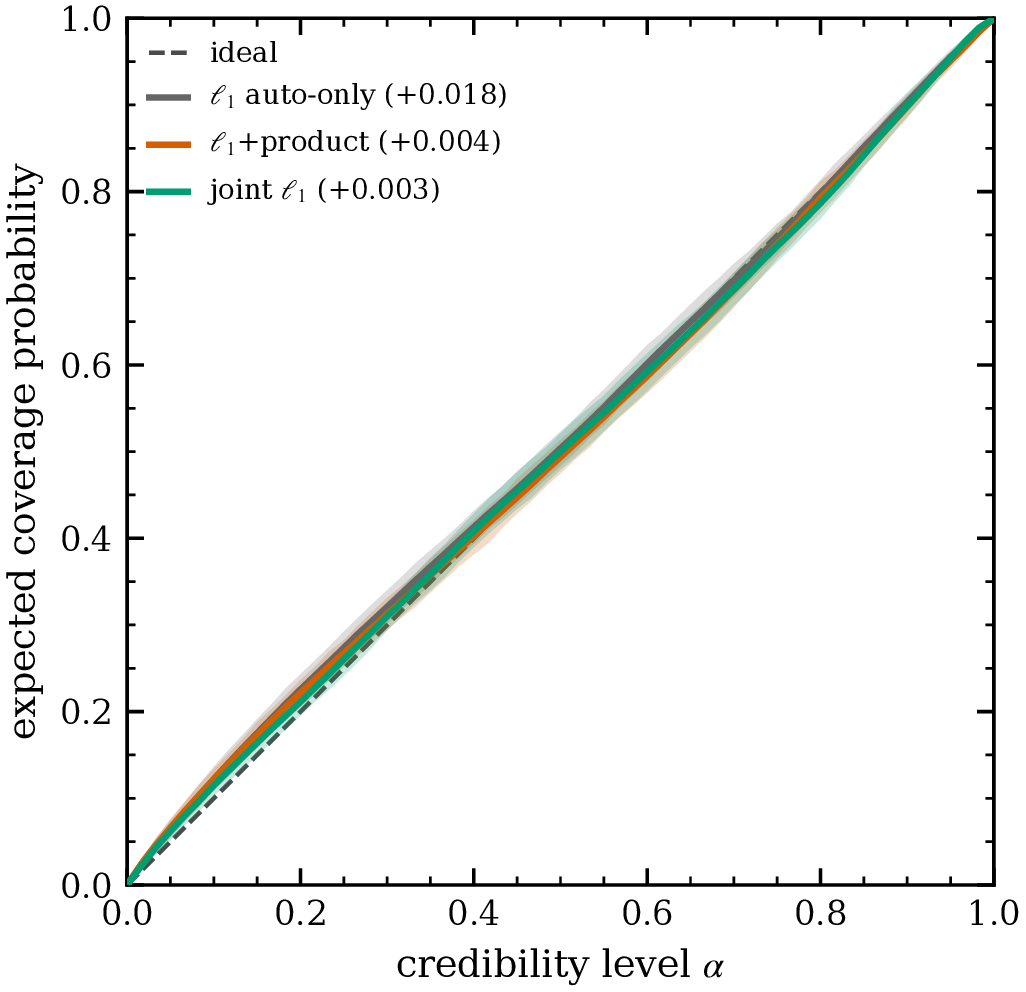
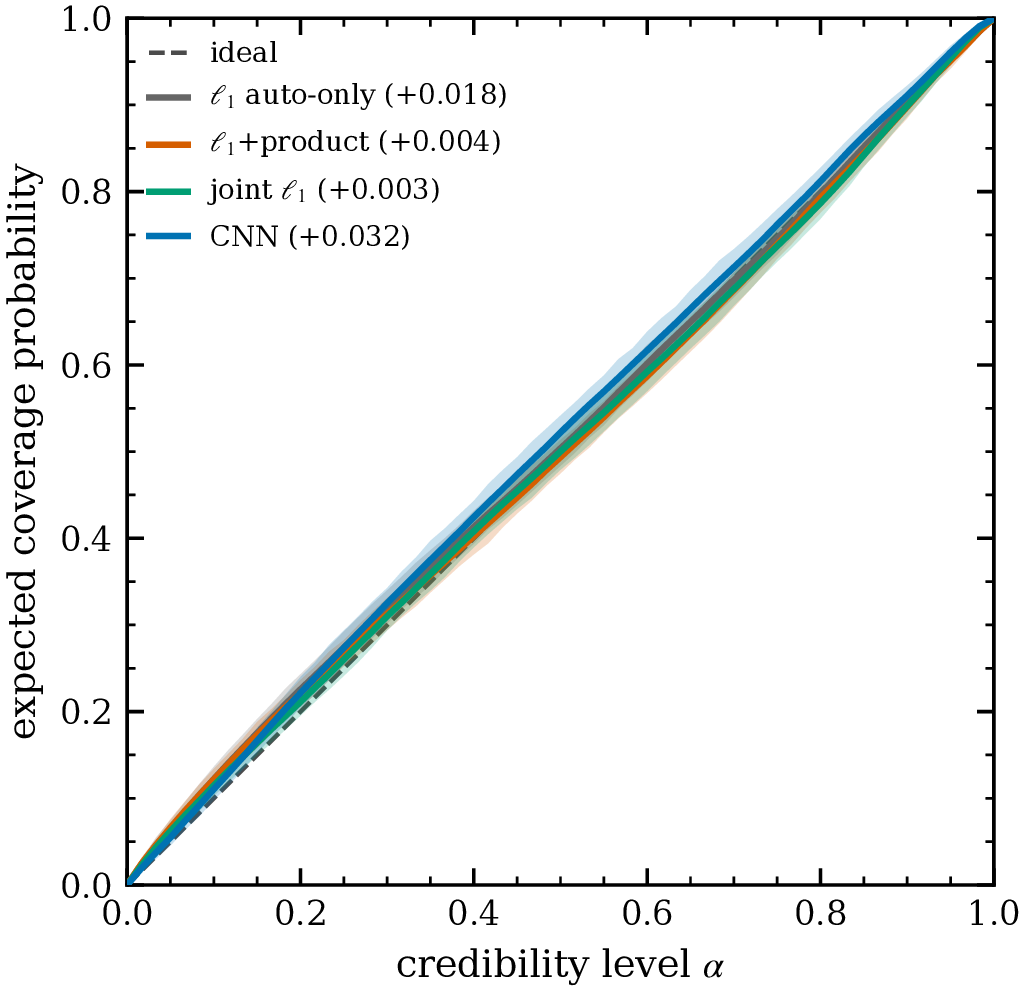
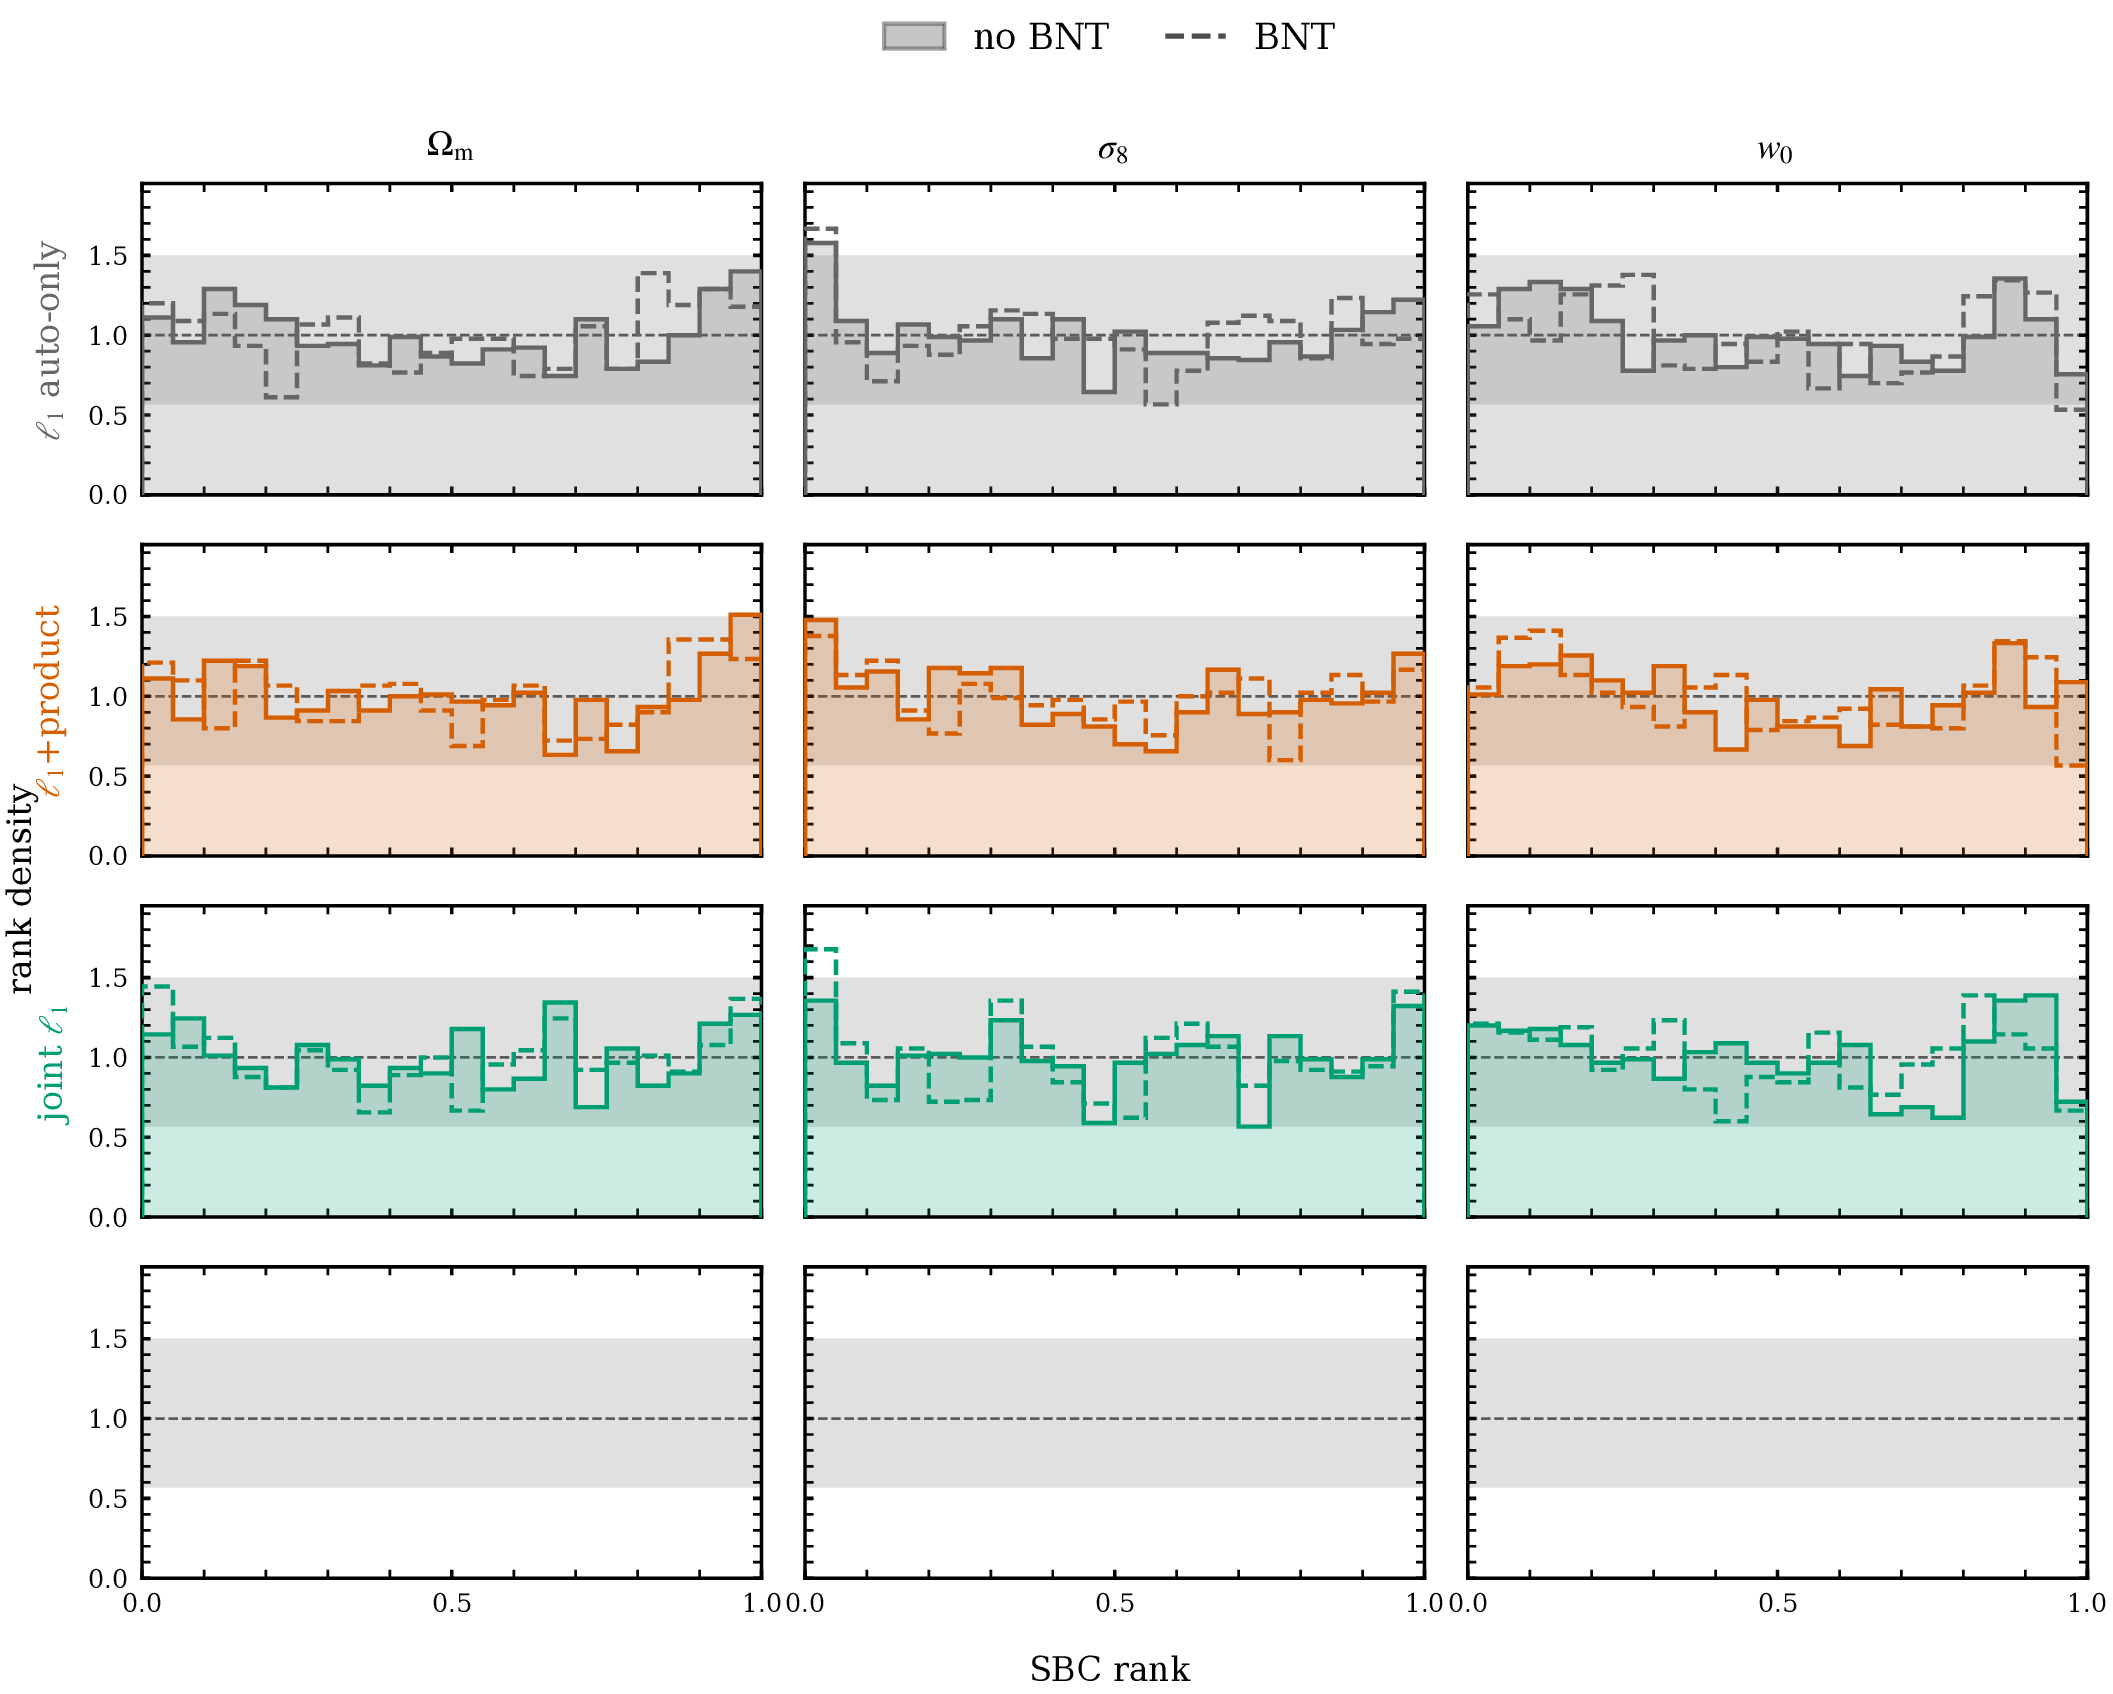
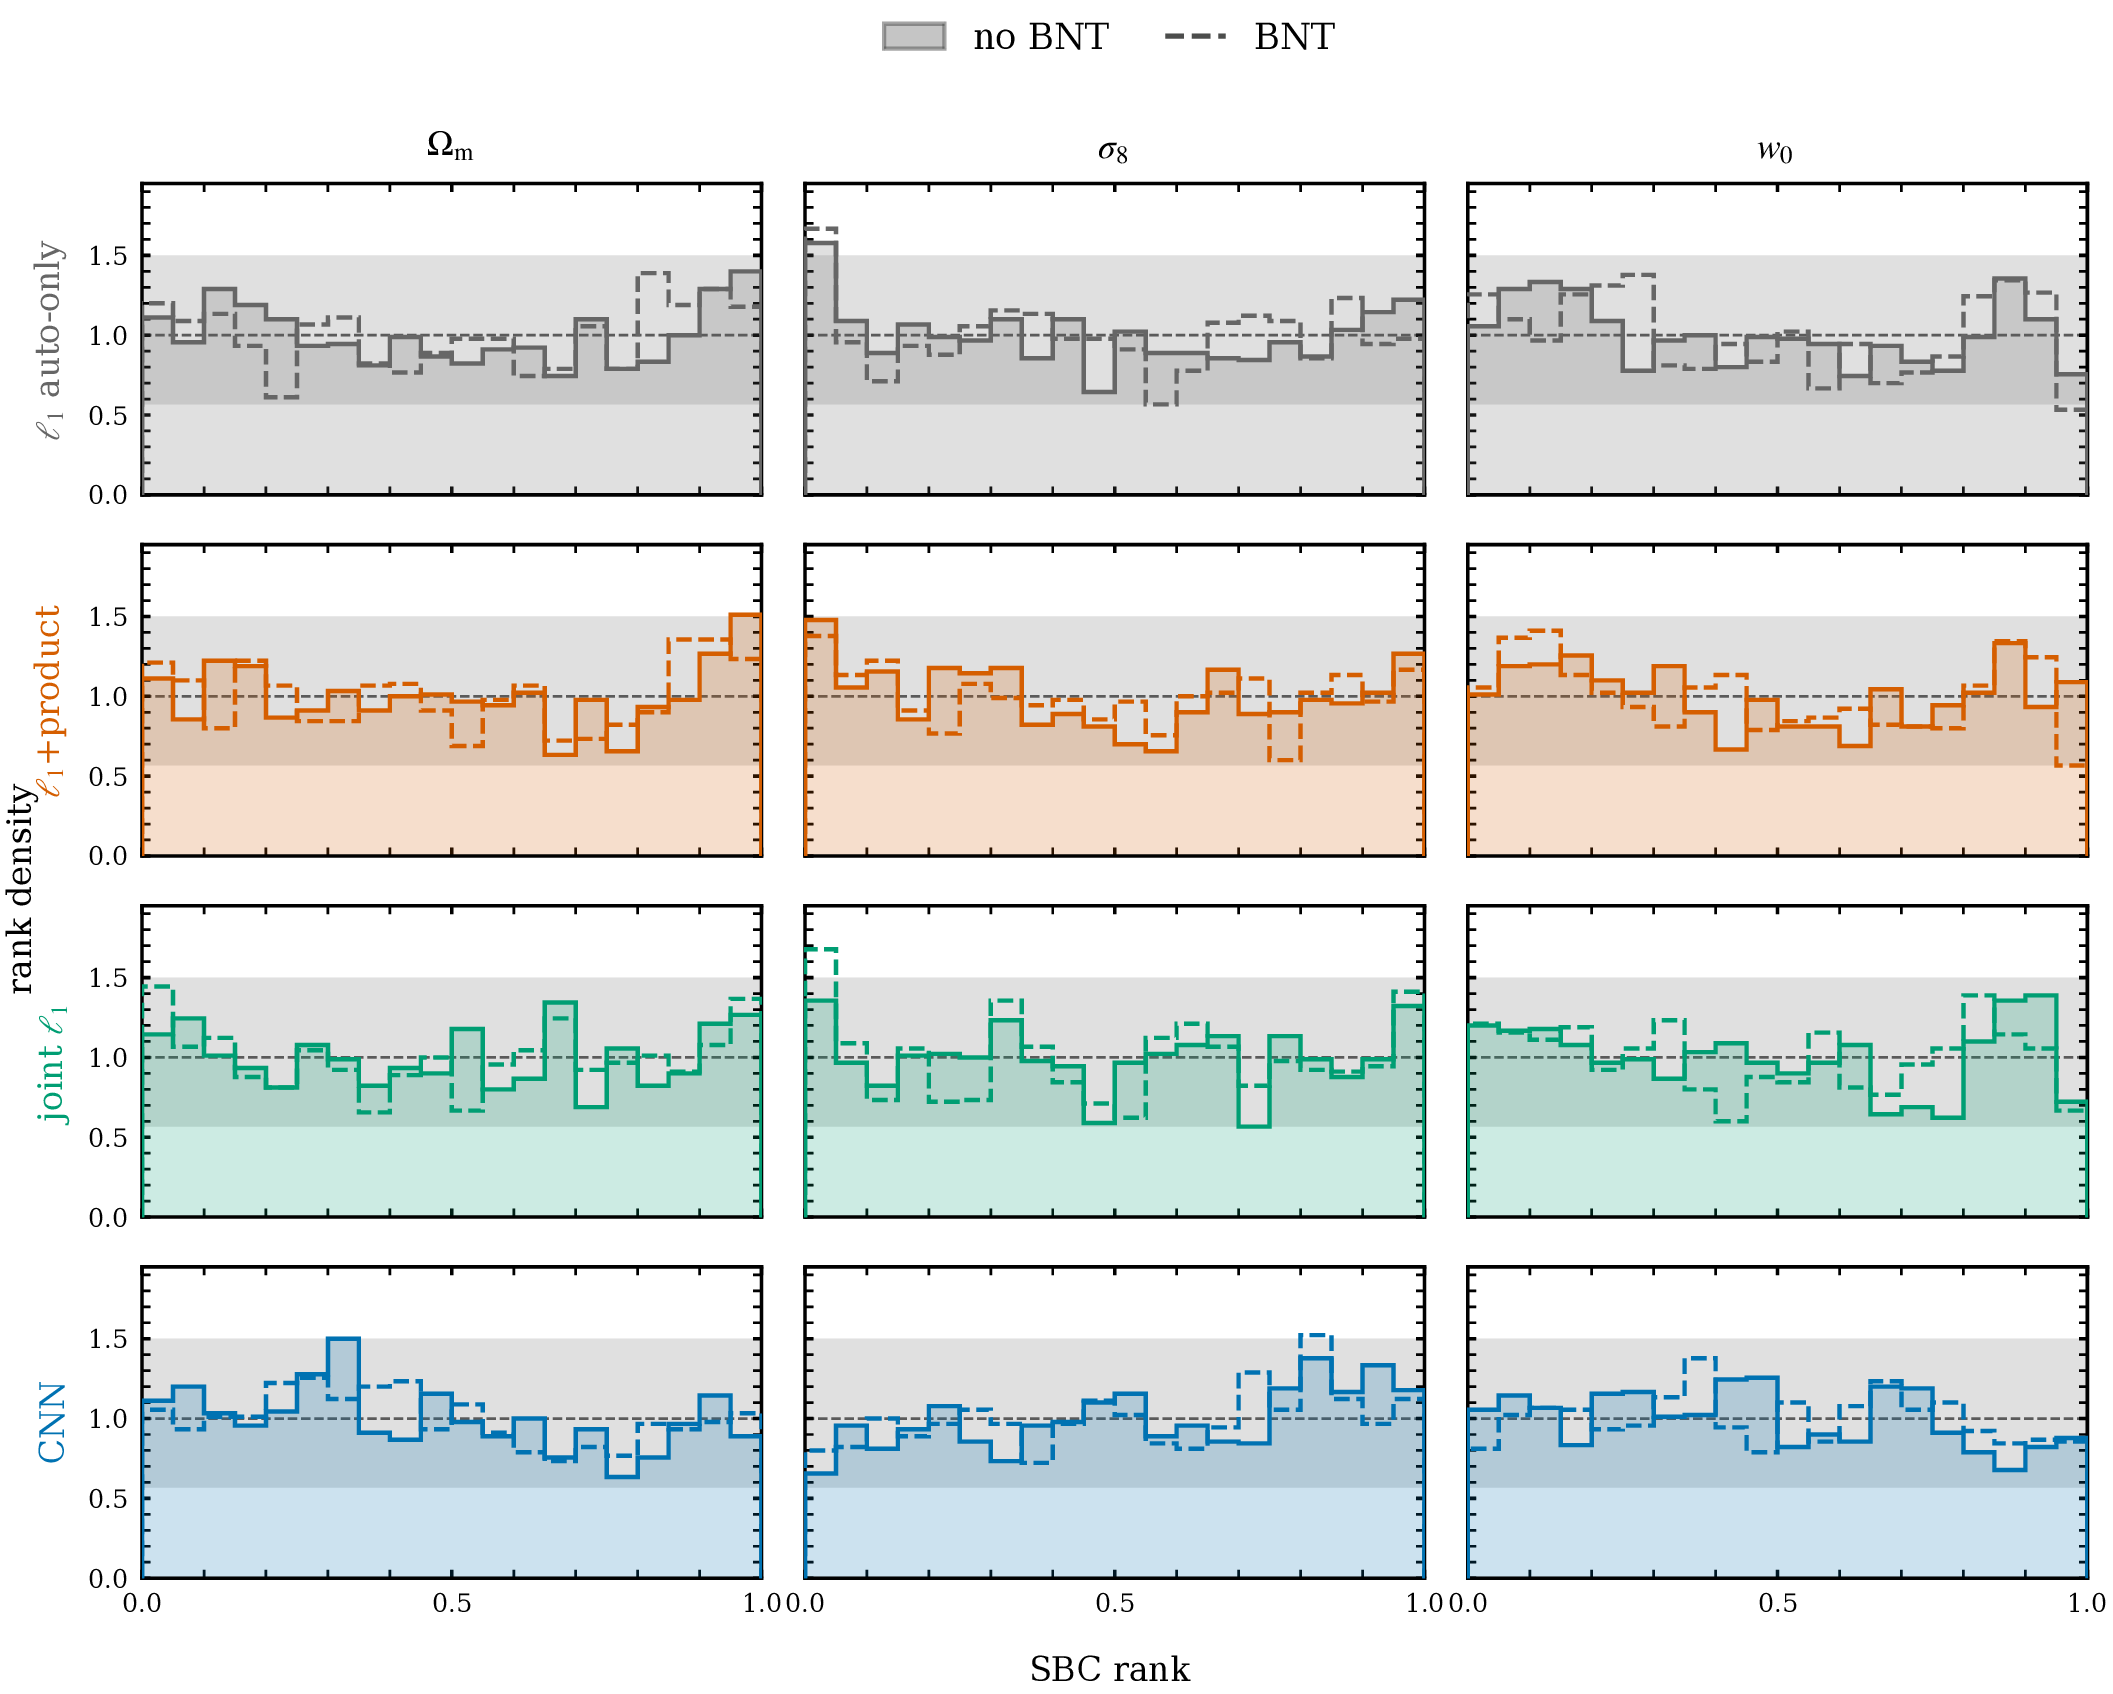
When the pipeline says it is 68% confident, is it right 68% of the time? Both tests answer that by rerunning the analysis on simulations where the true parameters are known.
Both average over many simulated datasets: they vouch for the pipeline in general, not for the one dataset we have.
Joint ℓ1 3371, CNN 3326, both calibrated. The optimised network buys no measurable constraining power.
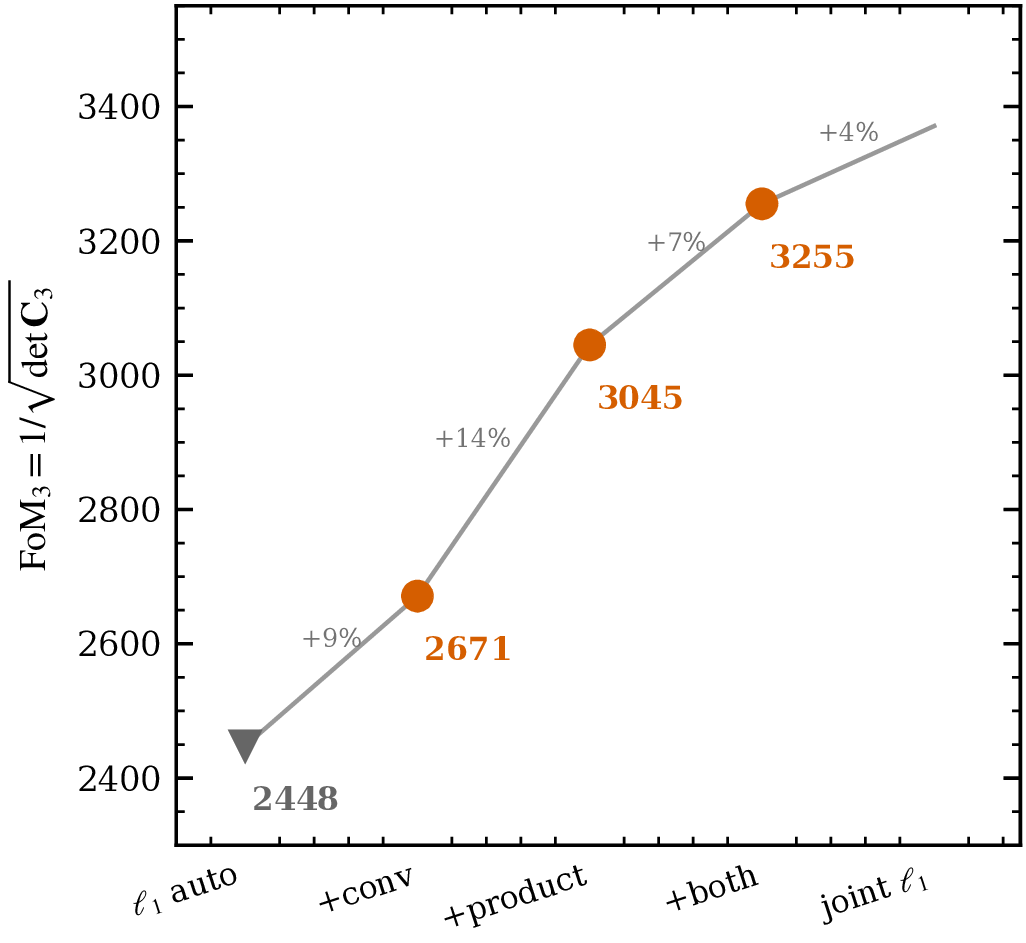
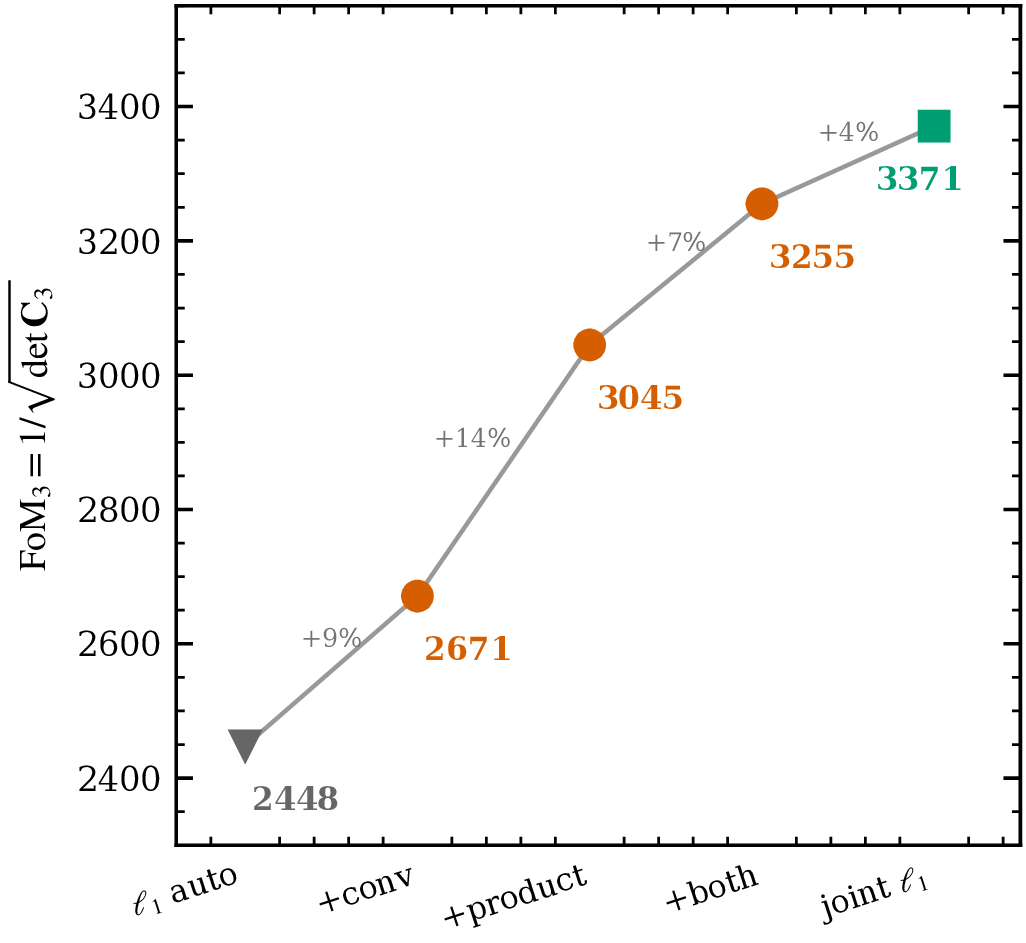
A full-sphere cross construction inflates this, but its channels carry 12–20% of their variance at ℓ < 18 against 0.4–1% for the autos. That is leakage. We use only the physically buildable flat-sky arms.
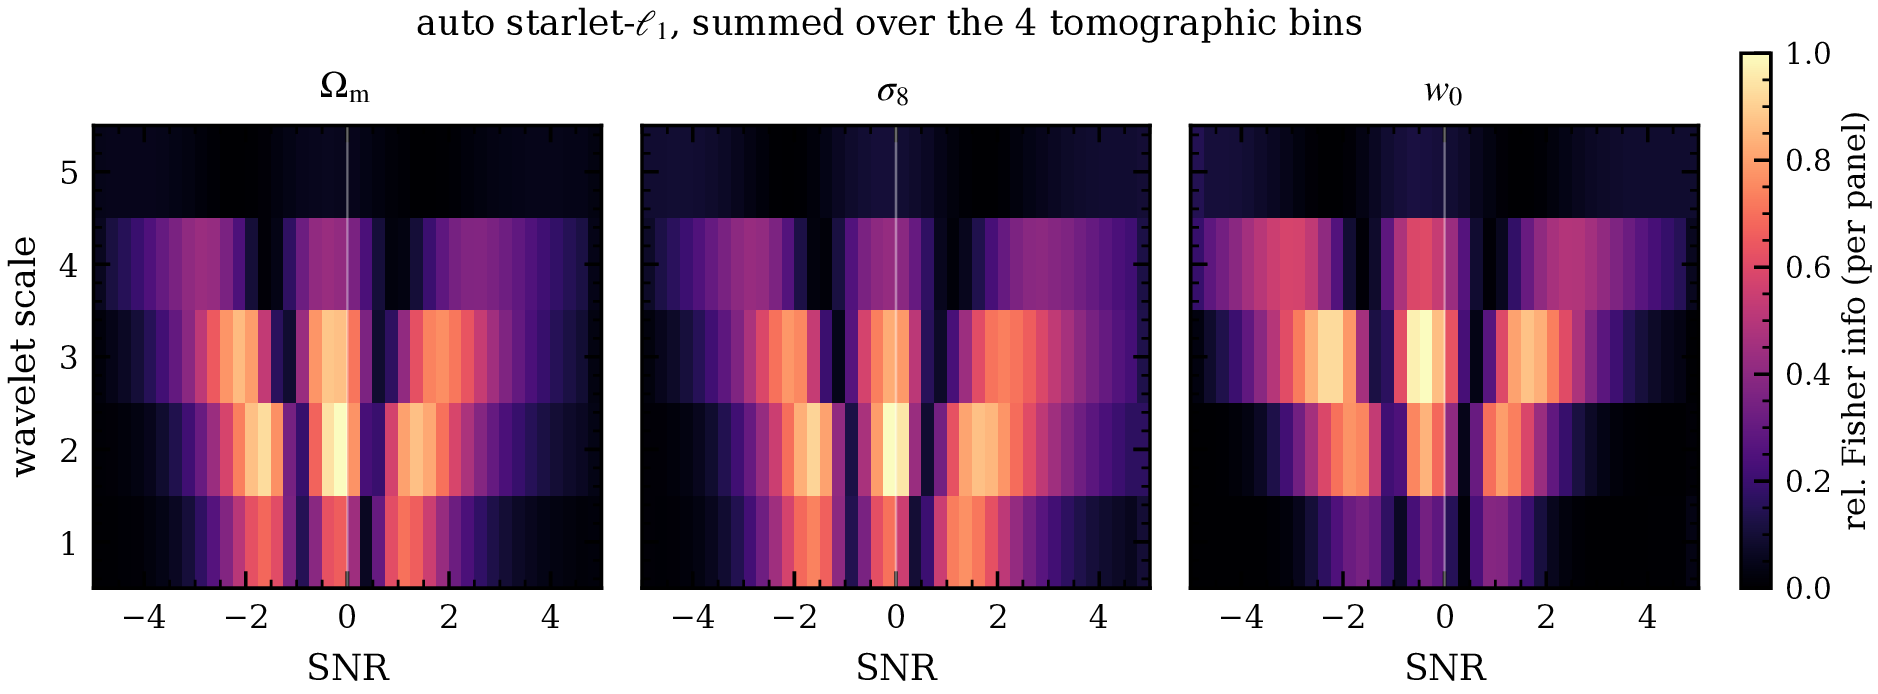
Intermediate scales ($j = 2$–3, tens of arcminutes) and moderate signal-to-noise ($|\nu| \approx 1$–2): mildly non-linear structure rather than the rare extreme peaks. Consistent with Paper I: drop $j=1$ and you keep most of it.
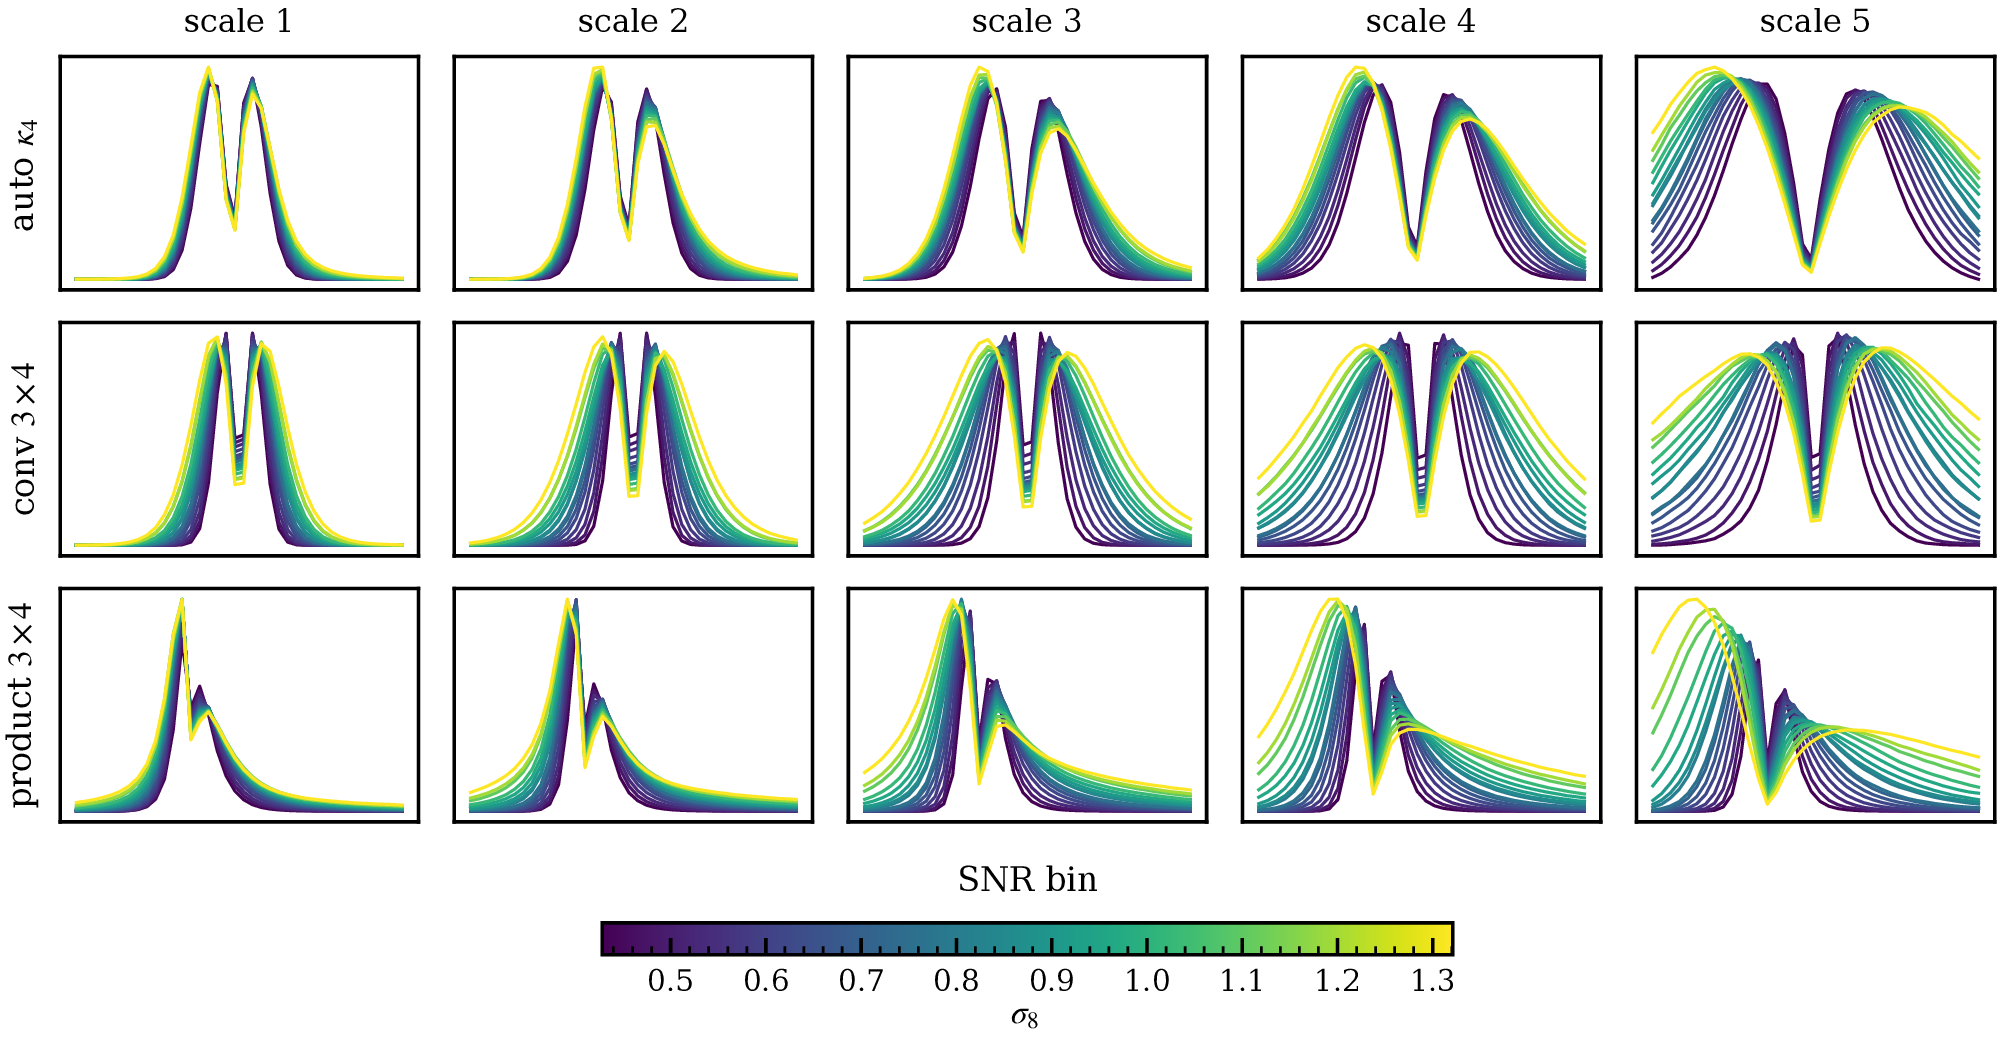
Coloured by $\sigma_8$. The statistic responds smoothly and monotonically across the prior: no training, no emulator, and the dependence is visible by eye.
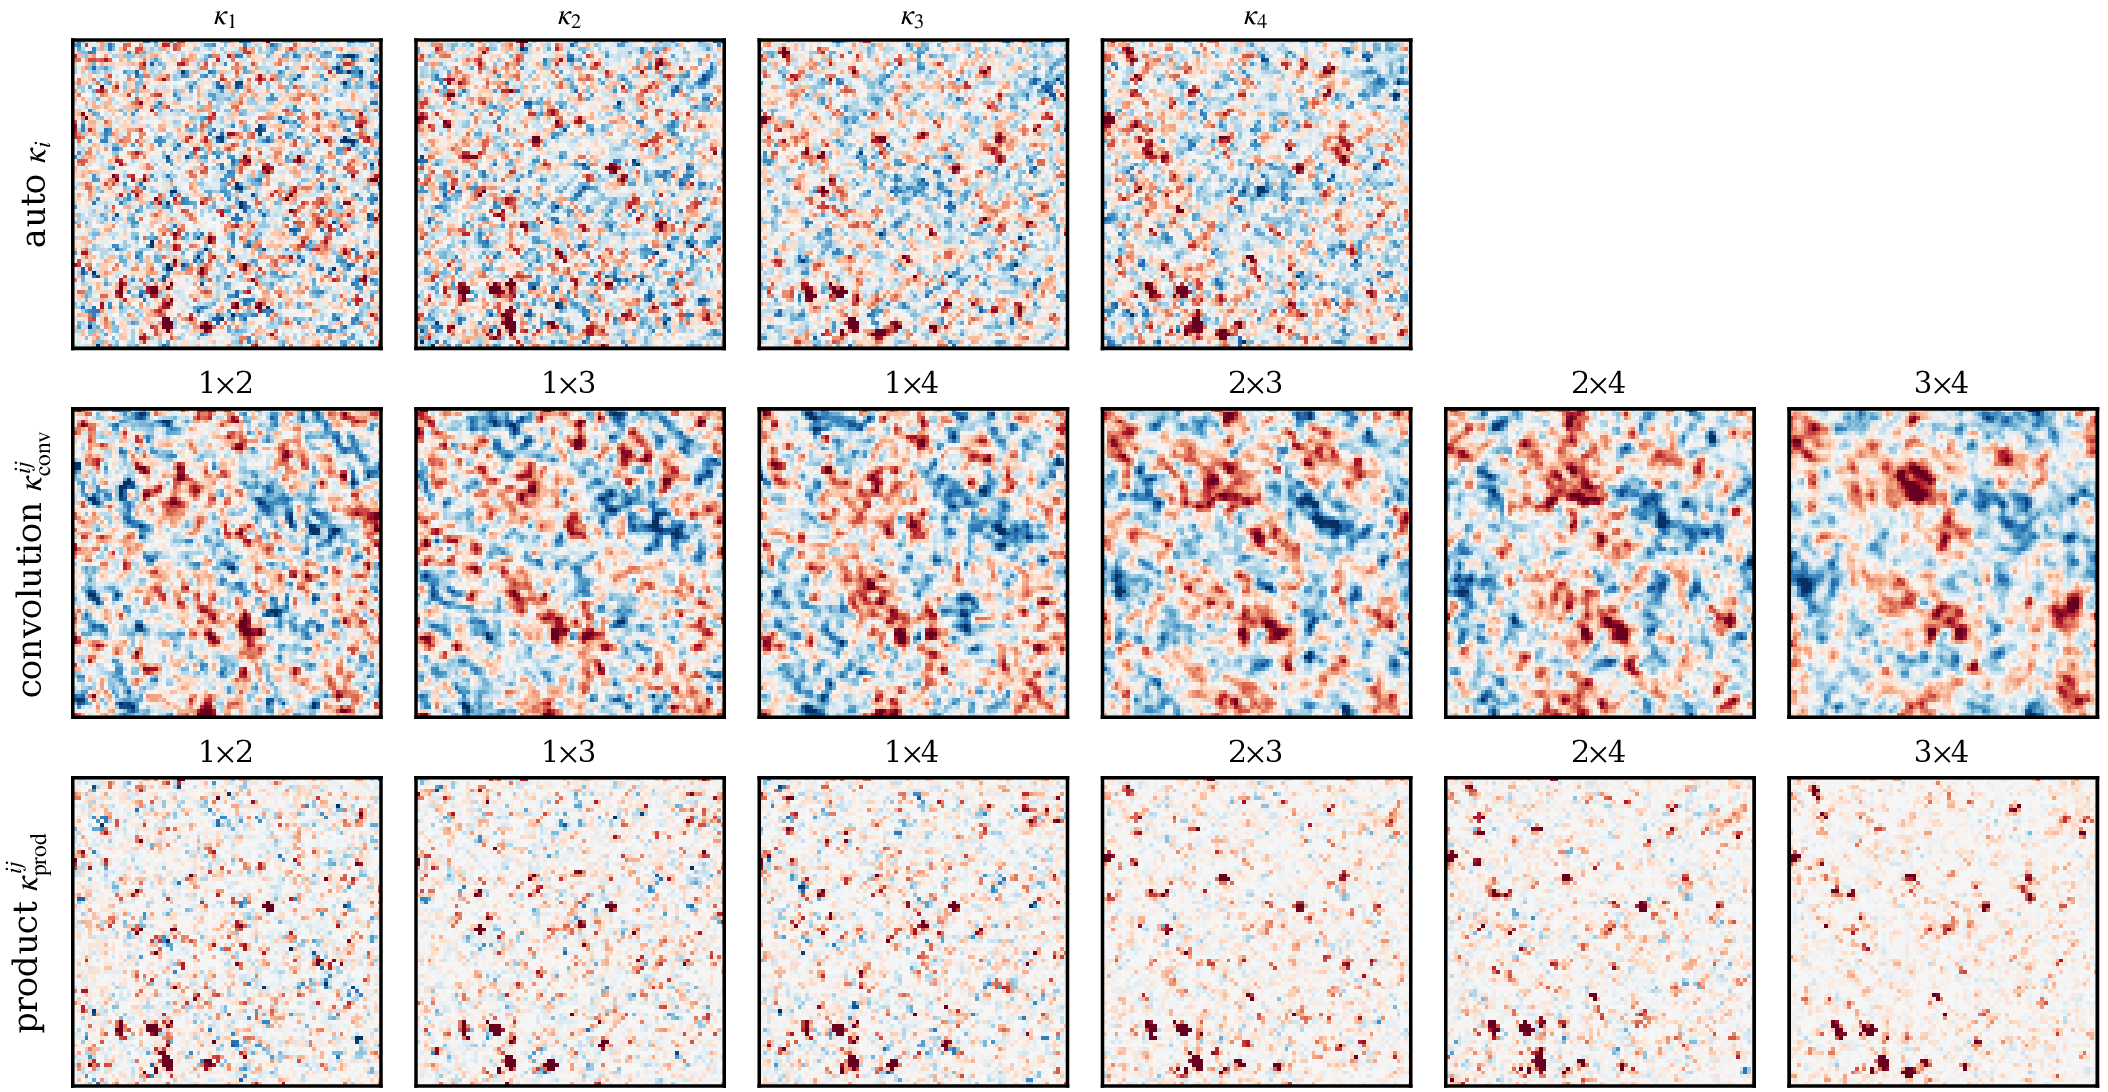
10°×10° gnomonic patches, 80×80 px (7.5′/px), $|b| < 75^{\circ}$. 180 patches per realisation × 50 noise realisations = 9,000 mock observations. Patch size chosen at 10° because gnomonic corner distortion falls from 6.3% at 20° to 1.5% at 10°.
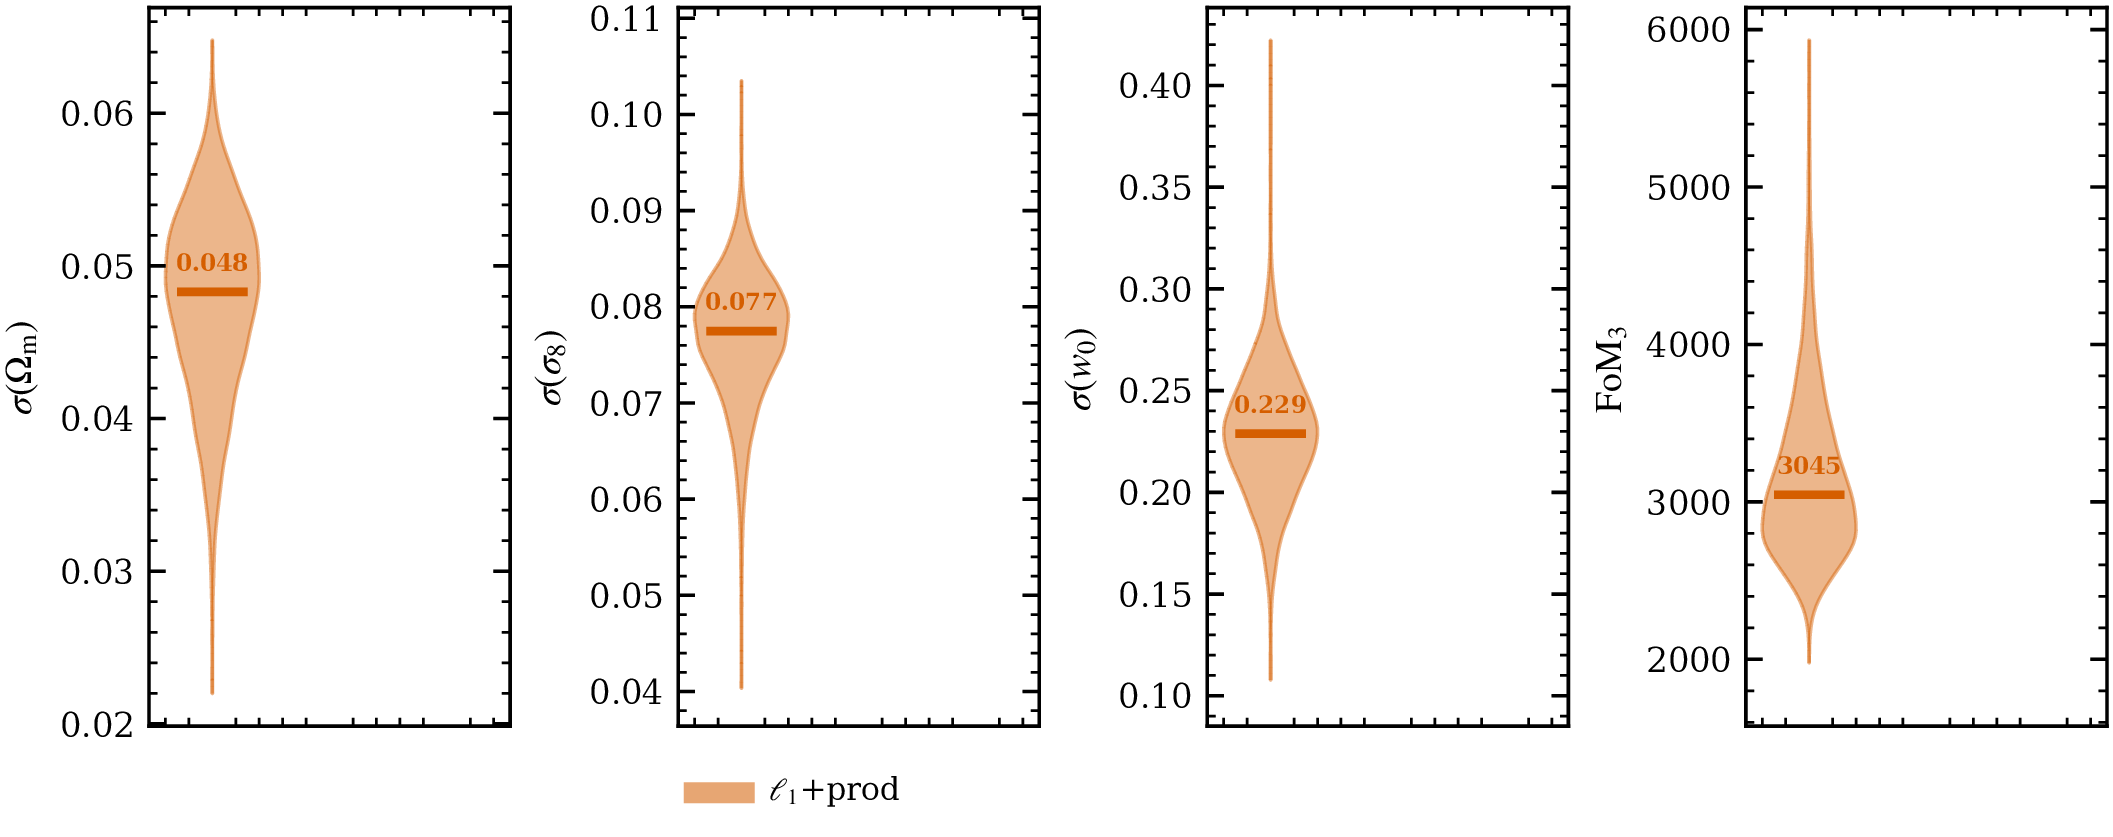
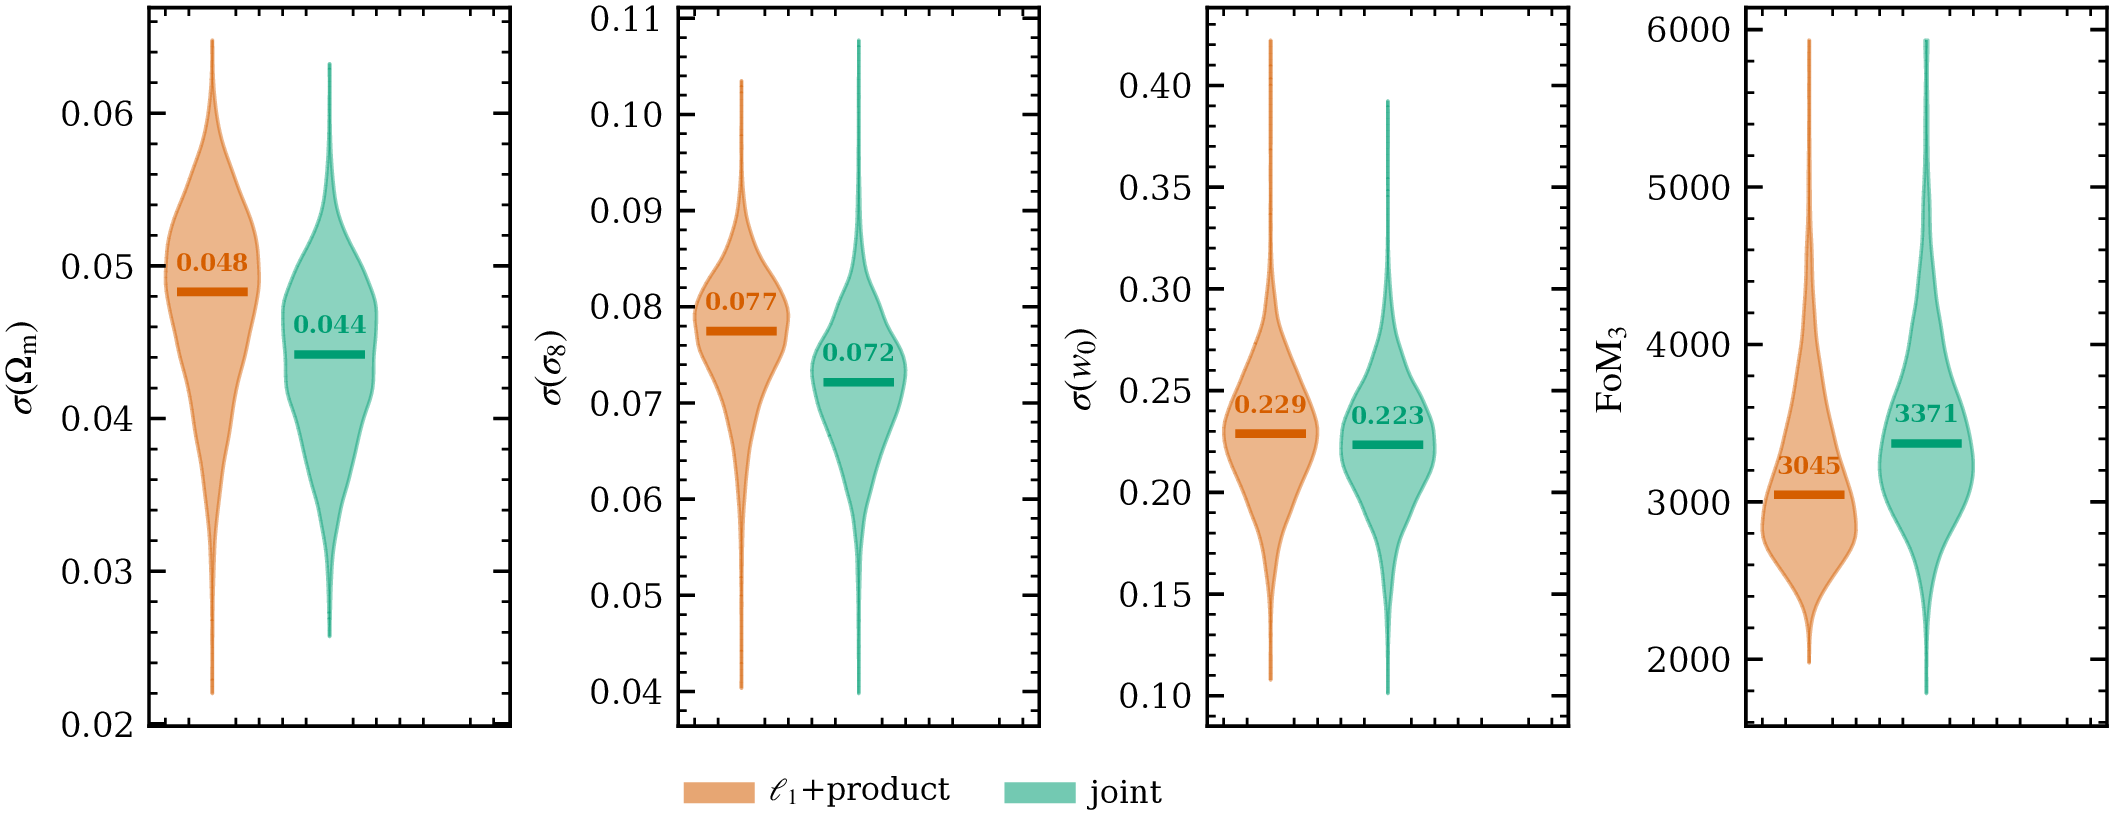
The answer to “FoM3 is fragile in a degenerate parameter space”: the marginals are quoted alongside it, and this is the population rather than a point. The ± on the medians is the spread over three independently trained compressors, the dominant source of run-to-run variability.
Baryonic feedback, the wavelet ℓ1-norm, and the BNT transform.
figure of merit relative to the power spectrum, on each statistic's own baryon-safe scales
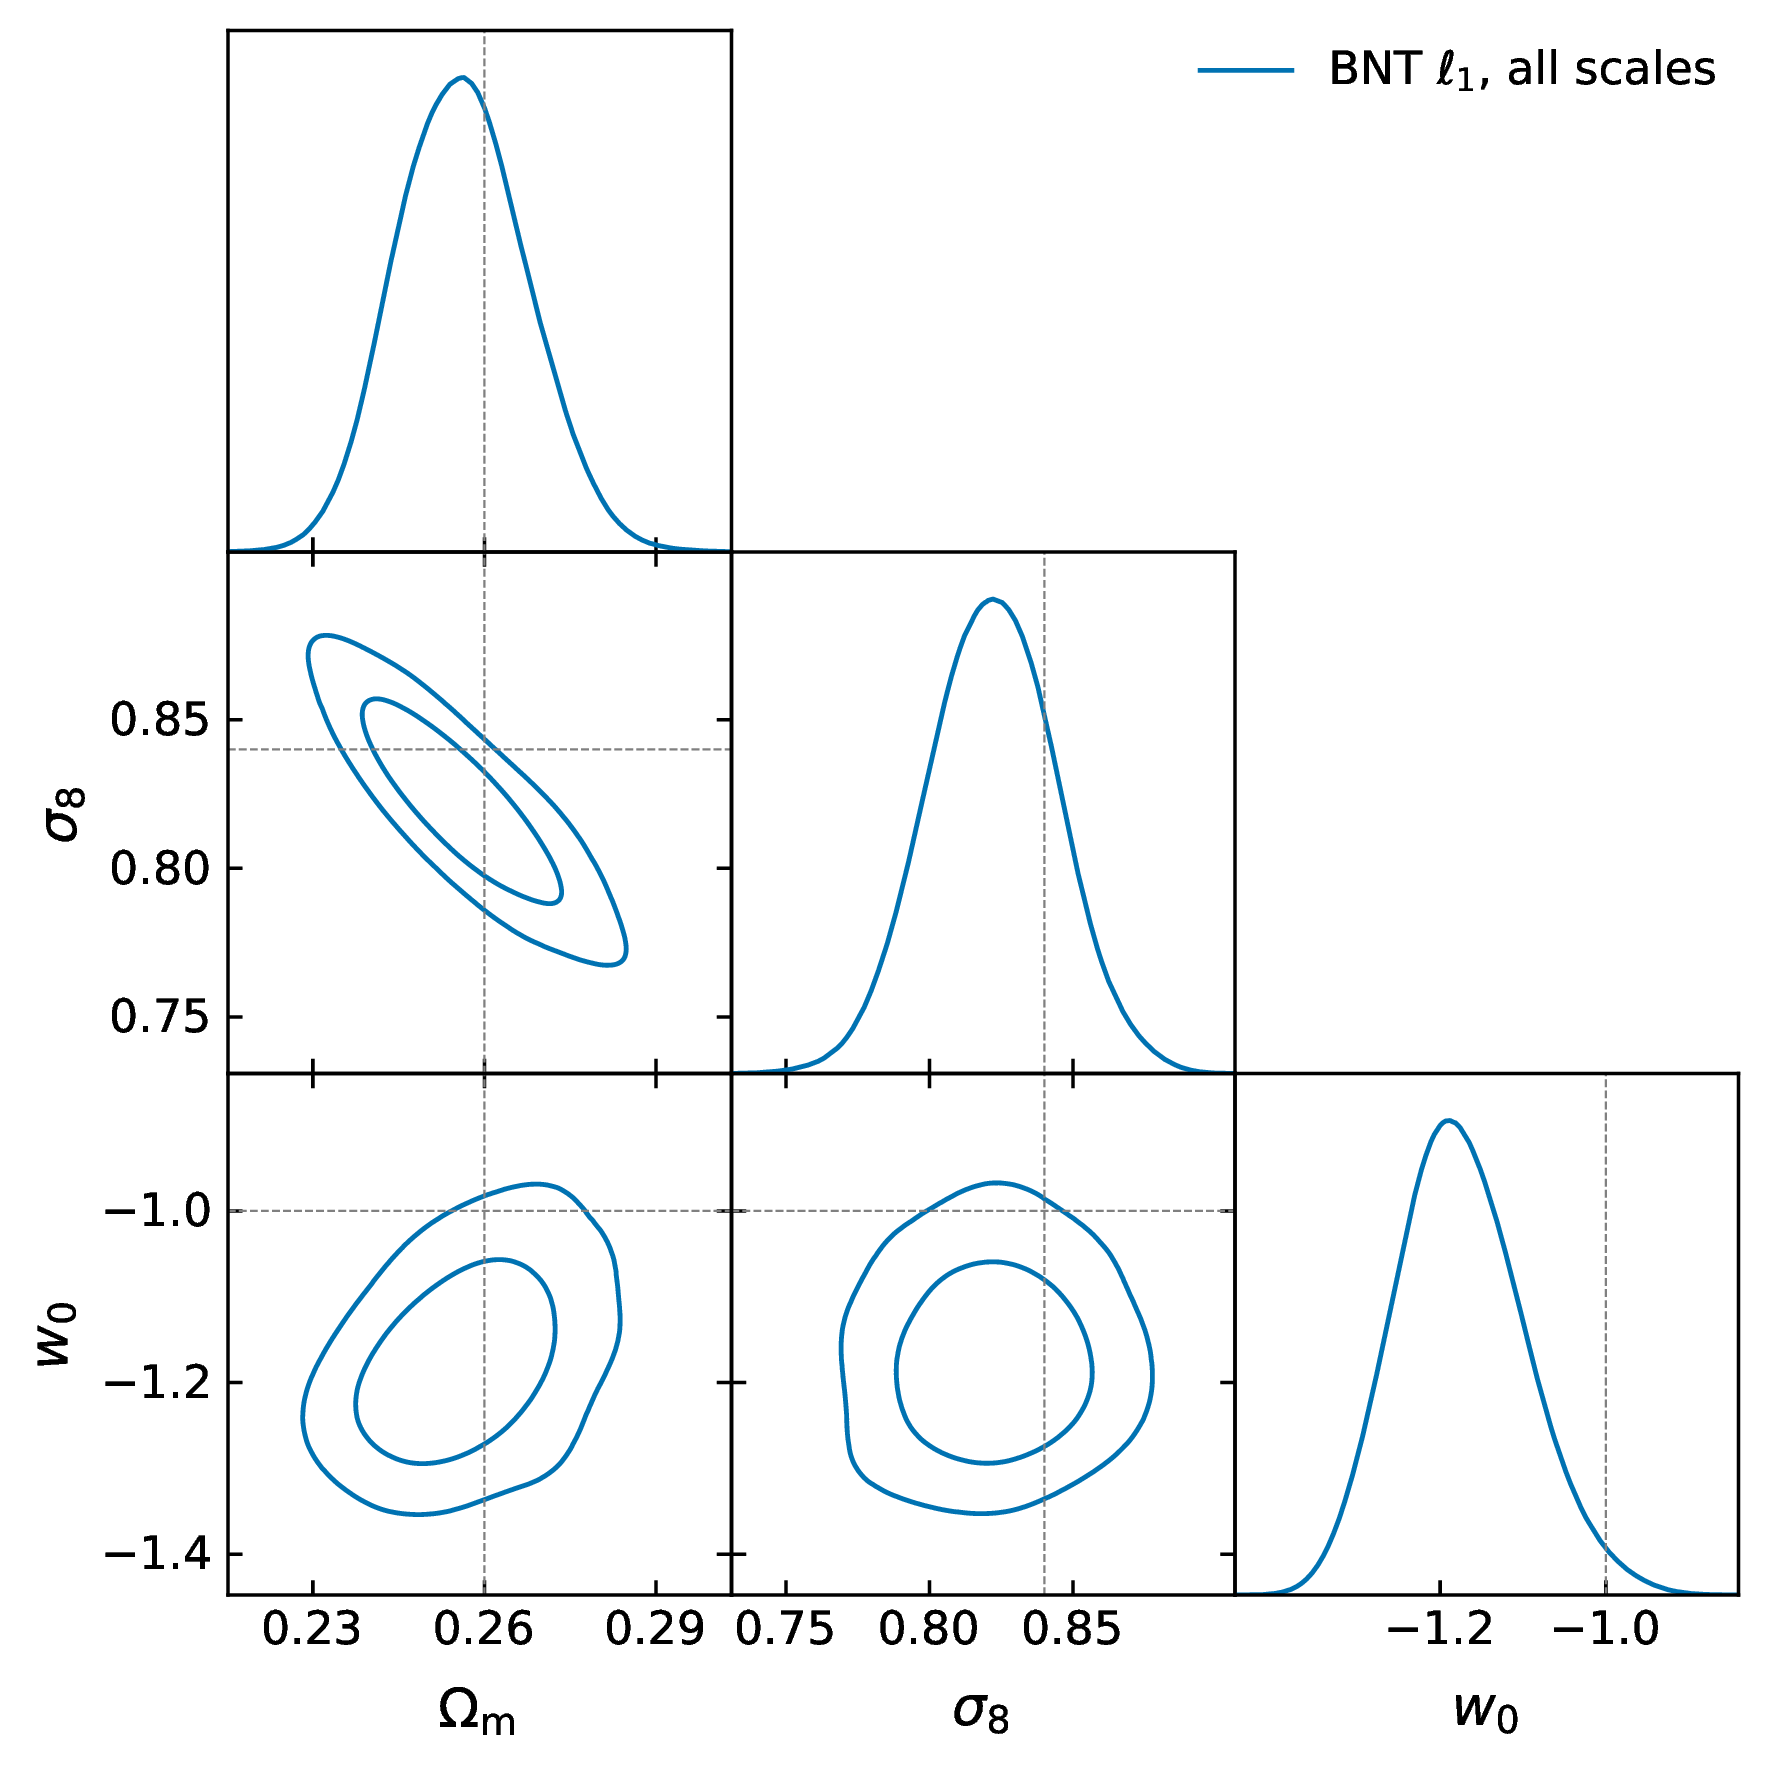
Conservative case: no feedback model, every contaminated scale removed.
Illustris: baryonic feedback reshaping the cosmic web
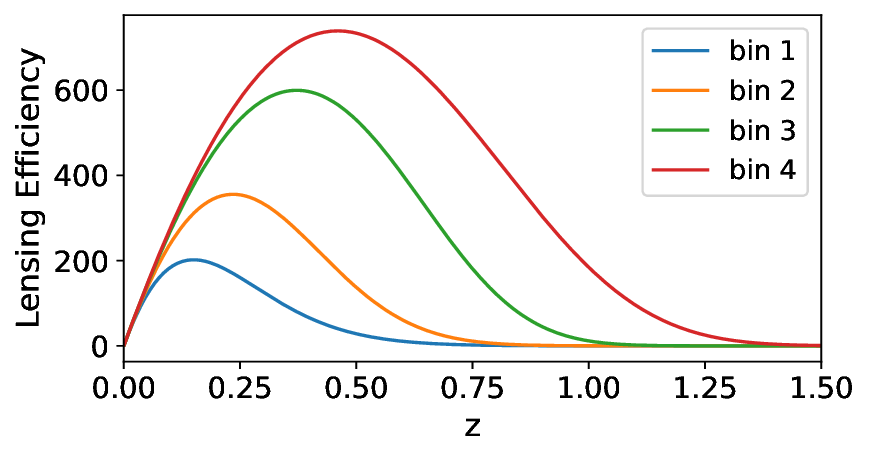
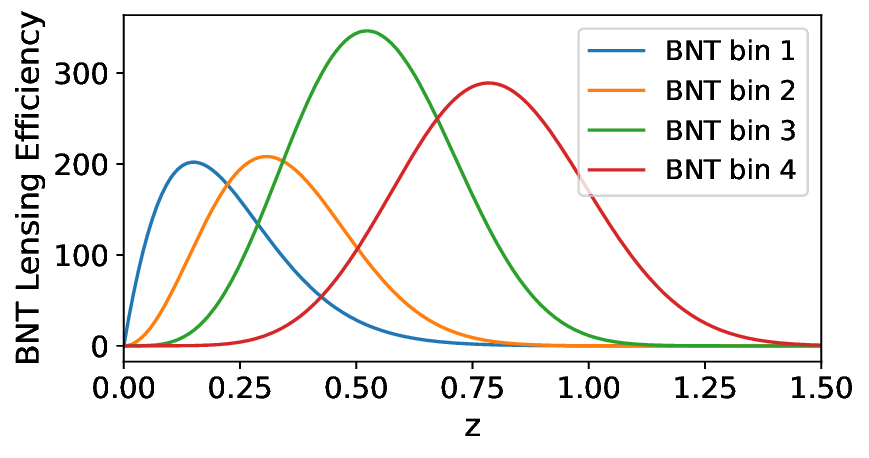
A fixed angular scale stops mixing redshifts, so the cut can go only where the systematic is
BNT = a fixed, invertible transform → nothing can have been lost...
Tersenov+ 2026, A&A and Tersenov+, submittedfigure of merit retained under the nulling
Same four summaries. In the standard frame they span 38% in FoM; in the nulled frame, a factor of six.
nulled frame over standard
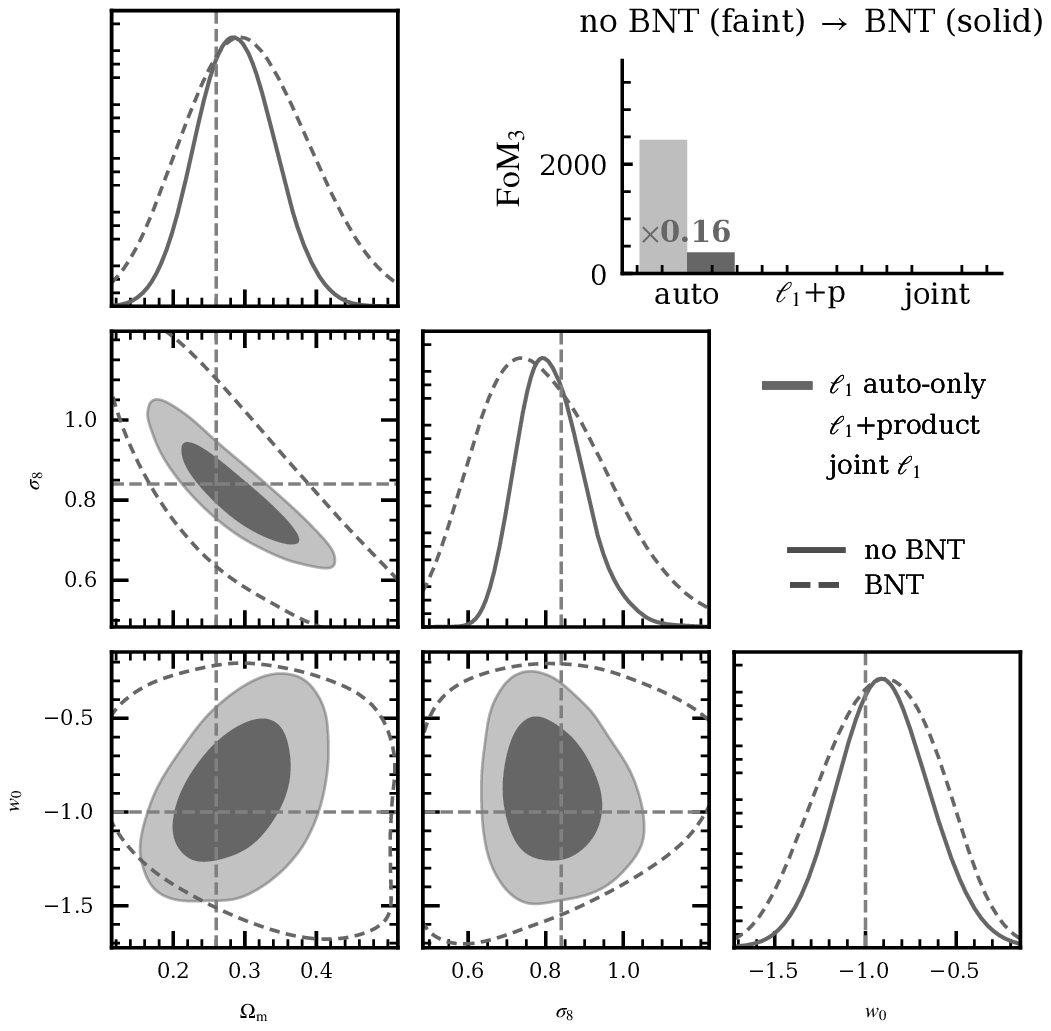
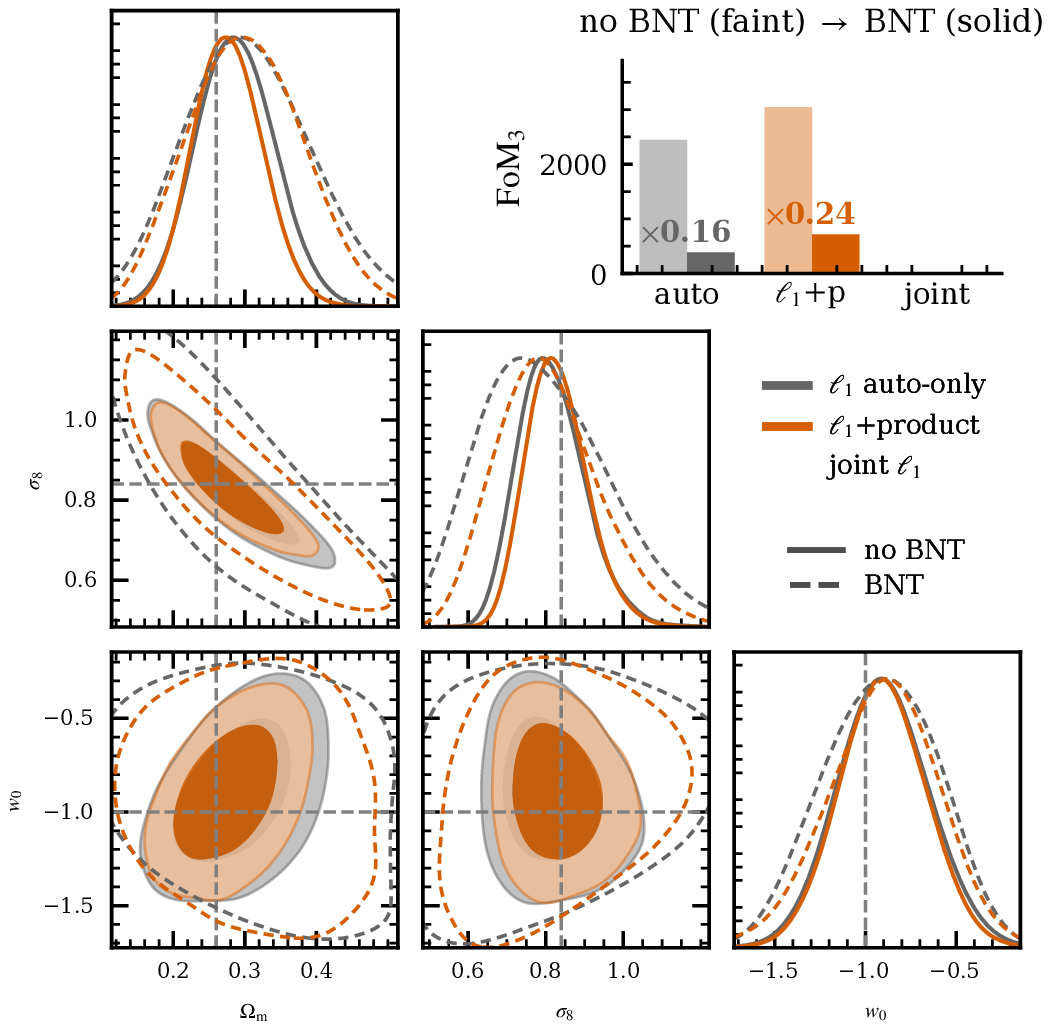
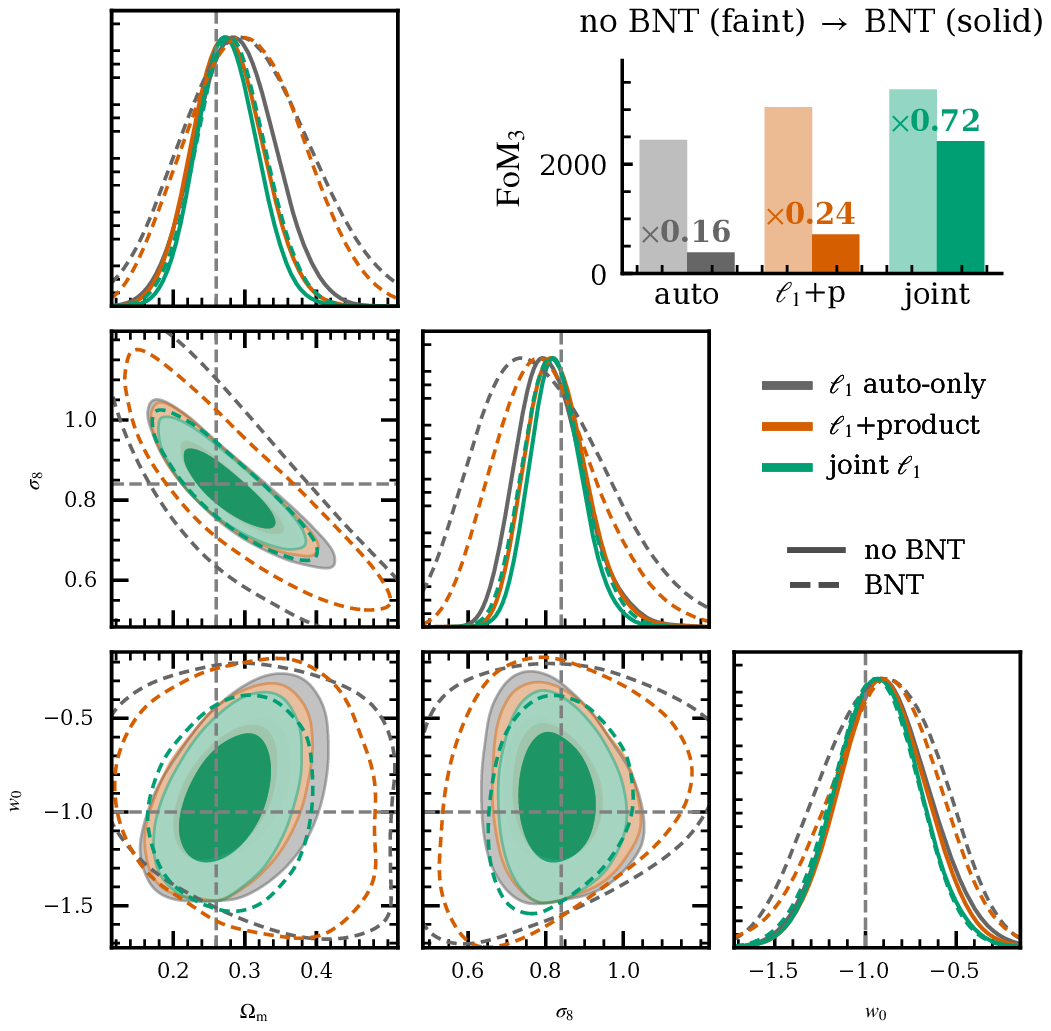
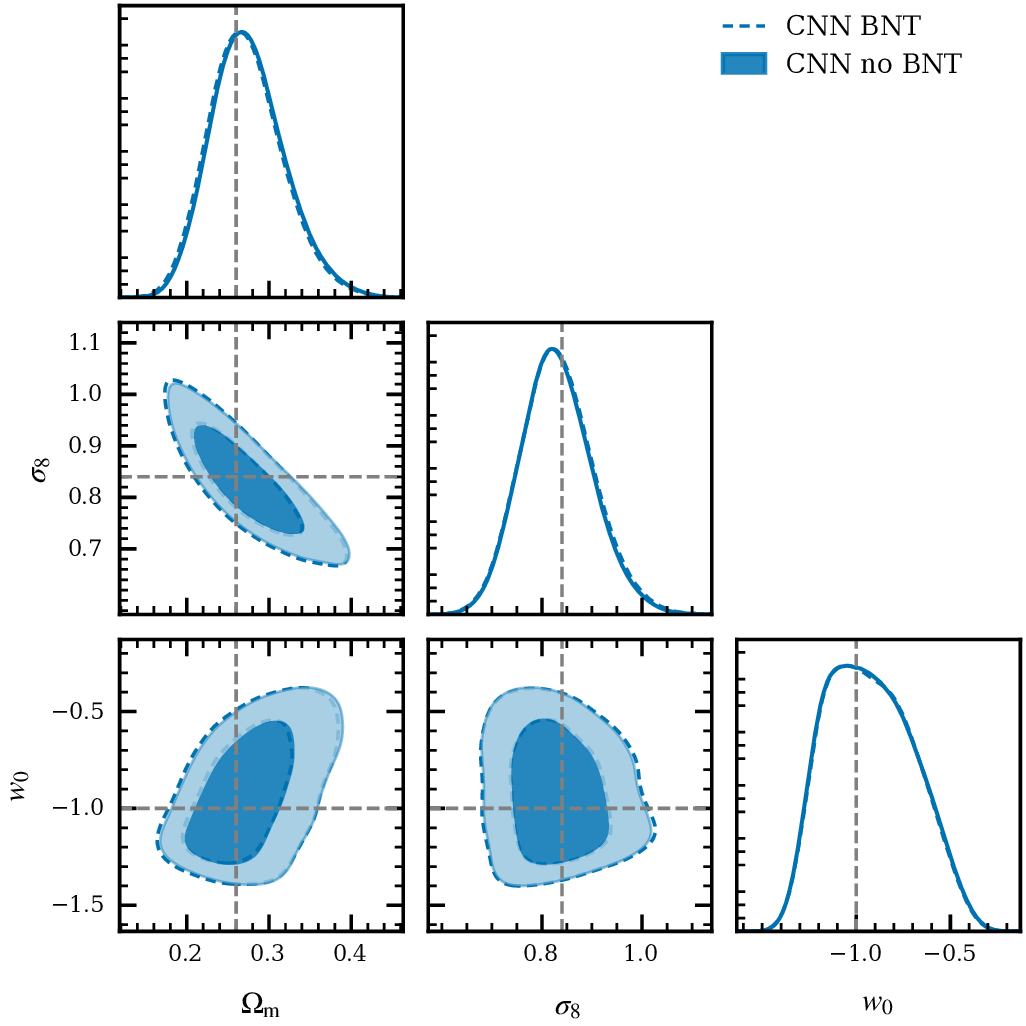
Nulling costs no constraining power provided some stage of the pipeline reads the bins jointly. The power spectrum with its cross-spectra is the simplest example.
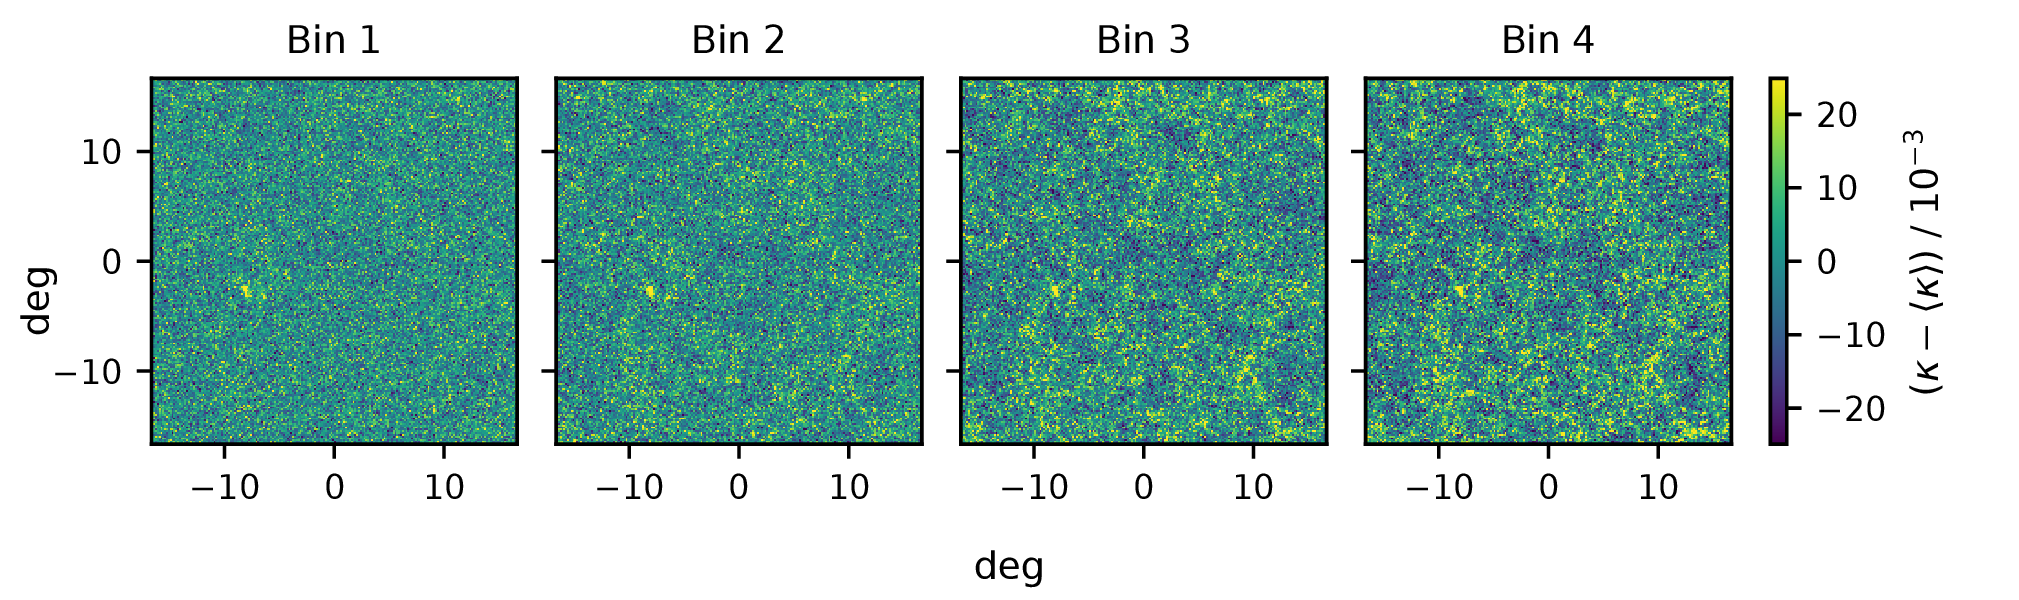
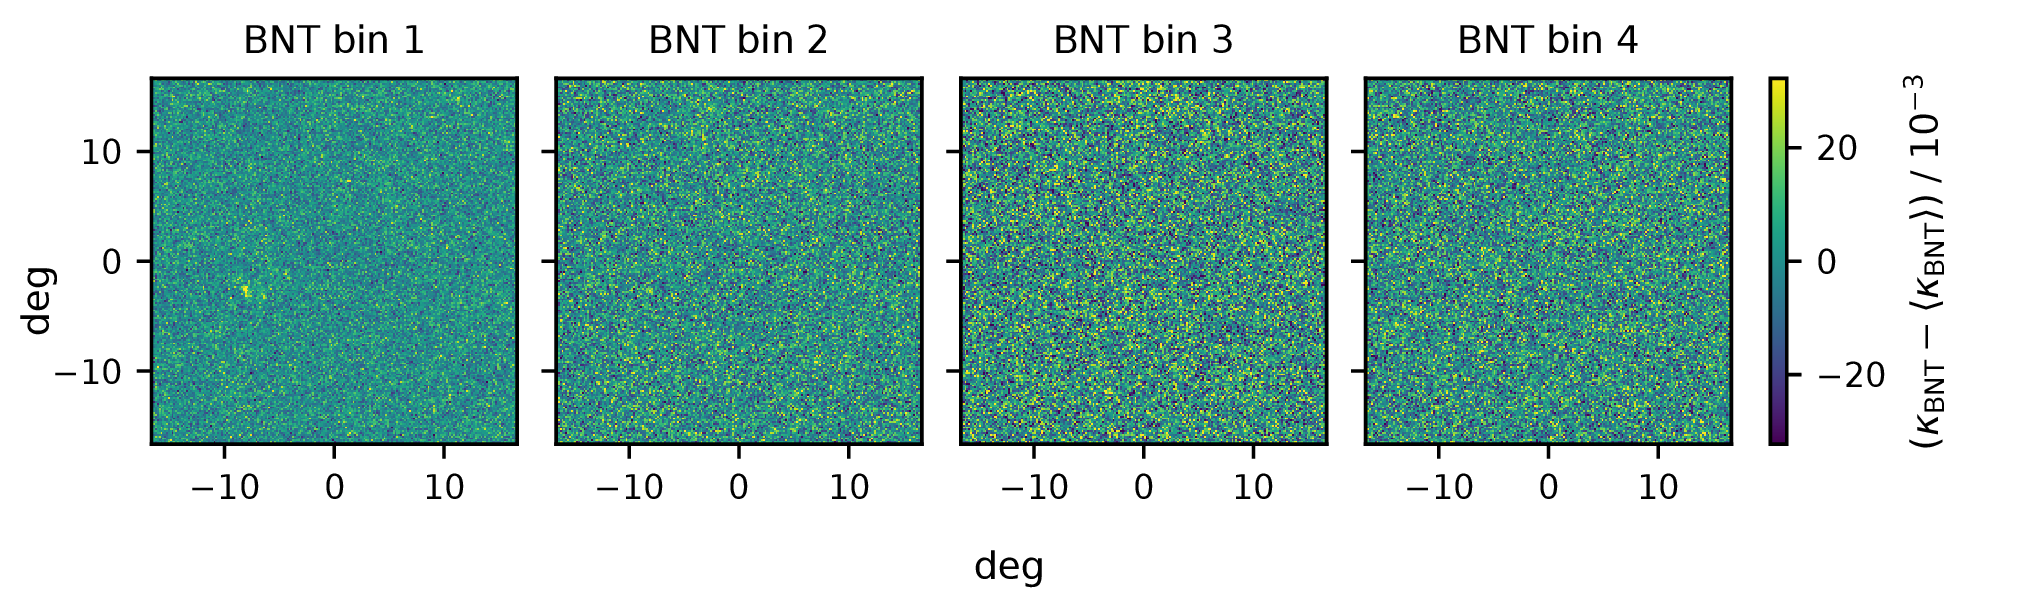
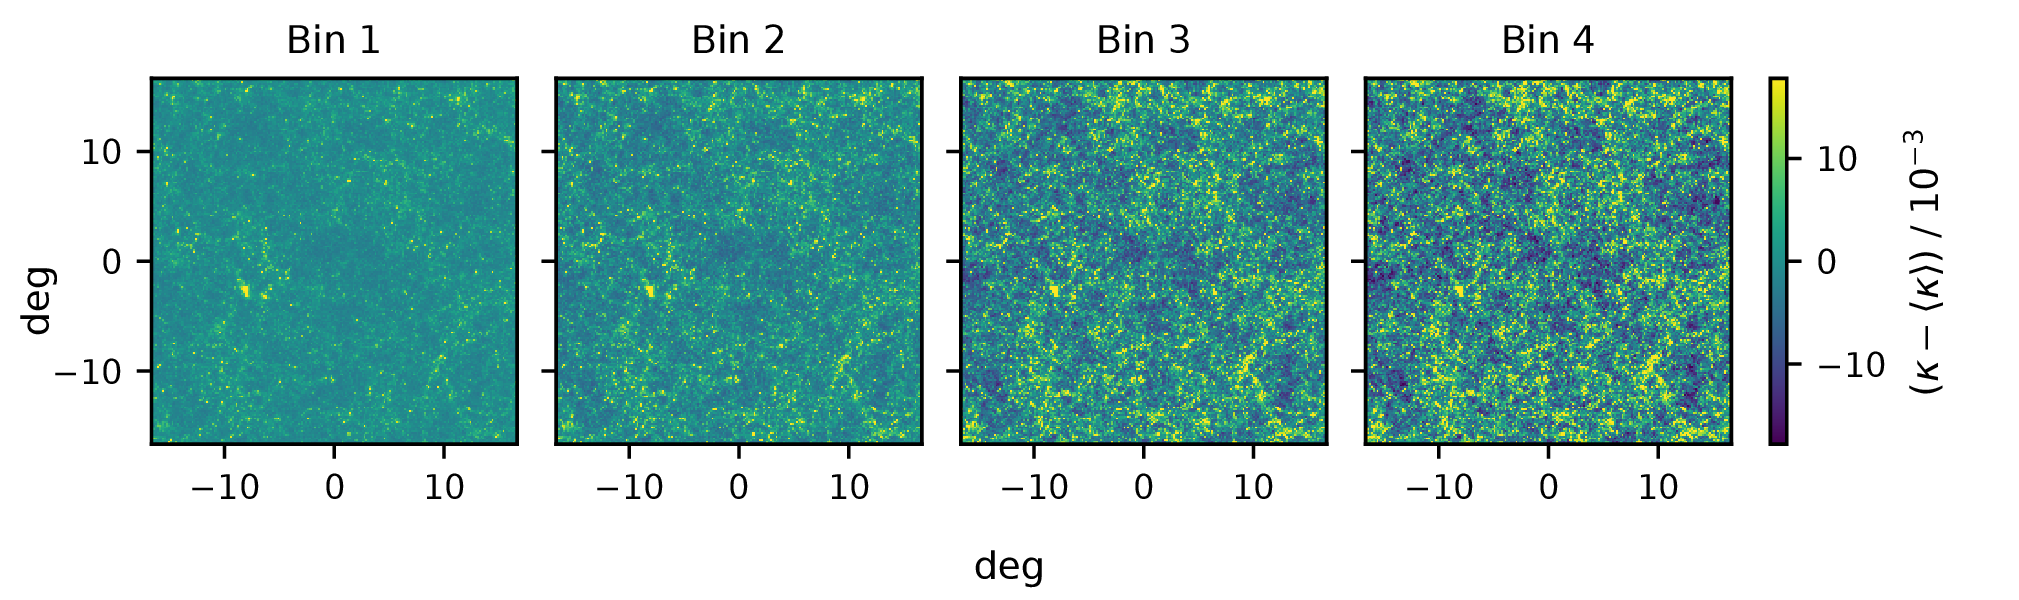
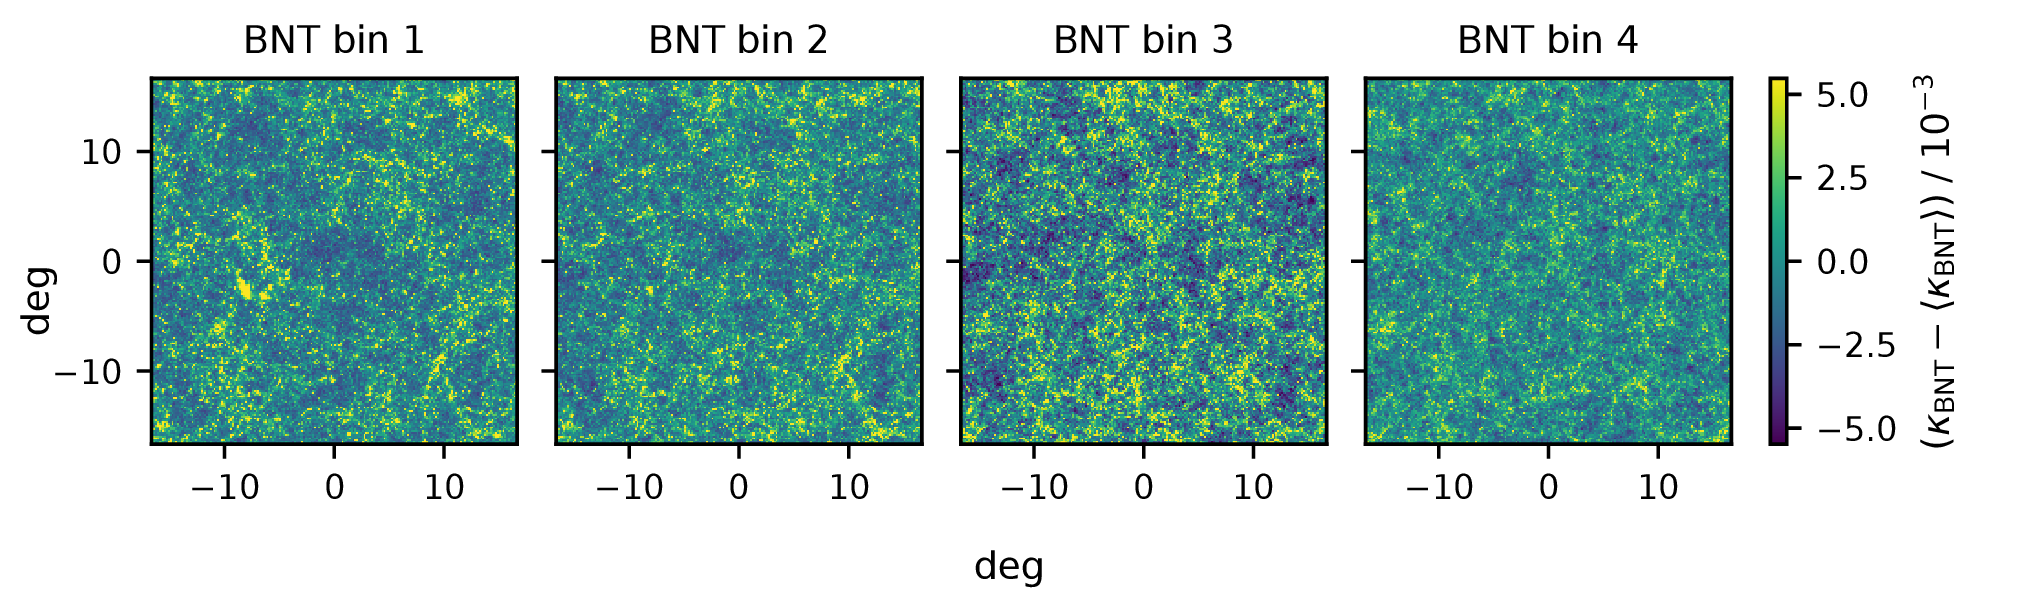
Without shape noise, BNT is an invertible redistribution of the signal (the common mode becomes one shallow map plus thin slices). The contour inflation comes from the correlated noise, not from lost signal.
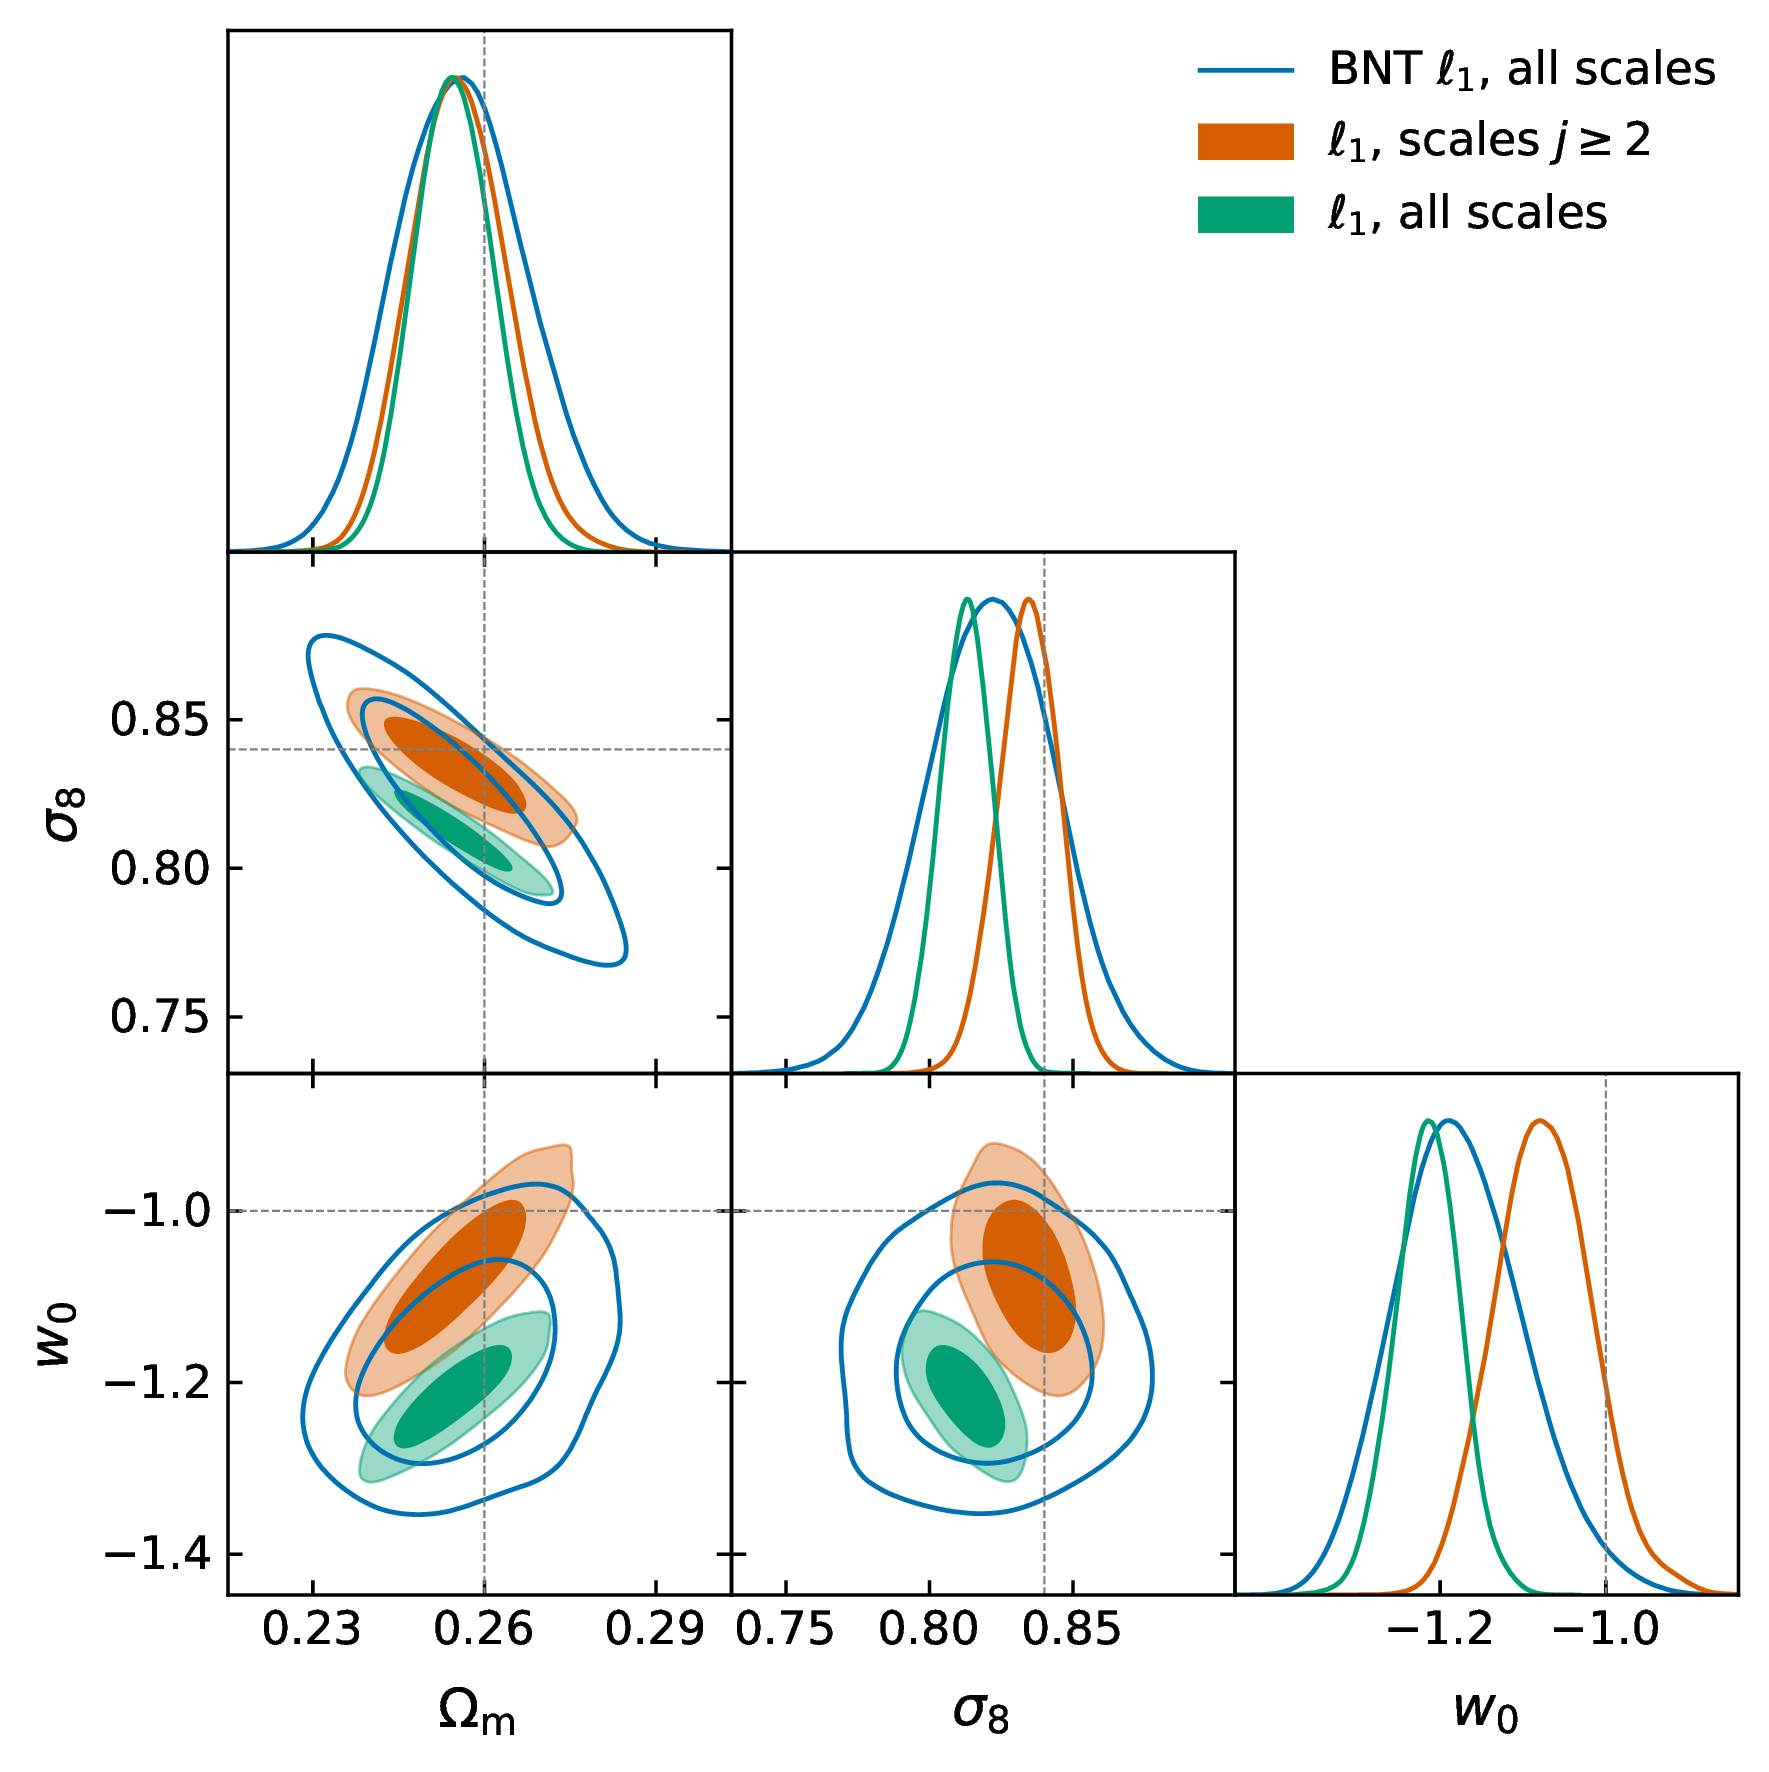
Outlook: a route to baryon-robust non-Gaussian SBI that keeps BNT's per-bin scale cuts without the contour inflation. A next step rather than a finished end-to-end measurement.
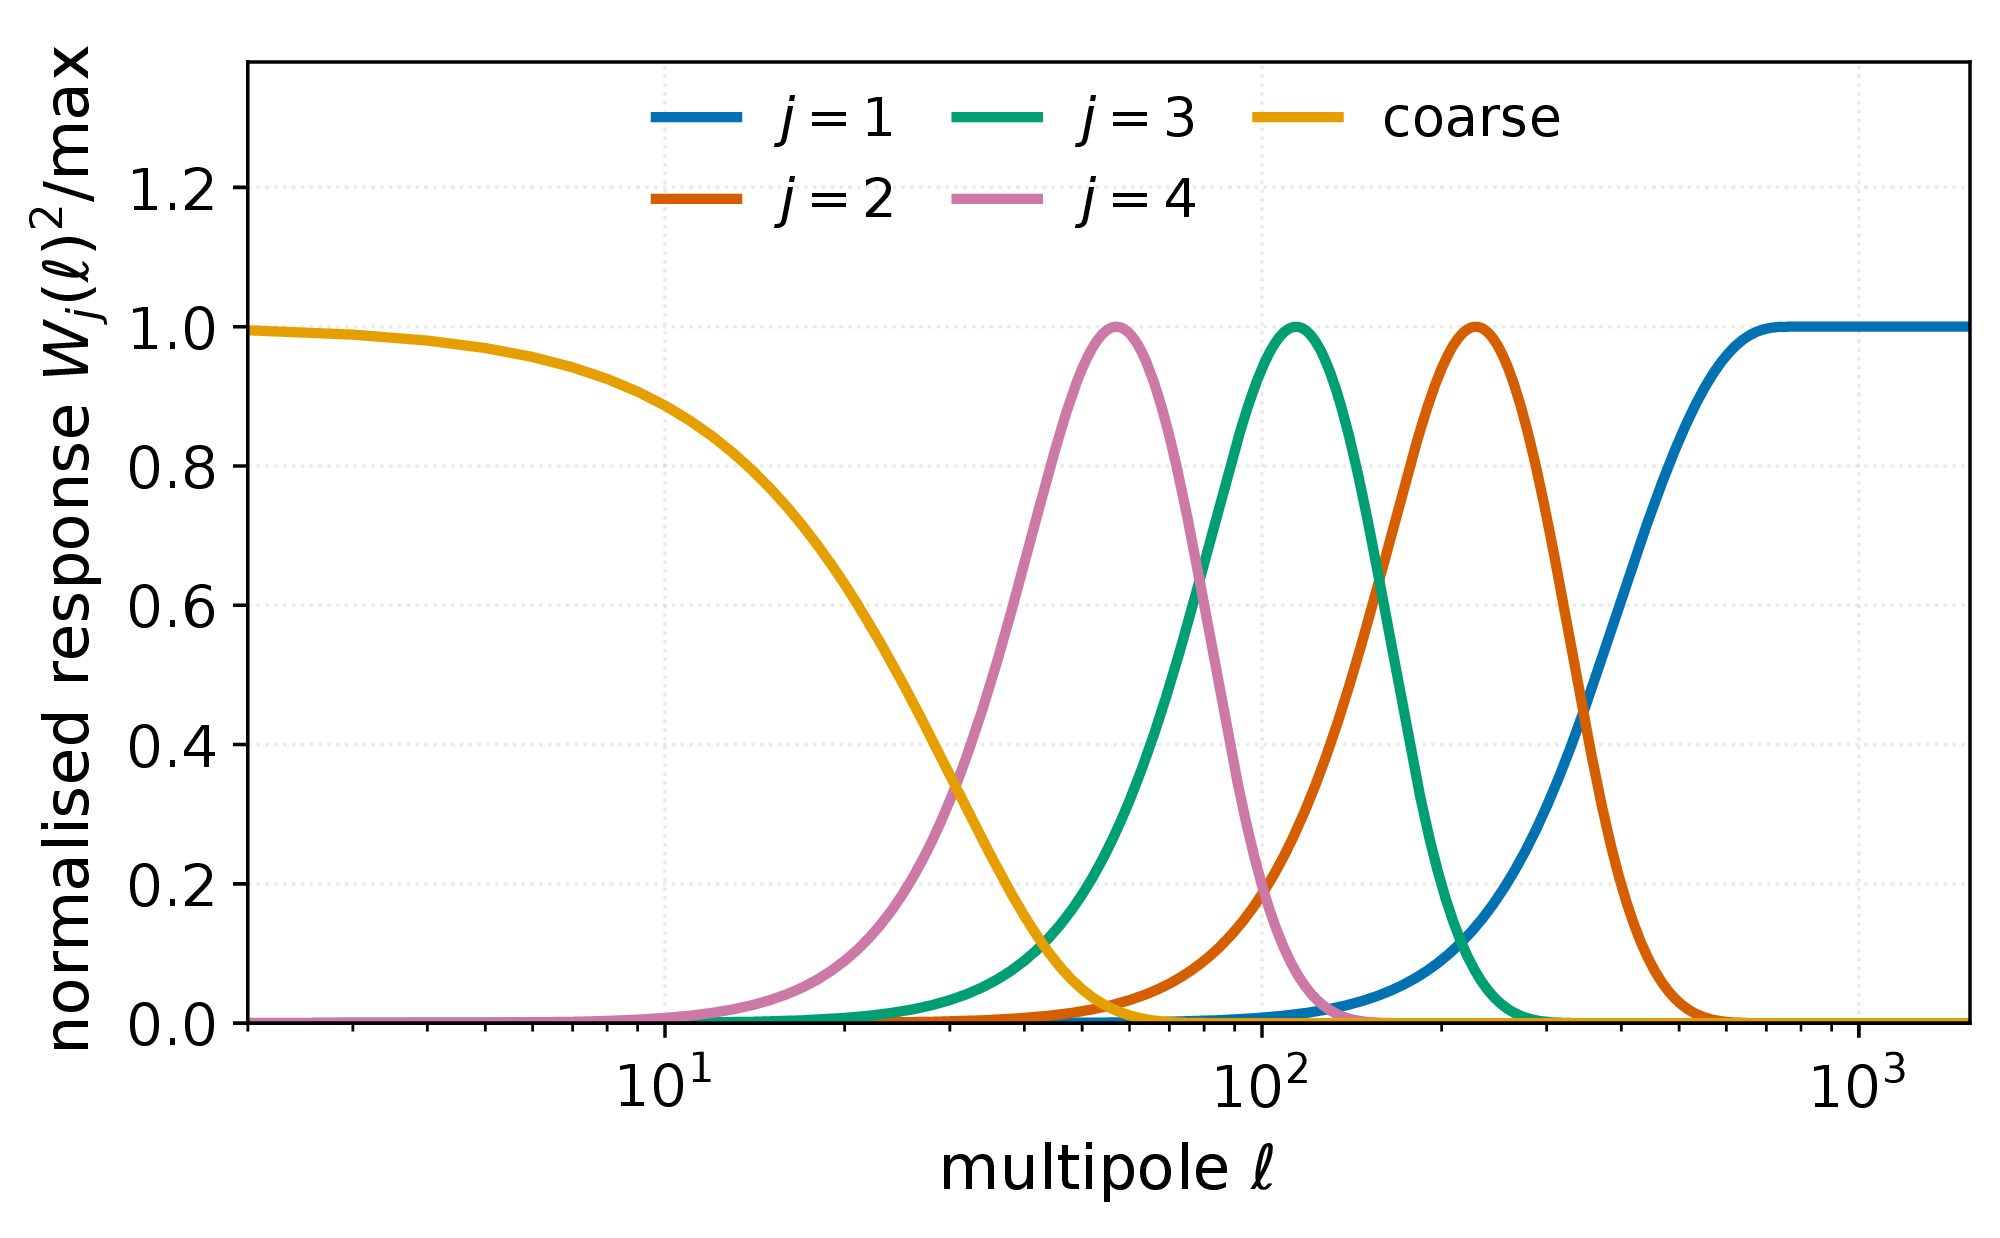
This is what "drop $j=1$" removes: the highest-frequency band, everything above $\ell \approx 500$. The other bands are untouched, at every survey area.
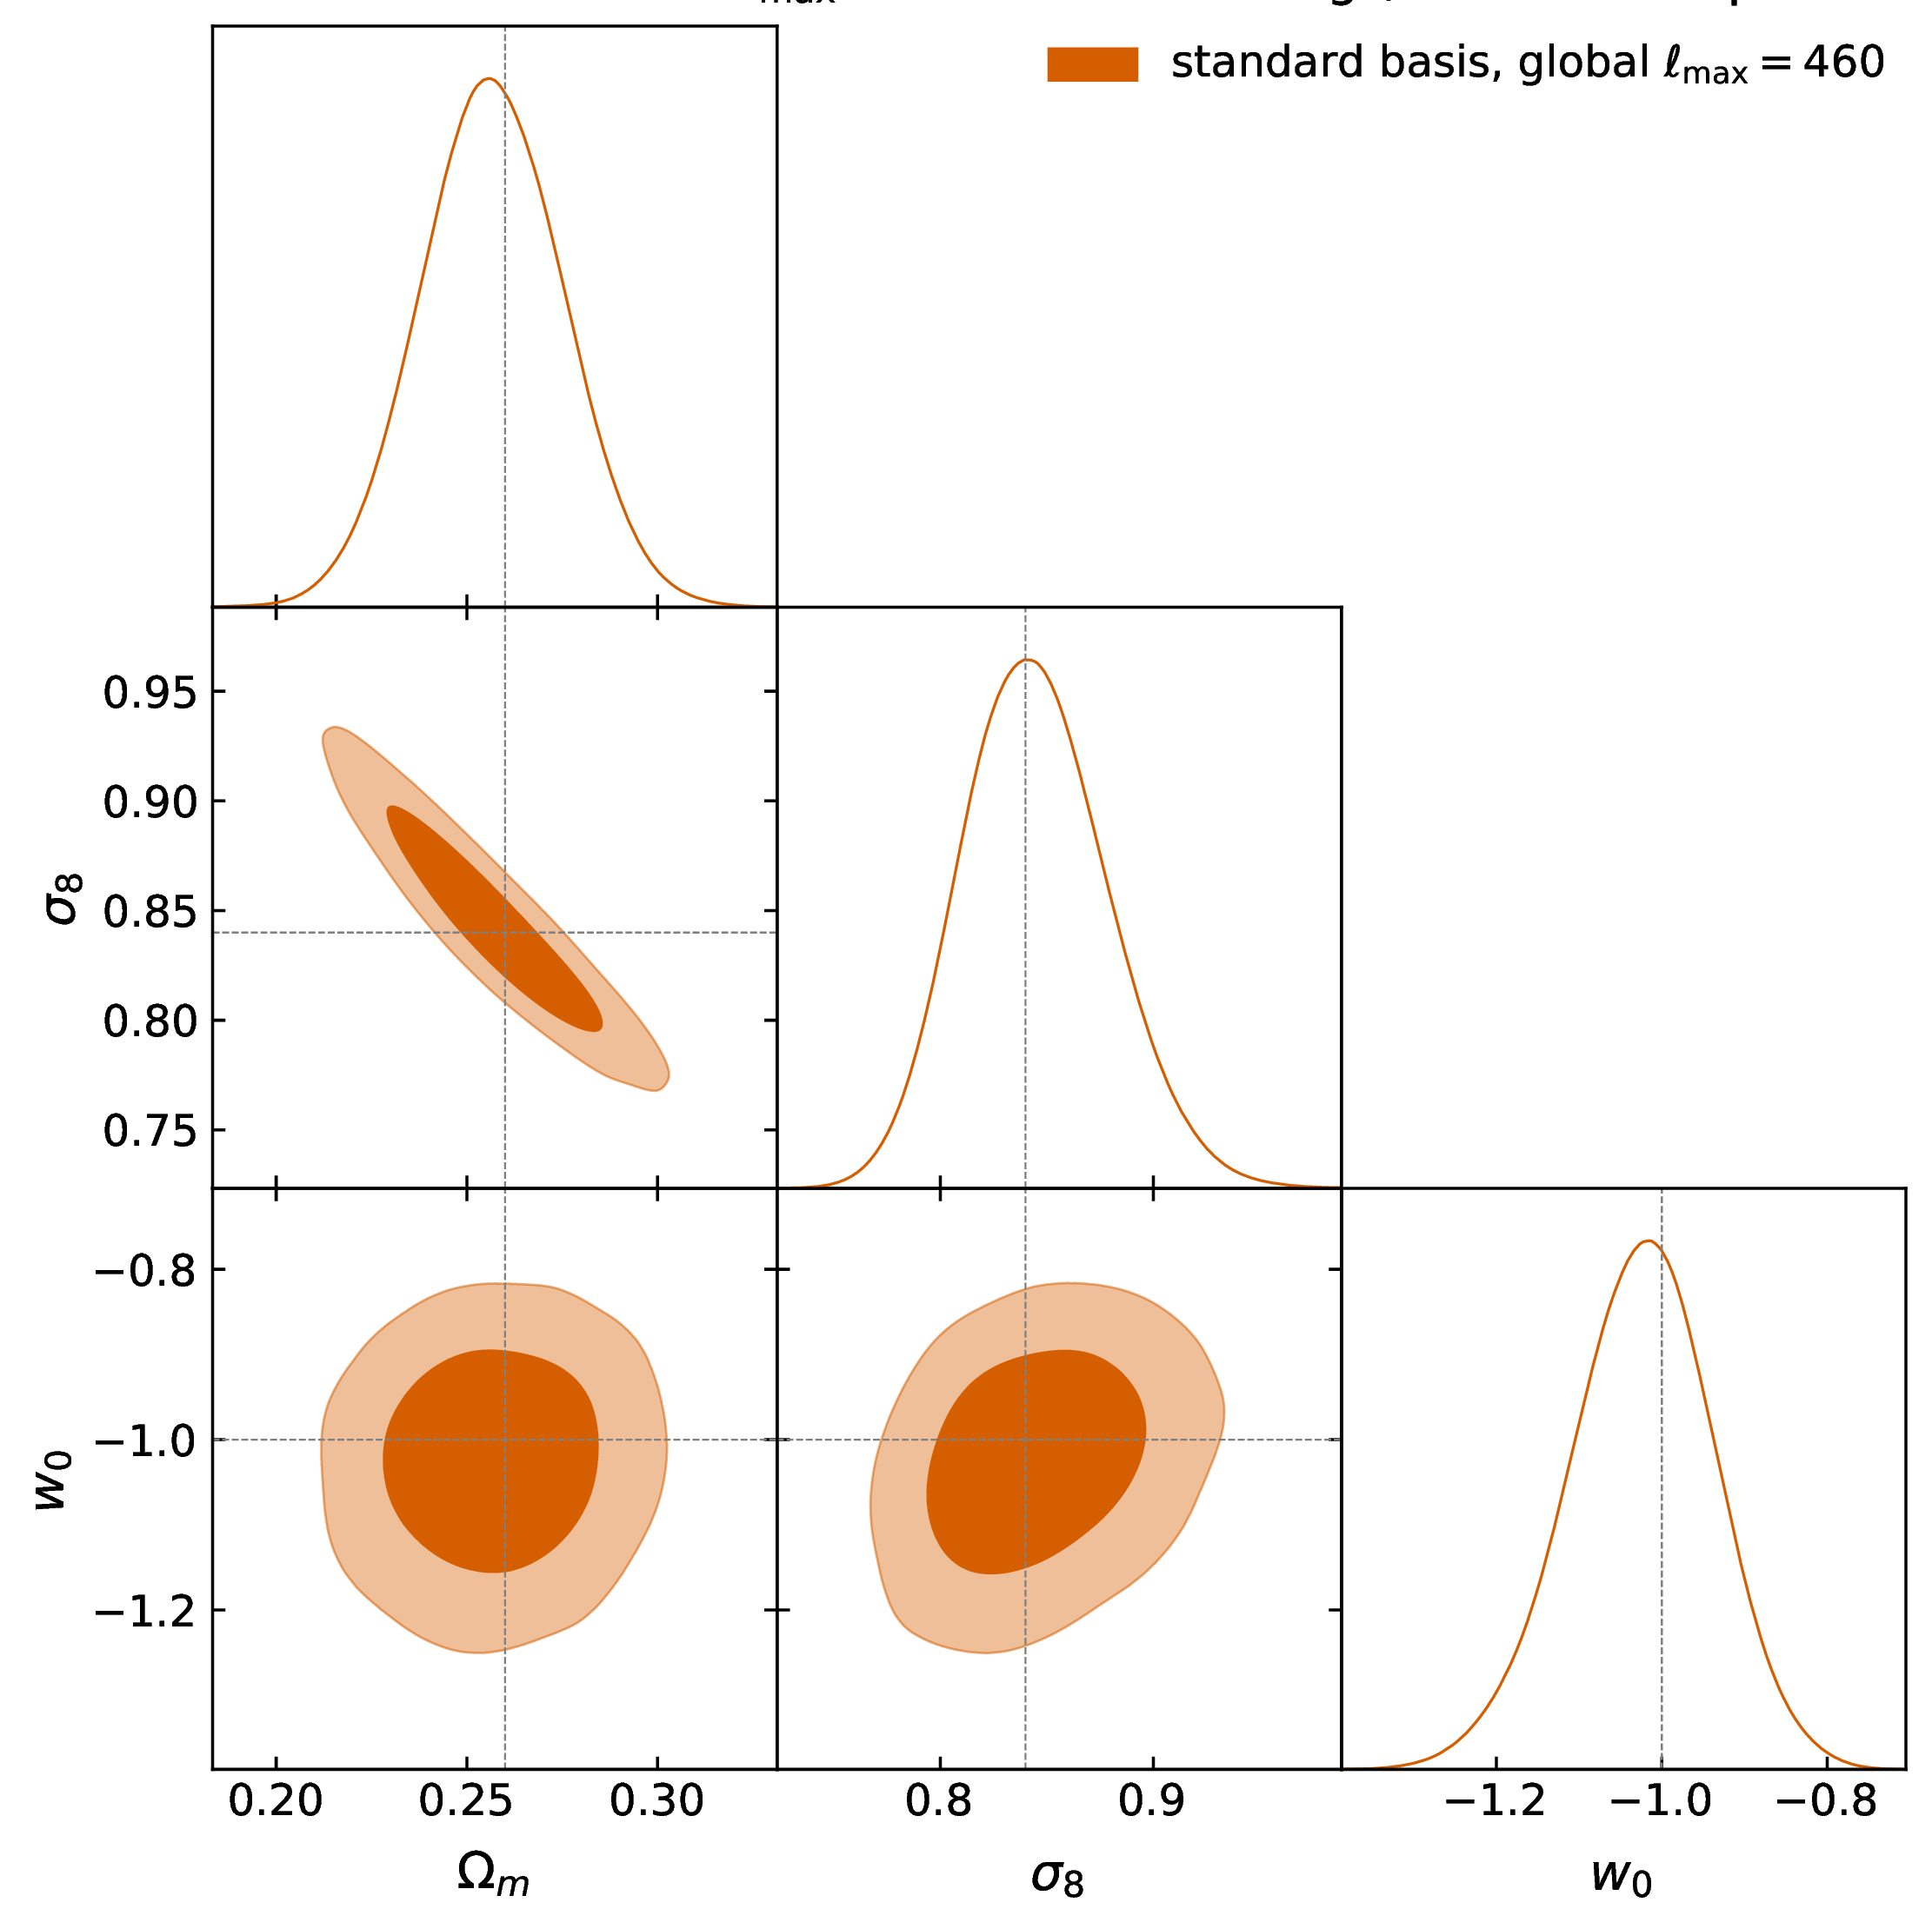
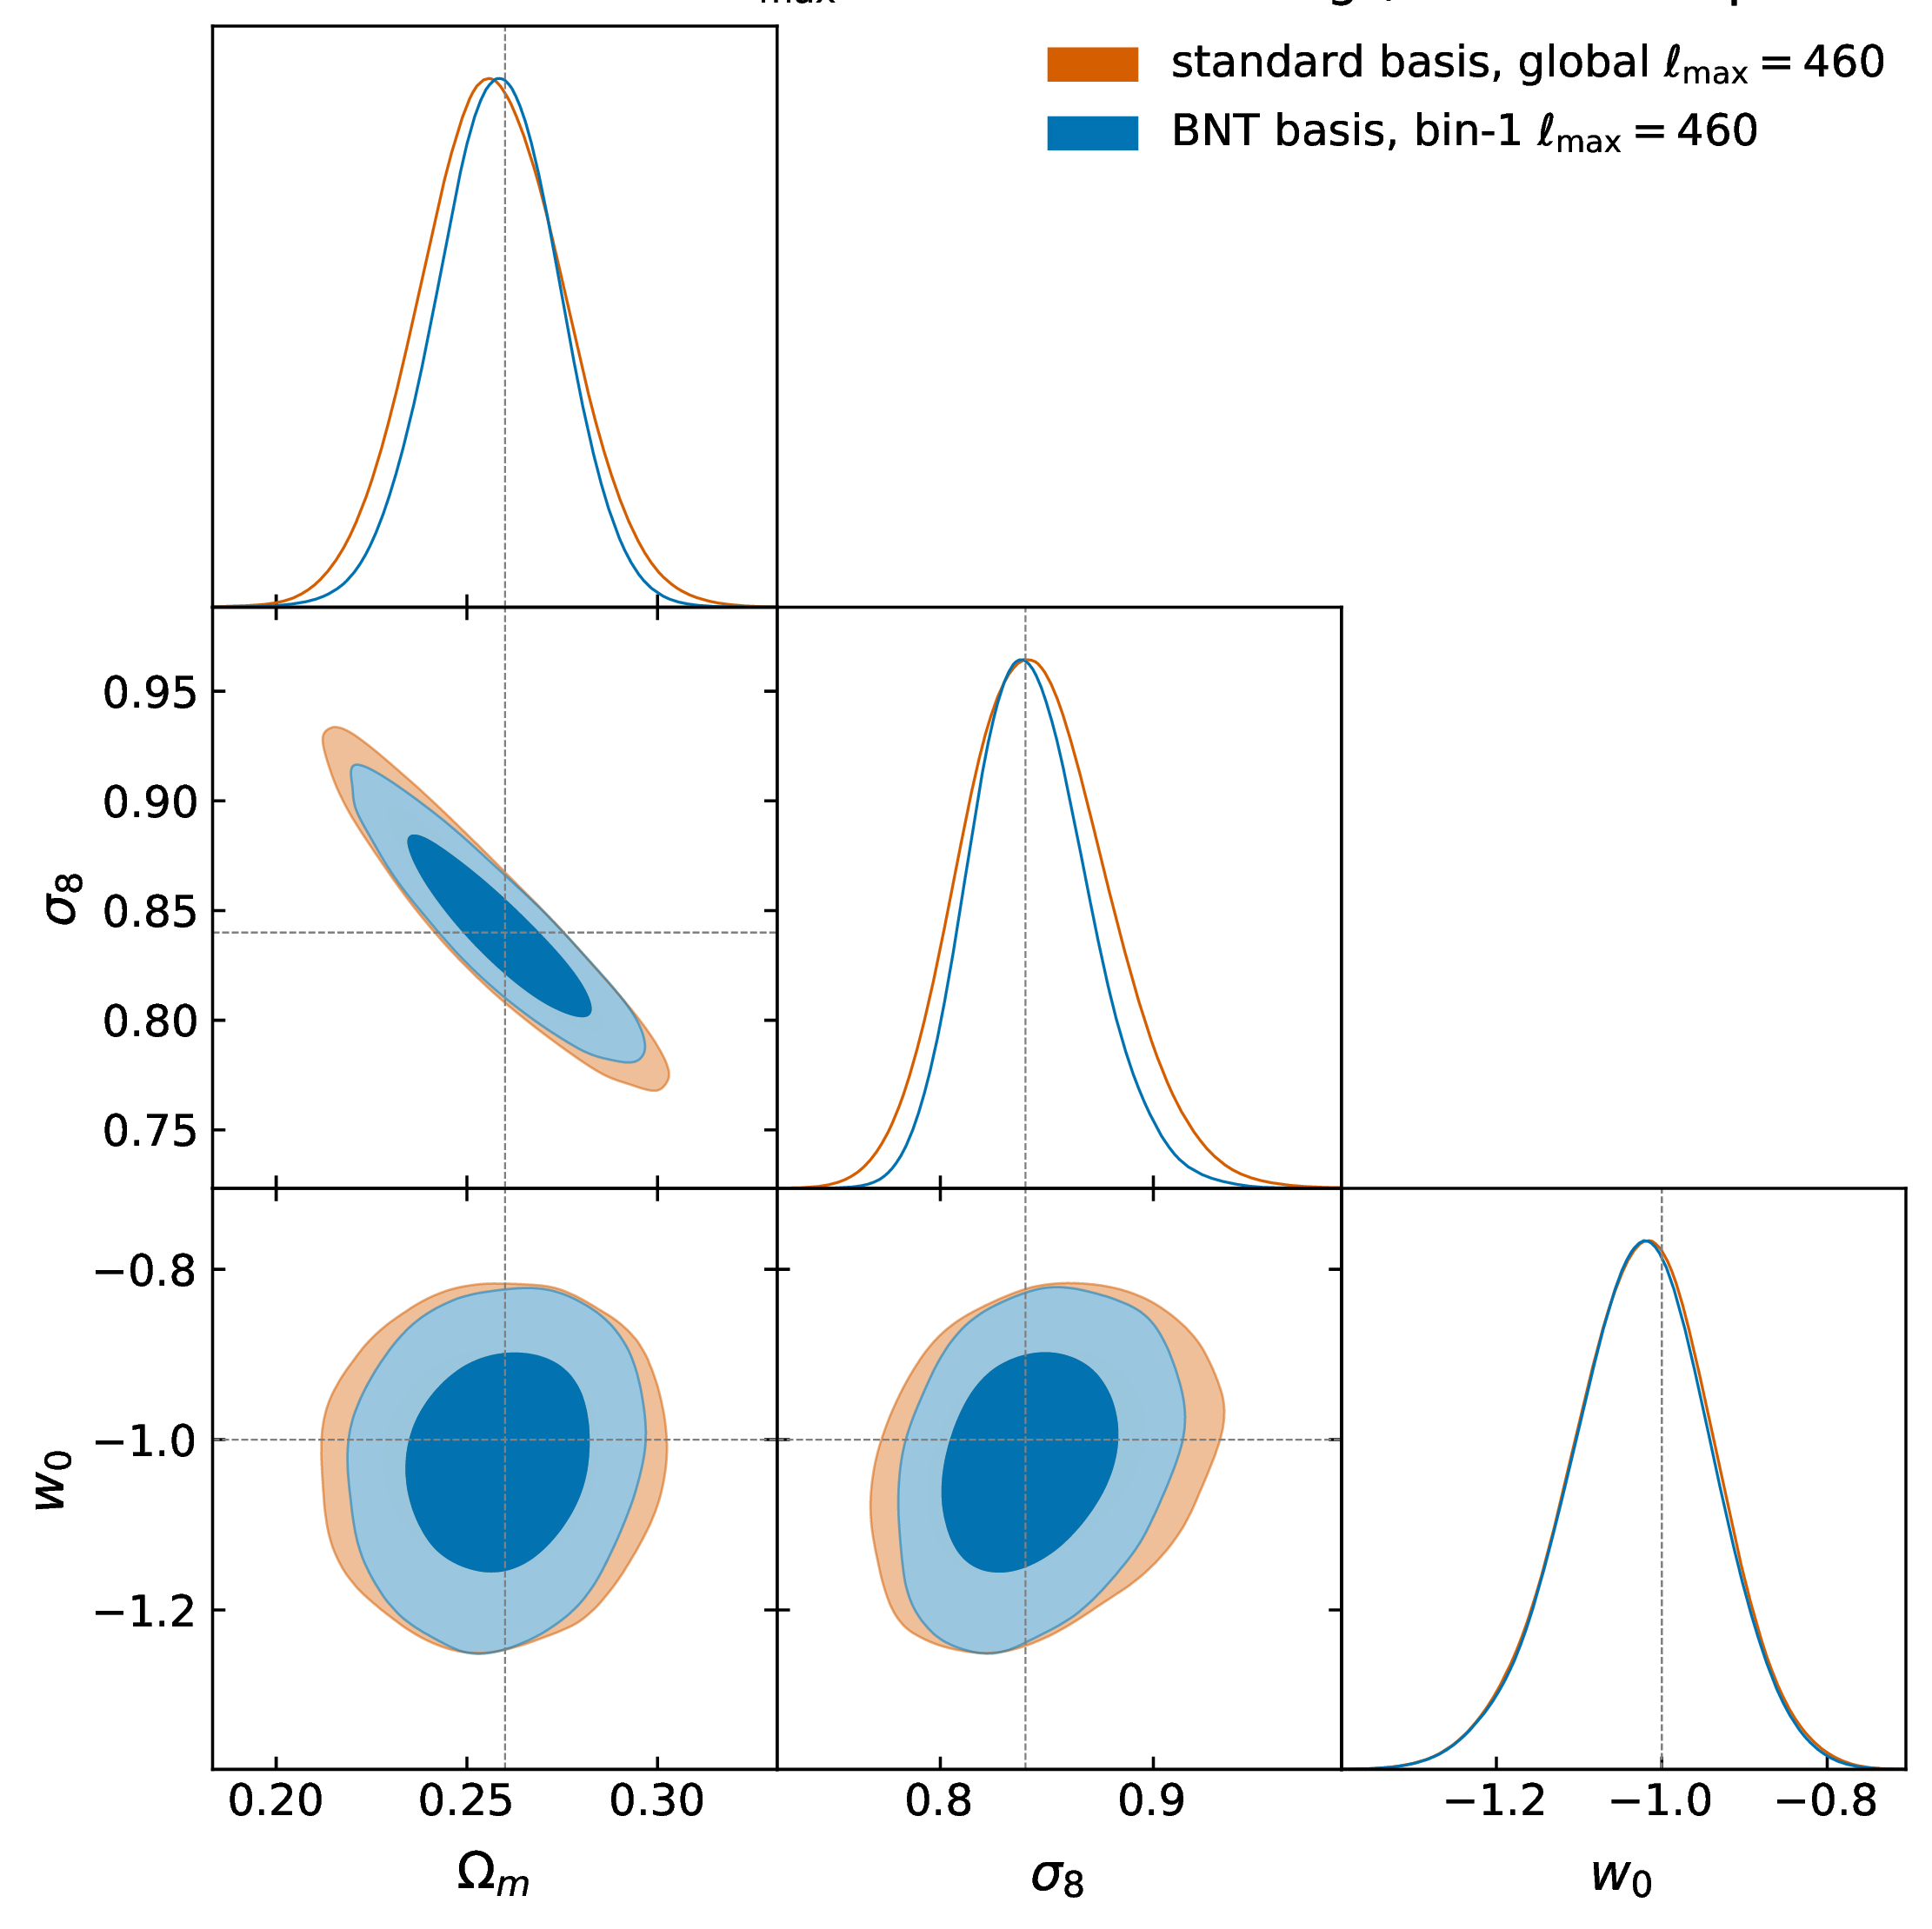
Baryon sensitivity localises to the first transformed bin, so the cut goes there alone and bins 2–4 keep $\ell_{\rm max} \approx 1024$: 92 of 120 bandpowers retained against 50 for the global cut. σ(Ωm) −14%, σ(σ8) −19%.
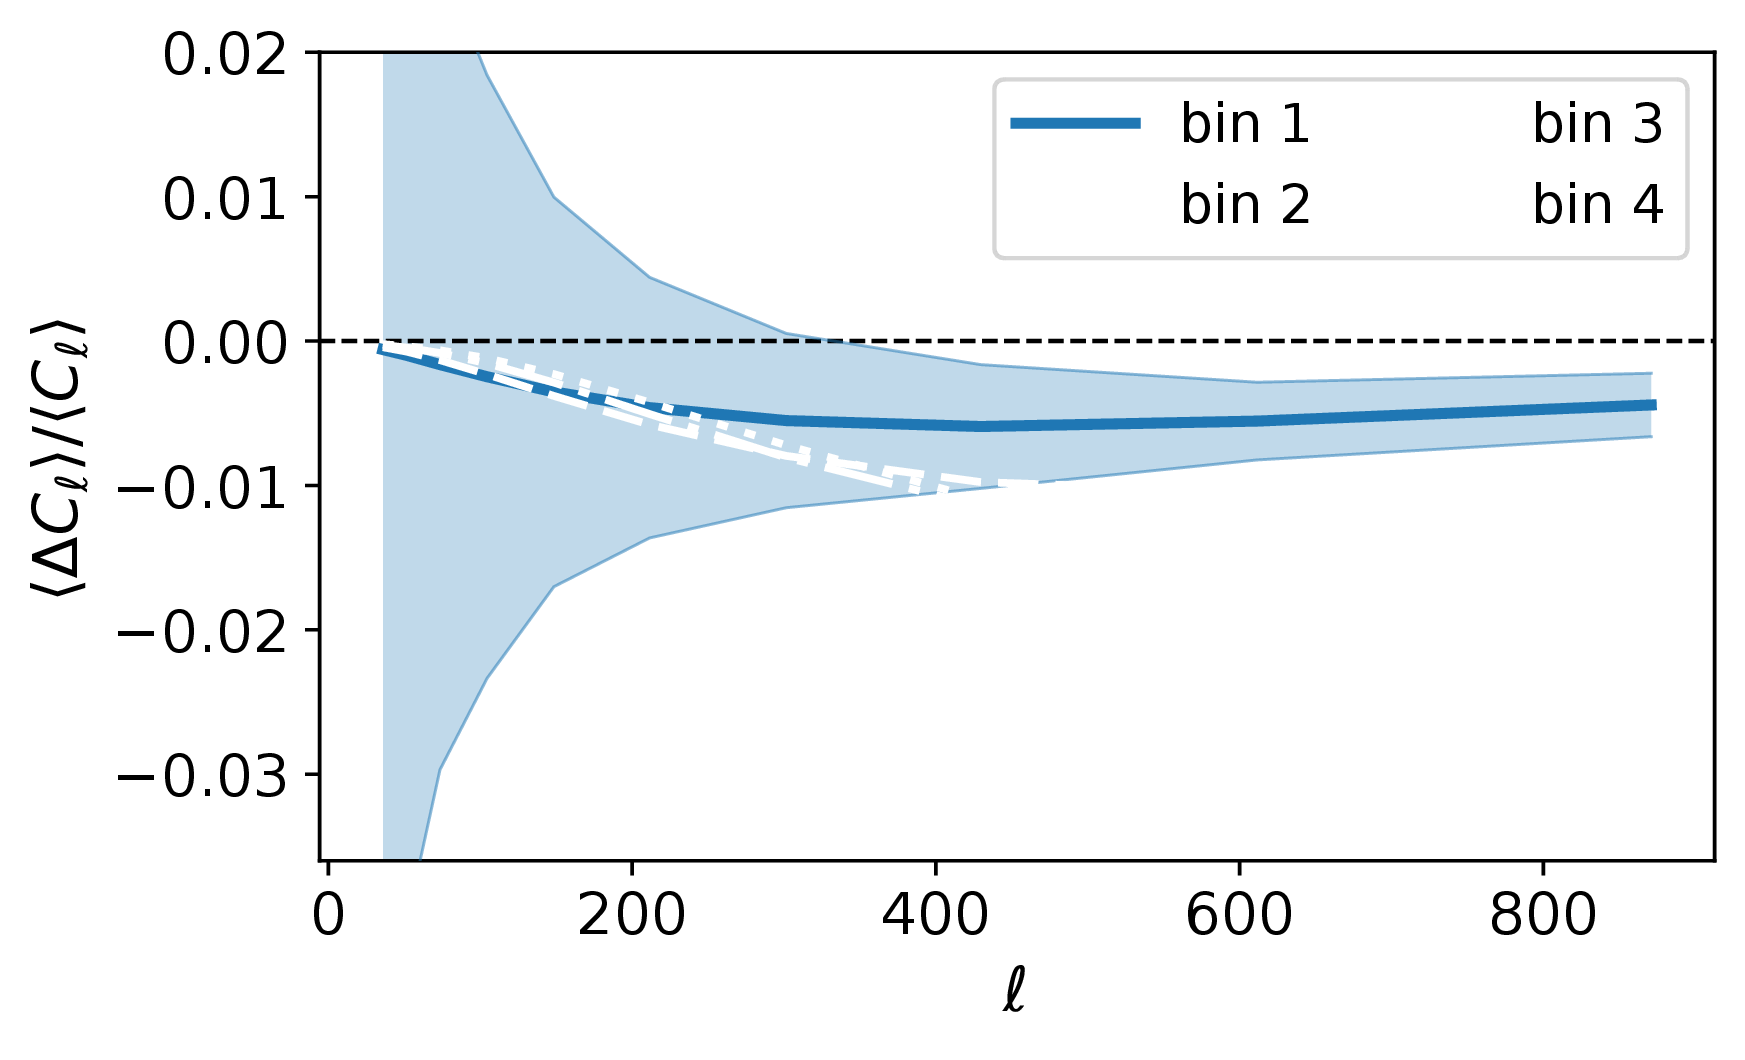
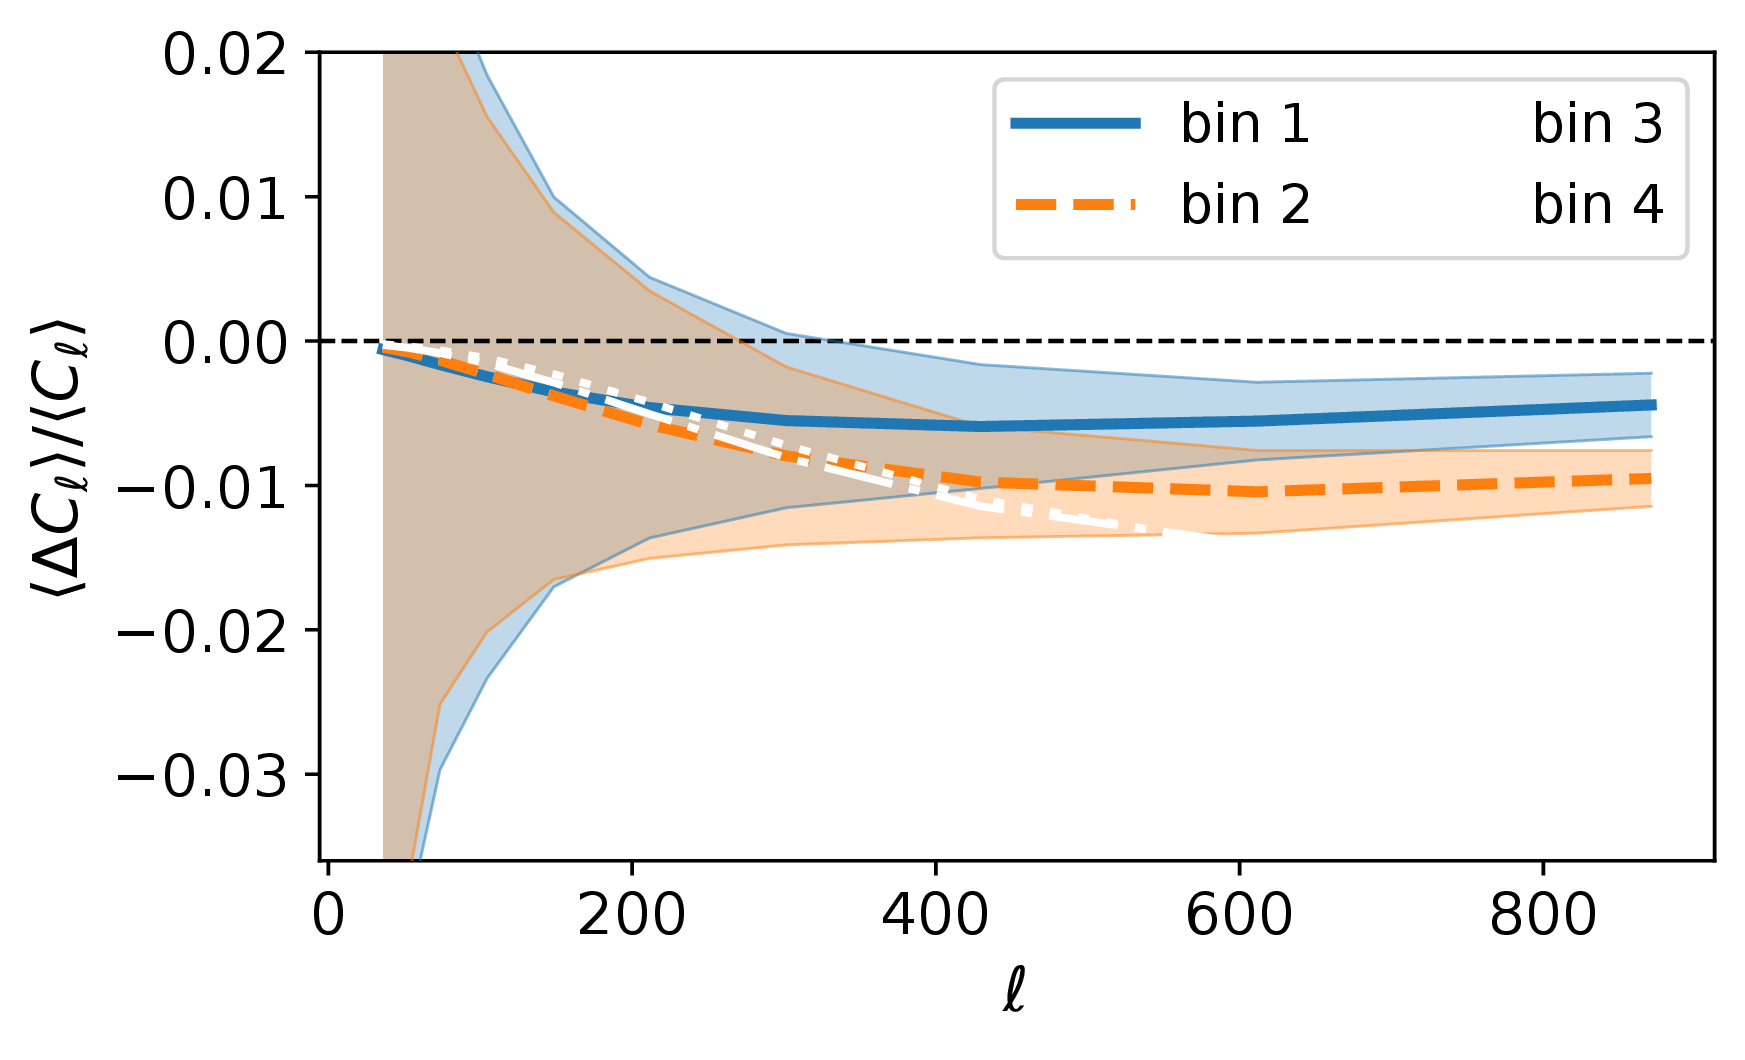
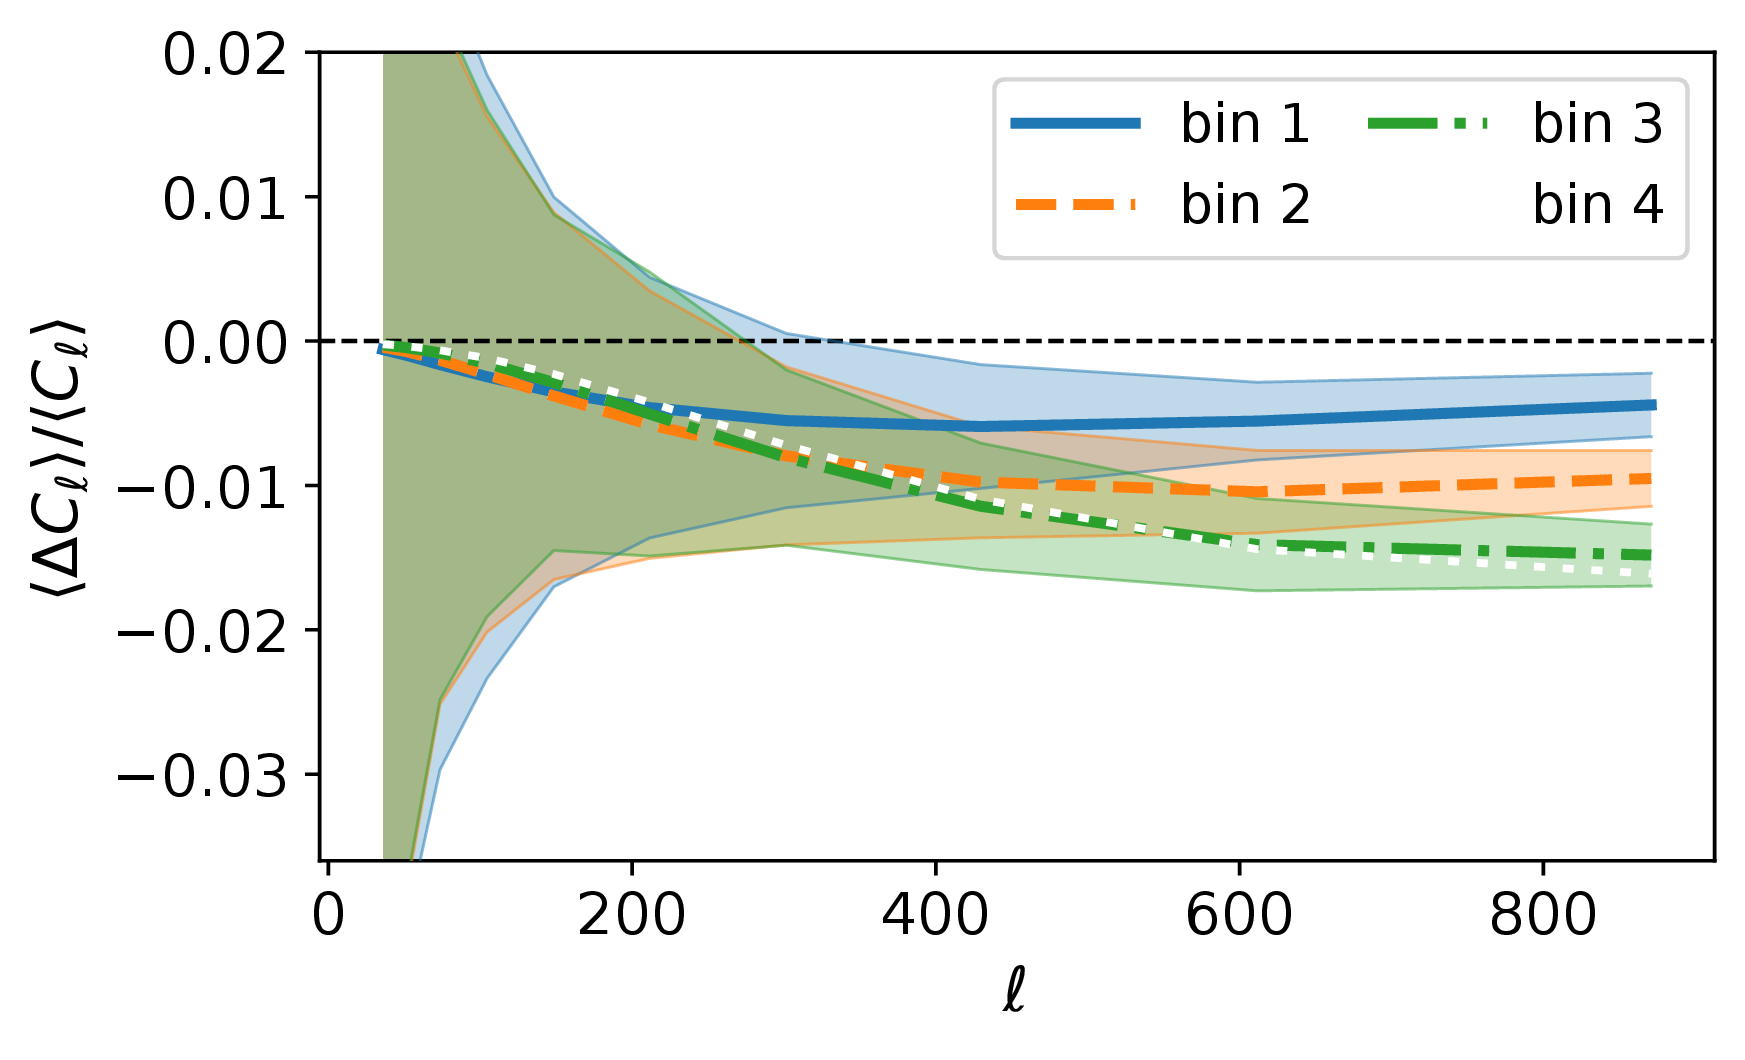
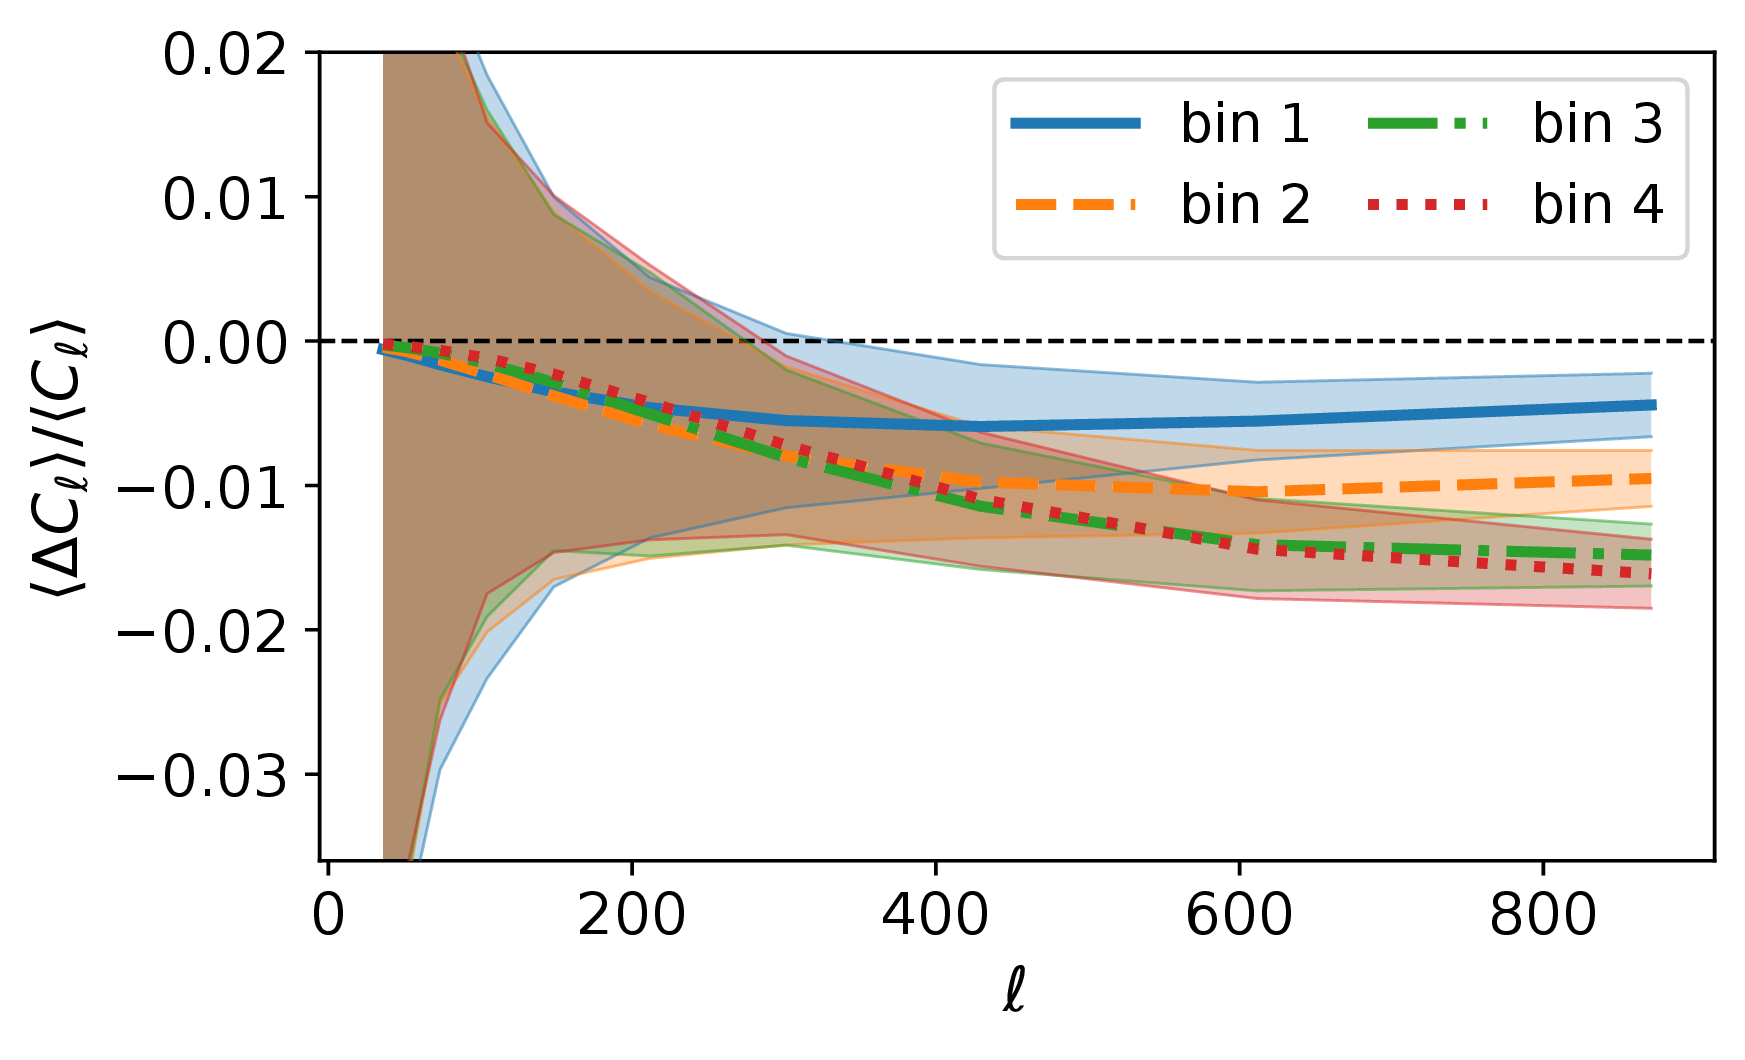
Reaches ≈1.5% by $\ell \approx 1000$. The apparent "high-z bins are worse" ordering is a noise artefact: the noise power dominates the denominator at low z. On noiseless maps the ordering inverts to the physically expected one.
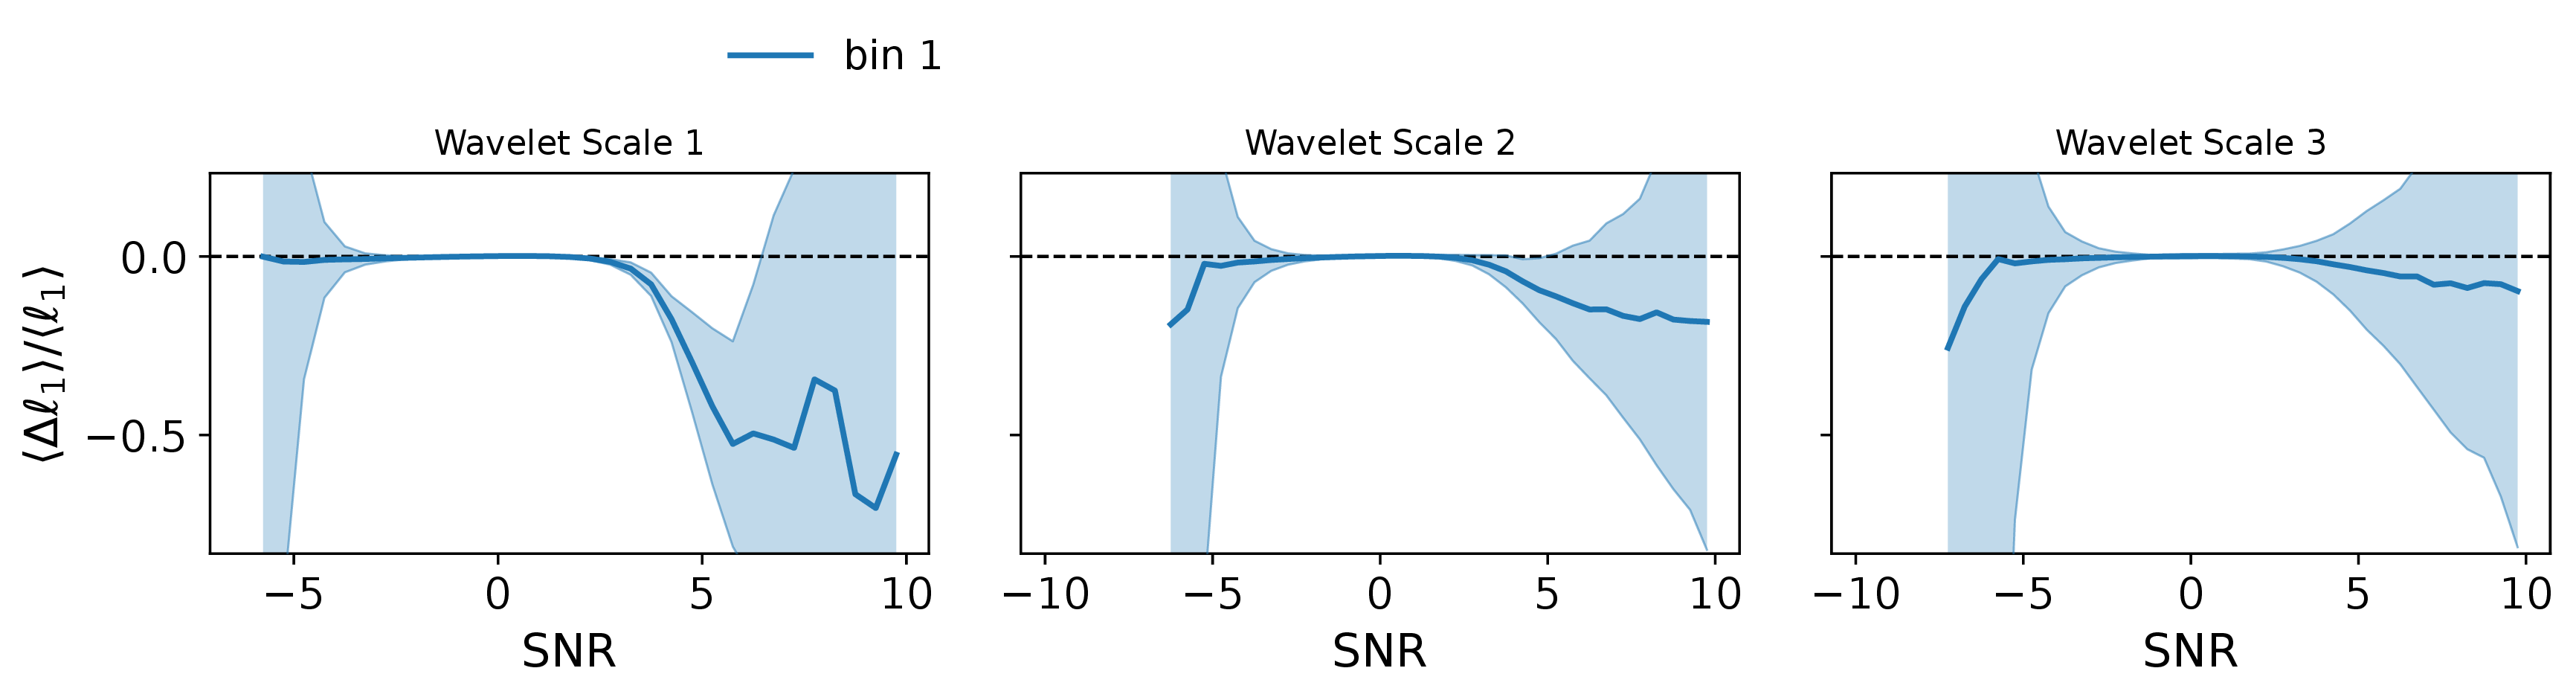
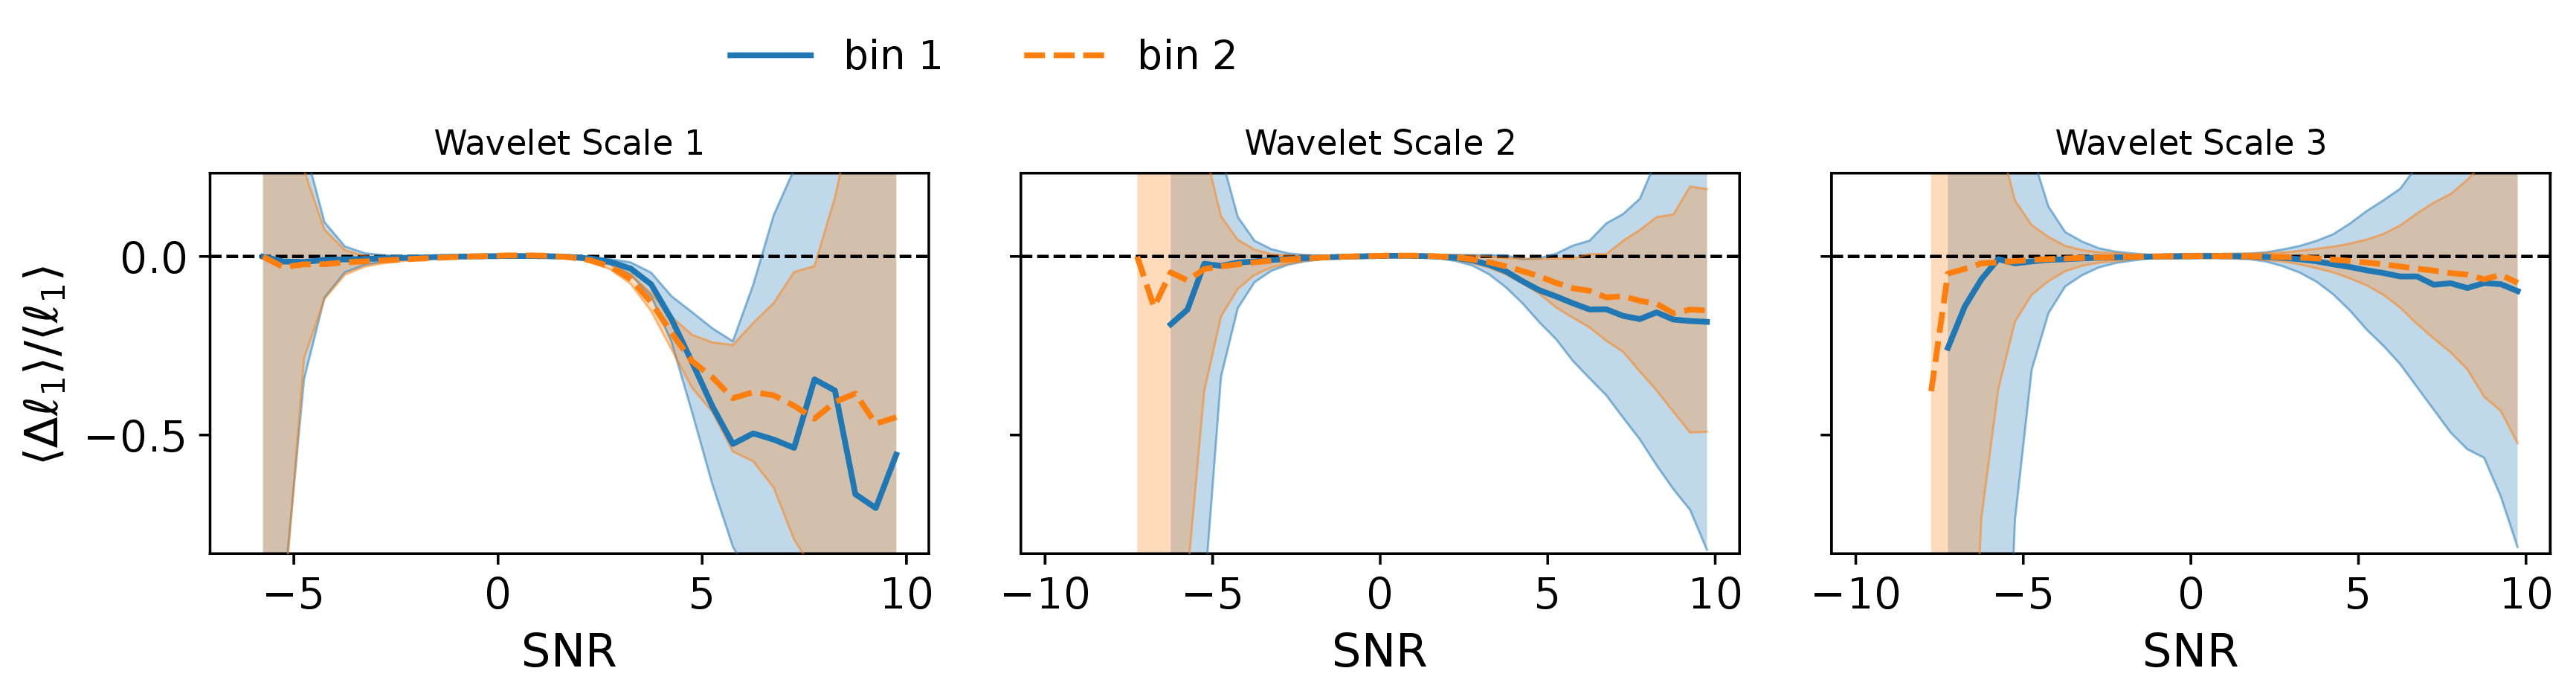
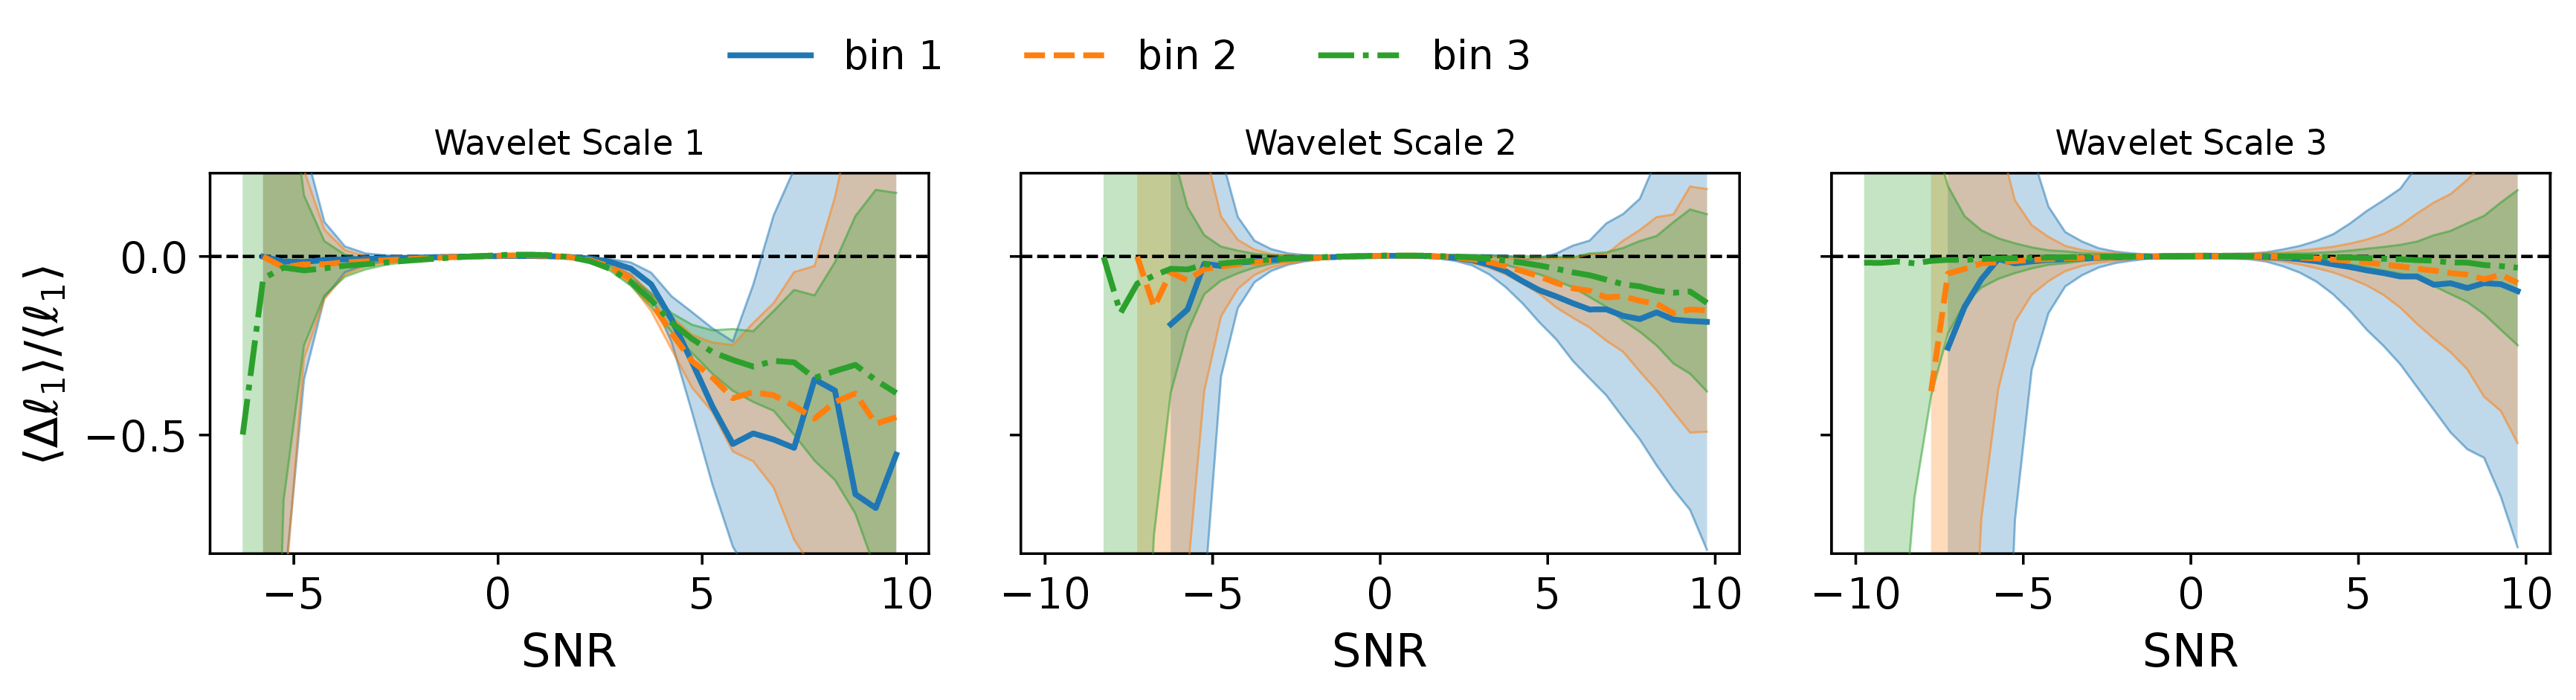
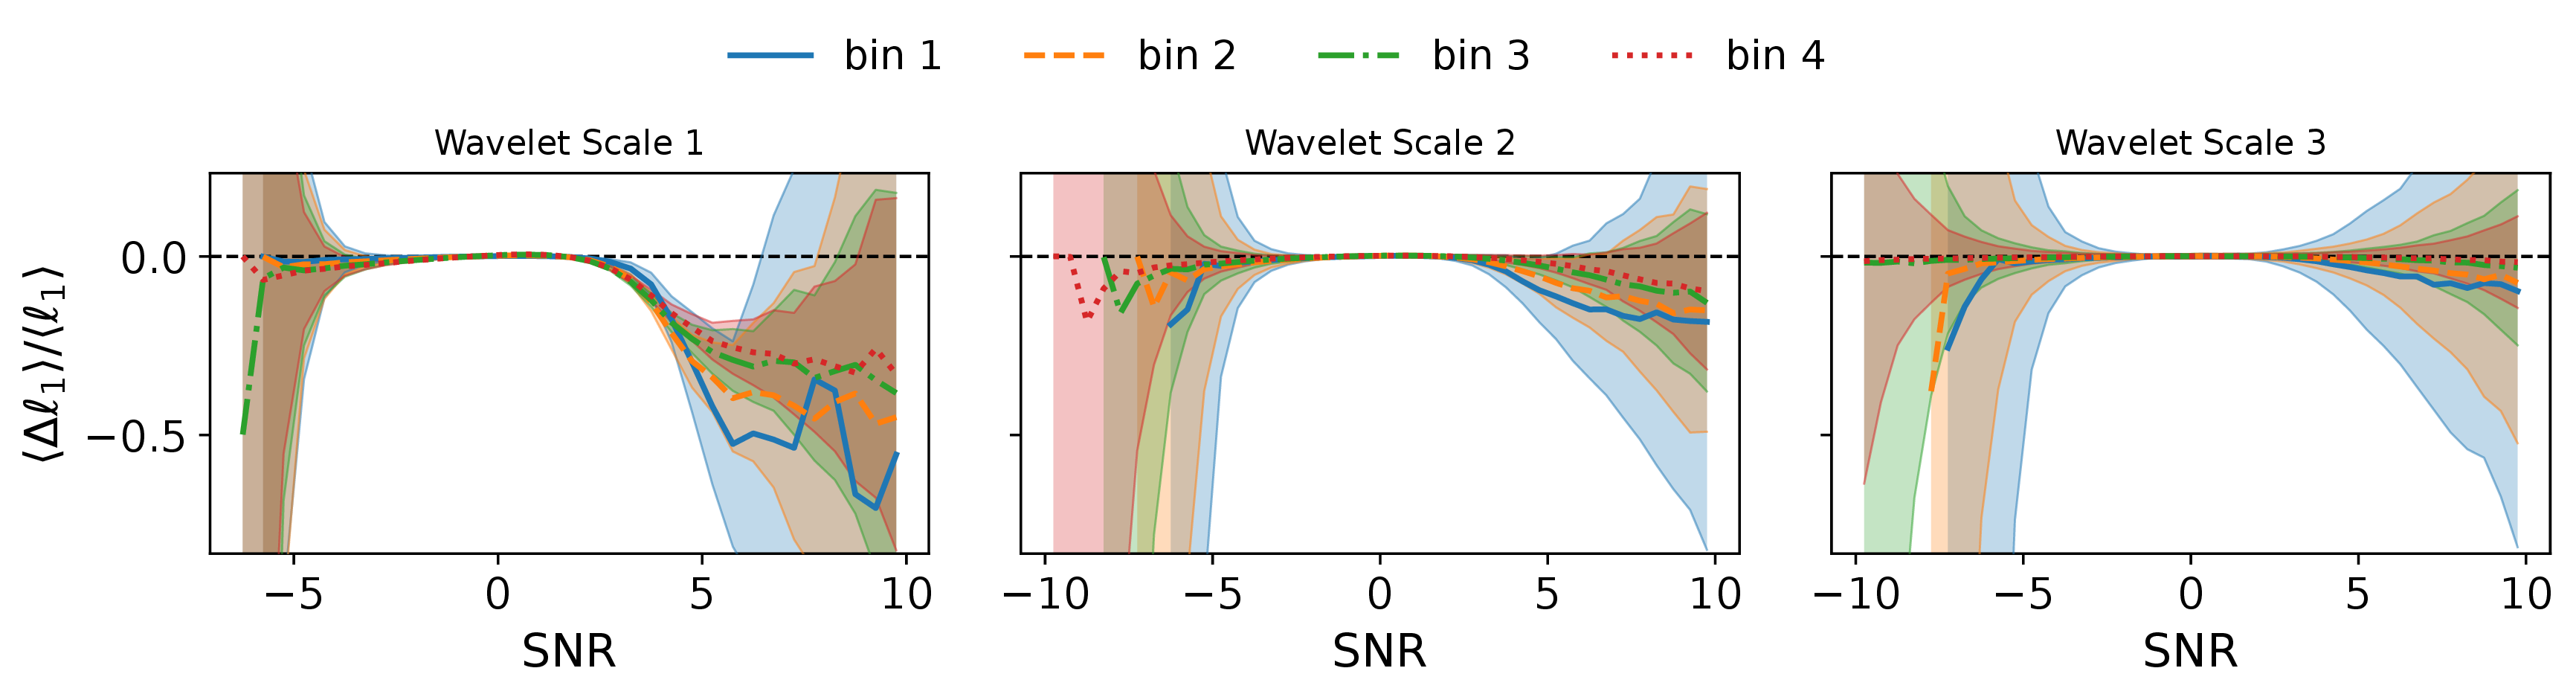
Concentrated in the positive SNR tail, and vanishing in the noise-dominated bulk ($|\nu| \lesssim 2.5$). That is why an SNR-space cut is available to higher-order statistics and not to the power spectrum. Left to future work in the paper.
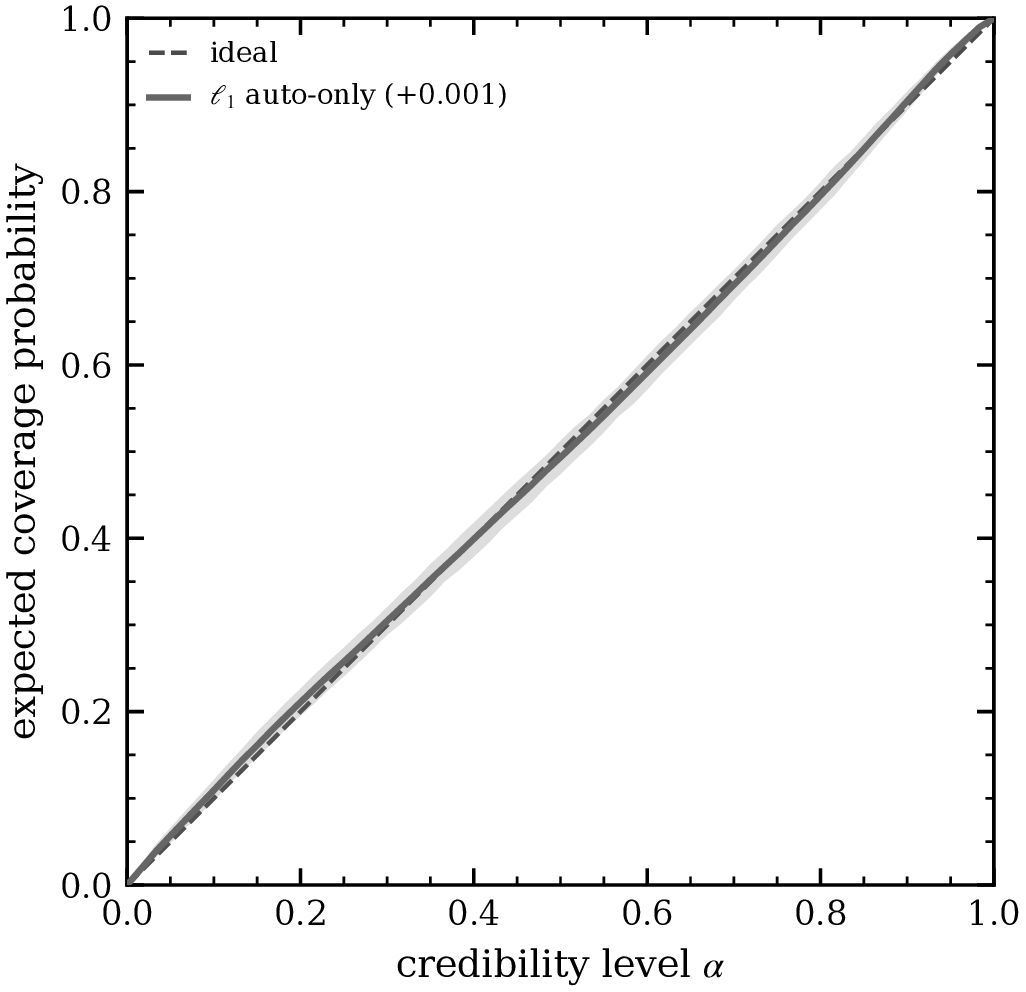
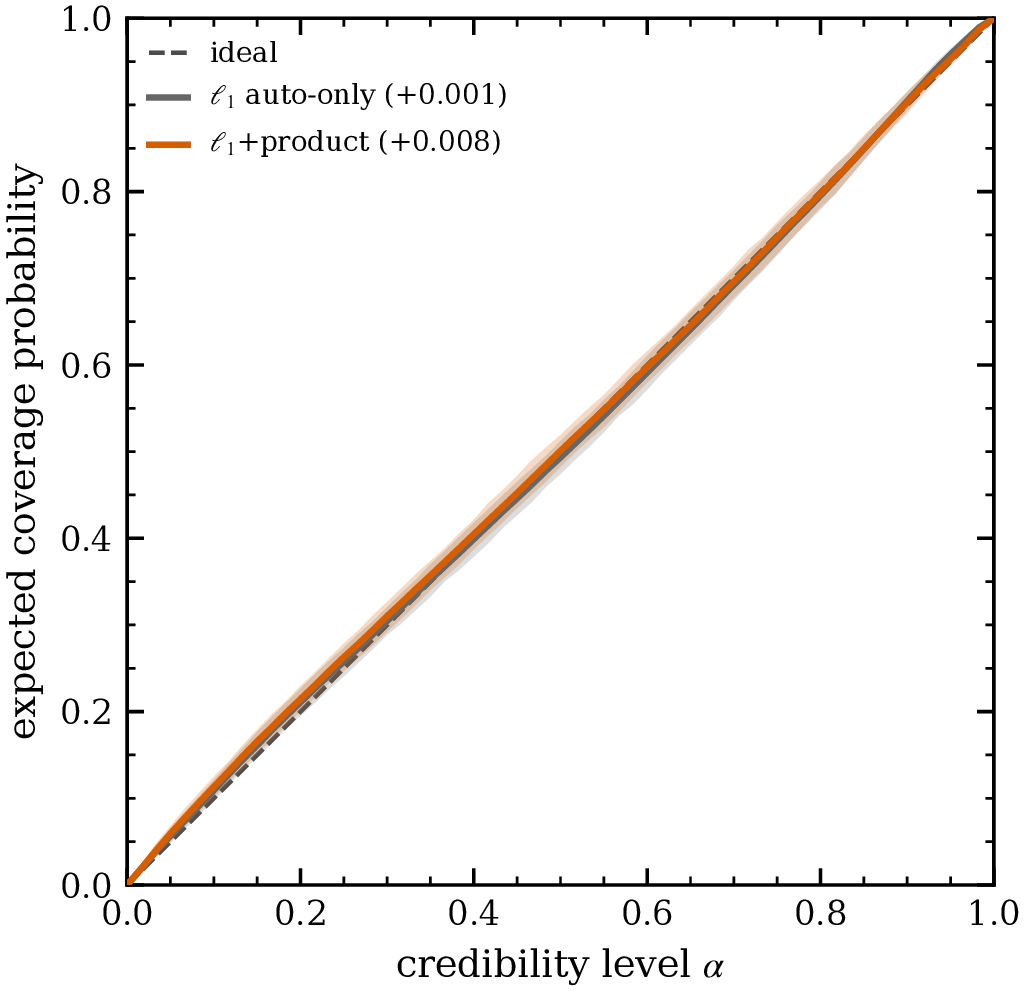
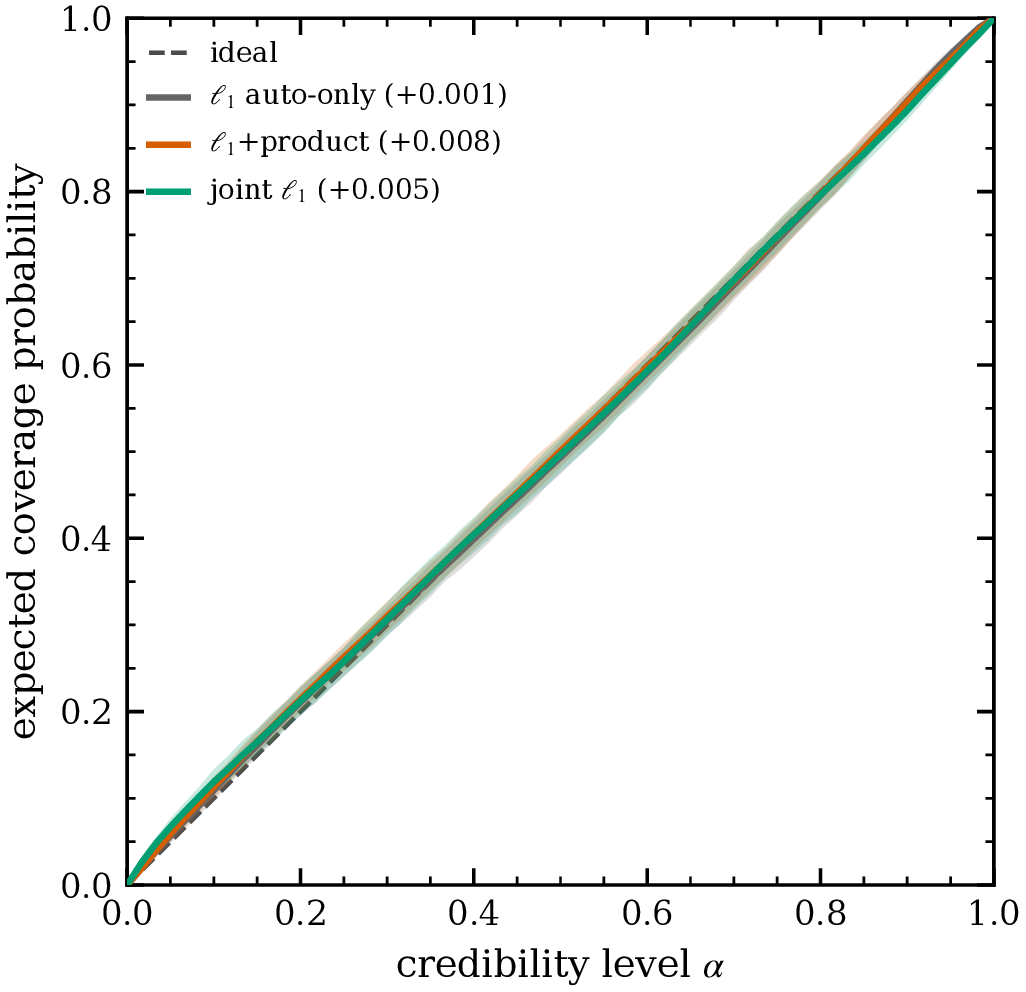
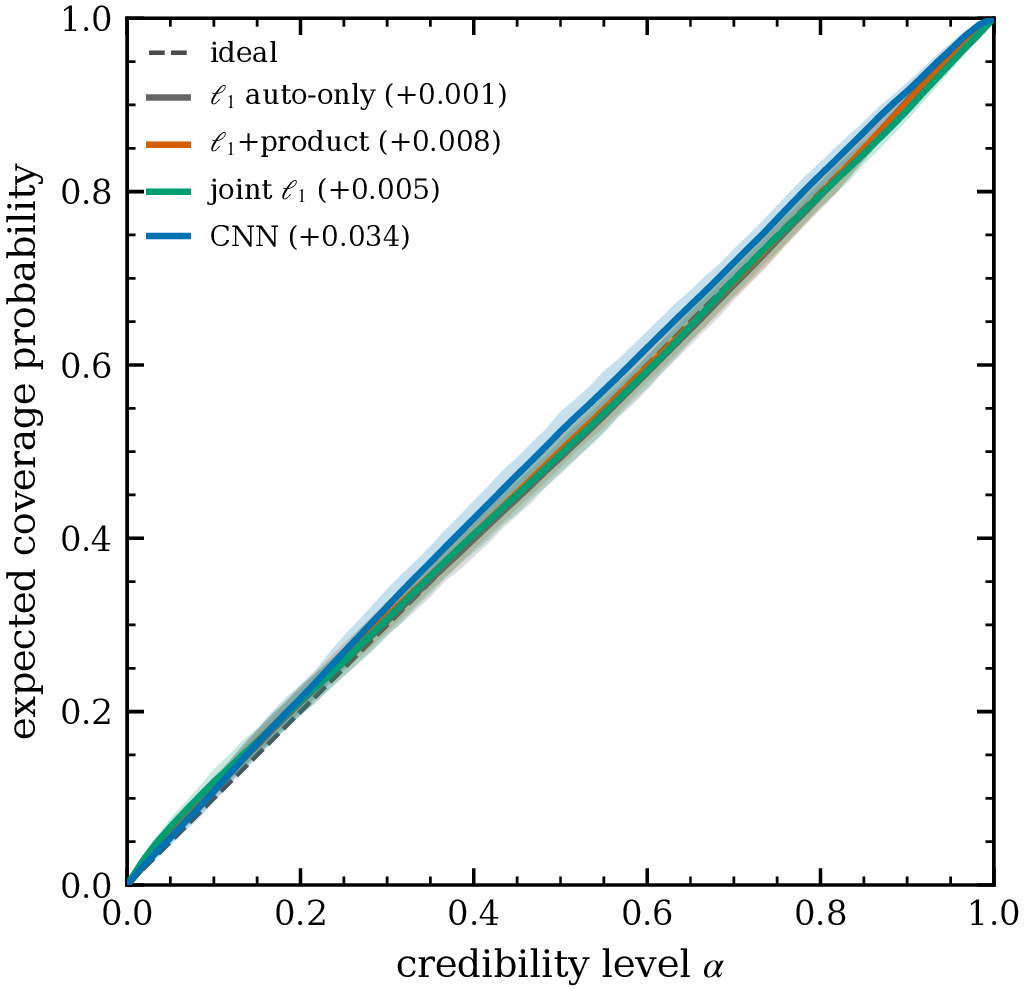
The collapse is calibrated: the wide contours report a real loss in that representation, not over-confidence. So the retention ladder measures information, not the quality of a fit.
Baryonic feedback is Part 4. These are the rest.
| systematic | what it is | how it is handled |
|---|---|---|
| intrinsic alignments | galaxies align with the tidal field, so shapes correlate without any lensing | 2pt: NLA, TATT. HOS: open |
| photometric redshifts | $n(z)$ from colours, not spectra. Stage IV needs $\bar z$ per bin to 0.002 | shift and width nuisances |
| shape measurement | PSF modelling, multiplicative and additive shear calibration, blending | calibrated on image simulations |
| masks and geometry | Kaiser–Squires is non-local, so gaps leak across the map: spurious peaks and B‑modes | inpainting, regularised mapping |
| covariance | no closed form for HOS. Hartlap factor, super-sample covariance | large simulation suites |
| source clustering | sources are assumed unclustered, and uncorrelated with the lenses | sub-percent for 2pt |
Every one of these is better understood for the two-point function than for higher-order statistics, and all of them bite hardest on the small scales where HOS earn their advantage.
All of it on simulations, deliberately. That is the first thing to change.
Not specific to lensing: a trained denoiser in a proximal scheme fits any linear inverse problem with known noise. Galaxy clustering; 21‑cm, where foreground removal sits where mass mapping sits here.
21 slides lifted unchanged from LAM 2026, for Act 0 and the Ch2 backup library.
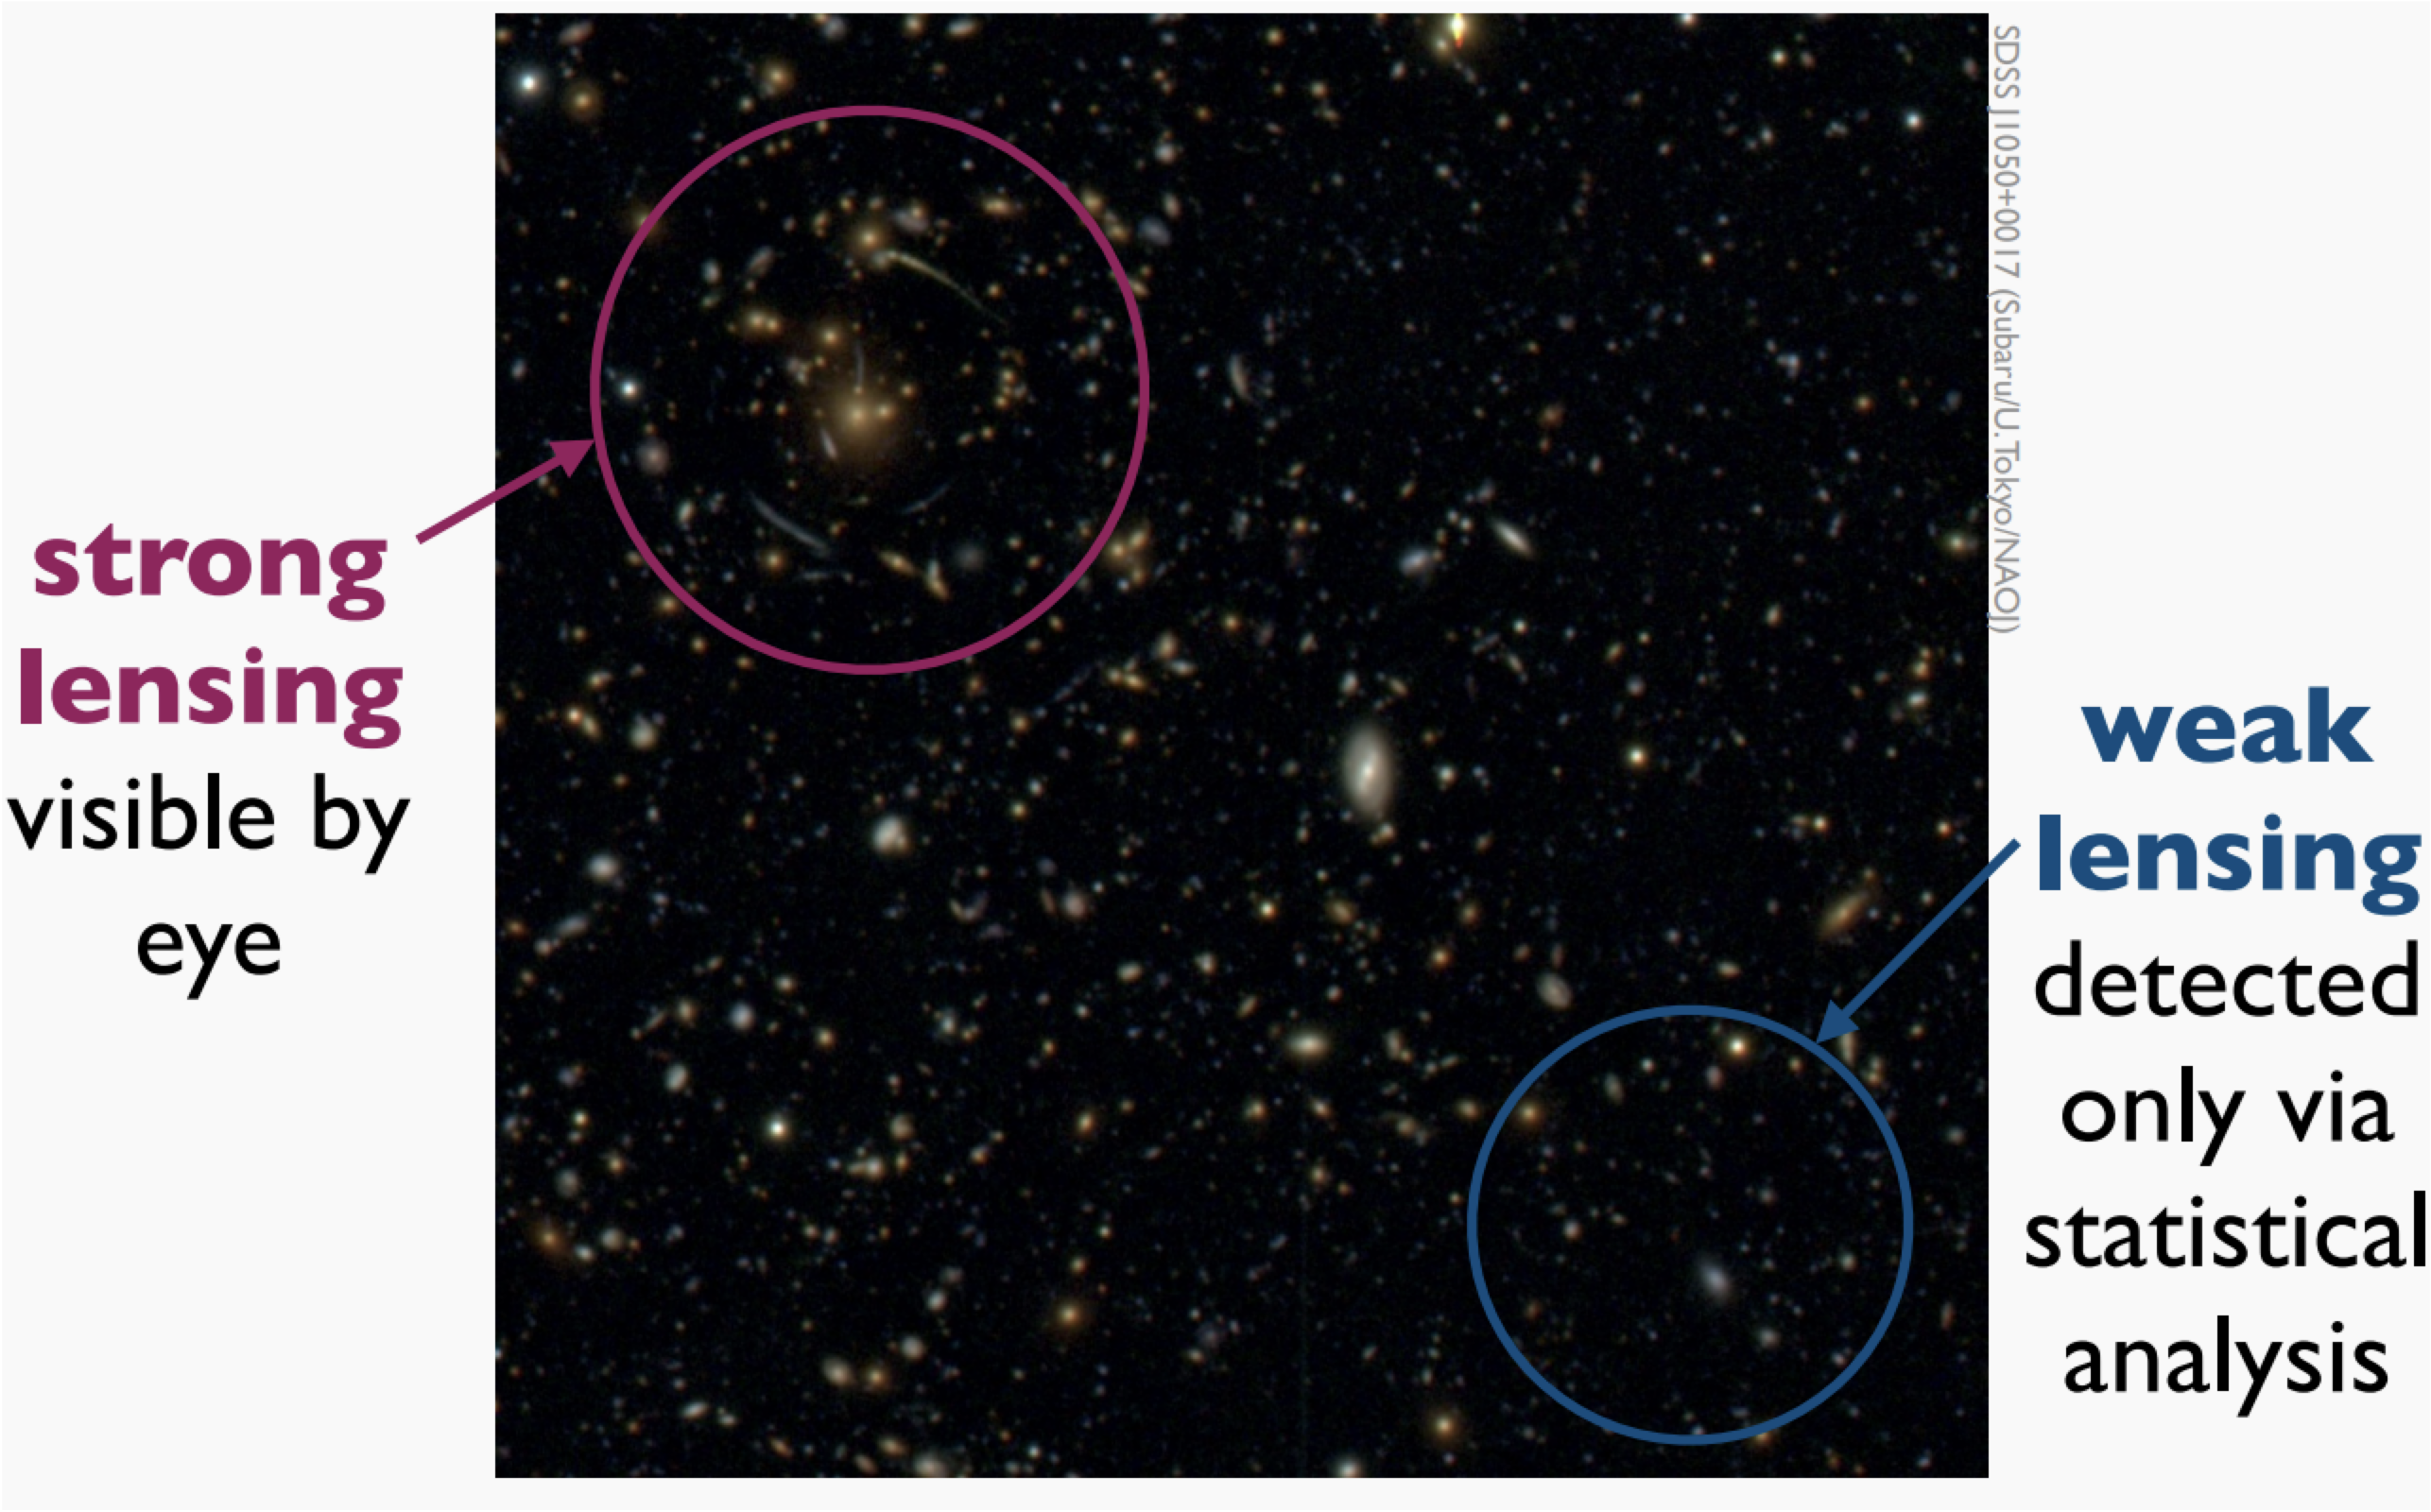
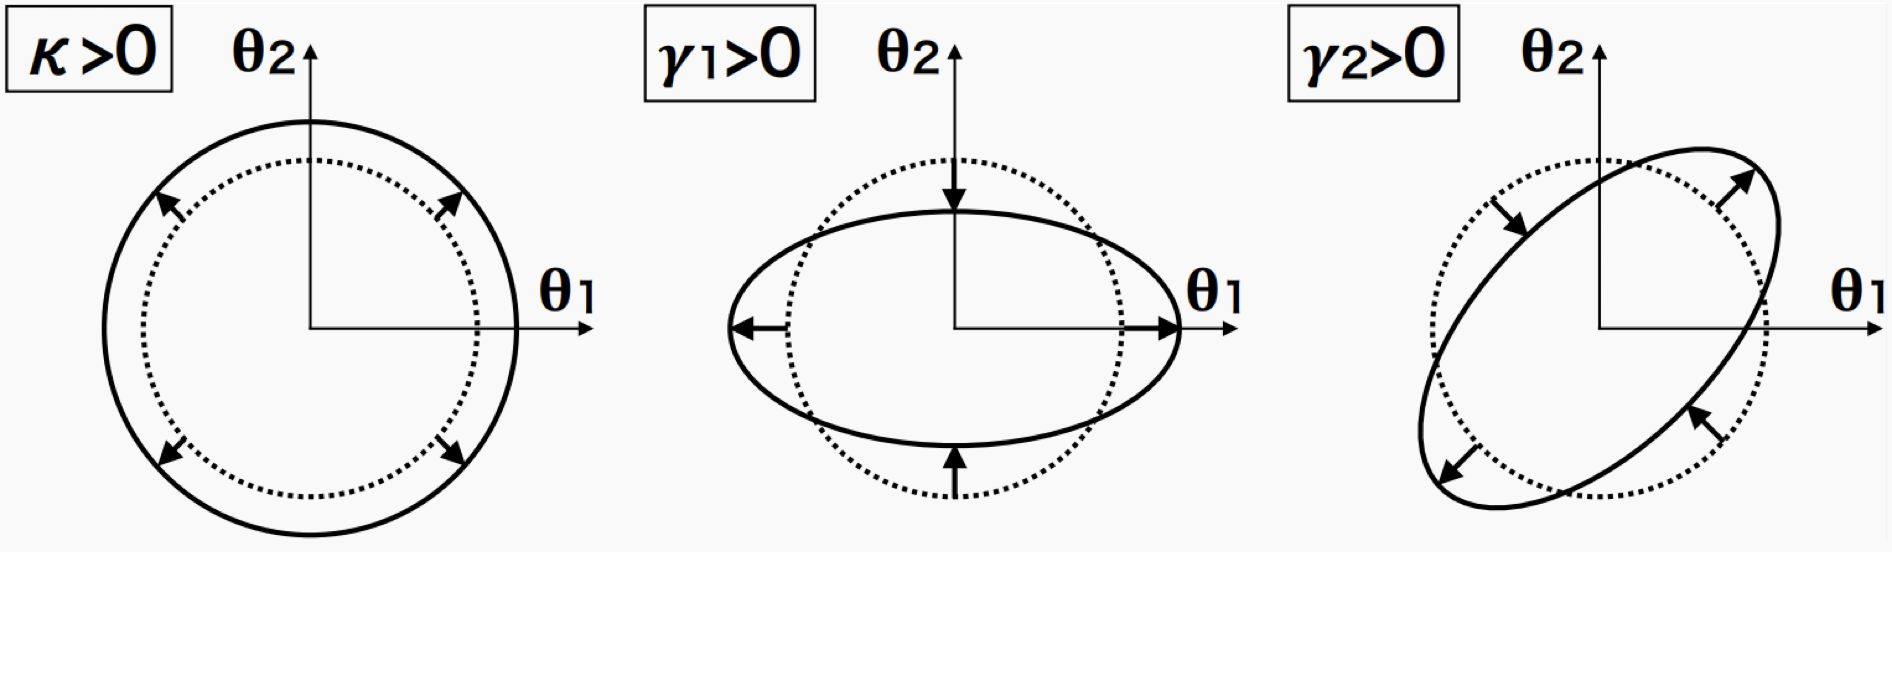
⟶ difficult to measure
⟶ can be measured by statistical analysis of galaxy shapes
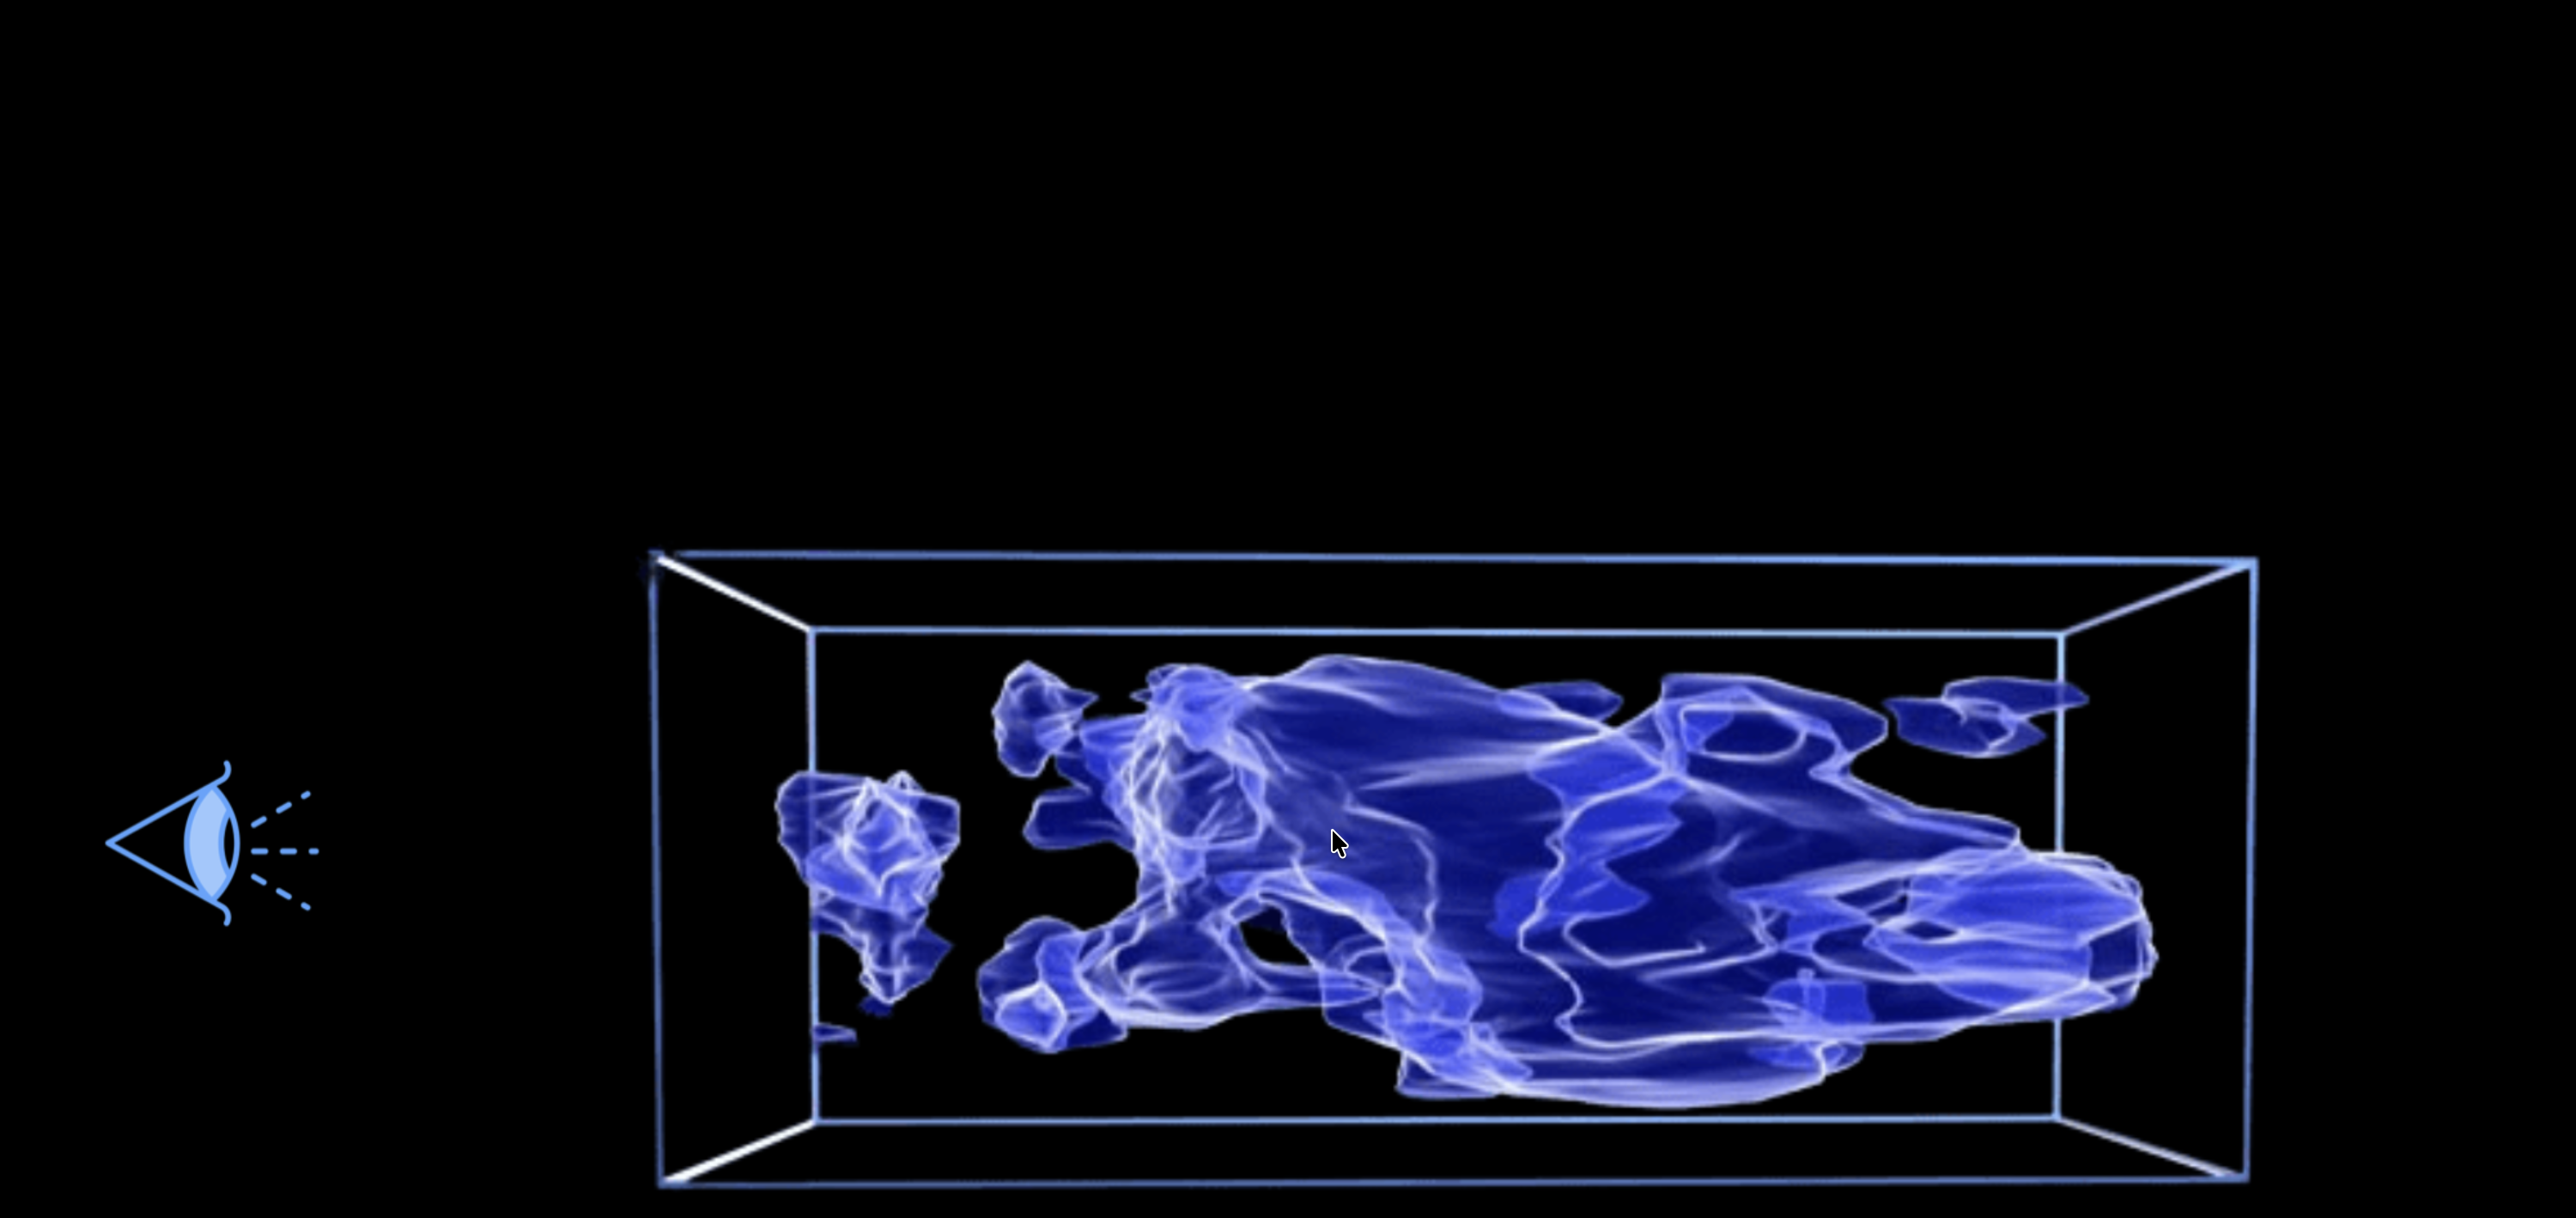
As a Line-of-sight (LOS) projection of the 3D overdensity:
\[ \kappa(\boldsymbol{\theta}) = \int_{0}^{\chi_s}\! d\chi\; W(\chi)\,\delta(\chi\,\boldsymbol{\theta},\chi),\qquad W(\chi)=\frac{3H_0^2\Omega_m}{2c^2}\,\frac{\chi(\chi_s-\chi)}{a(\chi)\,\chi_s}. \]